64GB RAM + 16GB VRAM: Which Open-Source Models Have Fewer Restrictions?

16GB VRAM is the hard bottleneck for local model running; 7B-13B quantized models are most realistic; unaligned doesn't mean smarter.
The article responds to a Reddit user's question about running "uncensored" local models on a 64GB RAM, 16GB VRAM configuration. The author clarifies that "uncensored" actually means low-refusal or unaligned, not without ethics. On the hardware side, 16GB VRAM is the key bottleneck: 7B-13B models with 4-bit quantization run smoothly, ~30B models need partial CPU offloading, and larger models respond noticeably slower. Commonly mentioned directions include Mistral fine-tunes, Llama 2/3 community fine-tunes, and smaller Yi and Qwen versions. The author emphasizes that unaligned models carry both risks and costs; removing safety alignment may reduce output reliability, and users bear compliance responsibility, so selection should start with clarifying use case.
When You Run Models Locally, What Do "Restrictions" Actually Mean?
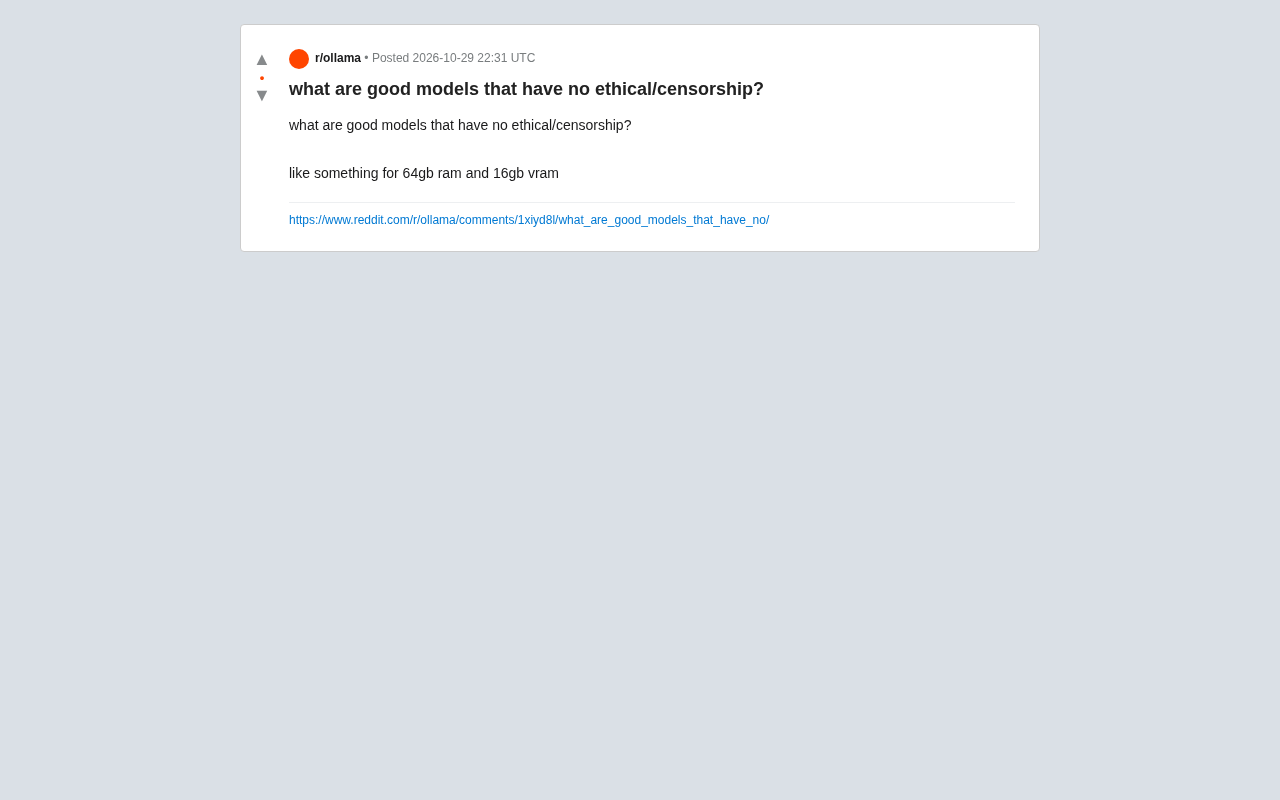
A Reddit post asked directly: "Are there any good models without ethical/censorship restrictions? For example, suitable for 64GB RAM and 16GB VRAM." The question itself reveals two things: the user wants local deployment, and they're frustrated by models' "refusal to answer" behavior.
Before discussing specific models, we need to clarify a commonly confused concept. "Uncensored" usually means the model won't refuse to answer certain topics due to safety alignment, but this doesn't mean the model is "without ethics." The more accurate term in the open-source community is "low-refusal" or "unaligned" models—they may be more open on sensitive topics, but are also more prone to producing inaccurate or harmful content.
What Can 64GB RAM + 16GB VRAM Run?
This hardware combination has a key bottleneck: VRAM. 16GB VRAM determines the model size you can fully load onto the GPU, while 64GB system RAM allows you to run larger models through CPU offloading, at the cost of speed.
From community practice, the realistic range for this configuration is: 7B to 13B parameter models can run fairly smoothly on GPU; ~30B models require partial offloading with acceptable speed; larger models mainly rely on CPU inference, with noticeably slower responses. Quantization techniques (like 4-bit quantization) are common methods to fit these models into VRAM.
Quantization in this context refers to representing model weights with lower bit-width to compress VRAM usage. Common approaches include GPTQ, AWQ, and GGUF (with llama.cpp), typically reducing original 16-bit weights to 4-bit or even lower. Rough estimate: a 7B model needs about 14GB VRAM in fp16, dropping to about 4GB with 4-bit quantization—this is what allows 13B models to run within 16GB VRAM. The cost is precision loss; low-bit quantization shows more obvious degradation on complex reasoning tasks, so the community generally recommends 4-bit as the balance point rather than pursuing ever-lower bit-width.
CPU offloading means placing some model layers in system memory for CPU computation rather than loading everything to GPU. Inference frameworks like llama.cpp support layer-by-layer allocation, handing off what doesn't fit to the CPU. Since CPU memory bandwidth is far lower than VRAM, each offloaded layer slows generation speed, often resulting in noticeably decreased token generation rates in practice. The point of 64GB RAM is to let you load larger models, but it doesn't mean you'll get acceptable interactive speed.
Model Families Frequently Mentioned in the Community
In similar discussions, Reddit users commonly mention several directions.
Mistral fine-tuned versions are among the most frequent answers. Mistral 7B and its derivatives, due to moderate size and rich community fine-tuning, run easily within 16GB VRAM, with multiple abliterated or low-refusal variants.
Llama 2/3 community fine-tunes are equally common. The Llama ecosystem is vast, with numerous community versions removing safety alignment, covering 7B to 13B parameters, suitable for this hardware tier.
Yi and Qwen series are mentioned in some discussions, especially smaller parameter versions, considered to perform well in Chinese and multilingual scenarios, with corresponding low-restriction fine-tunes in the community.
It should be noted that these recommendations come from user experience sharing; quality varies greatly between different fine-tuned versions, and different community versions of the same base model may perform drastically differently.
Abliteration is a technique to remove model refusal behavior without retraining: by identifying direction vectors within the model related to "refusal" and reducing that direction at inference or weight level, making the model more cooperative with prompts that would originally trigger refusals. Unlike RLHF fine-tuning which requires large amounts of data and compute, abliteration is low-cost and can be applied directly to existing open-source weights, hence its rapid popularity in the community. However, the side effect is potentially weakening the model's robustness in other scenarios—one reason why different abliterated versions of the same base model vary significantly.
Risks and Costs of Unaligned Models
Choosing low-restriction models isn't without cost. Safety alignment often serves the function of "reducing hallucinations and harmful outputs." Removing it makes models more open on sensitive topics, but may also make them less reliable in other scenarios.
A recurring reminder in the community: outputs from unaligned models require more human judgment. They indeed "beat around the bush" less in creative writing, role-playing, and certain research discussions, but aren't inherently more accurate on factual Q&A. Equating "uncensored" with "smarter" is a common misconception.
Another practical issue is legal and platform compliance. Different regions have different requirements for model output content; local deployment reduces platform-level restrictions, but users remain responsible for generated content.
How to Choose: Clarify Your Use Case First
Back to the original post's question—there's no single correct answer; it depends on use case. If the goal is creative writing or role-playing, community fine-tuned low-refusal models are a reasonable choice; for code or technical Q&A, mainstream aligned models are usually more stable; if researching model behavior itself, unaligned versions can serve as control groups.
On the hardware side, it's recommended to first test actual speed with 7B-13B quantized models, then decide whether it's worth enduring CPU offloading latency for larger models. 64GB RAM gives you room to experiment, but 16GB VRAM is the line that determines the experience.
One final point: the phrase "without ethical restrictions" itself deserves caution. Models won't take responsibility for your judgments; the more open the tool, the more important the user's judgment becomes.
One-line Summary
16GB VRAM is the hard bottleneck for local model running; 7B-13B quantized models are most realistic; unaligned doesn't mean smarter.
Paragraph Summary
The article responds to a Reddit user's question about running "uncensored" local models on a 64GB RAM, 16GB VRAM configuration. The author first clarifies that "uncensored" actually means low-refusal or unaligned, not without ethics. On the hardware side, 16GB VRAM is the key bottleneck determining experience: 7B-13B models with 4-bit quantization run smoothly, ~30B models need partial CPU offloading, and larger models respond noticeably slower. Commonly mentioned directions in the community include Mistral fine-tunes, Llama 2/3 community fine-tunes, and smaller parameter versions of Yi and Qwen. The author emphasizes that unaligned models carry both risks and costs; removing safety alignment may reduce output reliability, and users bear compliance responsibility, so selection should start with clarifying use case.
Related articles

iPhone Duo Transformed into a Windows 98 Gaming PC: Hands-On Test and Experience
XDA tests turning the iPhone Duo foldable into a Windows 98 gaming PC using RetroArch and DOSBox Pure with virtual 3DFX, running Unreal Tournament, Half-Life, and Quake 3, plus Windows XP feasibility and limits.

Type-Safe Keep Rules in R8 and DEX Optimization in Practice
Google Play requires over 25% DEX optimization. This article explains the R8 configuration analyzer, Jetpack Keep type-safe annotations, and the Android CLI validation tool to help Android developers narrow keep rules, improve shrinking/optimization/obfuscation, and reduce ANRs.

Why Are Old Buildings More Beautiful Than New Ones? Pulitzer Prize-Winning Author Reveals an Overlooked Economic Truth
Pulitzer Prize-winning author Robert Caro found that poorer countries built more beautiful buildings. He reveals how cheap skilled craftsmen created the intricate details of old New York architecture, and how rising labor costs changed architectural aesthetics.