AI Large Language Models for Beginners: Core Principles, Hallucinations, and Token Billing Explained

A clear breakdown of how large language models work, including hallucinations, Token billing, and Chinese open-source models.
This article uses ChatGPT's emergence as a starting point to trace the evolution from keyword-matching chatbots to large language models. It explains the two defining traits of LLMs — massive training data and enormous parameter counts — and the three breakthrough experiences they deliver. It also confronts their core limitation: outputs are probabilistic next-token predictions, not genuine understanding, which gives rise to AI hallucinations. The article also covers the rise of Chinese open-source models like DeepSeek and explains what Tokens are as a billing unit, helping readers use LLMs as informed, rational tools.
From Chatbots to Large Language Models: A Qualitative Leap
Before ChatGPT arrived, we weren't strangers to conversational AI. Chatbots like Microsoft Xiaoice had already been around for years — but they all shared the same fundamental limitation: ask the same question, get the same answer, every time. They had no memory of what you'd said earlier and no ability to internalize the information you provided.
The reason was simple: early chatbots were essentially keyword-matching systems. The backend held a library of keywords and rules; when a match was triggered, a predefined response was returned. This mechanical call-and-response loop made them look "smart" on the surface, while offering zero genuine comprehension.
That all changed in late 2022, when OpenAI launched ChatGPT. It became the fastest-growing consumer product in history by daily active users — and this was before it was even easy to access. People around the world jumped through hoops (VPNs, overseas phone numbers) just to try it.
Three Breakthrough Experiences ChatGPT Delivered
What made ChatGPT an overnight global phenomenon came down to three experiences users had never encountered before.
Extended, Coherent Contextual Memory
ChatGPT could remember what you said earlier in a conversation, understand pronoun references, and sustain coherent dialogue across many turns. Rather than processing each message in isolation, it responded based on the full conversational thread. This capability is what we call context.
Active Understanding and Clarifying Questions
It didn't just answer — it asked follow-up questions, reasoned through your intent, and could infer what you meant even when you used vague or ambiguous language.
Natural, Fluent Language
AI research has long used the Turing Test as a benchmark: if a human can't tell whether they're talking to a person or a machine, the machine passes. For many users, ChatGPT was the first time that line genuinely blurred — its responses felt natural and fluid, not robotic or scripted.
And crucially, early ChatGPT was completely free. Anyone who could load the webpage could use it. That combination made it a once-in-a-generation product.
What Is a Large Language Model: Two Kinds of "Large"
The term "large model" hinges on two distinct dimensions of scale.
The first is large training data. GPT-3.5, for instance, was trained on an enormous corpus scraped from the internet and digitized books — effectively a snapshot of human knowledge. That's why it seems to "know everything" about so many subjects.
The second is a large number of parameters. Parameters are essentially storage units within the model. The more parameters a model has, the broader its knowledge base and the more capable it is of understanding semantics and generating creative content.
From writing articles, poetry, and code to generating images, music, and video — the capabilities of large models continue to expand. This kind of integrated, multi-modal system is what we refer to today when we talk about large model systems.
The Rise of Chinese Open-Source Large Models
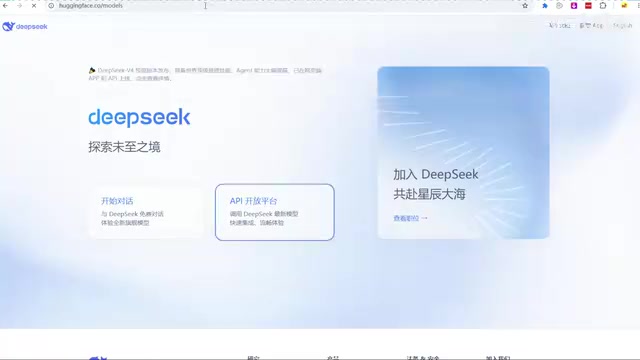
Today's large models fall into two broad camps: commercial closed-source models like OpenAI's ChatGPT, and open-source models. In the open-source arena, China has risen to become the world leader.
Platforms like HuggingFace give a clear picture of just how many open-source models now exist globally. Notable Chinese open-source models include:
- Alibaba's Qwen series
- Zhipu AI's GLM series (incubated by a Tsinghua University team)
- DeepSeekAd
- Moonshot AI's Kimi
- Xiaomi's MiMo
DeepSeek deserves special mention for two reasons: first, it open-sourced top-tier model weights, enabling anyone with sufficient hardware to self-host and run the model locally; second, it slashed remote API pricing to a fraction of what comparable models previously cost. In the early days, calling models like GPT via API was prohibitively expensive. DeepSeek made large model capabilities accessible to virtually every developer.
The Core Mechanism: Probabilistic Prediction
Many casual users develop a misconception that AI models genuinely "know everything." That's not how they work.
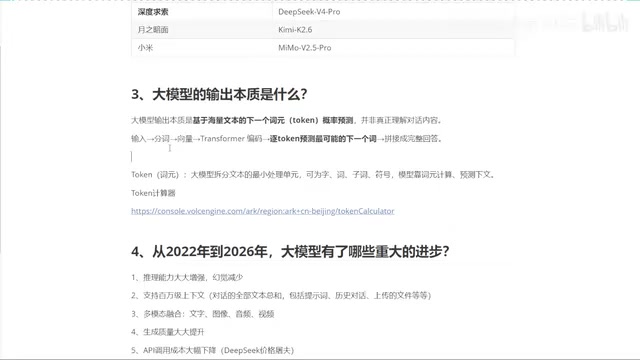
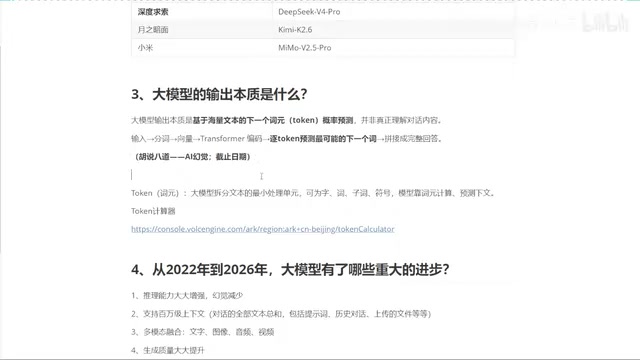
What a large model does at its core is probabilistic prediction. When you ask a question, the model processes your input — drawing on its training data (and now, often live web search) — and then predicts, word by word, what token is most likely to come next, stitching together a complete response. Four words capture the essence: probabilistic next-token prediction.
Why AI Hallucinations Happen
This is precisely why early ChatGPT was notorious for confidently making things up. Ask about a celebrity's recent news, and rather than admitting it didn't know, it would fabricate a detailed, plausible-sounding answer — some events entirely fictional, others wildly misattributed. This phenomenon is called AI hallucination.
Hallucinations arise from two root causes:
- The model is a probabilistic output engine, not a system that truly understands or verifies information.
- Training data has a cutoff date. Training large models is expensive and time-consuming — DeepSeek's training costs, including personnel, run into the millions of dollars, with training cycles lasting months to a year. Models simply cannot be retrained daily, which means anything that happened after the cutoff is unknown to them.
Hallucination rates have improved significantly in recent years, but the problem hasn't disappeared. Never blindly trust AI outputs in high-stakes domains like law or medicine — always verify.
What Is a Token: The Billing Unit for Large Model APIs
Using a large model via API costs money, and the billing unit is the Token — officially translated in China as 词元 (lexical unit).
Most models are priced at roughly two to three Chinese yuan per million tokens. But what exactly is a token? It's not as simple as "one English word equals one token, one Chinese character equals two tokens." Instead, tokenization follows specific splitting rules that break text into discrete units.
Using the online token calculator provided by ByteDance's Volcano Engine as an example: input a passage of Chinese text, and it segments by word unit — "推理" (reasoning) is one token, "能力" (capability) is one token, and numbers and punctuation each count as one. Interestingly, the word "DeepSeek" gets split into three tokens.
The actual cost per token is remarkably low. At two yuan per million tokens, a typical sentence of around a hundred tokens costs a fraction of a hundredth of a cent — a unit smaller than the smallest denomination of everyday currency. This is precisely why large model APIs have been able to scale so broadly across applications.
Understanding LLM Fundamentals Is the Starting Point for Safe Use
Whether you're doing security research, code auditing, or automated penetration testing, understanding how large models work under the hood is a prerequisite for using them responsibly. When we internalize that these models are fundamentally probabilistic predictors — that hallucinations are a structural risk, and that token costs are real but minimal — we can treat them as powerful tools rather than infallible oracles.
For anyone looking to enter the intersection of AI and security, grasping these foundational concepts is an unavoidable first step on the path to practical application.
Related articles

T3 Code: The Open-Source AI Coding Assistant's Comeback Story
T3 Code is an open-source AI coding assistant that unifies subscriptions like Codex and Claude, with powerful remote control and parallel task management.

Never Elected, Yet Ruled New York for 30 Years: The Ultimate Case Study in the Mechanics of Power
Robert Caro's biographies reveal how unelected Robert Moses ruled New York for 30 years through legal drafting and public authorities, and how Lyndon Johnson built leverage as a "powerless" Senate Majority Leader. Unpacking the underlying logic of accumulating and sustaining power.

The CPython 3.10 Recursion Trap and Synthetic Recovery in TokenGuard, an LLM Circuit Breaker
TokenGuard's author recounts a recursion crash caused by OrderedDict.pop in CPython 3.10 and introduces v0.3.0's Loop Nudge synthetic recovery, inline DLP scanning, and other new LLM agent circuit-breaker capabilities.