Calculating the Transformer Forward Pass by Hand: Understanding Large Models Matrix by Matrix

Hand-calculating the Transformer forward pass matrix by matrix builds solid intuition for large model internals.
The article introduces a Reddit learner's method of hand-writing a small example, labeling dimensions, and completing matrix multiplications to understand the Transformer forward pass. Hand calculation exposes dimension matching and numerical flow, helping grasp positional encoding's frequency signatures and encoder shape invariance. Once the encoder is mastered, BERT can be seen as a small modification adding segment embeddings and prediction heads. It also discusses the complementarity of hand calculation, coding, and visualization, notes that residual connections and layer normalization are common difficulties, and provides resources with exercises and a notebook to encourage hands-on practice from a minimal example.
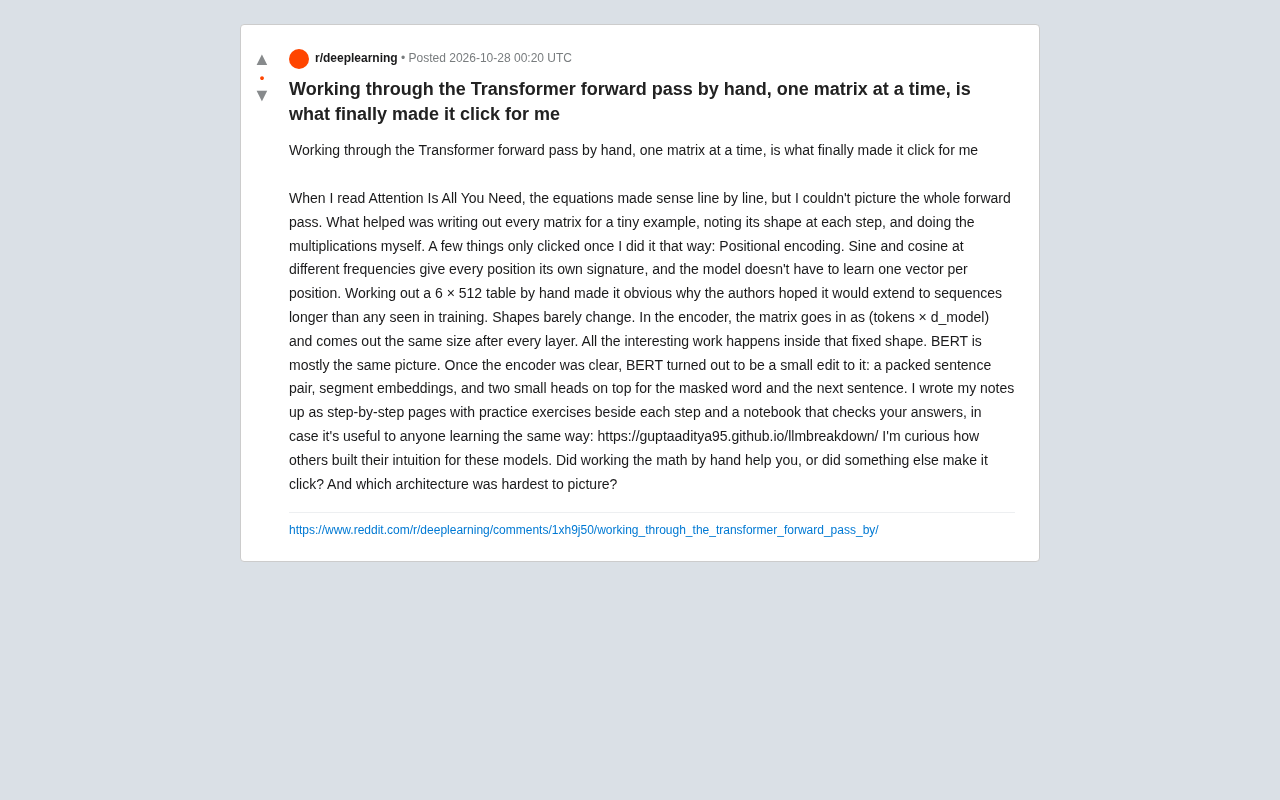
When reading Attention Is All You Need, each formula makes sense on its own, but when you try to string the entire forward pass together, you never quite have a complete picture in your head. Recently, I saw a learner's post on Reddit: by hand-writing every matrix in a small example, labeling the dimensions at each step, and performing the matrix multiplications himself, he finally got the Transformer to "run." This approach may seem clumsy, but it might be the most solid path to understanding the internal mechanisms of large models.
Why Hand-Calculating Matrix by Matrix Works
Reading papers and hand-calculating matrices are two different cognitive activities. The former familiarizes you with symbols and terminology; the latter forces you to deal with dimension matching, numerical flow, and the actual output at each step. The Reddit user mentioned that only after manually computing the 6×512 table of positional encodings did he truly understand why the combination of sine and cosine allows the model to distinguish different positions without needing to learn an independent vector for each position.
Another benefit of hand calculation is that it exposes the key fact of "shape invariance." In the encoder, the input matrix has shape (tokens × d_model), and after each layer the output shape is exactly the same. All semantic processing—attention weighting, feed-forward network transformations—happens inside this fixed-size container. Once you've traced this shape flow on paper, looking at a model architecture diagram no longer feels like a bunch of unrelated blocks.
d_model is the vector dimension representing each token in the Transformer, and also the hidden layer width shared by all layers inside the model. In the paper, the base model uses 512, so when a sequence of 6 tokens is input to the encoder, it forms a 6×512 matrix. This dimension not only determines the projection sizes of Q, K, V in attention, but also determines the expansion ratio of the feed-forward network's intermediate layer (typically 4x). The key to understanding d_model is that it is an invariant "container": no matter how many layers it passes through, each token is always represented by a 512-dimensional vector; what changes is the values in the vector, not the shape. Repeatedly labeling this dimension during hand calculation helps build an intuition of "shape conservation" and prevents getting lost when splitting multi-heads or adding residual connections.
Positional Encoding: How Frequencies Sign Each Position
Positional encoding is a section often skipped in the Transformer because it looks like just a few sine-cosine formulas. But when you actually compute the 6-position, 512-dimensional encoding table for a small example, you discover that different dimensions correspond to different frequencies: low dimensions change quickly, high dimensions change slowly. This design gives each position a unique "frequency signature," and the encoding differences between adjacent positions are smooth.
The authors hoped this encoding could generalize to longer sequences unseen during training. Hand-calculating the table intuitively shows why this hope is reasonable: the frequency pattern is mathematically defined and does not depend on data, so the encoding rule still holds when the sequence gets longer. Of course, actual generalization is limited by other parts of the model, but at least positional encoding itself is not a bottleneck.
Sinusoidal positional encoding has the formulas (PE_{(pos, 2i)} = \sin(pos/10000^{2i/d_{model}})) and (PE_{(pos, 2i+1)} = \cos(pos/10000^{2i/d_{model}})), where pos is the position index and i is the dimension index. The exponent term in the denominator makes different dimensions correspond to different wavelengths: low dimensions (small i) have short wavelengths and change quickly; high dimensions (large i) have long wavelengths and change slowly. This design is similar to the combination of different bit weights in binary encoding, so each position obtains a unique set of sine-cosine values. Because sine and cosine are continuous functions, the encoding differences between adjacent positions are smooth, and the model can learn relative position relationships through linear transformations. When hand-calculating the 6×512 table, you can intuitively see the periodic variation of each column (dimension), thereby understanding why this encoding can generalize to longer sequences without training.
Beyond the Encoder: BERT Is Just a Small Modification
This learner also discovered that once the hand-calculation workflow for the encoder is mastered, understanding BERT becomes much easier. BERT is basically the encoder with a few small modifications: packing sentence pairs into a single input sequence, adding segment embeddings to distinguish the two sentences, and then adding two small output heads on top, for masked word prediction and next sentence prediction respectively.
This "starting from the encoder" approach to understanding is more efficient than directly grinding through the BERT paper, because you can attach new components to an existing mental model. The experience of hand-calculating the encoder lets you know the meaning of each matrix multiplication, and when you see BERT's modifications, you can judge which parts are reused and which are new.
Segment embeddings are special vectors in BERT used to distinguish sentence pairs, added to token embeddings and position embeddings before being input to the encoder. In BERT's pre-training tasks, the input may be two sentences concatenated (e.g., [CLS] Sentence A [SEP] Sentence B [SEP]), and segment embeddings mark for each token whether it belongs to Sentence A or Sentence B (usually represented by 0 and 1), helping the model understand sentence boundaries and cross-sentence relationships. This differs from positional encoding: positional encoding marks the absolute position of a token in the sequence, while segment embeddings mark sentence membership. During fine-tuning, if the task does not involve sentence pairs, segment embeddings are usually all set to zero, but during pre-training they are crucial for the next sentence prediction task. Understanding this clarifies how BERT adapts the encoder's general representations to the two tasks of sentence-pair classification and masked language modeling.
Building Intuition Beyond Hand Calculation
This Reddit user was also curious about how others build intuition for the Transformer. Hand calculation is certainly not the only path. Some learn by writing minimal implementations, some use visualization tools to observe attention weights, and some infer model behavior from fine-tuning practice. Each method has a different focus: hand calculation strengthens numerical and dimensional intuition for the forward pass, writing code strengthens engineering implementation details, and visualization helps observe attention patterns.
A combination worth trying: first hand-calculate one layer of a small example, then write code to verify your hand-calculated results, and finally use visualization tools to observe the attention distribution in a real model. This cross-validation from the three angles of numbers, code, and phenomena makes understanding more three-dimensional.
For readers who want to reproduce this user's learning path, he organized his notes into a step-by-step page, with exercises next to each step, and a notebook to check answers, at https://guptaaditya95.github.io/llmbreakdown/ . This combination of "hand calculation + immediate feedback" makes it easier to solidify knowledge than simply reading papers or watching videos.
Residual Connections and Layer Normalization (Add & Norm) are standard operations after each sublayer (self-attention or feed-forward network) in the Transformer: first add the sublayer input and sublayer output (residual connection), then perform layer normalization. Residual connections alleviate the vanishing gradient problem in deep networks, allowing gradients to flow directly through the network; layer normalization normalizes each token's vector (mean 0, variance 1), stabilizing training dynamics. When hand-calculating the forward pass, residual connections appear as simple matrix addition, and layer normalization involves subtracting the mean and dividing by the standard deviation—steps are clear but computationally heavy. However, their impact on training—such as improved gradient flow and reduced internal covariate shift—often requires observing backpropagation or training curves to appreciate, so hand calculation helps understand the numerical operations, but complete intuition requires combining training dynamics analysis.
Which Architecture Is Hardest to Visualize
The question this user finally posed was: which architecture is hardest to form a mental picture of? From community discussions, the Transformer's encoder-decoder structure, the parallel splitting of multi-head attention, and the placement of residual connections and layer normalization are all common sticking points. Hand calculation can alleviate the first two, but the role of residuals and normalization often requires seeing gradient flow or training dynamics to fully understand.
If you are also learning the internal mechanisms of large models, why not find a minimal example, take out pen and paper, and write out the shape and multiplication of each matrix step by step. This won't make you an expert immediately, but it will give you an operable picture in your head the next time you read "d_model," "multi-head," or "positional encoding," rather than a pile of symbols waiting to be memorized.
One-line Summary
Hand-calculating the Transformer forward pass matrix by matrix is a solid path to building intuition about the internals of large models.
Paragraph Summary
The article introduces a Reddit learner's method of understanding the Transformer forward pass by hand-writing a small example, labeling dimensions, and completing matrix multiplications. Hand calculation exposes dimension matching and numerical flow, helping to understand key concepts such as the frequency signature of positional encoding and the shape invariance of the encoder. Once the encoder is mastered, BERT can be seen as a small modification adding segment embeddings and prediction heads. The article also discusses the complementarity of hand calculation, coding, and visualization as three learning paths, and points out that residual connections and layer normalization are common difficulties. Finally, it provides reproduction resources with exercises and a notebook, encouraging readers to start hands-on practice from a minimal example.
Related articles

T3 Code: The Open-Source AI Coding Assistant's Comeback Story
T3 Code is an open-source AI coding assistant that unifies subscriptions like Codex and Claude, with powerful remote control and parallel task management.

Never Elected, Yet Ruled New York for 30 Years: The Ultimate Case Study in the Mechanics of Power
Robert Caro's biographies reveal how unelected Robert Moses ruled New York for 30 years through legal drafting and public authorities, and how Lyndon Johnson built leverage as a "powerless" Senate Majority Leader. Unpacking the underlying logic of accumulating and sustaining power.

The CPython 3.10 Recursion Trap and Synthetic Recovery in TokenGuard, an LLM Circuit Breaker
TokenGuard's author recounts a recursion crash caused by OrderedDict.pop in CPython 3.10 and introduces v0.3.0's Loop Nudge synthetic recovery, inline DLP scanning, and other new LLM agent circuit-breaker capabilities.