COLM Conference Deep Dive: Positioning, Academic Ecosystem, and What It Reveals About AI Research

A deep dive into COLM, the only top conference dedicated exclusively to language modeling research.
COLM (Conference on Language Modeling), founded in 2024, is the only top-tier academic conference dedicated exclusively to language model research. This article explores why COLM rose quickly in the AI academic landscape, how its acceptance season fuels community discussion on Reddit, and what its emergence reveals about the broader shift from general ML research toward LLM specialization.
COLM: The Dedicated Academic Stage for the Language Model Era
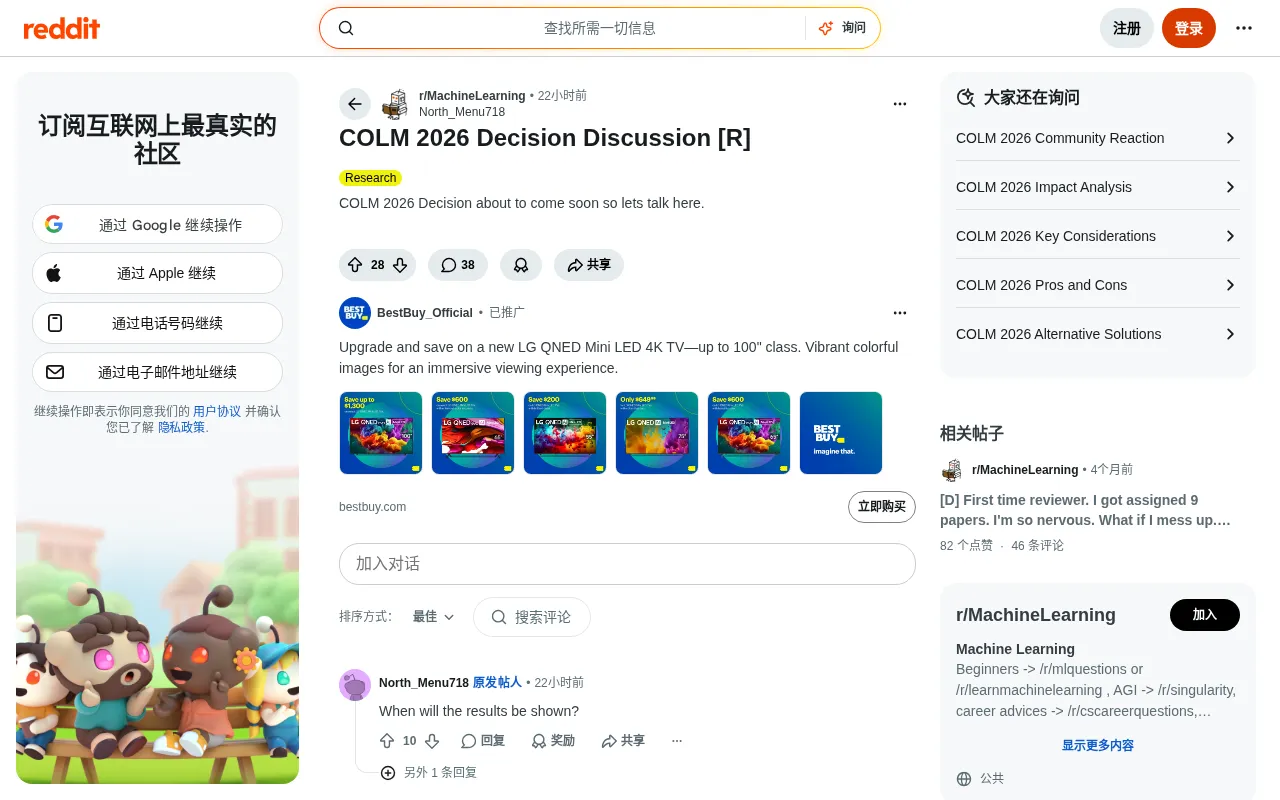
With COLM 2026 (Conference on Language Modeling) acceptance decisions on the horizon, Reddit's r/MachineLearning community has erupted into another round of spirited discussion. A thread titled "COLM 2026 Decision Discussion" has once again put this rapidly rising LLM-focused conference — young but already prominent — squarely in the spotlight.
Founded in 2024, COLM is currently the only top-tier academic conference dedicated exclusively to the theme of "Language Modeling." Unlike the established general-purpose machine learning venues — NeurIPS, ICML, ICLR, and their predecessors, which trace their roots back to the 1980s and 90s and have long dominated the AI publishing landscape — COLM was conceived from day one as a vertical conference for the LLM era. Its mission: to consolidate language model research scattered across dozens of venues into a single platform, enabling deeper and more focused academic exchange.
Why a New Conference Could Rise So Quickly
Within the traditional machine learning conference ecosystem, language model research has long been fragmented — split between NLP-focused venues (ACL, EMNLP) and general ML conferences. It's worth noting that ACL, EMNLP, NAACL, and their peers are more deeply rooted in linguistics and symbolic processing traditions, creating a meaningful paradigm gap with modern language model research centered on large-scale pretraining. The field had no dedicated home with "language modeling" as its core organizing principle. COLM arrived precisely to fill that institutional void.
Vertical Focus: Addressing Researchers' Real Needs
As large models like GPT, Claude, and Llama have successively taken off, the breadth and depth of language model research has expanded at a breakneck pace. The technical foundation underlying all of this is the Transformer architecture proposed by Vaswani et al. in 2017 — whose key innovation was replacing traditional recurrent neural networks with a self-attention mechanism, enabling highly parallelized sequence modeling. The large-scale pretraining paradigm built on this architecture — training general-purpose language representations on massive unlabeled text, then transferring to downstream tasks via fine-tuning or prompt engineering — has fundamentally rewritten the methodological foundations of AI research.
The research topics that have emerged from this are remarkably diverse: alignment techniques such as Reinforcement Learning from Human Feedback (RLHF) and Direct Preference Optimization (DPO), aimed at making model behavior conform to human intent and values; reliability concerns including hallucination mitigation and Chain-of-Thought reasoning; efficiency techniques such as quantization, distillation, and speculative decoding for inference acceleration; and fields like mechanistic interpretability, multimodal integration, and benchmark construction. Each sub-area is rich enough to sustain a substantial volume of high-quality research. COLM gives these researchers a community of like-minded peers — and that is its core competitive advantage over broader, general-purpose conferences.
Deep Integration of Academia and Industry
Among COLM's organizers and contributors are both researchers at the academic frontier and practitioners from top industrial labs — OpenAI, Anthropic, Google DeepMind, Meta, and others. In recent years, these industrial labs have become major sources of top-tier AI papers, with their output at some conferences even surpassing that of traditional academic institutions. They bring empirically grounded results backed by massive computational resources, and they have profoundly shaped the direction of the broader research ecosystem. This deep intertwining of academia and industry allows COLM to maintain academic rigor while staying tightly connected to the real problems at the cutting edge of the industry. That said, how to balance openness with academic fairness remains a topic of ongoing community concern.
Acceptance Season: A Collective Emotional Release
Whenever a top conference announces its acceptance decisions, social platforms light up with "Decision Discussion" threads. These posts serve as a concentrated outlet for the research community's collective emotions: retrospectives on reviewer feedback, discussions of the strategic dynamics of the rebuttal phase, and endless speculation about acceptance rates and evaluation criteria.
The Anxiety and Anticipation of Waiting
Top AI conferences universally employ a double-blind peer review process. The typical workflow includes: paper submission, reviewer assignment, initial scoring, the author rebuttal phase (the only window in which authors can actively intervene — clarifying misunderstandings and providing supplementary experiments in response to reviewer concerns), updated reviewer scores, synthesis by an Area Chair or Meta-Reviewer, and finally, the acceptance decision. This process routinely spans several months, and every reviewer score and meta-review comment puts authors on edge. For COLM, a relatively young LLM-focused conference, the quality and consistency of its reviewer pool is especially critical — and the stability of its evaluation standards and acceptance thresholds has been a recurring topic of community debate. For a conference only two or three editions old, "reputation" and "prestige" are still in the process of being built.
The Real Informational Value of Discussion Threads
These threads may look like little more than communal waiting rooms for anxious researchers, but they serve an important information-aggregation function. Researchers share their score distributions, exchange observations about acceptance patterns across different sub-areas, and collectively build up a picture of the conference's review quality. For first-time submitters, this ground-level intelligence is often more actionable than any official announcement.
What COLM Reflects About the Shifting AI Research Paradigm
COLM's rise is no accident. It is a microcosm of a broader shift in the center of gravity of AI research over the past few years.
From "General ML" to "Language Model Specialization"
In the early days of deep learning, researchers were primarily focused on general-purpose model architectures and optimization methods. As the Transformer architecture and large-scale pretraining became the dominant paradigm, language models themselves grew into complex systems worthy of independent study — with parameter counts leaping from hundreds of millions to hundreds of billions and even trillions, and the challenges of training engineering, inference optimization, safety alignment, and more far exceeding the scope of traditional ML research. The alignment, evaluation, inference efficiency, and hallucination mitigation research that has grown up around these models now constitutes a self-contained field. COLM is the institutionalization of that trend.
A Reshuffling of the AI Academic Publishing Ecosystem
The proliferation of new conferences is quietly reshaping the broader AI publishing landscape. Researchers must weigh their submission strategies across a growing array of venues: established top conferences with long histories and broad influence, or newer vertical conferences with more targeted positioning and tighter community focus? The influx of industry researchers has brought cutting-edge empirical results, but it has also sparked widespread discussion about research independence and reproducibility. Whether COLM can consolidate its position over the coming years will depend on its ability to consistently attract high-quality papers, maintain rigorous review standards, and build a predictable, credible academic reputation.
Closing Thoughts
With COLM 2026 acceptance decisions about to drop, the stakes extend well beyond the immediate fate of thousands of submitted papers — this is also a meaningful data point for assessing the health of the large language model research ecosystem. Growing a young conference takes time and sustained community investment. Regardless of the final outcomes, the very fact that these discussions are happening reflects the field's vibrant intellectual energy and its culture of open exchange. For researchers and practitioners who follow AI closely, keeping an eye on vertical conferences like COLM may be one of the best ways to catch early signals of where language model research is headed next.
Related articles

Data Scraping, AI Proofs, and Open Source Contracts: This Week's Deep Dive into the Tech World
From the 3D model crawler controversy and OpenAI's Lean formal proofs to AI agents challenging Brooks' Law and Debian rejecting LLM review, this week's tech discussions center on openness and verifiability.

Build a Reasoning Model from Scratch: An 11-Hour Open-Source Course Breakdown
Sebastian Raschka releases a free 8-episode, ~11-hour video course teaching you to build a reasoning model from scratch with Python and PyTorch—from a small Qwen3 model through Verifier, Inference Time Scaling, GRPO, and distillation, with open-source code on GitHub.

An 11-Hour Reasoning Model Course in Practice: How Small Models Learn to Think
Starting from Sebastian Raschka's 11-hour reasoning model course and HN buzz, this analyzes small-model training, legal text version control, Anthropic data policy, and product reliability reviews.