Completion or Agent? One Formula Explains the AI Coding Paradigm Divide

Completion guesses the next line, Agent completes the ticket—the divide is the feedback-loop harness.
The article distinguishes two ways AI coding tools work: Completion and Agent. Completion appears as gray ghost text, works at the unit of a single line, stops once it's done guessing, and won't self-correct from errors; Agent takes natural-language tasks, reads the repo, edits multiple files, runs tests, and after failures reviews errors and revises until it delivers a diff or pull request. The author proposes the core formula "Agent = Model + Harness," stressing that the model provides intelligence while the harness provides file reading, command execution, permission control, and the feedback loop—no loop means a one-shot generation, a loop makes it work like a junior engineer. So a stronger model doesn't automatically mean stronger coding. Selection advice: use completion for casual everyday coding, use Agent for multi-file delivery tasks, and both can run simultaneously. The criterion is whether the tool reads the repo, runs tests, and fixes itself—not completion accuracy.
Many people think that switching to a stronger code completion plugin means they've caught up with the pace of AI coding. But the real dividing line isn't how strong the model is—it's the difference between two ways of working: Completion and Agent. Bilibili's "Problem-Oriented Series" nailed this topic in a short video: completion guesses the next line, Agent completes the ticket.
The Essential Difference Between Completion and Agent
The most classic form of completion is the gray ghost text that appears before your cursor—you press Tab to accept it, and the suggestion is usually a line or a short snippet of a function. Its working boundary is clear: it stops once it's done guessing, and won't revise itself based on errors. While you struggle repeatedly through a ticket, it's only responsible for guessing the next line.
Agent is completely different. You assign a task in natural language, and it reads the repo, modifies multiple files, and runs tests; if it fails, it looks at the error, makes changes, and tries again until it delivers. The deliverable is often a diff, or directly an opened pull request.
The difference between the two isn't "who's smarter"—it's that the unit of work is different: the unit of completion is a line of code, and the unit of an Agent is a task.
Why the feedback loop matters: A feedback loop refers to the process by which a system adjusts its subsequent behavior based on the results produced by its own actions. In traditional programming, this loop is carried by humans—run the code, look at the error, fix it, run again. The core breakthrough of an Agent is internalizing this loop: after executing a test command it reads stderr, uses that to locate failing test cases, then generates a fix patch and re-verifies. This mechanism depends on three prerequisites: an executable tool environment, a parseable output format, and budget control for multi-round iteration. If any link is missing, the Agent degrades into a "one-shot generator." This also explains why the same model performs vastly differently across products—the gap is often not in the model weights, but in the design quality of the loop and the completeness of the tool ecosystem.
The Core Formula: Agent = Model + Harness
The video gives a formula worth remembering:
Agent = Model + Harness
The model provides intelligence, and the harness provides file reading, command execution, permission control, and the feedback loop. The key to this statement is the second half—without a loop, it's just a single generation; with a loop, it's like a junior engineer doing the work.
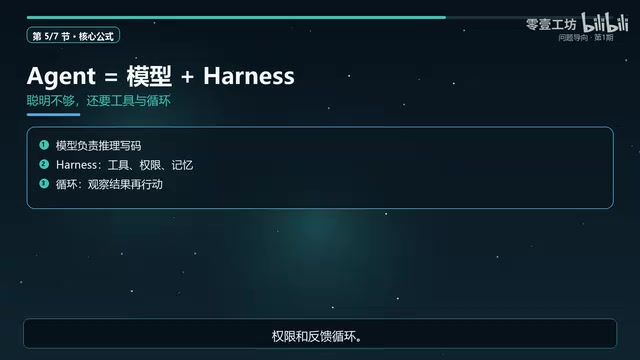
This breakdown explains why "switching to a stronger model" doesn't automatically equal "stronger coding ability." No matter how strong the model is, if the outer layer lacks a harness that reads the repo, executes commands, catches errors, and retries, it remains a one-shot text generator. Conversely, the maturity of the harness determines whether the Agent can truly close the loop: can it read the right files, can it get the tests to pass, can it self-correct after errors.
The origin and meaning of the term Harness: Harness originally referred to horse tack or a safety strap, and in software engineering it's borrowed to mean "the framework layer that wraps and drives a core component." In the context of AI Agents, the model itself is just a function that takes text in and outputs text, while the harness is the entire runtime infrastructure built around it: tool interfaces (reading/writing files, executing shell commands), environment awareness (repo structure, dependencies), state management (multi-turn conversation context), permission sandbox (restricting accessible paths and commands), and most critically the control loop—the iterative mechanism of "generate action → execute → observe result → decide the next step." The industry sometimes also uses scaffold, agent framework, or orchestrator to refer to similar concepts. Understanding this helps grasp: improvements in model capability are gradual, while the presence or absence of a harness is the qualitative dividing line between a "generator" and an "Agent."
How to Choose: It's Not Either-Or
The video's conclusion is very pragmatic: for everyday casual coding, completion is still great—low latency, low distraction, accept and go. But for tasks that need to be delivered—adding features, fixing a series of related files—you should bring in an Agent that can close the feedback loop. In many editors the two can be enabled simultaneously, each handling its own part.
The judgment criterion can be condensed into one sentence: Don't just look at whether you've switched plugins—look at whether it can read the repo, run tests, and fix itself. The one that can close the feedback loop is an Agent; the one that only guesses the next line is still completion.
The Practical Value of This Framework
Classifying AI coding tools by "whether they have a feedback loop" is more explanatory than ranking them by "model parameters" or "completion accuracy." It can also help you ask the right questions when choosing tools: Can this tool read the entire repo? Can it execute test commands? Will it automatically retry after failure? Where are the permission boundaries? The answers to these questions determine far more than "how long the completion suggestion is" whether it can complete the ticket for you.
According to the video's preview, future episodes will compare specific choices among Cursor, Claude Code, and Copilot—worth watching.
One-line Summary
Completion guesses the next line, Agent completes the ticket—the dividing line is whether it has a feedback-loop harness.
Paragraph Summary
The article distinguishes two ways of working for AI coding tools: Completion and Agent. Completion appears as gray ghost text, with a unit of work of a single line of code, stopping once it's done guessing and not self-correcting based on errors; Agent receives tasks in natural language, can read the repo, modify multiple files, and run tests, and after failure looks at the error and revises until it delivers a diff or pull request. The author proposes the core formula "Agent = Model + Harness," emphasizing that the model provides intelligence while the harness provides file reading, command execution, permission control, and the feedback loop—without a loop it's just a single generation, with a loop it's like a junior engineer doing the work. Therefore, switching to a stronger model doesn't automatically mean stronger coding ability. The selection advice is: use completion for everyday casual coding, use Agent for multi-file tasks that need to be delivered, and the two can be enabled simultaneously. The judgment criterion is whether the tool can read the repo, run tests, and fix itself—not just completion accuracy.
Related articles

T3 Code: The Open-Source AI Coding Assistant's Comeback Story
T3 Code is an open-source AI coding assistant that unifies subscriptions like Codex and Claude, with powerful remote control and parallel task management.

Never Elected, Yet Ruled New York for 30 Years: The Ultimate Case Study in the Mechanics of Power
Robert Caro's biographies reveal how unelected Robert Moses ruled New York for 30 years through legal drafting and public authorities, and how Lyndon Johnson built leverage as a "powerless" Senate Majority Leader. Unpacking the underlying logic of accumulating and sustaining power.

The CPython 3.10 Recursion Trap and Synthetic Recovery in TokenGuard, an LLM Circuit Breaker
TokenGuard's author recounts a recursion crash caused by OrderedDict.pop in CPython 3.10 and introduces v0.3.0's Loop Nudge synthetic recovery, inline DLP scanning, and other new LLM agent circuit-breaker capabilities.