DeepSeek V4.1 Flash Released: 552B-Parameter Multimodal Model That's Faster, Cheaper, and More Capable

DeepSeek V4.1 Flash debuts with 552B sparse multimodal architecture, surpassing the previous Pro flagship at lower cost.
DeepSeek has officially released and open-sourced V4.1 Flash, the first Flash-series model with native multimodal (vision) support. Built on a new Causal Encoder-Decoder asymmetric architecture with 552B total parameters — but only 8B/16B activated during inference — it outperforms DeepSeek V4 Pro on benchmarks while cutting KVCache HBM and SSD requirements to 1/4 and 1/8 respectively. The release includes a full ecosystem upgrade (WorkBody, CodeBody, OpenCode, DeepSeek Harness) and merges the app's three modes into one unified experience.
DeepSeek V4.1 Flash Is Now Live
The DeepSeekAd team has struck again, officially releasing and open-sourcing DeepSeek V4.1 Flash, with API access available under the name DeepSeek Flash. Perhaps the most notable highlight of this release compared to previous versions is that the model natively supports visual understanding — marking the Flash series' official entry into the multimodal era.
DeepSeek's naming strategy also reveals its product cadence: Flash is built for speed and accessibility, targeting high-frequency, low-cost everyday inference scenarios, while the more premium V4.1 Pro remains on the roadmap. This "Flash first, Pro to follow" release rhythm is reminiscent of the tiered flagship strategies common across the industry.
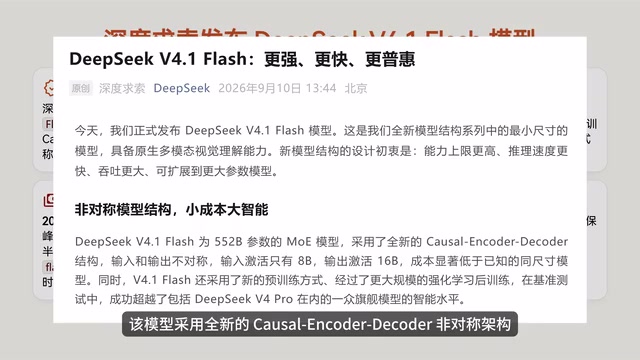
A New Causal Encoder-Decoder Asymmetric Architecture
On the technical side, V4.1 Flash adopts a brand-new Causal Encoder-Decoder asymmetric architecture with a total parameter count of 552B. However, during inference, only 8B parameters are activated on the input side and 16B on the output side.
This "large total, small activation" sparse design is a mainstream approach to cost reduction in today's large model landscape. By invoking only a subset of expert parameters during inference, the model retains the knowledge capacity and intelligence ceiling that come with massive scale, while keeping actual compute overhead extremely low. For a model with 552B total parameters but only a fraction activated, this means inference costs can approach those of small-to-medium models while delivering the capabilities of a much larger one.
Performance: Flash Surpasses the Previous-Generation Pro
The official claim is bold: V4.1 Flash "successfully surpasses the intelligence level of a range of flagship models in benchmark evaluations, including DeepSeek V4 Pro."
This is a striking conclusion. Historically, the Flash series occupied the "economy tier" in DeepSeek's lineup, with Pro being the flagship. The fact that the new-generation Flash can outperform the previous-generation Pro in intelligence metrics speaks to the magnitude of improvements delivered by architectural iteration — and explains why DeepSeek is comfortable routing legacy model traffic through Flash.
KVCache Memory and Storage Requirements Drastically Reduced
Beyond raw intelligence, V4.1 Flash delivers equally impressive system-level optimizations. Compared to the previous generation, the model's KVCache requirements for HBM (High Bandwidth Memory) and SSD have been reduced to one-quarter and one-eighth, respectively.
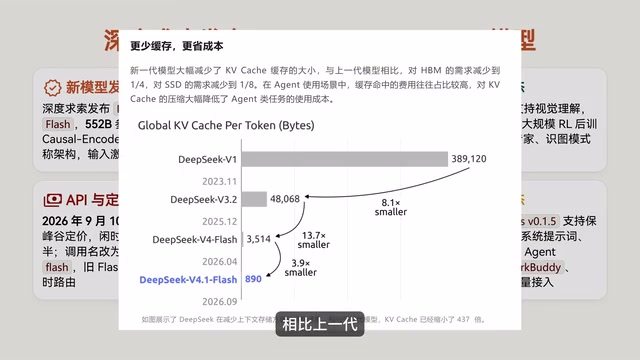
KVCache is the key mechanism for caching attention key-value pairs during large model inference, and it frequently becomes a memory bottleneck in long-context scenarios. Compressing HBM demand to 1/4 and SSD demand to 1/8 directly means a single GPU can handle longer contexts, more concurrent requests, or run on more affordable hardware. This is the engineering backbone behind "faster and more accessible" — it lowers not only the service costs on DeepSeek's end, but also the hardware barrier for open-source deployers.
Pricing Strategy and Model Migration Plan
Alongside the new model launch, updated Flash pricing has taken effect. DeepSeek has also reorganized and migrated legacy models:
- V4 Flash and V4 Flash Vision XP have been deprecated, with the old model names temporarily redirected to the new model;
- From September 14th at 12:00 PM Beijing Time until V4.1 Pro goes live, DeepSeek V4 Pro requests will also be redirected to V4.1 Flash, billed at Flash pricing.
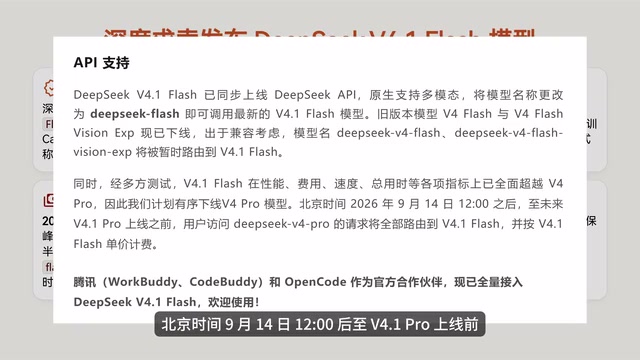
This migration strategy is cleverly designed: since the new Flash already exceeds the old Pro in intelligence, having Flash temporarily handle Pro requests before V4.1 Pro officially launches means users won't experience any capability degradation — they'll actually get a better service at a lower price. For developers, this is a dual win: a price cut and a capability upgrade rolled into one.
Toolchain and Ecosystem Fully Integrated
This release isn't just a model update — DeepSeek has simultaneously upgraded its entire ecosystem toolchain. WorkBody, CodeBody, and OpenCode have all been fully integrated with the new model.
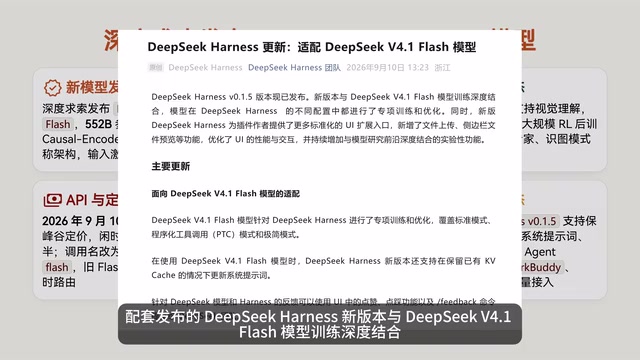
DeepSeek Harness Deeply Integrated with the Model
The newly released DeepSeek Harness has been deeply integrated with the training of V4 Pro and V4.1 Flash, and now supports updating system prompts while retaining KVCache. This feature is particularly valuable for agents, coding assistants, and other applications that require frequent system prompt adjustments. Previously, updating a system prompt typically invalidated the cache and triggered recomputation; now it can be done while preserving the cache, significantly reducing latency and cost in multi-turn interactions.
Three App Modes Merged into One
On the consumer-facing side, the DeepSeek app and web interface have also been simplified. The previously separate fast, expert, and thinking modes have been merged, with the new model providing unified service across all of them. Users no longer need to manually switch between modes — the model adaptively handles tasks of varying complexity. This "simplify the interface" philosophy is closely tied to the new architecture's ability to balance speed and intelligence within a single model.
Summary: What DeepSeek V4.1 Flash Delivers
Taken together, the launch of DeepSeek V4.1 Flash sends several clear signals:
- Architectural breakthrough: Through the Causal Encoder-Decoder asymmetric architecture and sparse activation, it achieves performance that surpasses the previous-generation flagship with significantly lower actual compute;
- Resource optimization: Drastically reduced KVCache demands on HBM and SSD pave the way for long-context inference and low-cost deployment;
- Full-stack upgrade: An integrated update spanning the model, toolchain, and end-user applications reflects DeepSeek's increasingly mature product execution.
With V4.1 Pro on the horizon, DeepSeek's model lineup is set to become even more complete. For developers and everyday users alike, this "smarter, faster, more affordable" upgrade is well worth trying out right away.
Related articles

Build a Reasoning Model from Scratch: An 11-Hour Open-Source Course Breakdown
Sebastian Raschka releases a free 8-episode, ~11-hour video course teaching you to build a reasoning model from scratch with Python and PyTorch—from a small Qwen3 model through Verifier, Inference Time Scaling, GRPO, and distillation, with open-source code on GitHub.

An 11-Hour Reasoning Model Course in Practice: How Small Models Learn to Think
Starting from Sebastian Raschka's 11-hour reasoning model course and HN buzz, this analyzes small-model training, legal text version control, Anthropic data policy, and product reliability reviews.

Lightpanda: A Headless Browser Built for AI and Automation
Lightpanda is a headless browser built from scratch in Zig for AI and automation, with 37,852 GitHub stars. This analysis covers its technical approach, design choices, and use cases.