FlexCast: Decoupling Autoregression — A New Paradigm for Time Series Foundation Models
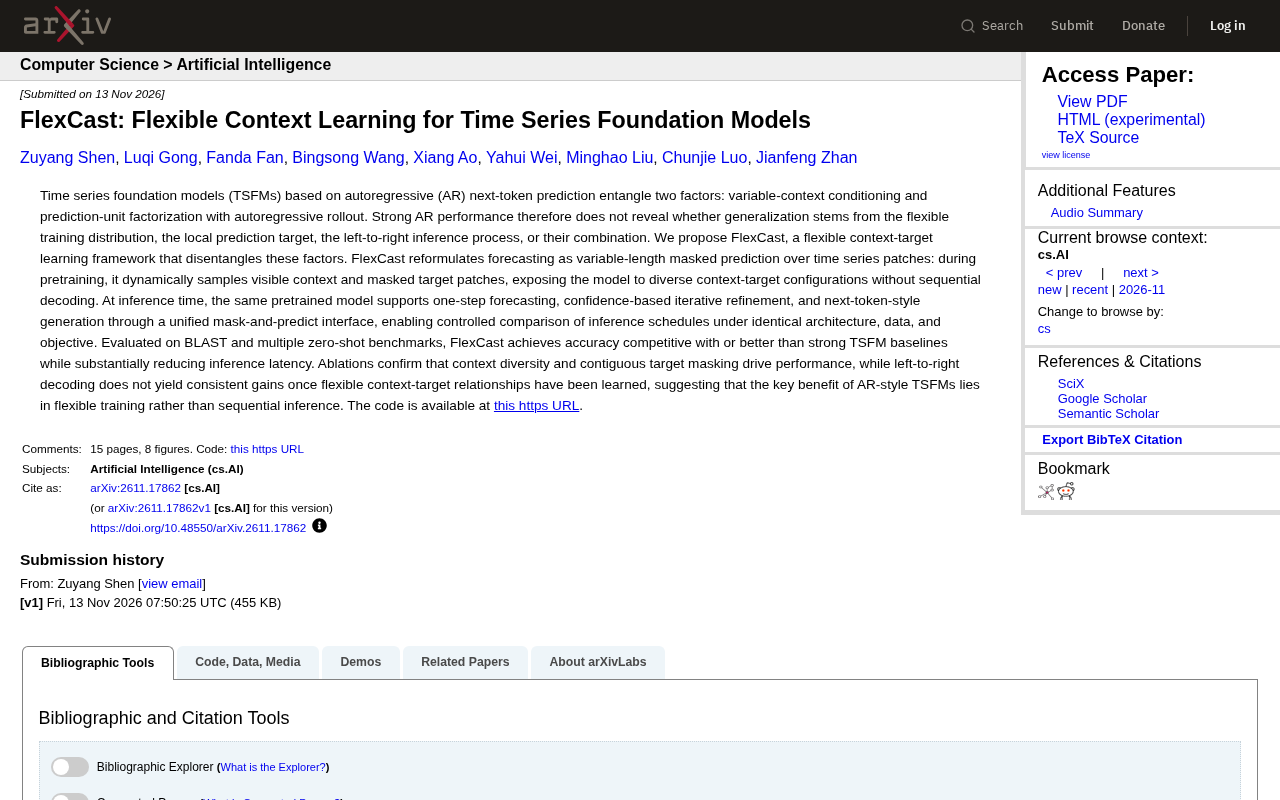
FlexCast decouples the three factors of autoregression, showing flexible training—not sequential decoding—drives TSFM performance.
FlexCast decomposes the autoregressive paradigm of time series foundation models into variable context conditioning, prediction unit decomposition, and autoregressive rollout, replacing sequential generation with variable-length masked prediction. On BLAST and zero-shot benchmarks, it matches or beats strong baselines with significantly lower inference latency, and ablations confirm context diversity and contiguous target masking drive gains.
The autoregressive (AR) paradigm for time series foundation models (TSFMs) has long been regarded as the performance benchmark, but a new study raises a sharp question: does AR's power come from flexible training distributions, local prediction objectives, or the left-to-right inference process? The FlexCast framework decouples these factors and delivers a counterintuitive answer — sequential decoding is not the key; flexible training is the source of performance.
The "Black Box" of Autoregression: Three Entangled Factors
Most current TSFMs are built on autoregressive next-token prediction. This design bundles three factors together: variable context conditioning, prediction unit decomposition, and autoregressive rollout. When a model performs well, researchers cannot tell whether the credit belongs to the flexible training distribution, the local prediction objective, or the left-to-right inference process itself.
This entanglement creates a practical dilemma: to improve model generalization, must autoregressive decoding be retained? Or is it enough to borrow its training strategy? FlexCast's starting point is precisely to open this black box and subject each factor to independent testing.
Autoregressive rollout refers to the process in which a model repeatedly feeds its own predictions as input for the next step during inference, gradually generating a complete sequence. In time series foundation models, this mechanism typically manifests as left-to-right prediction token by token or patch by patch, with each step depending on all prior outputs. The core risk of rollout is error accumulation: deviations in early steps propagate along the generation chain and amplify, leading to unstable long-range forecasts. Meanwhile, rollout forces inference to be executed serially, making it difficult to parallelize and thus driving up latency. FlexCast decouples rollout from the training distribution and prediction objective precisely to test whether this sequential generation process itself contributes to performance, rather than being merely a byproduct of the training strategy.
FlexCast's Core Mechanism: Masked Prediction Replaces Sequential Generation
FlexCast reframes the prediction task as variable-length masked prediction over time series patches. During pretraining, the model dynamically samples visible context and masked target patches, thereby encountering diverse "context-target" configurations without relying on sequential decoding.
At inference, the same pretrained model supports three modes through a unified "mask-predict" interface: one-step prediction, confidence-based iterative refinement, and next-token-style generation. This design enables controlled comparison of different inference strategies under the same architecture, data, and objective — something difficult to achieve in traditional AR frameworks.
Variable-length masked prediction draws on the idea of masked language modeling but adapts it for time series patches: in each pretraining step, the model randomly selects several contiguous patches as prediction targets and the remaining patches as visible context, with both mask length and position varying dynamically. This design forces the model to learn to infer any missing patch from any visible context, rather than merely fitting a fixed "history-to-future" mapping. Compared with fixed masking, variable-length masking covers a range of difficulties from short-range interpolation to long-range extrapolation, bringing the training distribution closer to the diverse missingness patterns in real applications. FlexCast's ablation experiments show that it is precisely this contiguous target masking together with context diversity that constitutes the main source of performance gains.
Experimental Performance: On-Par or Better Accuracy, Substantially Lower Latency
Evaluations on BLAST and multiple zero-shot benchmarks show that FlexCast's accuracy is comparable to or even better than strong TSFM baselines, while inference latency is significantly reduced. Ablation experiments further confirm that context diversity and contiguous target masking are the main drivers of performance gains.
More notably, once the model has learned flexible context-target relationships, left-to-right decoding does not yield consistent gains. This finding directly challenges the default assumption that "sequential inference is the source of AR models' advantage" and points to a simpler conclusion: the core value of AR-style TSFMs lies in flexible training, not sequential inference.
BLAST is a commonly used collection of zero-shot benchmarks for evaluating time series foundation models, covering multiple domains and forecasting horizons to test model generalization on unseen datasets. Zero-shot evaluation means the model is not fine-tuned on downstream data at all and predicts directly in its pretrained state, placing extremely high demands on the flexibility of the training distribution. FlexCast's performance on BLAST and multiple zero-shot benchmarks essentially verifies that the generalization advantage brought by a flexible training distribution can exist independently of autoregressive decoding. This also explains why, under the same architecture and data, non-sequential inference modes such as one-step prediction and iterative refinement can match or even exceed the accuracy of autoregressive baselines.
Implications for Time Series Foundation Models
FlexCast's significance goes beyond being just a new framework. It offers a methodology: when a modeling paradigm becomes popular, it is necessary to decompose its success factors and avoid mistaking irrelevant design choices for necessary conditions. For TSFM practitioners, this means that when pursuing stronger generalization, they may not need to bear the complexity and latency costs of autoregressive decoding.
The research code is open-sourced on GitHub (BenchCouncil/FlexCast), providing a basis for subsequent reproduction and extension. The evolution of time series foundation models may be shifting from "stacking autoregression" to a new stage of "flexible in-context learning."
One-line Summary
FlexCast decouples the three factors of autoregression, proving that flexible training rather than sequential decoding is the source of TSFM performance.
Paragraph Summary
FlexCast decomposes the autoregressive paradigm of time series foundation models into three entangled factors — variable context conditioning, prediction unit decomposition, and autoregressive rollout — and replaces sequential generation with variable-length masked prediction. During pretraining, it dynamically samples visible context and masked target patches; at inference, the same model supports one-step prediction, confidence-based iterative refinement, and next-token-style generation. On BLAST and multiple zero-shot benchmarks, FlexCast matches or exceeds strong baselines in accuracy while significantly reducing inference latency. Ablations show that context diversity and contiguous target masking are the main drivers of performance, with no consistent gain from left-to-right decoding. The study concludes that the core value of AR-style TSFMs lies in flexible training, not sequential inference, and the code is open-sourced.
Related articles
GLM 5.5 Arrives: Has Claude Cracked the 167-Year-Old Riemann Hypothesis?
Claude and a mathematician claim to have proved the 167-year-old Riemann Hypothesis, Zhipu's GLM 5.5 is imminent, Google's Loop agent surfaces, and Thinking Machines open-sources Inkling 2 Mini.
AI Coding Made Building Cheap, but Not Maintenance
AI coding agents make internal tools cheap to build but not to maintain. This article examines the hidden liabilities of tool sprawl and proposes three governance principles: inventory, ownership, and reuse first.
Microsoft SideWinder Strategic Commander: A Failed Innovation Attempt
A review of Microsoft's SideWinder Strategic Commander gaming peripheral: its design intent, usability flaws, and market positioning, and why peripheral innovation must respect user habits.