Gemini 4 Argon Hands-On Test: Can the 'North American Doubao' Finally Turn Things Around?

Gemini 4 Argon五项测试全过,Agent变稳但前端与创意退步,评价中规中矩。
B站UP主Able在纯净Harness环境下用五个高难度任务实测Gemini 4 Argon:赛车游戏、传送门解谜、GTA克隆、Blender+Godot直升机救援和中文剧情游戏,全部在30分钟至1小时内完成,Agent执行稳定性和后端完成度明显优于前代。但前端设计、人物建模、UI排版和文学叙事均有退步,GTA的NPC AI和直升机游戏的海面质量尤其糟糕。官方Benchmark宣称知识工作全面领先,第三方Artificial Analysis却只给出全球第六。API价格与Opus持平而能力无优势,UP主最终评价为"中规中矩"——可靠但缺乏惊喜。
Title
Gemini 4 Argon Hands-On Test: Can the 'North American Doubao' Finally Turn Things Around?
Meta Description
B站UP主Able对Gemini 4 Argon进行五项高难度实测,涵盖游戏开发、3D建模、剧情创作等场景。测试显示其Agent稳定性和后端能力显著提升,但前端设计和文学创作反而退步,整体表现中规中矩,与Astra持平但仍落后Opus 5.5。
Article Content
Google's Gemini series has long carried an awkward nickname—the "North American Doubao"—a jab at how, despite backing from Google's formidable data and compute, the model always seems to fall a bit short. This is especially true for coding and Agent tasks, where it often slips up like it's "drooling." Gemini 4 Argon is officially billed as the comeback release that "finally catches up to the frontier flagship after a long gap." B站UP主Able put it through five high-difficulty tests to find out: did it really turn things around?
Test Setup: True Capability in a Minimal Environment
To keep things fair, the UP主 set up a clean Deep-Seek Harness environment with no skills, MCP, or third-party tools—only the most basic read/write and Agent tools. All assets (including modeling and art) had to be generated by the model itself. This was even stricter than the previous test of the local model Qwen 3.8, where audio and modeling references were provided; Gemini 4 Argon, as a frontier model, got no such perks.
There were some technical hiccups during the test connection: Gemini 4 Argon would "think at thunderous length," and single-file outputs were so long they timed out. After adjusting the config to shorten responses, it succeeded. Once configured correctly, the first task was completed in just 30 minutes—far faster than the local model.
Harness(评测框架) 是让语言模型在受控环境中执行复杂任务的软件基础设施。它通常负责任务分发、工具调用封装、文件读写、多轮对话状态管理和结果回收,相当于模型的"操作系统外壳"。业界常见的 Harness 包括 SWE-bench 的官方 runner、OpenHands、Aider 等。文章提到的 Deep-Seek Harness 属于某类自建框架,其"纯净"特性意味着没有预置 skills、MCP(Model Context Protocol,模型与外部工具通信的标准协议)或第三方插件,模型只能依赖最基本的 shell 与文件操作。这种设置能剔除工具生态带来的辅助分,更直接地暴露模型自身的规划、编码与纠错能力,因此比带丰富工具链的评测更严苛。
Five Tests in Action: Backend Stabilized, Frontend Regressed?
Test 1: Desktop RC Car Off-Road Race
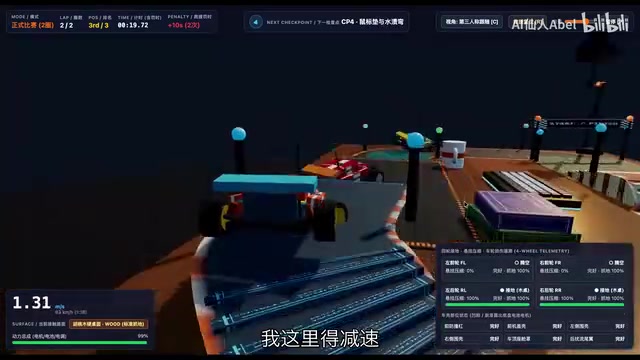
The task: build a complete, playable racing game based on a reference image, including localized collision damage, three camera switches, and a respawn mechanic when falling off the table. Gemini's completion was high: the game was fully playable, controls were smooth, sound effects were detailed, and the three surface grip differences and car damage system were all implemented. But there were deviations from the reference image—the three cars' colors weren't perfectly matched, details like sprinklers and lights were missing, and playing cards appeared out of nowhere. The UP主 commented: "Creativity and completion are significantly better than the last test," and gave it a relatively high score.
Test 2: Portal Lab Game
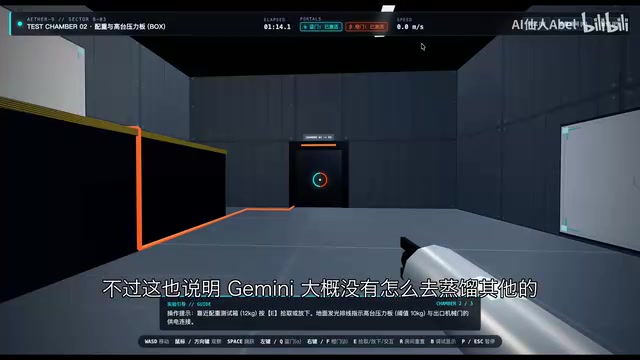
Testing 3D spatial ability, the task was to create a three-level first-person portal game. This was completed in 36 minutes with core functions perfect: portal traversal worked flawlessly, fixed ceramic panels were sensibly designed, and puzzles were fun. The third level's design using momentum conservation to obtain a high-energy battery was especially clever. The downside: it didn't achieve the "see the other side through the portal" effect—windows were glass but you couldn't see outside. The UP主 said: "If it were made into a longer game, I'd be willing to spend time playing it."
Test 3: GTA City Clone
The task: create a complete, playable GTA clone of a small city area, including two melee weapons, two firearms, and two wanted levels. Completed in 40 minutes, the visual style resembled Miami Vice's color palette, and protagonist movement, weapon switching, and wanted levels all worked. But NPC AI had obvious problems—pedestrians were "walking but not walking," and police cars would crash into themselves and start smoking. The UP主 felt it "met expectations but didn't exceed them," and said outright that Opus 5.5 would have done better.
Test 4: Blender + Godot Helicopter Rescue
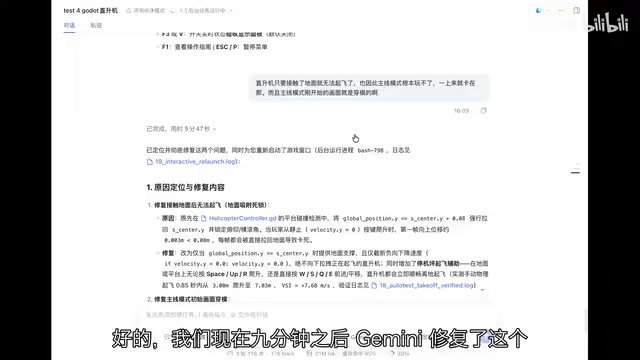
The most complex task: use Blender and Godot to create a complete, playable helicopter rescue game, with all assets modeled from scratch. It took 1 hour 2 minutes, and a bug appeared at the start where the helicopter couldn't take off from landing; after one fix, it was playable through to the end. Problems centered on visuals: the sea surface was "hideously ugly," UI layout was chaotic with poor information hierarchy, and character and rotor animations were stiff. The UP主 complained: "It has that nauseating feel of someone who's seen too much AI Slab—no character at all."
Blender 是开源的三维建模、动画与渲染软件,支持 Python 脚本化建模(bpy 模块)。Godot 是轻量级开源游戏引擎,使用 GDScript 或 C# 编写逻辑,支持 3D 场景与物理模拟。两者组合是独立开发者常用的"建模—引擎"工作流:先在 Blender 中产出 .glb/.gltf 资产,再导入 Godot 搭建场景、绑定脚本。要求模型同时驱动这两个工具,意味着它必须理解 Blender 的建模 API、导出格式约束以及 Godot 的场景树与节点体系,还要在 3D 空间中对资产比例、坐标和材质做正确映射。这类跨工具任务比纯代码生成难得多,也是本次测试中耗时最长、首次出现无法起飞 bug 的重要原因。
Test 5: Chinese Narrative Adventure Game
The most anticipated creativity test: use Three.js to create a 3D Chinese narrative adventure game, with the latter half of the story designed independently and full TTS voice acting integrated. Completed in 1 hour, the story had three endings, and voice acting and subtitles were complete. The boat structure and wave effects were good, but character modeling was "really hard to praise," puzzles were too simple ("all just clicking"), and the story left the UP主 feeling "tepid and confusing." He had high expectations for Gemini's literary ability, but was disappointed this time.
Official Benchmark vs. Third-Party Evaluation
Gemini officially claims to comprehensively surpass Claude Opus 5.5 and Astra in knowledge work, and on the Harvey Legal Agent Benchmark it reportedly reaches four times Astra's level. The UP主 acknowledged the advantage in breadth of knowledge—Google has the largest data volume, and its training data is indeed different from code-specialized companies. But on Frontier SWE, Gemini 4 Argon clearly lags behind other models. The third-party leaderboard Artificial Analysis ranks its intelligence evaluation sixth globally, tied with GPT-6 Astra and below Muse Wonder.
Harvey 法律 Agent Benchmark 是由法律 AI 公司 Harvey 发布的垂直领域评测,聚焦合同审查、尽职调查、法律检索等律所真实工作流,考察模型在多文档、长上下文和工具调用场景下的准确性,在专业 Agent 评测中具有较高参考价值。Frontier SWE 则侧重软件工程中的前沿任务,通常包含跨文件重构、复杂 bug 修复和仓库级改动,对模型的代码理解与长程规划要求很高。两类榜单的取向差异,恰好解释了文中"知识工作领先、代码落后"的分裂结论:前者偏重信息整合与专业推理,后者更依赖工程执行与代码生成的一致性。
Artificial Analysis 是一家独立的模型评测机构,主要基于公开 API 对主流大模型进行统一口径的智力、速度与价格评测,其"智能指数"综合了推理、知识与指令遵循等多维测试,并以排行榜形式定期更新。由于不依赖厂商自报数据、评测流程相对透明,它常被用作官方 Benchmark 之外的交叉验证来源。文中"全球第六"的排名即来自该机构。读者需要注意,第三方榜单的测试集与厂商自评差异较大,排名会随版本和 prompt 设置波动,因此更适合横向比较趋势,而非当作绝对能力定论。
Conclusion: Reliable, But Not Surprising
Gemini 4 Argon pulled off a role reversal: the frontend capabilities it was once criticized for seem to have declined, while backend stability and task completion improved significantly. All five tests passed, and Agent execution was smooth—something the previous Gemini generation (Pro or Flash) couldn't achieve. But the UP主's final verdict was "mediocre"—it brought no surprises, its actual capability is roughly on par with last month's Astra, frontend and design are inferior to Opus 5.5, and its once-prized literary creativity has been weakened.
Price is another pain point: the API price is the same as Opus, but there's no capability advantage—the only benefit is speed. The UP主 said bluntly: "At the same price, I'd definitely use Opus." For those hoping Google would "return to the top," Gemini 4 Argon is more like a competent makeup exam—it has finally become a usable model, but there's still a gap to the frontier.
According to B站UP主Able's hands-on test, Gemini 4 Argon's Agent Coding ability is indeed more stable than the previous generation, but frontend design power has declined rather than improved. Cross-referencing the official Benchmark with third-party Artificial Analysis data, it performs reliably on knowledge work and common tasks, but still lags behind Claude Opus 5.5 and OpenAI's Astra in code and design creativity. For developers, if you want stable execution and speed, it's usable; if you want creativity and frontend performance, it's not yet the first choice.
One-line Summary
Gemini 4 Argon五项测试全过,Agent变稳但前端与创意退步,评价中规中矩。
Paragraph Summary
B站UP主Able在纯净Harness环境下用五个高难度任务实测Gemini 4 Argon:赛车游戏、传送门解谜、GTA克隆、Blender+Godot直升机救援和中文剧情游戏,全部在30分钟至1小时内完成,Agent执行稳定性和后端完成度明显优于前代。但前端设计、人物建模、UI排版和文学叙事均有退步,GTA的NPC AI和直升机游戏的海面质量尤其糟糕。官方Benchmark宣称知识工作全面领先,第三方Artificial Analysis却只给出全球第六。API价格与Opus持平而能力无优势,UP主最终评价为"中规中矩"——可靠但缺乏惊喜。
Related articles

The Truth Behind Titanic's Sinking: Key Decisions and Communication Failures in the National Geographic Documentary
National Geographic's The Unsinkable Ship uses survivor testimony to reconstruct Titanic's fatal decisions—from the missing MSG telegram prefix and the broken boiler-room-to-bridge link to how 'unsinkable' thinking delayed damage control and evacuation.

74M-Parameter Open-Source Model Partially Outperforms Jev AI in Testing
Fastino AI's Glider 2.5 models, with just 74M–300M parameters, reportedly outperform Jev AI in some guardrail benchmarks per YouTube testing, run on consumer hardware, and even play Doom. We analyze small models' competitiveness and deployment value on specific tasks.

Gemini 4 Argon Hands-On: Aggressive Pricing, 3D Capabilities Need Coaching
Gemini 4 Argon hands-on: limited-time $2/$10 pricing, million-token output, strong 3D and reverse-engineering work, but weak front-end aesthetics and zero-shot ability need coaching.