GLM-4.6 Flash Hands-On: Does It Really Outperform DeepSeek on Value?
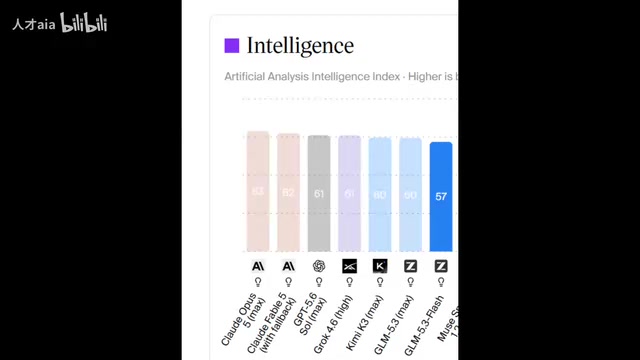
GLM-4.6 Flash offers compelling promo pricing, but long-term costs and real-world performance still need careful evaluation.
Zhipu AI's GLM-4.6 Flash positions itself with near-flagship capability at aggressive promotional pricing — currently undercutting DeepSeek Flash at peak hours, though pricier during off-peak periods. The model scores well on "Pareto frontier" value-efficiency charts, but third-party benchmark rankings don't always reflect real business use cases. Zhipu also leaned into meme culture with community-driven marketing, signaling a broader industry shift. Verdict: worth testing during the promo window, but evaluate total cost and actual fit before committing.
Zhipu's New Model Claims to Be "Cheaper and More Capable"
Zhipu AI recently launched GLM-4.6 Flash, a new lightweight model centered around one core selling point: cost-effectiveness. According to a review video on Bilibili, this Flash-tier model delivers performance that rivals mainstream flagship models while maintaining an extremely low price — and in some dimensions, it reportedly matches or even surpasses both the Flash and Pro versions of DeepSeekAd.
For those who've been watching China's domestic LLM price wars, this signals yet another round of aggressive cost competition. Over the past two years, ever since DeepSeek ignited the low-price trend, domestic model vendors have been locked in a constant tug-of-war between capability and cost. Zhipu's strategy this time is clear: near-flagship performance at a price far below the competition.
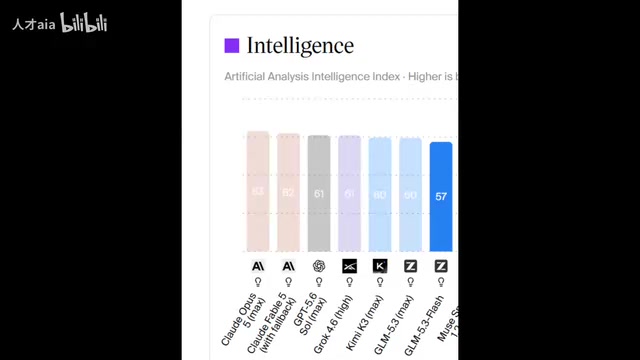
Based on the capability rankings shown in the review, this Flash model holds its own against a wide range of mainstream models in the market. It's worth noting that "Flash" typically refers to a vendor's lightweight, low-latency variant, designed for high-concurrency, cost-sensitive applications. Achieving near-flagship performance at this tier is genuinely noteworthy.
GLM-4.6 Flash Pricing Strategy: The Real Cost Behind a 50% Discount
The biggest highlight mentioned in the video is that the model is currently in an official promotional phase — offered at roughly half its standard price. Using AI-assisted calculations, the reviewer concluded that at this promotional rate, GLM-4.6 Flash is cheaper than DeepSeek Flash, and even undercuts DeepSeek's peak-hour API costs.
However, one detail deserves an objective look: the reviewer himself acknowledged that this is a promotional price. During off-peak hours, GLM-4.6 Flash is actually slightly more expensive than DeepSeek. In other words, this pricing advantage depends heavily on the current promotion — users planning long-term costs need to factor in the regular pricing once the discount ends.
This is a typical pattern in the LLM price wars: vendors use time-limited promotions to quickly capture market share and mindshare. But the true long-term cost of usage must account for call timing, concurrency levels, cache hit rates, and other variables. Focusing solely on a "half-price" deal can be misleading.
Does the "Best Value" Claim Actually Hold Up?
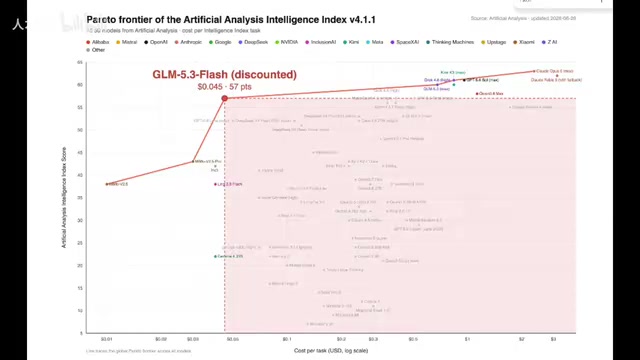
The video references a "value-for-money leaderboard" concept — essentially comparing models that are either cheaper but less capable, or equally capable but more expensive. Within this framework, GLM-4.6 Flash reportedly "demolishes" (the video's exact word was "斩杀", meaning "slays") competitors in the same price range, earning it the title of "the most cost-effective model available right now."
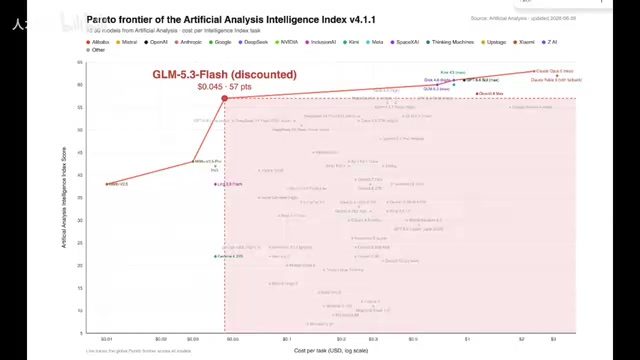
This "Pareto frontier of value" analysis essentially plots models on a two-dimensional capability-vs-price chart, identifying which ones deliver the most capability per dollar, or the lowest price for a given capability level. From that perspective, GLM-4.6 Flash does occupy a notably favorable position.
That said, it's worth pointing out that these rankings typically come from third-party benchmark platforms (the video references the "AA榜" leaderboard) and may not reflect real-world business performance. There's often a gap between what benchmark tasks measure and what your actual use case demands. Whether it's truly right for your application is something only hands-on testing can confirm.
The "Milk Meme" Moment: Zhipu Leans Into Community Culture
Toward the end of the video, there's an amusing detail worth mentioning: a popular internet meme about a "milk model" had been circulating online, and Zhipu apparently noticed the buzz. The company rolled out a version with a related name (referred to in the video as "OX"), actively joining in on the joke.
This reflects a broader shift in how Chinese LLM vendors approach marketing — moving away from pure technical metrics toward more grassroots community engagement and meme culture. By playing along with user humor and generating conversation, vendors can achieve significant organic reach at minimal cost. In an increasingly commoditized competitive landscape, this kind of cultural differentiation is becoming more and more common.
Bottom Line: GLM-4.6 Flash Is Worth Trying — Just Don't Judge by the Promo Price Alone
Overall, GLM-4.6 Flash's core appeal lies in the combination of near-flagship capability and an attractive promotional price. For cost-conscious developers and enterprise users prioritizing value, it's genuinely worth testing during this current promotional window.
But a rational assessment should include the following considerations:
- Promo pricing ≠ long-term cost: The half-price discount will eventually end, and off-peak usage may actually cost more than DeepSeek;
- Leaderboard rankings are a reference, not a verdict: Third-party benchmarks don't always align with real-world performance — always validate with your own use case;
- "Slaying DeepSeek" is marketing language: Both models have their own strengths and applicable scenarios; neither completely dominates the other.
The LLM competition has entered a new phase of nuanced cost-efficiency optimization. Rather than being swayed by a single promotional slogan, it's worth doing a multi-dimensional evaluation based on your actual application scenario, call frequency, and budget — and finding the model that truly fits your needs.
Related articles

Build a Reasoning Model from Scratch: An 11-Hour Open-Source Course Breakdown
Sebastian Raschka releases a free 8-episode, ~11-hour video course teaching you to build a reasoning model from scratch with Python and PyTorch—from a small Qwen3 model through Verifier, Inference Time Scaling, GRPO, and distillation, with open-source code on GitHub.

An 11-Hour Reasoning Model Course in Practice: How Small Models Learn to Think
Starting from Sebastian Raschka's 11-hour reasoning model course and HN buzz, this analyzes small-model training, legal text version control, Anthropic data policy, and product reliability reviews.

Lightpanda: A Headless Browser Built for AI and Automation
Lightpanda is a headless browser built from scratch in Zig for AI and automation, with 37,852 GitHub stars. This analysis covers its technical approach, design choices, and use cases.