GLM-5.3 Weights Released: 744B MoE Giant Model with vLLM Day-0 Support
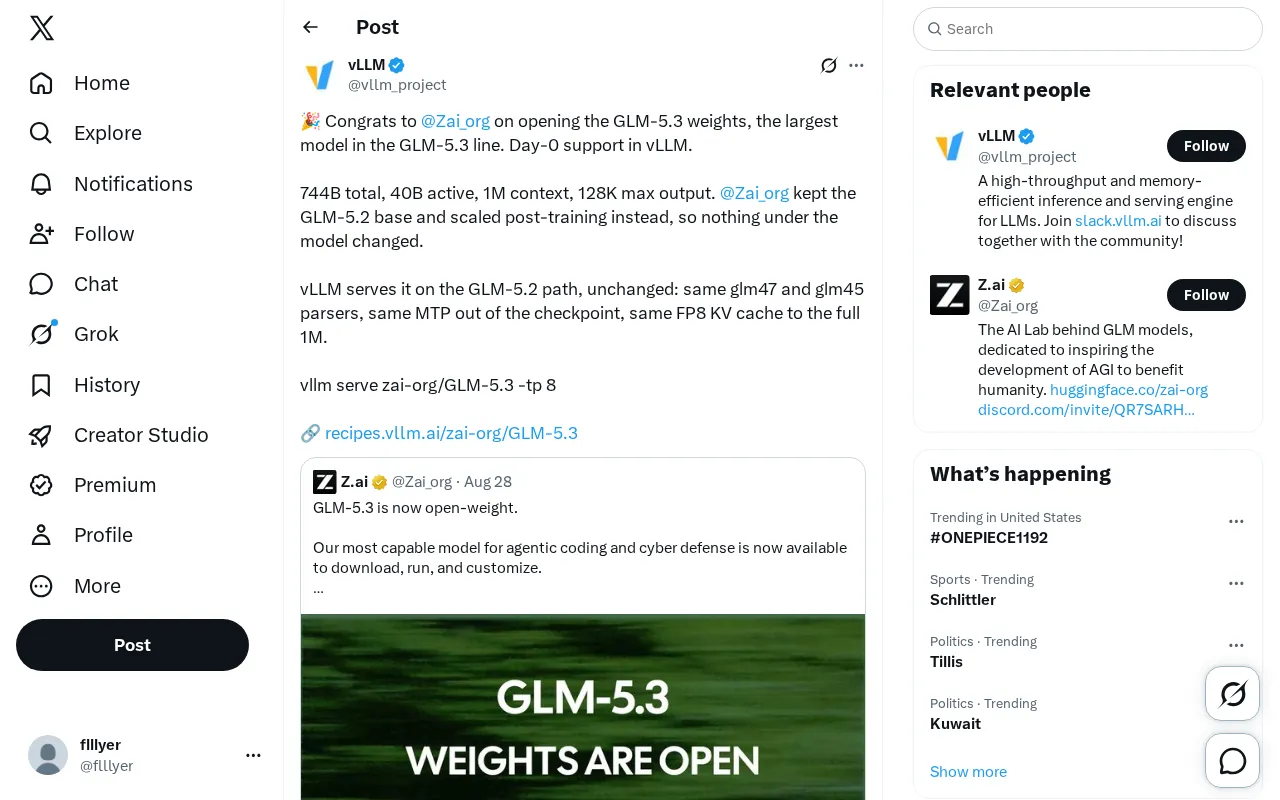
Zhipu open-sources GLM-5.3, a 744B MoE model built on the GLM-5.2 base with vLLM Day-0 support.
Zhipu has officially open-sourced GLM-5.3, a sparse MoE model with 744B total parameters and 40B activated parameters, supporting up to 1M token context. The key strategy was retaining the GLM-5.2 pre-trained base and scaling only the post-training stages (SFT/RLHF/DPO), delivering capability gains at lower cost while keeping the inference path unchanged — enabling vLLM Day-0 support. FP8 KV cache halves memory overhead, making million-token context feasible on multi-GPU setups.
GLM-5.3 Weights Go Open Source: Zhipu Releases 744B Giant Model
Zhipu (Zai_org) has officially open-sourced the GLM-5.3 model weights, representing the largest model in the GLM-5.3 series. What makes this release particularly notable is that the popular inference framework vLLM offers Day-0 support, meaning developers can seamlessly deploy and run the model on the very day it launched.
The publicly disclosed specifications are impressive:
- Total parameters: 744B (744 billion)
- Activated parameters: 40B (40 billion)
- Context length: Up to 1M (1 million tokens)
- Maximum output: 128K tokens
The combination of 744B total parameters with only 40B activated parameters makes it clear this is a sparse MoE (Mixture of Experts) architecture. This design gives the model a massive knowledge capacity while keeping inference costs relatively manageable — only about 5.4% of parameters are activated per forward pass.
Keeping the Base, Scaling Post-Training
One notable technical detail in this release: Zhipu did not retrain the model's base. Instead, they retained the GLM-5.2 base and focused on extending and reinforcing the post-training stage.
As stated in the original announcement: "@Zai_org kept the GLM-5.2 base and scaled post-training instead, so nothing under the model changed."
There's a clear engineering rationale behind this strategy.
Advantages of Reusing the Base
Pre-training a model at the 744B scale is extraordinarily expensive, requiring massive compute and data resources. If the GLM-5.2 base already has strong foundational capabilities, investing additional effort in post-training stages — such as SFT, RLHF, and DPO — can deliver significant capability gains at a fraction of the cost.
This reflects a broader trend in the large model race: the focus is gradually shifting from "scaling pre-training" to "optimizing post-training quality." As base model capabilities approach saturation, improvements in alignment, reasoning, and instruction following during post-training become the key differentiators.
Direct Benefits for Inference and Deployment
Because the underlying architecture is unchanged, GLM-5.3 can fully reuse GLM-5.2's inference path — clearing the way for immediate toolchain support.
vLLM Day-0 Support: GLM-5.3 Inference Deployment in Detail
The vLLM team has confirmed that GLM-5.3 runs directly through GLM-5.2's inference path in vLLM, with no changes required. Specifically:
- Same parsers: Reuses the glm47 and glm45 parsers
- Same MTP: Multi-Token Prediction configuration is read directly from the checkpoint
- Same FP8 KV cache: Supports full 1M context
For developers, the deployment command is refreshingly simple:
vllm serve zai-org/GLM-5.3 -tp 8
The -tp 8 flag specifies 8-way Tensor Parallelism, which also hints at the multi-GPU hardware requirements for running a 744B model.
How FP8 KV Cache Enables Million-Token Context
FP8 KV cache support up to the full 1M context is one of GLM-5.3's key capabilities. One of the biggest bottlenecks in long-context inference is that KV cache VRAM usage grows linearly with sequence length. Storing the KV cache in FP8 precision dramatically reduces memory overhead — roughly half compared to FP16 — which is the core technical enabler for making million-token context practical in real deployments.
Combined with the MTP (Multi-Token Prediction) mechanism, GLM-5.3 is well-positioned for tasks like long-document summarization and ultra-long document analysis.
What GLM-5.3's Open Source Release Means for the Community
The release of GLM-5.3 weights, paired with Day-0 support from a mainstream inference framework, reflects a growing maturity in the open-source ecosystem around Chinese-developed large models. For developers and enterprises, this means:
- Ready to use immediately: No waiting for community adaptation — deployable in production on launch day
- Manageable inference costs: MoE sparse activation + FP8 optimization dramatically lowers the barrier to running an ultra-large model
- Top-tier scale: 744B total parameters places it among the largest open-source models currently available
For enterprises and research institutions looking to run very large models on their own infrastructure, GLM-5.3 offers a compelling combination of parameter scale, long-context capability, and engineering accessibility.
Summary
The release of GLM-5.3 is less a debut of an entirely new model and more a textbook example of capability uplift driven by post-training. By reusing the GLM-5.2 base and concentrating investment in post-training, Zhipu managed to control R&D costs while ensuring seamless toolchain compatibility. vLLM's Day-0 support and FP8 long-context optimization are what make this 744B MoE model genuinely viable for real-world engineering deployment.
Note: The information above is primarily sourced from vLLM's official announcements on social platforms. Some technical details — such as specific benchmark results — are still pending official disclosure and community verification.
Related articles

Data Scraping, AI Proofs, and Open Source Contracts: This Week's Deep Dive into the Tech World
From the 3D model crawler controversy and OpenAI's Lean formal proofs to AI agents challenging Brooks' Law and Debian rejecting LLM review, this week's tech discussions center on openness and verifiability.

Build a Reasoning Model from Scratch: An 11-Hour Open-Source Course Breakdown
Sebastian Raschka releases a free 8-episode, ~11-hour video course teaching you to build a reasoning model from scratch with Python and PyTorch—from a small Qwen3 model through Verifier, Inference Time Scaling, GRPO, and distillation, with open-source code on GitHub.

An 11-Hour Reasoning Model Course in Practice: How Small Models Learn to Think
Starting from Sebastian Raschka's 11-hour reasoning model course and HN buzz, this analyzes small-model training, legal text version control, Anthropic data policy, and product reliability reviews.