Mac Studio M5 Ultra 512GB Pricing Sparks Debate: Is $22,299 Worth It?
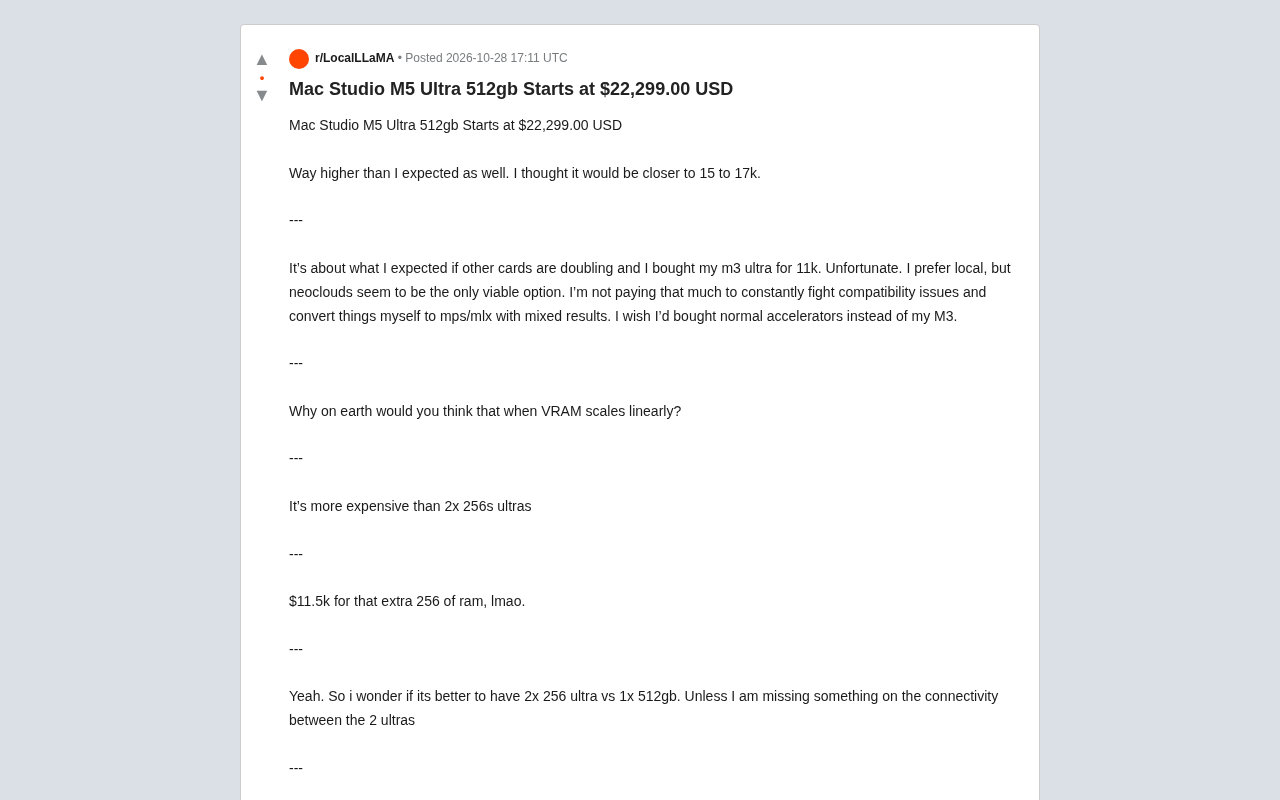
Mac Studio M5 Ultra 512GB at $22,299 far exceeds expectations, sparking community doubts about Apple's AI workstation pricing and ecosystem.
The Reddit community is hotly debating the $22,299 price of the Mac Studio M5 Ultra 512GB, far above users' expected $15k-$17k range. Discussion focuses on Apple's linear pricing logic: upgrading from 256GB to 512GB costs about $11.5k more, even higher than the total price of two 256GB versions. Some users point out that single-machine interconnect speed is the core advantage of the 512GB version, but it only has practical meaning for models requiring over 200GB of memory. An M3 Ultra user expressed disappointment with poor compatibility in local AI deployment and regret over not choosing a regular accelerator card. Overall, the community believes this pricing pushes the top configuration into luxury territory, while the professional users who truly need it are precisely the most cost-sensitive.
Pricing Far Exceeds Expectations, Community Erupts
A recent Reddit post about the pricing of the Mac Studio M5 Ultra 512GB version has sparked heated discussion. According to the post title, this configuration starts at $22,299. The original poster stated bluntly: "Way higher than I expected too, I thought it would be around 15k to 17k."
This price quickly ignited community discussion. For a desktop workstation aimed at professional workloads, the $22,299 threshold is clearly not something ordinary users would consider, but even price-insensitive professional users are beginning to re-examine whether Apple's pricing strategy is still reasonable.
Long-time User Disappointment: From M3 Ultra to M5 Ultra
A user who already purchased the M3 Ultra (spending $11k) expressed mixed emotions. He mentioned that if other configurations are doubling in price, then this price is "roughly within my expectations," but he still feels regretful.
More critically, his user experience: "I prefer running locally, but neoclouds seem to be the only viable option. I don't want to spend that much money and constantly struggle with compatibility issues. Converting to MPS/MLX myself has also yielded inconsistent results. I really wish I had bought a regular accelerator card instead of the M3."
This passage points out the core pain point of Apple Silicon in AI workloads: while the unified memory architecture is attractive, the software ecosystem's compatibility and toolchain maturity still leave many professional users frustrated.
Unified Memory Architecture (UMA) is one of the core designs of Apple Silicon chips. The CPU, GPU, and neural engine share the same physical memory pool, eliminating the need to copy data between system memory and VRAM as in traditional discrete graphics solutions. This architecture has a natural advantage in large model inference scenarios: model weights only need to be loaded once and can be accessed by all compute units, theoretically supporting models far exceeding discrete GPU VRAM capacity. However, the trade-off is that memory capacity is tied to the chip package, users cannot upgrade it themselves, and Apple's pricing for memory capacity is far above market average. Additionally, while UMA's memory bandwidth leads in mobile devices, it still lags behind data center-grade GPU HBM bandwidth, which can become a bottleneck in high-concurrency inference or training scenarios.
MPS and MLX are two key machine learning frameworks in the Apple ecosystem. MPS (Metal Performance Shaders) is Apple's GPU-accelerated computing library, through which frameworks like PyTorch access Apple Silicon GPUs via the MPS backend; MLX is Apple's array computing framework designed specifically for Apple Silicon, emphasizing efficient computation under unified memory. The common pain point of both lies in ecosystem maturity: a large number of open-source models and operators are optimized for CUDA by default, and migrating to MPS/MLX requires additional adaptation. Some operators even lack native support, forcing users to manually convert or fall back to CPU—this is the root cause of the "compatibility issues" and "inconsistent results" mentioned by that M3 Ultra user.
Linear Pricing Logic: Should Doubling VRAM Mean Doubling Price?
Facing the high pricing, one user tried to analyze rationally: "When VRAM scales linearly, why would you think the price wouldn't scale linearly?"
This leads to a basic logic of Apple's pricing: memory capacity is the main driver of price. From 256GB to 512GB, the price is not simply additive but shows a significant jump.
Another user directly pointed out: "This is more expensive than two 256GB Ultras." Someone immediately calculated: "That extra 256GB of memory costs $11.5k, lol."
This comparison casts doubt on the reasonableness of the pricing: if two 256GB versions combined can approach or even meet requirements in performance, why choose a single 512GB?
Dual Machines vs Single Machine: Interconnect Speed Becomes the Key Variable
Someone in the discussion raised a practical question: "So I'm wondering whether two 256GB Ultras would be better or one 512GB? Unless I'm missing something about the connectivity between two Ultras."
Another user gave a key response: "You're missing interconnect speed, unless the model you want to run requires more than 512GB of unified memory."
This reveals a hidden advantage of Apple's high-end workstations: the unified memory bandwidth and interconnect efficiency within a single machine cannot be simply matched by external multi-machine setups. For large model inference tasks requiring ultra-large memory and sensitive to communication latency, a single 512GB version still has its irreplaceable value.
But the discussion also pointed out: "It's only worth it if the model you're running needs more than 200GB of memory. Most models aren't close to that requirement yet."
Neoclouds (new cloud service providers) are a type of GPU cloud service model that has emerged in recent years. Unlike traditional public clouds like AWS and Azure, they focus on providing on-demand high-performance GPU compute with more flexible pricing and faster deployment, and are often used by AI researchers and startup teams for model training and inference. For professional users whose local deployment is hindered, neoclouds offer an alternative "pay-per-use" path: no need to invest tens of thousands of dollars upfront in a workstation, nor bear the costs of hardware depreciation and compatibility debugging. This is also the practical reason why that M3 Ultra user turned to neoclouds—when local hardware and software adaptation costs are too high, the marginal cost of cloud compute becomes more attractive.
Interconnect speed here refers to the bandwidth and latency of data transmission between multiple machines. When users try to network two 256GB Mac Studios to obtain equivalent 512GB memory, the machines are typically connected via Thunderbolt or Ethernet, whose bandwidth (on the order of tens of Gbps) is far lower than the bandwidth of unified memory within a single machine (on the order of hundreds of GB/s). For frequent inter-layer communication and parameter synchronization in large model inference, this gap can significantly slow things down and even make dual-machine setups infeasible for certain tasks. Therefore, the value of a single 512GB machine lies not only in capacity but also in its internal high-bandwidth, low-latency interconnect characteristics, which are difficult to replicate with external multi-machine setups.
Who Needs 512GB? Realistic Considerations of Demand Boundaries
Looking at the discussion as a whole, 512GB unified memory targets a very narrow professional scenario: AI researchers or enterprise users who need to load ultra-large-scale models and cannot accept multi-machine communication overhead.
For most local AI practitioners, model requirements under 200GB are more common, and the 256GB version can already cover a considerable portion of workloads. When model scale has not reached the critical point requiring a single 512GB machine, dual-machine setups are more attractive in terms of cost—even considering interconnect losses.
This also explains why the community reaction is so intense: Apple's pricing strategy has pushed the "top configuration" into luxury territory, while the user group that truly needs this configuration is precisely the professional users most sensitive to cost-effectiveness.
Apple's Dilemma in Local AI
From M3 Ultra to M5 Ultra, Apple's pricing logic for professional workstations is becoming increasingly clear: unified memory is the core of the premium, and doubling capacity means a significant price jump. But users' actual feedback shows that beyond hardware specifications, the maturity of the software ecosystem also determines purchasing decisions.
The M3 Ultra user's regret is quite representative—"wish I had bought a regular accelerator card." When the compatibility cost of local AI deployment remains high, even if Apple offers attractive memory specifications, professional users will vote with their feet and turn to neoclouds or other hardware solutions.
The $22,299 price tag is, to some extent, a confidence test by Apple in its own ecosystem barriers. But the community's reaction shows that this barrier is not as solid in the AI workload space as Apple imagines.
Related articles

14 Core Concepts of Reasoning Models: From Chain of Thought to GRPO Explained
A systematic breakdown of 14 core concepts of reasoning models: chain of thought, test-time compute, verifiers, RLVR and GRPO, distillation, and reward hacking, plus rules for controlling thinking-token costs to help you decide when reasoning is worth paying for.

OpenAI's Claimed Refutation of ETH Sparks Debate, Meta Bets Big on AI Infrastructure
OpenAI claims an AI-assisted discovery that challenges the Exponential Time Hypothesis (ETH) and launches the mid-tier GPT-6.1 Tera. Cloudflare discloses a cross-customer data leak postmortem, and Meta plans $95B in AI infrastructure financing.

Data Scraping, AI Proofs, and Open Source Contracts: This Week's Deep Dive into the Tech World
From the 3D model crawler controversy and OpenAI's Lean formal proofs to AI agents challenging Brooks' Law and Debian rejecting LLM review, this week's tech discussions center on openness and verifiability.