Machine Learning Self-Study Roadmap: A Four-Stage Path from Python Basics to Landing an Internship

Stop drowning in notes — a four-stage, project-first ML roadmap to land your first internship.
Using a real Reddit case of a junior CS student paralyzed by 2,700 pages of ML notes, this article argues the real problem is information overload, not lack of resources. It lays out a four-stage roadmap: 2–3 weeks on data processing, 3–4 weeks on core algorithms, 4–6 weeks building end-to-end projects, then ongoing interview prep. The core principles are goal-driven reverse engineering and building before you feel fully ready — because 2–3 solid GitHub projects are what actually land internships.
A Common Learning Dilemma
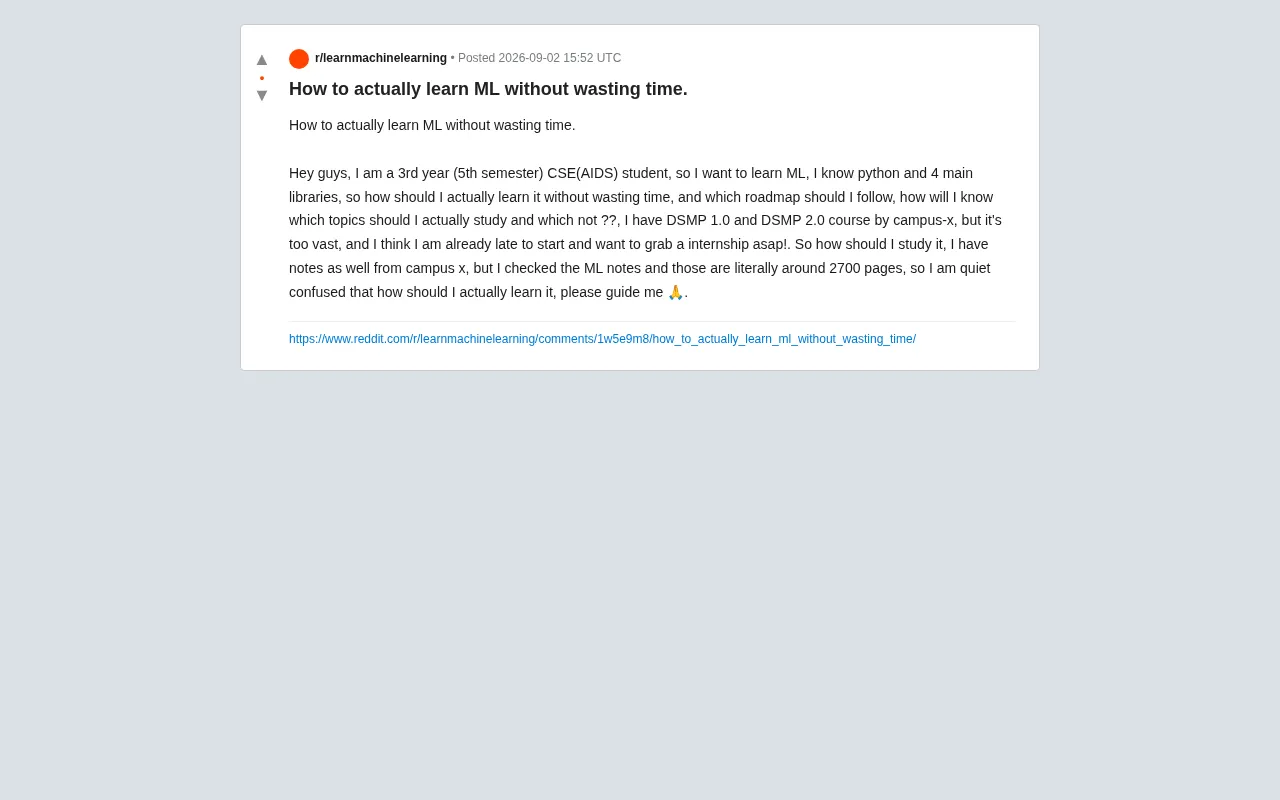
On Reddit, a junior-year computer science student (majoring in AI and Data Science) posted a plea for help: he already knew Python and four core libraries, had access to CampusX's DSMP 1.0 and 2.0 courses, and even had 2,700 pages of machine learning notes — yet he still felt completely lost.
His core anxiety is remarkably relatable: too much content and no idea where to start, worried about falling behind, and desperate to land an internship.
This is a problem almost every self-taught ML learner runs into. Resources have never been the bottleneck — the real scarcity is the ability to filter and follow the right learning sequence. This article uses that real-world case as a starting point to map out a machine learning study path that avoids wasting time.
Why 2,700 Pages of Notes Can Actually Be a Trap
The student's problem isn't "not enough material" — it's information overload. Those 2,700 pages look impressive, but they're designed for systematic top-to-bottom reading, not for fast, goal-oriented learning aimed at landing an internship.
Complete Courses vs. Goal-Driven Learning
Courses like DSMP are built for comprehensive coverage. They include a lot of derivations and niche algorithms that rarely come up in real projects. Working through them page by page could take six months or more — and you might still not be able to build a project independently when you're done.
A more effective approach is reverse engineering: start by looking at what entry-level ML or data roles actually require, then work backward to figure out what skills you need. Use your existing notes and courses as a reference manual, not required reading.
Ditch Perfectionism: Good Enough Understanding → Start Building
Many people believe they need to fully master linear algebra, probability theory, and the mathematical derivations behind every algorithm before touching a project. The reality is the opposite — understand enough, then build. When you hit a knowledge gap during a project, that's the moment to go back and consult those 2,700 pages. Learning in context is far more efficient.
A Practical Four-Stage ML Self-Study Roadmap
For someone with a Python foundation who wants to land an internship as quickly as possible, the learning process can be compressed into four stages.
Stage 1: Solidify Data Processing Skills (2–3 Weeks)
Since you already know NumPy, Pandas, and Matplotlib, focus on working with real, messy data:
- Data cleaning, handling missing values and outliers
- Feature engineering (encoding, normalization, feature selection)
- Exploratory Data Analysis (EDA)
Beginners often skip this stage, but it's exactly what takes up the most time in actual internship work.
Stage 2: Master Core ML Algorithms (3–4 Weeks)
You don't need to learn dozens of algorithms. Focus on the industry workhorses:
- Linear Regression / Logistic Regression
- Decision Trees and Random Forests
- Gradient Boosting (XGBoost, LightGBM)
- K-Nearest Neighbors, K-Means Clustering
For each algorithm, nail three things: what problem it solves, what the core intuition is, and how to implement it with scikit-learn. Set the math derivations aside for now — intuition comes first.
Stage 3: Build End-to-End Projects (4–6 Weeks)
This is the critical leap from "I've studied this" to "I can actually do this" — and the most important part of any ML self-study roadmap. Aim for 2–3 end-to-end projects covering different problem types:
- A classification project (e.g., customer churn prediction)
- A regression project (e.g., house price prediction)
- A Kaggle competition involving real, dirty data
Walking through the full pipeline — data collection → cleaning → modeling → evaluation → tuning — is worth more than watching ten hours of video. These projects will also become your most convincing talking points on a résumé and in interviews.
Stage 4: Fill in Gaps and Prepare for Interviews (Ongoing)
This is when those 2,700 pages of notes finally earn their keep — as on-demand reference material. Supplement your knowledge with high-frequency interview topics like model evaluation metrics, overfitting and regularization, and cross-validation.
The Myth of "Starting Too Late"
The student mentioned feeling like he had "already started too late" — a common but unnecessary anxiety.
Starting machine learning in your junior year is absolutely not too late. Hiring managers care about whether you can complete a project independently and explain your thinking clearly — not whether you started in freshman or junior year. Instead of worrying about your starting point, focus on producing something you can show.
A realistic timeline: complete all four stages in about three months, upload your projects to GitHub, and put together a portfolio. With 2–3 solid projects, you're ready to apply for data analyst or entry-level ML internships.
Three Core Principles for Self-Taught ML Learners
Drawing from this case, here are principles that apply to most people teaching themselves machine learning:
- Work backwards from the job description: Look at what roles actually require, then decide what to learn. Stop spending time on irrelevant content.
- Prioritize doing over reading: Spend 70% of your time writing code and building projects. Theory is a support structure, not a prerequisite.
- Measure progress by output: Use "finished a showable project" as your milestone — not "read X number of pages."
There will always be more ML material to read than you can ever finish. But a strong project portfolio is what actually opens the door to internships. Instead of being crushed by 2,700 pages of notes, start writing your first project today.
Related articles

T3 Code: The Open-Source AI Coding Assistant's Comeback Story
T3 Code is an open-source AI coding assistant that unifies subscriptions like Codex and Claude, with powerful remote control and parallel task management.

Never Elected, Yet Ruled New York for 30 Years: The Ultimate Case Study in the Mechanics of Power
Robert Caro's biographies reveal how unelected Robert Moses ruled New York for 30 years through legal drafting and public authorities, and how Lyndon Johnson built leverage as a "powerless" Senate Majority Leader. Unpacking the underlying logic of accumulating and sustaining power.

The CPython 3.10 Recursion Trap and Synthetic Recovery in TokenGuard, an LLM Circuit Breaker
TokenGuard's author recounts a recursion crash caused by OrderedDict.pop in CPython 3.10 and introduces v0.3.0's Loop Nudge synthetic recovery, inline DLP scanning, and other new LLM agent circuit-breaker capabilities.