NVIDIA cuBLAS Introduces New FP64 Algorithms: Accelerating Scientific Simulation
NVIDIA cuBLAS adds optimized FP64 algorithms and new APIs to accelerate dense matrix operations in scientific simulation.
NVIDIA announced in its developer blog that the cuBLAS library has added a set of optimized algorithms for FP64, aiming to solve the high time cost of high-precision dense matrix operations in scientific simulation. The article notes that molecular dynamics, quantum chemistry, and other fields must use FP64 due to error accumulation, and operations such as GEMM are the main overhead in simulation pipelines. The new algorithms center on dense general matrix multiplication and add new API entry points so developers can explicitly select algorithm paths to handle irregular matrix shapes. Beneficiaries include simulation software such as GROMACS and LAMMPS that rely on cuBLAS. During migration, it is necessary to first profile the time share of FP64 GEMM and verify numerical consistency, because the new paths may introduce floating-point rounding differences.
Scientific simulation has long faced a thorny contradiction: fields such as molecular chemistry and materials science demand extremely high numerical precision, yet high-precision dense matrix operations happen to be among the most time-consuming parts of GPU workloads. NVIDIA recently disclosed in its developer blog that the cuBLAS library has added a set of optimized algorithms targeting FP64 (double-precision floating point), with the goal of "making high-precision computation no longer a bottleneck in simulation pipelines."

Why FP64 Remains a Hard Requirement for Scientific Computing
The deep learning community is used to discussing FP16, BF16, and even FP8, but scientific simulation takes a different path. Force field integration in molecular dynamics, matrix diagonalization in quantum chemistry, and stiffness matrix solving in finite element analysis all amplify errors through iterative processes, and switching to lower precision often directly leads to unreliable results.
NVIDIA explicitly states in its blog post that for many scientific simulations, execution time is "largely consumed by high-precision dense general matrix operations." In other words, although fundamental linear algebra operations like GEMM have mature algorithms, they remain the highest-overhead item in the entire simulation pipeline. As the most core BLAS implementation in the CUDA ecosystem, cuBLAS's FP64 path efficiency directly determines how fast upper-layer applications can run.
FP64 (double-precision floating point) refers to representing a floating-point number with 64 binary bits, of which 52 bits are used for the mantissa (significant digits), 11 bits for the exponent, and 1 bit for the sign. Compared with FP32 (single precision, 24-bit mantissa), FP64 has a machine precision of approximately 2.2×10⁻¹⁶, while FP32 is only about 1.2×10⁻⁷. In scientific simulations, the number of iterations can reach millions of steps, and rounding errors at each step accumulate; FP32 precision may cause results to deviate from the physical true value after only a few dozen steps, whereas FP64 can support long-time integration. In addition, FP64 theoretical throughput on GPUs is typically only 1/2 to 1/32 of FP32 (depending on architecture), and it requires more registers and bandwidth, making FP64 GEMM optimization more challenging than low-precision optimization.
What the New Algorithms Change
From the official description, these newly added FP64 algorithms are not a single trick but a set of implementation optimizations centered on dense general matrix multiplication, while also covering the calling interface level—NVIDIA mentions adding new API entry points to cuBLAS so developers can explicitly select these algorithm paths.
What is worth noting here is the wording "algorithms" rather than "operators." The performance ceiling of matrix multiplication is usually determined jointly by three aspects: the degree of overlap between data movement and computation, the efficiency of blocking strategies in utilizing on-chip storage, and how to select the optimal kernel under different matrix shapes. Matrix size distributions in scientific computing scenarios are often highly irregular—some come from regular large matrices in lattice models, and some from irregular dense blocks transformed from sparse structures. General-purpose kernels tend to lose performance under extreme shapes, and targeted algorithms are precisely meant to fill such gaps.
For developers, the value of the new API lies in handing over the "right to choose": the application layer can call a more suitable implementation based on its own matrix characteristics, rather than passively accepting the default path.
GEMM (general matrix multiplication) is the core Level-3 operation in BLAS libraries, computing C = α·A·B + β·C, where A, B, and C are dense matrices. Its performance is usually measured in FLOPS and is limited by memory bandwidth and compute unit utilization. Modern GPU implementations of GEMM use tiling: large matrices are divided into small blocks suitable for on-chip shared memory, reducing global memory access through data reuse. Parameters such as block size, thread block shape, and register blocking strategy need to be tuned for matrix dimensions and GPU architecture. Matrices in scientific computing often exhibit extreme shapes such as "long strips" or "tall and skinny," making it difficult for general-purpose kernels to reach peak performance, hence the need for targeted algorithms.
What It Means for Real Workloads
The most direct beneficiaries are simulation codes already running on GPUs. Molecular dynamics software such as GROMACS and LAMMPS, as well as various custom CUDA-based solvers, all rely on cuBLAS at the bottom layer for dense linear algebra. Once the FP64 path is accelerated, such applications may achieve a reduction in overall simulation time without changing algorithm logic, simply by upgrading the library version and adjusting the calling method.
NVIDIA positions these algorithms as an infrastructure update for "accelerating scientific simulation," rather than an end-to-end solution for a specific industry. This positioning is actually more pragmatic: cuBLAS is a shared foundation, and the performance dividend will propagate along the dependency chain to chemistry, materials, meteorology, structural mechanics, and other fields, but the specific gain depends on the proportion of FP64 operations in each application's total runtime.
GROMACS and LAMMPS are two widely used open-source molecular dynamics simulation packages. GROMACS is known for high performance, and its GPU-accelerated path makes extensive use of cuBLAS for dense matrix operations (such as FFT and matrix multiplication in PME mesh calculations); LAMMPS supports multiple force fields and parallel modes, and its GPU package also relies on cuBLAS for some linear algebra operations. These packages usually use FP64 as the default precision because error accumulation in force field integration directly affects energy conservation and trajectory stability. Acceleration of the cuBLAS FP64 path means these packages can shorten simulation time simply by upgrading the library without changing algorithms, but the actual gain depends on the proportion of GEMM in total runtime (typically the PME part accounts for a relatively high share).
Practical Advice for Migration and Tuning
For teams planning to follow this update, several points are worth considering in advance. First, perform performance profiling to confirm the time share of FP64 GEMM in your own workload—if the share is not high, library-level optimization will improve end-to-end metrics only to a limited extent. Then verify numerical consistency: the new algorithm paths may differ slightly from old implementations in floating-point rounding order, and simulations sensitive to results need regression comparisons. Finally, there is the kernel selection strategy; for scenarios where matrix shapes evolve over simulation steps, it may be necessary to switch different algorithm entry points by stage rather than fixing a configuration once and for all.
This update continues cuBLAS's consistent approach: encapsulating the complexity of low-level performance engineering into the library while exposing controllability through APIs. For scientific computing developers, this is a low-intrusion performance opportunity, but to truly realize it, targeted validation based on one's own workload is still required.
Related articles
AI Writes Your Code—Do You Still Need to Learn Git? Five Reasons
AI coding agents handle Git operations automatically—is it still necessary to learn Git? Five reasons: team communication, reviewing agent PRs, monitoring code changes, fallback when AI goes down, and the joy of learning—plus how the focus of learning Git is shifting in the agent era.
Anthropic Reportedly Prices IPO at $83 Per Share, Valuing Company at $1.5 Trillion
Anthropic reportedly prices IPO at $83 per share, above the expected range, with a fully diluted valuation of $1.5 trillion. This article analyzes the signal significance of the pricing and its impact on the AI industry's financing environment.
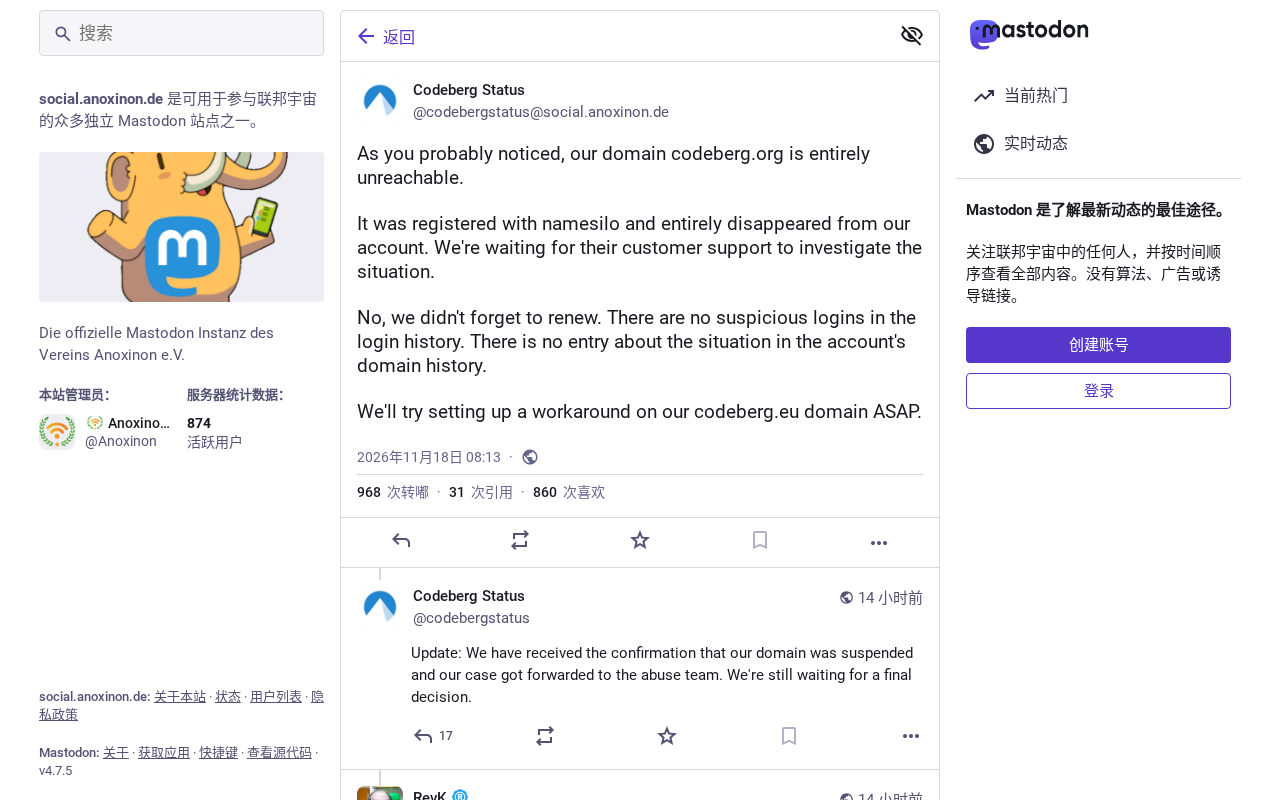
Open-Source Code Hosting Platform Codeberg Suffers Outage, Sparking Debate in Developer Community
Open-source code hosting platform Codeberg.org suffered an outage, sparking Hacker News debate over nonprofit platform stability and open-source infrastructure dependency risks.