OmniScore-Bench: A Comprehensive Evaluation of VLMs' Sheet Music Reading Capabilities
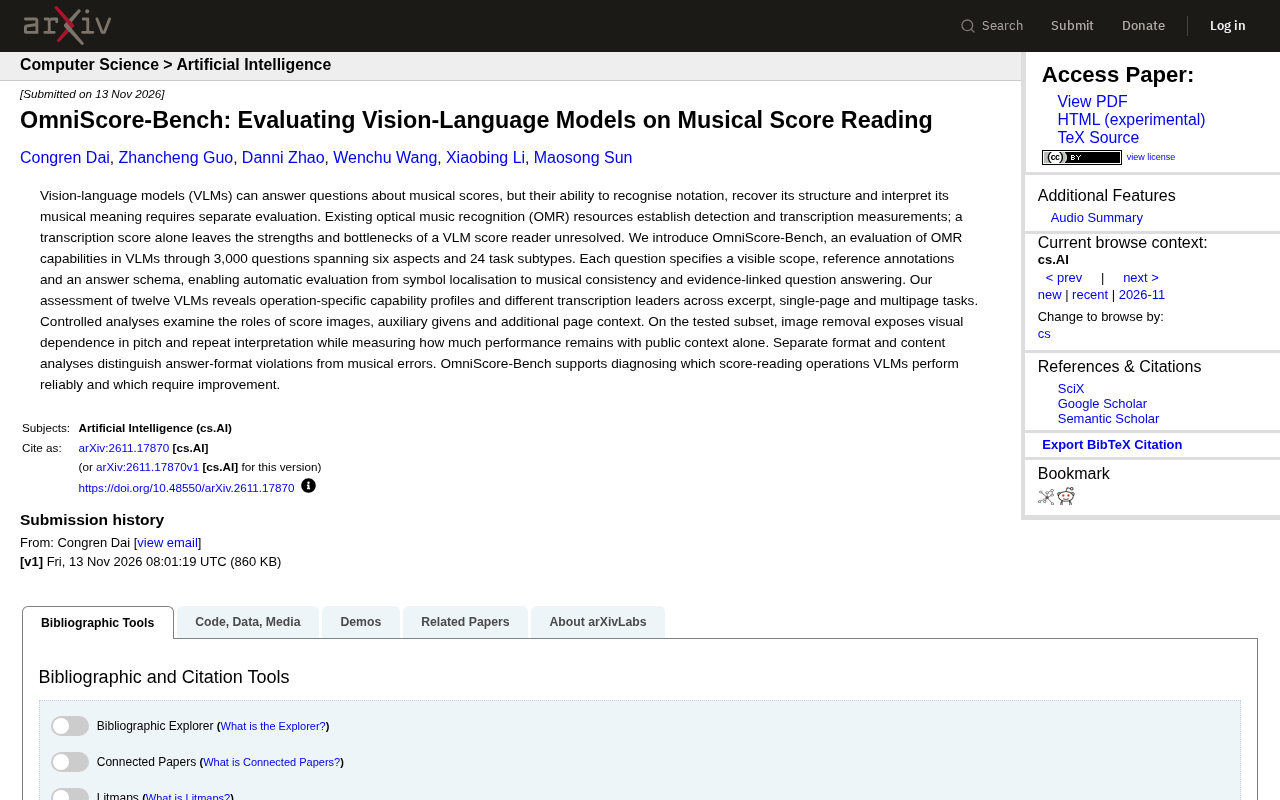
OmniScore-Bench systematically diagnoses 12 VLMs' sheet music reading capabilities with 3000 questions across six aspects and 24 sub-tasks.
Existing OMR evaluations only focus on symbol detection and transcription accuracy, failing to reveal specific bottlenecks of VLMs in sheet music reading. OmniScore-Bench contains 3000 questions covering six aspects—symbol recognition, structural parsing, pitch and rhythm interpretation, repeats and navigation, harmony and tonality, and evidence reasoning—subdivided into 24 sub-tasks for automatic evaluation. Evaluation of 12 VLMs shows operation-specific capabilities: transcription leaders vary by task granularity. Controlled experiments show removing images exposes reliance on visual input, and format/content analysis distinguishes answer format violations from genuine musical errors. The benchmark provides a fine-grained tool for diagnosing model weaknesses and guiding targeted optimization.
Vision-language models (VLMs) can already answer simple questions about sheet music, but do they truly understand notation, structure, and musical semantics? Existing Optical Music Recognition (OMR) resources only provide measurements of detection and transcription, failing to reveal the strengths and bottlenecks of VLMs in sheet music reading. To address this, researchers introduce OmniScore-Bench, an evaluation benchmark with 3000 questions spanning six aspects and 24 sub-tasks, designed to systematically assess VLMs' OMR capabilities.
Why is a dedicated sheet music reading benchmark needed?
Traditional OMR evaluation focuses on symbol detection and transcription accuracy, but this is only the starting point of sheet music reading. A complete sheet music reader needs to recognize symbols, recover structure (e.g., measures, voices, repeats), and interpret musical meaning (e.g., pitch, rhythm, harmony). Transcription scores alone cannot determine where a VLM is weak—is it missing the key signature, or misinterpreting repeat signs? OmniScore-Bench fills this gap through fine-grained task design.
Multi-dimensional task design
The benchmark contains 3000 questions, each specifying the visible scope, reference annotations, and answer format, supporting automatic evaluation from symbol localization to musical consistency and evidence-linked question answering. The six aspects cover core sheet music reading abilities: symbol recognition, structural parsing, pitch and rhythm interpretation, repeats and navigation, harmony and tonality, and evidence-based reasoning. The 24 sub-tasks further subdivide these, for example, distinguishing single-page versus multi-page segmentation under "structural parsing."
Optical Music Recognition (OMR) is the classic task of converting sheet music images into machine-readable symbol sequences, typically outputting structured formats such as MusicXML or MEI. Traditional OMR pipelines include staff detection, symbol classification, pitch inference, and rhythm alignment, with evaluation metrics primarily based on Symbol Error Rate (SER). However, SER only measures whether local symbols are written correctly; it does not verify whether global structures such as barlines, voice crossing, and repeat jumps are self-consistent, nor does it reflect the model's understanding of harmonic function or tonal relationships. OmniScore-Bench's fine-grained sub-tasks are designed to add diagnostic signals at the structural and semantic levels on top of OMR transcription.
Capability profiles of twelve VLMs
The researchers evaluated 12 VLMs and found that different models exhibit specific capability profiles across different operations. For example, in excerpt, single-page, and multi-page tasks, the leading models in transcription are not the same—some models excel at short-segment symbol recognition but decline in multi-page structure recovery. This operational specificity indicates that models cannot be simply ranked by a single score; instead, appropriate tools should be selected based on application scenarios.
Controlled variable analysis: the role of images and context
By removing sheet music images and providing only public context, the researchers measured the degree of visual reliance. On test subsets, image removal exposed the dependence of pitch and repeat interpretation on visual input, while quantifying how much performance can be retained with public context alone. Furthermore, format and content analysis distinguished answer format violations from musical errors—some failures stem from output format mismatches rather than musical misunderstanding, which has important implications for post-processing in real-world deployment.
Visual reliance is a metric measuring the performance drop of multimodal models when images are removed. If a question type can still be answered correctly in text-only context, it suggests the model may rely on language priors or dataset biases rather than actually reading the image; conversely, a sharp performance drop indicates that the capability genuinely requires visual input. This ablation design aligns with the "blind test" approach in the VQA field, used to examine whether models faithfully use visual evidence. In sheet music scenarios, pitch recognition and repeat sign interpretation highly depend on symbol positions and graphical layout, so the performance gap after image removal serves as direct evidence of whether the model is "looking at the image to answer."
Implications for VLM sheet music reading
The value of OmniScore-Bench lies in its diagnostic nature: it not only tells you whether a model "works" but also points out "where it fails." For developers, this means targeted optimization is possible—such as strengthening multi-page structure modeling or reducing format violations. For applications like music education and digital sheet music libraries, model selection requires weighing reliability on key operations. Current VLMs still have obvious shortcomings in sheet music reading, but the fine-grained feedback provided by the benchmark points the way for improvement.
Limitations and future directions
The benchmark currently focuses on Western notation and can be extended to other notation systems in the future. Additionally, automatic evaluation relies on answer formats, limiting coverage of open-ended musical interpretation. Nevertheless, OmniScore-Bench takes an important step toward systematically evaluating VLMs' sheet music reading capabilities.
Common Western Notation is based on the five-line staff, key signatures, time signatures, and a fixed pitch system, while other notation systems differ significantly: for example, numbered musical notation uses digits to represent scale degrees, gongche notation uses Chinese characters to record relative pitch, and guitar tablature indicates fingerings by string and fret positions rather than absolute pitch. Extending the benchmark to these systems requires redefining symbol ontologies, structural hierarchies, and answer formats, and handling equivalence judgments for the same piece under different notations. This is not merely a data augmentation problem but also involves standardization at the music ontology level, which is a major challenge for cross-notation evaluation.
One-line Summary
OmniScore-Bench systematically diagnoses 12 VLMs' sheet music reading capabilities with 3000 questions across six aspects and 24 sub-tasks.
Paragraph Summary
Existing OMR evaluations only focus on symbol detection and transcription accuracy, failing to reveal specific bottlenecks of VLMs in sheet music reading. To address this, researchers introduce OmniScore-Bench, containing 3000 questions covering six aspects—symbol recognition, structural parsing, pitch and rhythm interpretation, repeats and navigation, harmony and tonality, and evidence reasoning—subdivided into 24 sub-tasks with automatic evaluation. Evaluation of 12 VLMs shows operation-specific capabilities: transcription leaders vary by task granularity. Controlled experiments show that removing images exposes reliance of pitch and repeat interpretation on visual input, while format and content analysis distinguishes answer format violations from genuine musical errors. The benchmark provides a fine-grained tool for diagnosing model weaknesses and guiding targeted optimization.
Related articles
GLM 5.5 Arrives: Has Claude Cracked the 167-Year-Old Riemann Hypothesis?
Claude and a mathematician claim to have proved the 167-year-old Riemann Hypothesis, Zhipu's GLM 5.5 is imminent, Google's Loop agent surfaces, and Thinking Machines open-sources Inkling 2 Mini.
AI Coding Made Building Cheap, but Not Maintenance
AI coding agents make internal tools cheap to build but not to maintain. This article examines the hidden liabilities of tool sprawl and proposes three governance principles: inventory, ownership, and reuse first.
Microsoft SideWinder Strategic Commander: A Failed Innovation Attempt
A review of Microsoft's SideWinder Strategic Commander gaming peripheral: its design intent, usability flaws, and market positioning, and why peripheral innovation must respect user habits.