PIVOT: How Online Teacher Correction Breaks Through the Sparse Reward Bottleneck of RLVR

PIVOT uses teacher trajectory correction plus token-level KL supervision to break the sparse reward dilemma of RLVR.
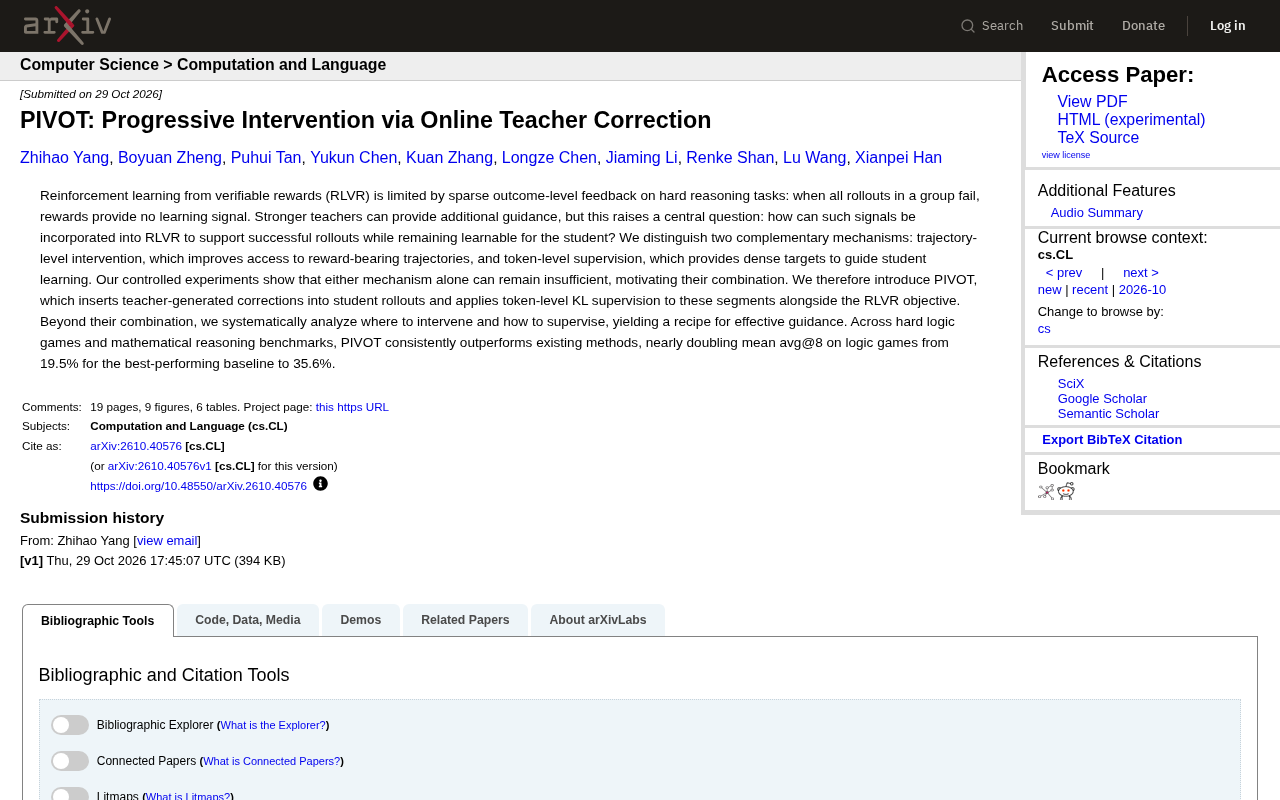
The article introduces the core bottleneck of RLVR on difficult reasoning tasks: when a group of rollouts all fail, the reward is zero and policy gradients cannot update. The new method PIVOT inserts teacher correction segments into student trajectories so failed trajectories can enter reward-bearing regions, while applying token-level KL supervision to the corrected segments for dense signals, jointly optimized with the original RLVR objective. Controlled experiments show each mechanism alone is insufficient, and only their combination works. On logic game benchmarks, PIVOT raises avg@8 from 19.5% to 35.6%, with mathematical reasoning benchmarks also confirming generality. The paper systematically analyzes intervention positions and supervision modes to form a reusable guidance recipe.
Reinforcement Learning from Verifiable Rewards (RLVR) is currently the mainstream paradigm for improving the reasoning capabilities of large models, but it has a fundamental bottleneck: when a group of rollouts all fail, the reward signal is zero, and the model cannot learn anything from it. This is especially true for difficult reasoning tasks, where sparse outcome-level feedback greatly reduces training efficiency.
A new study called PIVOT proposes a targeted solution—inserting online corrections from a teacher model into student trajectories and applying token-level KL supervision to the corrected segments. On logic game and mathematical reasoning benchmarks, PIVOT raises the average avg@8 on logic games from 19.5% for the best baseline to 35.6%, nearly doubling it.
The Sparse Reward Dilemma: No Signal to Learn From When Everything Fails
The core assumption of RLVR is that the model generates a set of candidate answers, and as long as one of them passes the verifier, it can obtain a positive reward and reinforce the corresponding reasoning path. But in difficult tasks, this assumption often fails—the entire group of rollouts fails, the within-group reward variance is zero, and policy gradient updates have nothing to work with.
The paper points out that this is precisely the key limitation of RLVR on difficult reasoning tasks: sparse outcome-level feedback fails exactly in the scenarios where the model most needs to learn. The solution is to introduce a stronger teacher model to provide additional guidance, but this raises a question: how can teacher signals be integrated into the RLVR framework so that they both help the student produce successful rollouts and remain within the student's learnable range?
RLVR and policy gradients: RLVR usually adopts group-relative policy optimization methods such as GRPO, sampling a group of rollouts for the same prompt, using an outcome verifier to assign 0/1 rewards, and then updating the policy with the standardized within-group reward as the advantage function. This design relies on variance in within-group rewards: if all succeed or all fail, the advantages are all zero and the gradient vanishes. Total failure is especially common in difficult tasks, because the verifier only recognizes the final answer, and no signal is given even if the intermediate reasoning steps are reasonable. This explains why purely outcome-level rewards have limited scalability on reasoning tasks, and it also constitutes the direct motivation for introducing a teacher model for process-level guidance.
Complementarity of Two Mechanisms: Trajectory Intervention and Token Supervision
The paper decomposes teacher guidance into two complementary mechanisms:
- Trajectory-level intervention: Insert teacher corrections into student-generated trajectories, giving originally failed rollouts a chance to reach regions of trajectory space that carry rewards. This solves the question of "whether there is any successful experience to learn from."
- Token-level supervision: Provide dense target signals for the corrected segments, directly guiding the student's learning direction at each token. This solves the question of "how to learn efficiently once successful trajectories are available."
Controlled experiments show that either mechanism alone is insufficient: with only trajectory intervention, the student lacks fine-grained guidance; with only token supervision, it is difficult to obtain enough reward-bearing trajectory samples. This motivated the researchers to combine the two into the PIVOT method.
PIVOT's Method Design: Inserting Corrections + KL Supervision
PIVOT works as follows: insert teacher-generated correction segments into student rollouts, then apply token-level KL supervision to these segments and jointly optimize with the original RLVR objective.
The research team did not stop at a simple combination, but systematically analyzed two key design dimensions: where to intervene (the choice of insertion position) and how to supervise (the mode of action of KL supervision). These analyses yielded a "recipe" for effective guidance, making the method reproducible and transferable.
You may not have noticed that this design preserves the autonomy of the student model—teacher corrections intervene only when needed, rather than replacing the student in completing the entire reasoning process.
What token-level KL supervision means: KL divergence measures the difference between two probability distributions. In PIVOT, at the token positions where teacher correction segments are located, the student model's next-token distribution at that position is constrained to be close to the teacher's distribution, i.e., minimizing KL(student‖teacher). Unlike directly applying cross-entropy (hard labels) to the corrected segments, KL supervision uses the teacher's full soft distribution as a soft target, preserving the teacher's relative confidence over candidate tokens. The signal is smoother and less likely to make the student overfit to a single answer. Since supervision acts only on the inserted segments, the original student tokens are still driven by the RLVR reward, and the two types of loss are jointly optimized, thereby obtaining dense process-level guidance while preserving the student's autonomous exploration.
Experimental Results: Logic Game Performance Nearly Doubles
On difficult logic game and mathematical reasoning benchmarks, PIVOT consistently outperforms existing methods. The most striking data come from logic games: the average avg@8 rises from 19.5% for the best baseline to 35.6%, nearly doubling. This magnitude of improvement shows that once the sparse reward problem is alleviated, the model's reasoning potential on difficult tasks can be substantially unleashed.
Performance on mathematical reasoning benchmarks also verifies the method's generality—PIVOT is not effective only for one type of task, but is applicable to a broad range of scenarios requiring multi-step reasoning.
The avg@8 metric: avg@8 refers to independently sampling 8 reasoning trajectories for the same question, computing the proportion that are correct, and then averaging over all questions. It measures the model's expected accuracy under multiple attempts and reflects the model's potential distribution on difficult tasks better than single-attempt pass@1. This metric is especially sensitive for sparse-reward methods: if the model can occasionally succeed, avg@8 will be noticeably higher than greedy decoding accuracy; if the entire group fails, it will be close to zero. Therefore, the improvement from 19.5% to 35.6% means the model has gone from "almost unable to reach the correct answer" to "about one-third of multiple attempts succeed," reflecting a substantial increase in the number of learnable successful trajectories.
Implications for RLVR Research
The value of PIVOT lies not only in performance gains, but also in providing a clear framework: decomposing teacher guidance into two orthogonal dimensions, "trajectory reachability" and "token-level supervision." This decomposition has direct reference value for future research—any RLVR improvement that attempts to introduce external guidance can examine the completeness of its own design from these two dimensions.
The paper's systematic analysis of intervention positions and supervision modes also reminds researchers that when combining different mechanisms, they should not stop at the level of "stacking," but need to understand the boundaries of each design choice. For training on reasoning tasks trapped by sparse rewards, PIVOT provides an actionable path of progressive intervention.
One-line Summary
PIVOT uses teacher trajectory correction plus token-level KL supervision to break the sparse reward dilemma of RLVR.
Paragraph Summary
The article introduces the core bottleneck of RLVR on difficult reasoning tasks: when a group of rollouts all fail, the reward is zero and policy gradients cannot update. The new method PIVOT introduces a teacher model, inserting teacher correction segments into student trajectories so that failed trajectories have a chance to enter reward-bearing regions, while applying token-level KL supervision to the corrected segments to provide dense signals, jointly optimized with the original RLVR objective. Controlled experiments show that trajectory intervention and token supervision are each insufficient alone, and only their combination is effective. On logic game benchmarks, PIVOT raises avg@8 from 19.5% for the best baseline to 35.6%, and mathematical reasoning benchmarks also verify its generality. The paper also systematically analyzes intervention positions and supervision modes, forming a reusable guidance recipe.
Related articles
OpenAI Math Breakthrough, Anthropic IPO, and Reasoning Model Tutorial
OpenAI unveils math, CS, and physics results, claiming proof that ETH is false; Anthropic files for IPO, disclosing revenue and customer data; SpaceX gets $40B GPU financing; open-source model tool-calling accuracy issues and constrained decoding; 8-video reasoning model tutorial.

14 Core Concepts of Reasoning Models: From Chain of Thought to GRPO Explained
A systematic breakdown of 14 core concepts of reasoning models: chain of thought, test-time compute, verifiers, RLVR and GRPO, distillation, and reward hacking, plus rules for controlling thinking-token costs to help you decide when reasoning is worth paying for.

OpenAI's Claimed Refutation of ETH Sparks Debate, Meta Bets Big on AI Infrastructure
OpenAI claims an AI-assisted discovery that challenges the Exponential Time Hypothesis (ETH) and launches the mid-tier GPT-6.1 Tera. Cloudflare discloses a cross-customer data leak postmortem, and Meta plans $95B in AI infrastructure financing.