Qwen 3.8 Flash Local Deployment Benchmarks: 43 token/s on a Single Spark

Qwen 3.8 Flash hits 43 token/s on a single Spark with 180B params matching 320B flagship models.
Qwen 3.8 Flash is a vision-language model from the Qwen team that matches GLM 5.3 Flash (320B) in benchmark performance with only 180B parameters. It delivers 30–43 token/s on a single DGX Spark and 55–70 token/s in dual Spark TP2 mode, supporting 4 concurrent agents. NVIDIA Media quantization preserves near-lossless quality at 4-bit precision. TP2 is the optimal configuration for balancing inference speed and VRAM usage, making Qwen 3.8 Flash the top local deployment choice for individual developers and small teams.
Model Overview: Half the Parameters, Flagship-Level Performance
Qwen 3.8 Flash is quickly becoming a favorite in the local AI community. According to the latest benchmark data from Artificial Analysis, this model's overall capability rating places it in the same tier as GLM 5.3 Flash — but with only half the parameter count (180B vs 320B). Across specialized tests including GDPPDF, long reasoning contexts, and scientific reasoning, Qwen 3.8 Flash matches GLM and even pulls ahead on select metrics.
For local deployment users, this means near-flagship performance at a fraction of the hardware cost. Notably, the model includes native vision support rather than adding it experimentally after the fact like DeepSeekAd V4 Flash — giving it a stability and quality advantage on multimodal tasks.
Hardware Configs and Inference Speed Benchmarks
The test team ran a full suite of benchmarks across three representative hardware configurations. Here are the detailed results:
Single DGX Spark
- Time to first token: 8 seconds
- Inference speed: 30–43 token/s
- KV cache pool: 995K (TP2 mode)
- Max context window: 262K tokens
Dual Spark TP2
- Inference speed: 55–70 token/s
- KV cache pool: ~5M
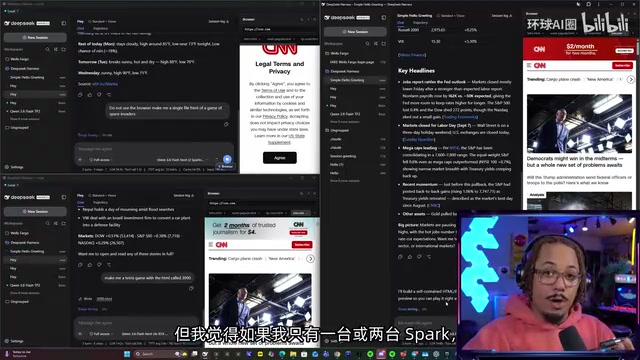
- Concurrency: 4 fully concurrent agents simultaneously
4× RTX 3090
- Time to first token: 6 seconds
- Inference speed: 133–161 token/s
- Optimal mode: TP2
One important caveat: TP4 mode showed no speed advantage in testing, with performance landing between TP1 and TP2. TP2 is the recommended sweet spot, striking the best balance between inference performance and VRAM utilization.
Quantization: How NVIDIA's Native Media Quantization Holds Up
All models in this test run on NVIDIA's Media quantization technology. Compared to other community quantization approaches, NVIDIA's method has a clear edge in preserving lossless model quality — 4-bit quantization dramatically reduces VRAM usage while keeping the model's full capabilities intact.
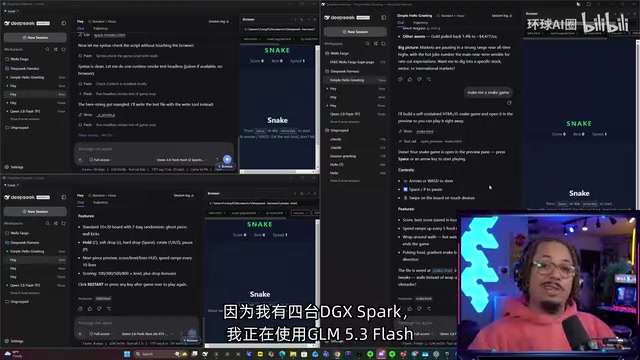
In real-world task testing, the quantized Qwen 3.8 Flash performed consistently across the following scenarios:
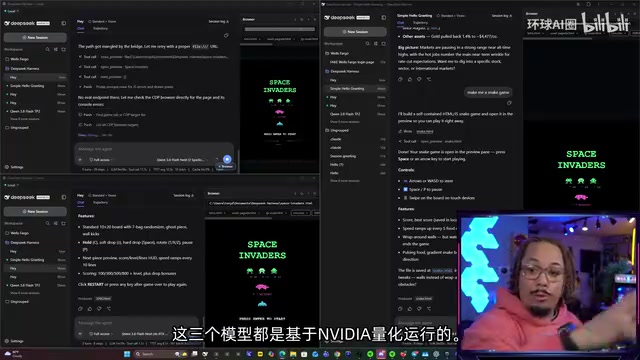
- Building HTML games (Tetris, Snake, Space Invaders)
- Web search and information retrieval
- Browser automation
These results confirm that the Media quantization process does not meaningfully degrade the model's practical reasoning ability.
Deployment Strategies and Agent Configurations by Hardware
Based on the testing, here are tailored deployment recommendations for different hardware setups:
Single / Dual Spark Users
Qwen 3.8 Flash should be your primary daily driver. Compared to DeepSeek V4 Flash, it offers stronger native vision capability and faster inference, covering over 80% of automation task requirements.
4× DGX Spark Users
A tiered deployment strategy is recommended to build a complete multi-agent system:
- Supervisor agent: GLM 5.3 Flash running in TP4 mode
- Worker agents: Qwen 27B (NVLink-accelerated, 200 token/s)
- Sub-agents: Qwen 3.6 35B
RTX 3090 Users
2× RTX 3090 can run this model but requires substantial system memory. A 4× RTX 3090 configuration delivers the best experience, with inference speeds around 160 token/s.
Qwen 3.8 Flash vs GLM, DeepSeek, and Other Competitors
Here's how Qwen 3.8 Flash stacks up against the major alternatives:
| Comparison | Qwen 3.8 Flash | GLM 5.3 Flash | DeepSeek V4 Flash |
|---|---|---|---|
| Parameter count | 180B | 320B | — |
| Dual Spark inference speed | 55–70 token/s | Slower | ~70 token/s |
| Native vision support | ✅ Native | ✅ Native | ⚠️ Experimental |
| Single/dual Spark friendliness | High | High resource demand | Moderate |
- vs GLM 5.3 Flash: Half the parameters with comparable capability, and a clear speed advantage on single/dual Spark setups.
- vs DeepSeek V4 Flash: Similar inference speeds, but stronger vision capability and better overall stability.
- vs Qwen 27B: The 27B variant hits 200 token/s with NVLink acceleration, but Qwen 3.8 Flash has a lower deployment barrier on general-purpose hardware.
Qwen 3.8 Flash has already become one of the most popular deployment choices in the local AI community. Complete deployment recipes and benchmark data have been shared publicly, significantly lowering the barrier to entry.
Looking Ahead
If the Qwen team releases a TP4-optimized Flash version that pushes inference speeds on DGX Spark closer to 100 token/s, this model could become the definitive benchmark for local deployment.
As it stands, for most individual developers and small teams, Qwen 3.8 Flash already hits the best balance between hardware cost, inference speed, and model capability.
Related articles

T3 Code: The Open-Source AI Coding Assistant's Comeback Story
T3 Code is an open-source AI coding assistant that unifies subscriptions like Codex and Claude, with powerful remote control and parallel task management.

Never Elected, Yet Ruled New York for 30 Years: The Ultimate Case Study in the Mechanics of Power
Robert Caro's biographies reveal how unelected Robert Moses ruled New York for 30 years through legal drafting and public authorities, and how Lyndon Johnson built leverage as a "powerless" Senate Majority Leader. Unpacking the underlying logic of accumulating and sustaining power.

The CPython 3.10 Recursion Trap and Synthetic Recovery in TokenGuard, an LLM Circuit Breaker
TokenGuard's author recounts a recursion crash caused by OrderedDict.pop in CPython 3.10 and introduces v0.3.0's Loop Nudge synthetic recovery, inline DLP scanning, and other new LLM agent circuit-breaker capabilities.