Stop Strangling AI Agents with Workflows — Give Them "Childproofing" Instead

Agent engineering should shift from rigid workflows to environmental constraints and outcome verification, letting strong models plan autonomously.
The article explores a "childproofing" agent architecture proposed by a Reddit developer, arguing verification over orchestration: precise operations like counting and data cleaning go to code scripts, checking evidence at each step rather than locking models into flowchart paths; the harness itself is the application; behavior is defined via plain-English profiles so domain experts can adjust directly. A Customer Pulse prototype runs two vastly different scenarios on the same codebase. The article also notes three traps of rigid workflows and the real costs of tokens, latency, and sandbox security.
Stop Strangling AI Agents with Workflows — Give Them "Childproofing" Instead
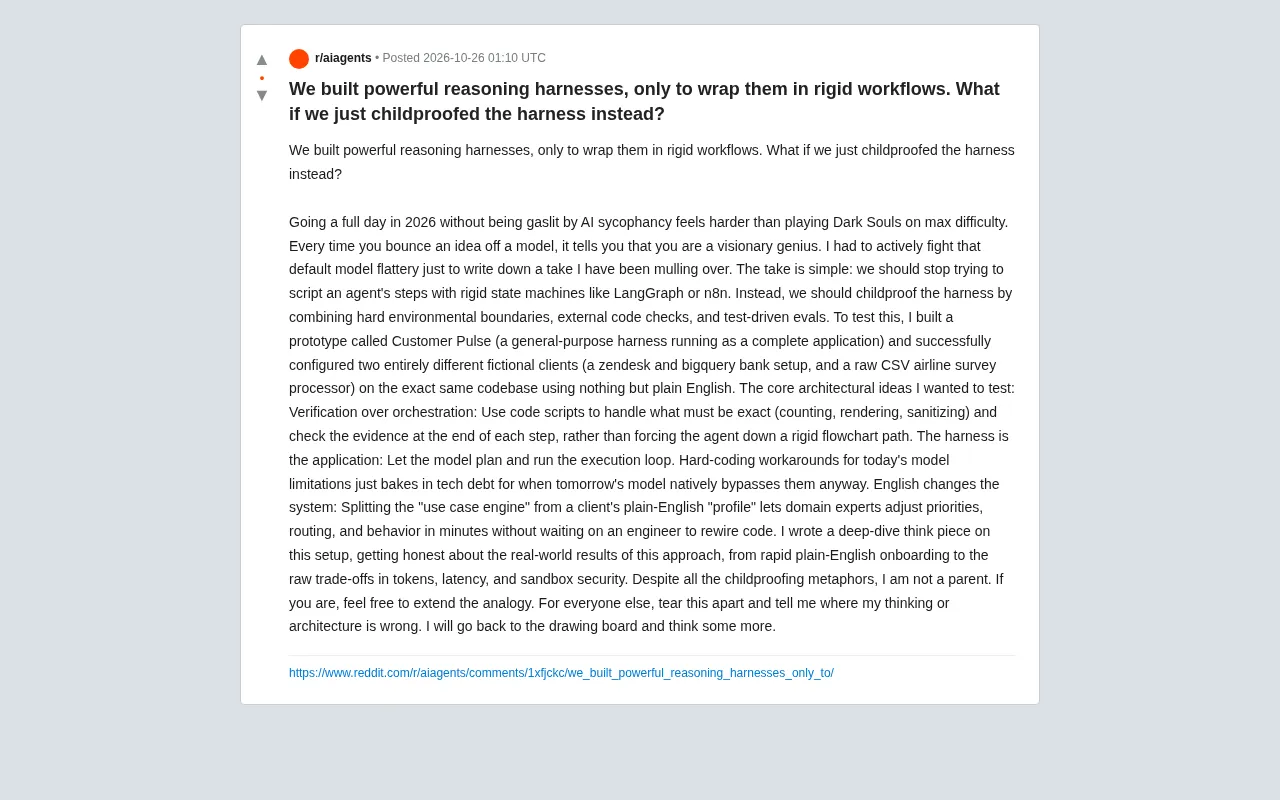
For the past two years, the mainstream approach to building AI agents has been drawing flowcharts: using tools like LangGraph and n8n to break every step into nodes, locking down model behavior with state machines. This approach looks controllable, but it rests on an implicit assumption — that models will make mistakes, so they must be constrained by scripts.
A developer on Reddit proposed a contrarian idea: rather than binding powerful reasoning models with rigid workflows, why not "childproof" the runtime environment instead. He built a prototype called Customer Pulse for this purpose and made the architectural trade-offs public. This idea deserves careful analysis because it touches on a fundamental divergence in agent engineering: orchestration vs. verification — which one is the real focus.
Core Argument: Verification Over Orchestration
The original poster's core thesis can be summarized in three points.
First, verification takes priority over orchestration. Operations that must be precise — counting, rendering, data cleaning — are handled by code scripts, checking evidence at the end of each step rather than forcing the agent down a preset flowchart path. The model handles planning and the execution loop; the code handles guardrails and verification.
Second, the harness itself is the application. Let the model plan on its own and run its own execution loop. Hardcoding various workarounds for the current model's deficiencies is essentially planting technical debt for the future — when the next generation of models natively bypasses these limitations, all the patches you wrote become a burden.
Third, natural language changes system behavior. By separating the "use-case engine" from the customer's plain-English "profile," domain experts can adjust priorities, routing, and behavior in minutes without waiting for engineers to change code and rewire everything.
All three point to the same architectural choice: an agent's behavioral boundaries are defined by environmental constraints and outcome verification, not by flowcharts.
Harness in the agent context refers to the framework layer that wraps the large model and manages its running loop: it receives the model's action intents, executes tool calls, feeds results back to the model, and decides when to terminate. Unlike traditional workflow engines, a harness does not presuppose step order; it only provides tools, context management, and termination conditions. When the article says "the harness itself is the application," it means the application logic is no longer scattered across flowchart nodes but concentrated in this running loop and its configuration — the model handles autonomous planning within the loop, and the harness handles execution and feedback.
Prototype Validation: One Codebase Runs Two Completely Different Scenarios
To validate this idea, the author built Customer Pulse — a general-purpose harness that runs as a complete application.
He configured two completely different fictional customer scenarios: one being a banking customer service system with Zendesk plus BigQuery, the other an airline survey system processing raw CSV. Both scenarios run on the exact same codebase, with configuration switches and behavior adjustments relying solely on plain-English descriptions.
What makes this test valuable is that it examines a key hypothesis: if the harness is well designed, can the same runtime adapt to vastly different business logic through natural-language profiles? The author's conclusion is yes, while also candidly acknowledging the costs — token consumption, latency, and real trade-offs in sandbox security are all addressed in his in-depth long-form article.
In other words, this approach is not free. Abandoning rigid workflows buys flexibility, but at the cost of inference expense and engineering complexity.
Why Rigid Workflows Are a Trap
Understanding the value of this view requires seeing three problems with the current workflow paradigm.
Model capabilities are rising; workarounds are depreciating. Every time you write hardcoded logic for "the model can't do X," you're betting that this deficiency will persist long-term. Reasoning models iterate far faster than most teams' release cycles; what required a state machine as a fallback last year might be reliably handled by a single prompt this year. Hardcoded constraints don't disappear on their own — they become legacy code that no one dares to delete.
Flowcharts assume the wrong invariants. State machines excel at processes with determined steps and limited branches. But judgments in real business are often fuzzy — how to prioritize, who this piece of information should be routed to, what counts as "good enough evidence." Cramming these judgments into nodes and edges means using the rigidity of engineering structures to approximate the flexibility of business semantics, inevitably generating a large amount of exception handling.
Domain experts are locked out of the system. In a purely code-orchestrated solution, adjusting behavior means changing code, testing, and deploying. But the people who truly understand business priorities are usually operations staff or domain experts, not engineers. Translating behavior definitions into plain-English profiles shortens the feedback loop from business intent to system behavior.
Workaround here specifically refers to hardcoded patches written to compensate for gaps in the model's current capabilities — for example, forcing the model to output a fixed format at a certain node, jumping to a branch upon detecting specific keywords, or repeatedly emphasizing in the prompt "don't do something." What these patches have in common is that they're tied to the current model's deficiencies rather than the essence of the business. Their hidden cost: the more patches there are, the more system behavior depends on a fragile coupling between prompts and code; when models upgrade, patches often aren't proactively cleaned up, instead becoming legacy logic that's hard to judge as still necessary, raising the cognitive burden of subsequent modifications.
Evals (evaluation sets) refer to test collections used to systematically measure the quality of agent outputs, typically composed of input samples and judgment criteria, where judgment can be exact matching, rule validation, or model scoring (LLM-as-judge). In a verification-first architecture, evals take on the correctness-guaranteeing responsibility previously borne by flowchart nodes, so their coverage and the rigor of judgment criteria directly determine system reliability. The challenge is that open-ended tasks lack a single correct answer, requiring tiered judgment criteria and continuous feeding of real failure cases back into the evaluation set — itself an engineering effort requiring long-term investment.
The Real Costs: Don't Ignore the Trade-offs
This approach sounds elegant, but the author himself doesn't shy away from its costs — which is precisely what makes the discussion worth referencing.
Tokens and latency. Letting the model plan its own execution loop means more reasoning steps and longer context. Compared to workflows following fixed paths, each step may incur additional model-call overhead. For latency-sensitive scenarios, this is a hard constraint.
Sandbox security. The key to "childproofing" is that environmental boundaries must be genuinely hard boundaries — the file system, network access, and data writes must all be truly restricted. If the boundaries are merely gentleman's agreements in prompts, the security of the entire architecture is out the window. The author explicitly lists sandbox security as a trade-off that needs serious attention, not a detail to gloss over.
The premise of the evaluation system. Test-driven evals require you to be able to define what "did it right" means. This is easy for counting, formatting, and data integrity, but hard for open-ended judgments. A verification-first architecture shifts complexity from "orchestration" to "evaluation" — the latter is no simpler than the former.
Sandbox is an isolated execution environment at the operating system or container level, limiting the files, network, and system calls a process can access through mechanisms like namespaces, permission controls, and resource quotas. In the agent context, what distinguishes a sandbox from "prompt constraints" is that it's a mandatory boundary: even if the model is induced or hallucinates into performing dangerous operations, the sandbox will refuse at the kernel or runtime level. For "childproofing" to hold, code execution, file reads/writes, and external API calls must all fall within the sandbox, complemented by the principle of least privilege — otherwise the so-called environmental constraints degenerate into soft suggestions that the model can bypass.
What This Means for Agent Engineering
Setting aside the prototype's completeness, this discussion points to a shift already underway: the center of gravity in agent engineering is moving from "how to string steps together" to "how to define boundaries and verify outcomes."
If model capabilities continue to strengthen, then in the long run, the most valuable engineering investment is not writing more sophisticated flowcharts, but building more reliable execution environments, stricter code-level verification, and evaluation sets that better reflect real business goals. The former depreciates with model iteration; the latter continues to appreciate.
The author jokes in the post that "despite all the childproofing metaphors, I'm not a parent," and invites everyone to dissect his architecture. The invitation itself is worth answering: rigid workflows aren't wrong — they remain effective in scenarios where model capabilities are insufficient and processes are highly deterministic. The real question is, when models can already reason on their own, are we still using strong models the way we constrain weak ones?
The answer may vary by scenario, but it's at least worth every agent builder asking again: Does the workflow I wrote amplify the model's capabilities, or is it doing for the model what it can already do itself?
Related articles

T3 Code: The Open-Source AI Coding Assistant's Comeback Story
T3 Code is an open-source AI coding assistant that unifies subscriptions like Codex and Claude, with powerful remote control and parallel task management.

Never Elected, Yet Ruled New York for 30 Years: The Ultimate Case Study in the Mechanics of Power
Robert Caro's biographies reveal how unelected Robert Moses ruled New York for 30 years through legal drafting and public authorities, and how Lyndon Johnson built leverage as a "powerless" Senate Majority Leader. Unpacking the underlying logic of accumulating and sustaining power.

The CPython 3.10 Recursion Trap and Synthetic Recovery in TokenGuard, an LLM Circuit Breaker
TokenGuard's author recounts a recursion crash caused by OrderedDict.pop in CPython 3.10 and introduces v0.3.0's Loop Nudge synthetic recovery, inline DLP scanning, and other new LLM agent circuit-breaker capabilities.