The Value of Weak Supervisors: What the Student Inherits, Not How Accurate the Supervisor Is

The value of a weak supervisor depends on the errors the student model inherits, not on its own accuracy.
This article challenges the common practice of selecting supervisors by labeling accuracy in weak supervision, arguing that a supervisor's value is relative to the student model: for squared loss and linear learners, value is determined by the error after the student's learning operator, so the same supervisor can have vastly different value for different students. Student-relative value cannot be directly identified from unlabeled data, but the missing information can be compensated by finite-dimensional projections and a small amount of clean labels, with the cost of clean-label compensation determined by the geometry of unresolved directions. Under Gaussian designs, the paper quantifies when exact teacher structure outperforms ordinary stacking and when weak supervisors combined with clean labels beat using clean labels alone. The practical takeaway: when weighting supervisors, consider the student model's learning dynamics rather than relying solely on supervisor error rates.
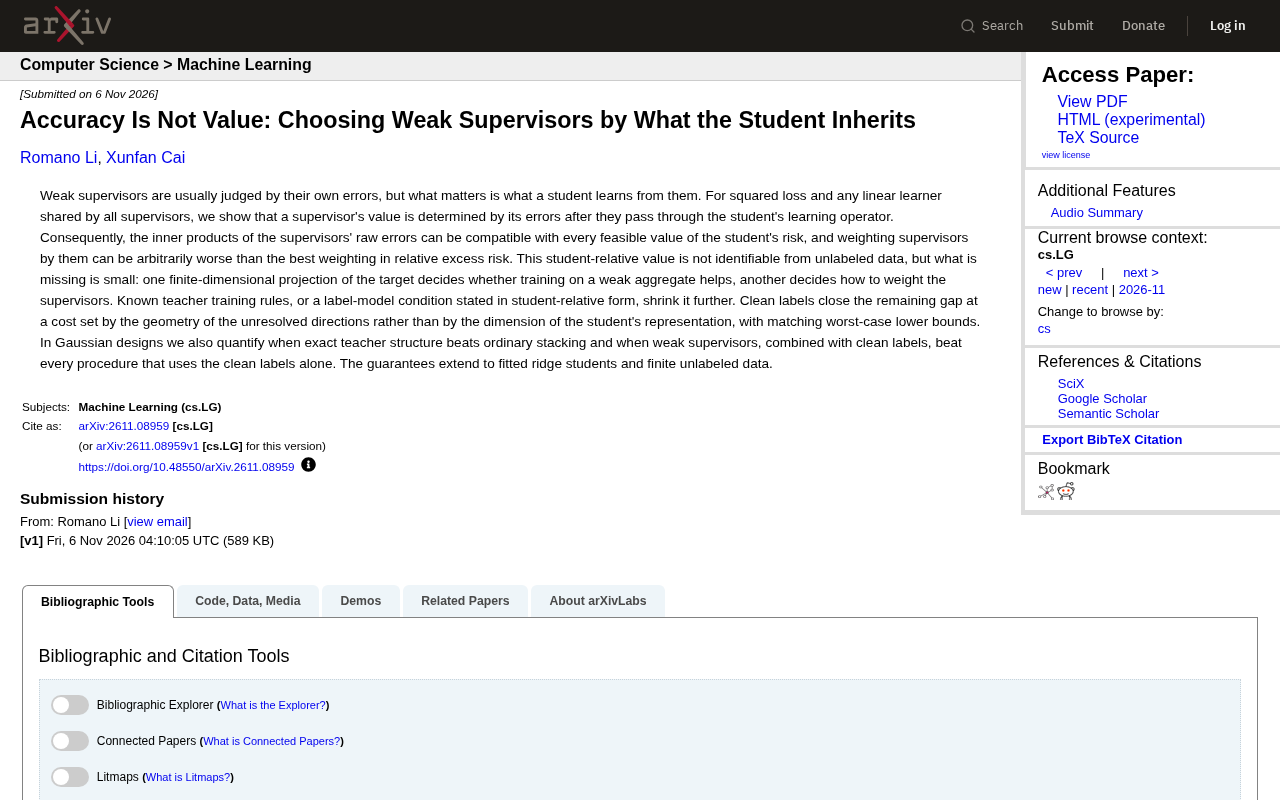
In weak supervision, we often use labeling accuracy to select and weight supervisors. But a new study makes a counterintuitive argument: the value of a weak supervisor is not determined by its own error rate, but by what the student model inherits from it. In other words, accuracy is not value.
Core Argument: Value Is Relative, Not Absolute
The paper opens by noting that we usually judge a supervisor by its own errors, but what really matters is what the student learns from it. For squared loss and any linear learner shared by all supervisors, the authors prove that a supervisor's value is determined by its error after passing through the student's learning operator.
This means the same weak supervisor can have vastly different value for different student models. The student does not directly copy the supervisor's errors; instead, its own learning process "filters" or "amplifies" them. Consequently, weighting supervisors by the inner product of raw errors can yield arbitrarily bad results—potentially far worse than the best weighting (in terms of relative excess risk).
Squared loss and linear learners: Squared loss is one of the most commonly used loss functions in regression tasks, defined as the square of the difference between the predicted value and the true value: $\ell(\hat{y}, y) = (\hat{y} - y)^2$. It penalizes large errors more heavily and has good mathematical properties (differentiable everywhere, convex), making it convenient for theoretical analysis. A linear learner refers to a model whose hypothesis space consists of linear functions, such as linear regression or ridge regression, where learning can be viewed as a linear combination of input features. The paper restricts its analysis to this setting because the learning operator of a linear learner has a closed-form expression, allowing "the error the student inherits from the supervisor" to be precisely characterized as the supervisor's error after a linear transformation. This provides a rigorous mathematical foundation for proving that "value is relative."
Identifiability: Student-Relative Value Cannot Be Directly Obtained from Unlabeled Data
The paper further points out that this "student-relative value" cannot be directly identified from unlabeled data—but the missing information is actually small: one finite-dimensional projection suffices to determine whether training on weak aggregation helps, and another projection determines how to weight the supervisors.
Some existing teacher training rules, or label model conditions expressed in student-relative form, can further close this gap. Clean labels can compensate for the remaining gap at a cost determined by the geometry of the unresolved directions (rather than the student's representation dimension), and the authors provide a matching worst-case lower bound.
Identifiability: In statistics and machine learning, identifiability refers to whether model parameters or target quantities can be uniquely determined from observable data. Here, "student-relative value" is a quantity that depends on the student model and learning algorithm, and with only unlabeled data (i.e., only features $X$ without labels $Y$), we cannot observe the relationship between supervisor errors and student errors, so this value is not identifiable. The paper notes that the missing information has limited dimensionality: one finite-dimensional projection determines "whether training on weak aggregation helps," and another determines "how to weight the supervisors." This means that although full identification is impossible, optimal decisions can be approximated by estimating these low-dimensional projections. Clean labels provide additional supervisory signals that can compensate for the remaining gap at a cost related to the geometry of the unresolved directions, and this cost does not grow with the student's representation dimension, thereby theoretically guaranteeing the efficiency of a small number of clean labels.
Theoretical Guarantees and Analysis under Gaussian Designs
Under Gaussian designs, the authors also quantify two scenarios:
- When exact teacher structure outperforms ordinary stacking;
- When weak supervisors combined with clean labels can beat all procedures that use only clean labels.
These guarantees also extend to fitted ridge students and the case of finite unlabeled data.
Gaussian designs: This refers to the setting where data features follow a multivariate Gaussian distribution, i.e., $X \sim \mathcal{N}(\mu, \Sigma)$. Gaussian designs are very common in theoretical analysis because they allow for closed-form risk expressions and precise phase transitions. Under Gaussian designs, the behavior of linear learners can be characterized by the eigenstructure of the covariance matrix $\Sigma$, enabling precise comparison of the expected risks of different supervisor weighting strategies. The paper uses this setting to quantify two scenarios: the superiority of exact teacher structure (i.e., knowing the covariance structure of supervisor errors) versus ordinary stacking (simple averaging or accuracy-based weighting), and whether weak supervisors combined with clean labels can outperform methods using only clean labels. These guarantees also extend to fitted ridge students and finite unlabeled data, enhancing the practical relevance of the conclusions.
Implications for Weak Supervision Practice
This research has direct implications for weak supervision practice: one cannot simply assign weights based on a supervisor's labeling accuracy. Instead, one should consider how the student model utilizes the supervisor's errors. In practice, this means evaluating a supervisor's value based on the specific student architecture and learning algorithm, rather than relying on generic accuracy metrics.
Moreover, the study shows that although unlabeled data cannot directly identify student-relative value, combining it with a small amount of clean labels can effectively approximate the optimal weighting. This provides a theoretical basis for designing more efficient weak supervision schemes in scenarios where labeling is costly.
Weak supervision and the teacher-student framework: Weak supervision aims to train models using multiple imperfect supervision sources (e.g., heuristic rules, crowdsourced annotations, distant supervision) without relying on large amounts of precise manual labeling. The teacher-student framework is a typical paradigm: multiple teachers (supervisors) provide noisy labels, and a student model trains on these labels. Traditional methods typically weight teachers based on their accuracy or confusion matrices, but this paper points out that a teacher's true value depends on the student model's learning dynamics—the student does not simply copy the teacher's errors but filters or amplifies them through its own hypothesis space and regularization. Therefore, weighting strategies should account for the student architecture and learning algorithm, for example by estimating low-dimensional projections of student-relative value to optimize weights, or by incorporating a small amount of clean labels for calibration. This provides new ideas for designing more efficient weak supervision schemes.
Conclusion
The view that "accuracy is not value" challenges a common assumption in weak supervision. It reminds us that a supervisor's value is relative to the student and can be approximated through finite-dimensional projections and a small amount of clean labels. For researchers and engineers, this means that when selecting and weighting weak supervisors, one should pay more attention to the student model's learning dynamics rather than focusing solely on the supervisor's own error rate.
Related articles
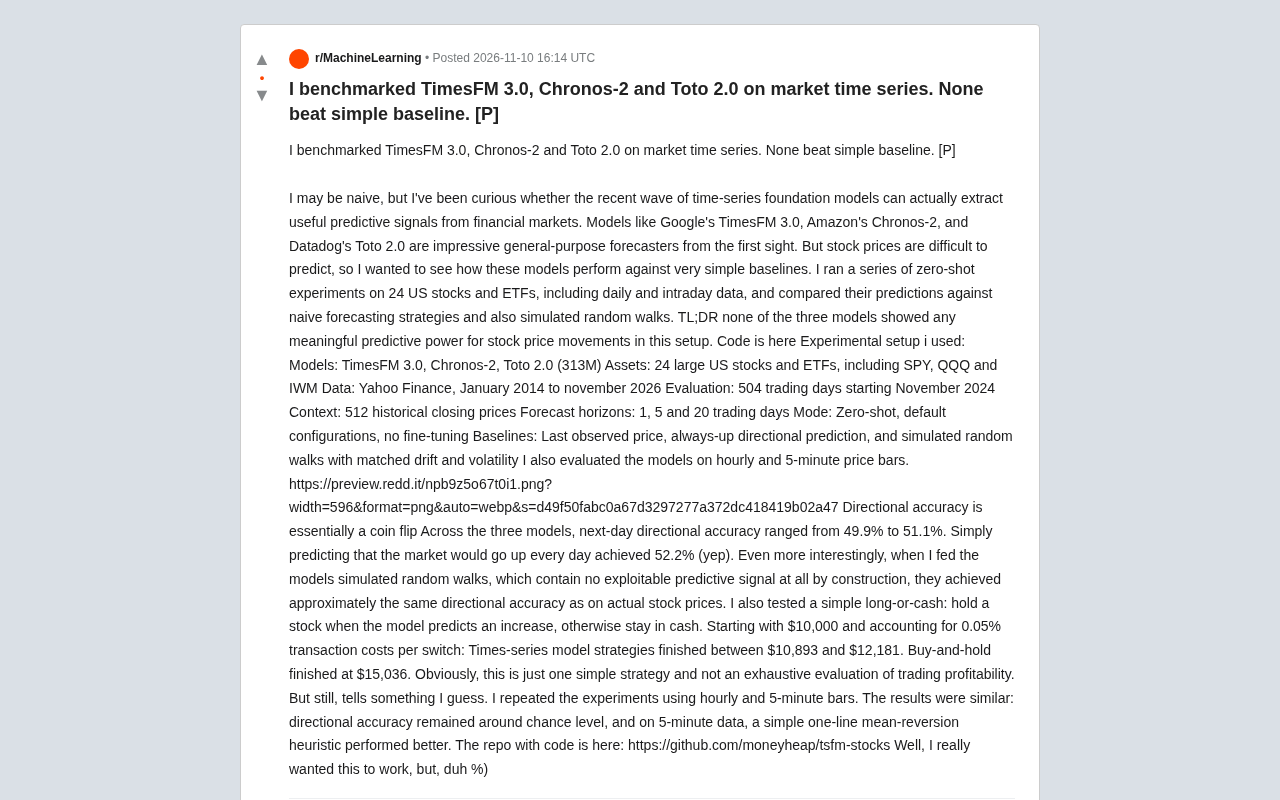
Putting TimesFM 3.0, Chronos-2, and Toto 2.0 to the Test: Time-Series LLMs Can't Beat Simple Baselines
A developer's zero-shot benchmark of TimesFM 3.0, Chronos-2 and Toto 2.0 on 24 U.S. stocks and ETFs: directional accuracy of just 49.9%-51.1%, and simulated trading underperformed buy-and-hold. Time-series foundation models show no edge over simple baselines on financial data.
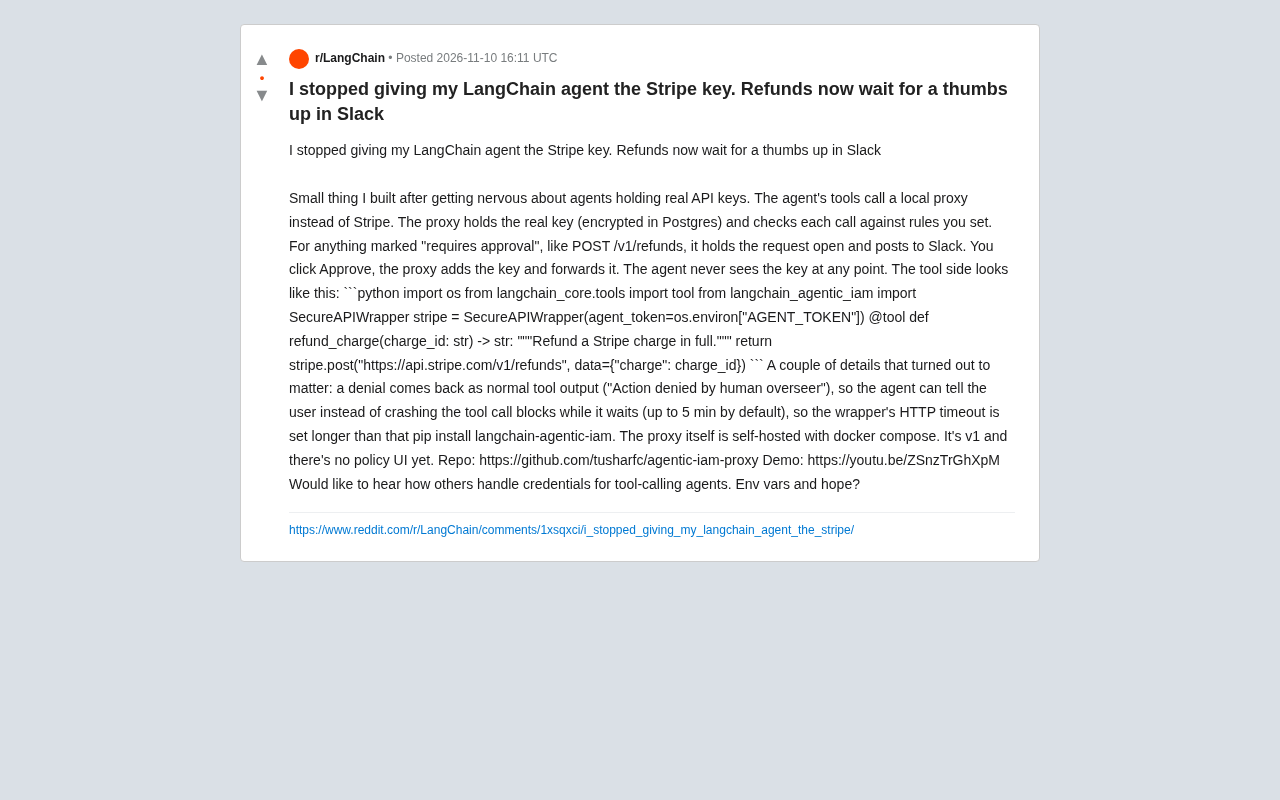
LangChain Agents No Longer Hold Stripe Keys: Refunds Require Slack Approval
A developer shares a credential management approach for LangChain agents: agents don't hold Stripe keys, and sensitive operations like refunds are forwarded through a local proxy and only executed after human approval in Slack, with code examples and engineering details.
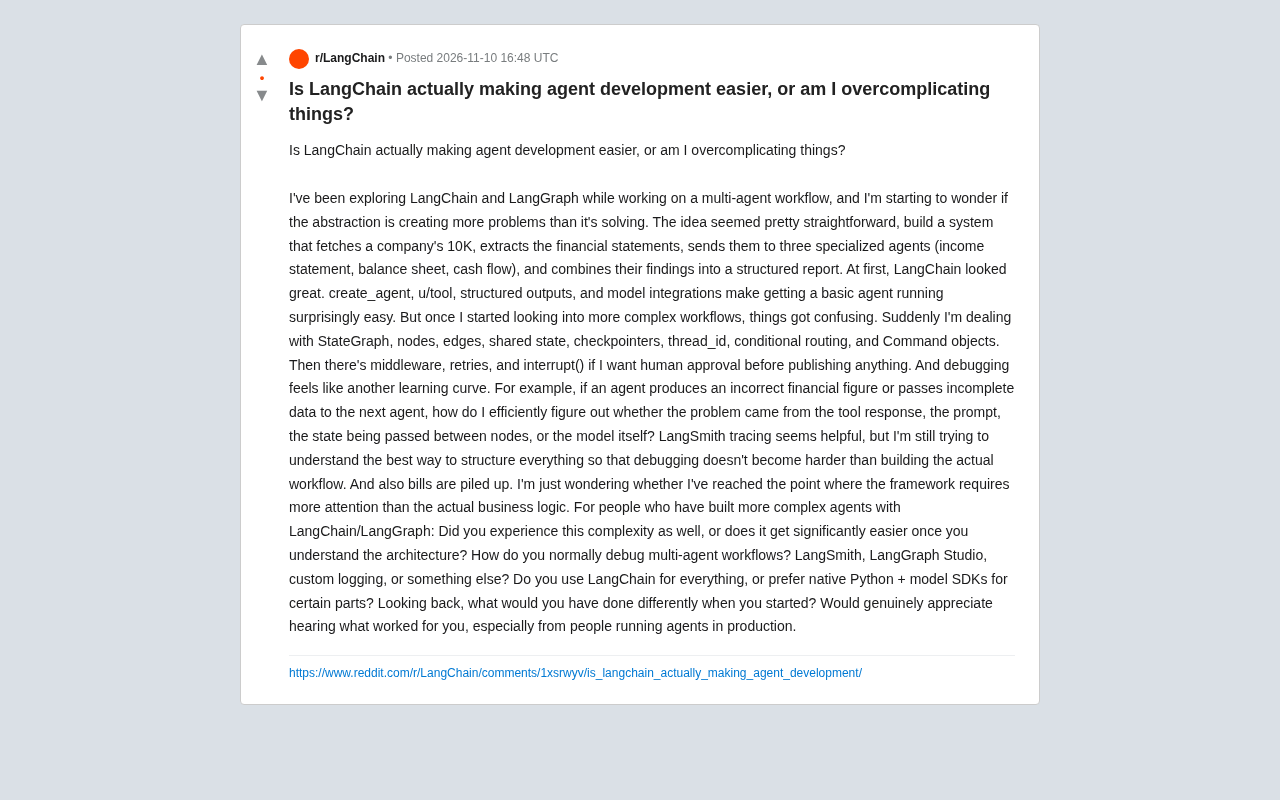
Does LangChain Really Make Agent Development Easier? A Developer Reflects on the Cost of Abstraction
A Reddit developer reflects on the abstraction cost of LangChain and LangGraph in multi-agent workflows: easy to start, but StateGraph, state management, debugging, and cost control add new complexity. The discussion covers debugging methods, whether to mix native Python + model SDKs, and production trade-offs.