Think Before You Link: How Reasoning + Retrieval Tackles Rare Entity Linking in Multilingual Settings

Training-free reasoning + retrieval raises rare entity linking accuracy by up to 23.3% on the MERLIN multilingual benchmark.
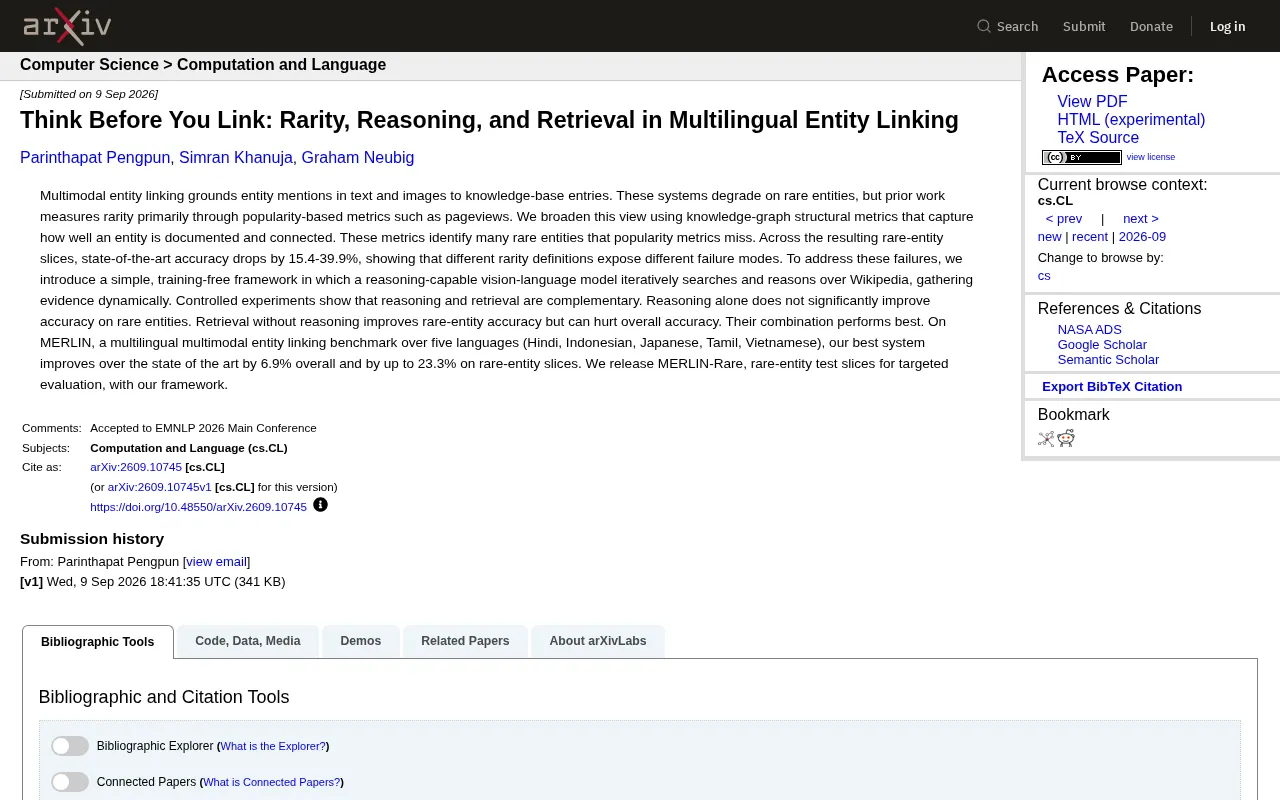
The arXiv paper *Think Before You Link* addresses the long-overlooked problem of rare entities in multimodal entity linking. It shows that measuring rarity by Wikipedia pageviews alone is fundamentally flawed — entities that are isolated and sparsely documented in the knowledge graph are invisible to popularity metrics, yet cause state-of-the-art systems to lose up to 39.9% accuracy. The proposed training-free framework has a vision-language model iteratively retrieve evidence from Wikipedia and reason dynamically over it. Ablations confirm that reasoning and retrieval are mutually necessary: reasoning alone cannot cover knowledge gaps, while retrieval without reasoning introduces noise. On the five-language MERLIN benchmark, the framework achieves a 6.9% overall accuracy gain and up to 23.3% on rare entity slices, with the MERLIN-Rare evaluation set released as an open resource.
The Hidden Weakness of Entity Linking: Why Rare Entities Get Left Behind
Multimodal Entity Linking is a foundational technology that bridges natural language processing and knowledge bases. Its job is to map entity mentions — references to people, places, or organizations in text and images — to their corresponding entries in a knowledge base. When a passage or photo references a specific individual, location, or organization, the system must determine exactly which record in the knowledge base it corresponds to.
This capability underpins information retrieval, question answering, and knowledge graph construction. Yet a new arXiv paper, Think Before You Link, exposes a long-overlooked weakness in these systems: even state-of-the-art models fail significantly when dealing with rare entities.
Redefining Rarity: Knowledge Graph Structural Metrics Beyond Popularity
The Limits of Traditional Popularity-Based Metrics
Prior research has almost universally relied on popularity-based metrics to determine whether an entity is "rare" — most commonly Wikipedia pageviews. The intuition is straightforward: entities with few views appear less often in training data, so models are naturally more likely to get them wrong.
The authors argue, however, that popularity alone misses a large class of genuinely difficult entities. They introduce knowledge-graph structural metrics, which assess rarity based on how completely an entity is documented in the knowledge base and how richly it is connected to other entities.
Evaluation Blind Spots Revealed by the Structural View
The findings are striking: these structural metrics surface many rare entities that popularity signals miss entirely. An entity can have a respectable pageview count yet be an "island" in the knowledge graph — sparsely documented and poorly connected — and these entities pose just as much of a challenge to models.
On the rare-entity slices identified through structural metrics, accuracy on current state-of-the-art systems drops by a remarkable 15.4% to 39.9%. This strongly demonstrates that different definitions of rarity expose different types of failure. A single popularity-based lens is far from sufficient to fully assess system robustness.
The Solution: A Training-Free Reasoning + Retrieval Framework
Core Design Philosophy
To address these failure modes, the researchers propose a simple, training-free framework. The key idea is to have a reasoning-capable vision-language model work the way a human researcher would:
- Iterative search: repeatedly querying Wikipedia for relevant information
- Dynamic reasoning: analyzing and drawing inferences from retrieved evidence
- Evidence accumulation: progressively gathering clues and refining conclusions rather than producing a one-shot answer
This "think while you look" mechanism is exactly what the paper's title, Think Before You Link, captures.
Validating the Complementarity of Reasoning and Retrieval
One of the paper's most valuable contributions is a set of carefully designed ablation experiments that cleanly separate the contributions of reasoning and retrieval:
- Reasoning alone: no meaningful accuracy gain on rare entities. The model's internal knowledge has clear limits — pure "thinking" cannot fill a knowledge gap.
- Retrieval without reasoning: improves accuracy on rare entities, but can hurt overall performance. New information is brought in, but without the ability to effectively filter and integrate it.
- Reasoning combined with retrieval: best overall performance. Retrieval supplies external evidence; reasoning handles selection and synthesis. The two genuinely complement each other.
This finding provides solid empirical backing for the growing trend of combining RAG (Retrieval-Augmented Generation) with reasoning-capable models.
MERLIN Multilingual Benchmark: Up to 23.3% Improvement
The team evaluated the framework on MERLIN, a multilingual multimodal entity linking benchmark covering five languages: Hindi, Indonesian, Japanese, Tamil, and Vietnamese — languages that are typically under-resourced in NLP research and thus provide a more demanding test of cross-lingual generalization.
The results are impressive:
- Overall accuracy improves by 6.9% over the current state of the art
- On rare entity slices, improvement reaches as high as 23.3%
The gains are most pronounced precisely where the baseline systems are weakest — rare entity scenarios.
Open Resource MERLIN-Rare: A New Standard for Rare Entity Evaluation
To support future research, the team also releases MERLIN-Rare — a set of test slices specifically targeting rare entities, open-sourced alongside their framework. This gives the research community a focused evaluation tool that allows rare entity handling to be measured independently and precisely.
Takeaways: Three Lessons from the Reasoning–Retrieval Combination
The significance of this work goes beyond benchmark scores. It offers three deeper insights:
How we evaluate determines what problems we see. When the research community relies solely on popularity to measure rarity, structurally rare entities are systematically overlooked, leading to overly optimistic assessments of model capability.
Reasoning and retrieval are natural partners. When tackling problems that lie beyond a model's knowledge boundary, external evidence and reasoning ability are both essential — neither alone is sufficient.
Training-free frameworks are increasingly practical. In the era of large language models, intelligently orchestrating reasoning and retrieval can deliver substantial performance gains without the cost of retraining — an attractive path for real-world deployment.
Related articles

Fifty Years Studying Power: Robert Caro's Writing and Insights on Power
Robert Caro reflects on 50 years studying power: Lyndon Johnson's persuasion and leverage, Robert Moses's transformation from idealist to ruthless builder, the dilemmas of large-scale construction, and his methods of compressing themes and solitary focus in biography writing.

Can a $20,000 Robot Do Your Chores? The Test Results Are Surprising
A YouTube test video shows how a $20,000 robot responds to commands like washing dishes, turning off lights, taking out trash, and feeding the dog. This article analyzes its real capability boundaries, the state of voice interaction technology, and how far household robots are from mainstream adoption.
The Complete Guide to Running AI Models Locally: Inference Engines and Tool Stack Explained
A systematic breakdown of the complete local LLM tool stack: from PyTorch and GGML compute libraries to llama.cpp, vLLM, SGLang inference engines and Ollama, LM Studio wrapper layers, with benchmark data on performance differences and selection logic.