Unsloth v0.1.801 Update: Auto Compaction and LAN Remote Access Explained

Unsloth v0.1.801-beta adds auto context compaction, LAN remote access, and 200+ performance improvements.
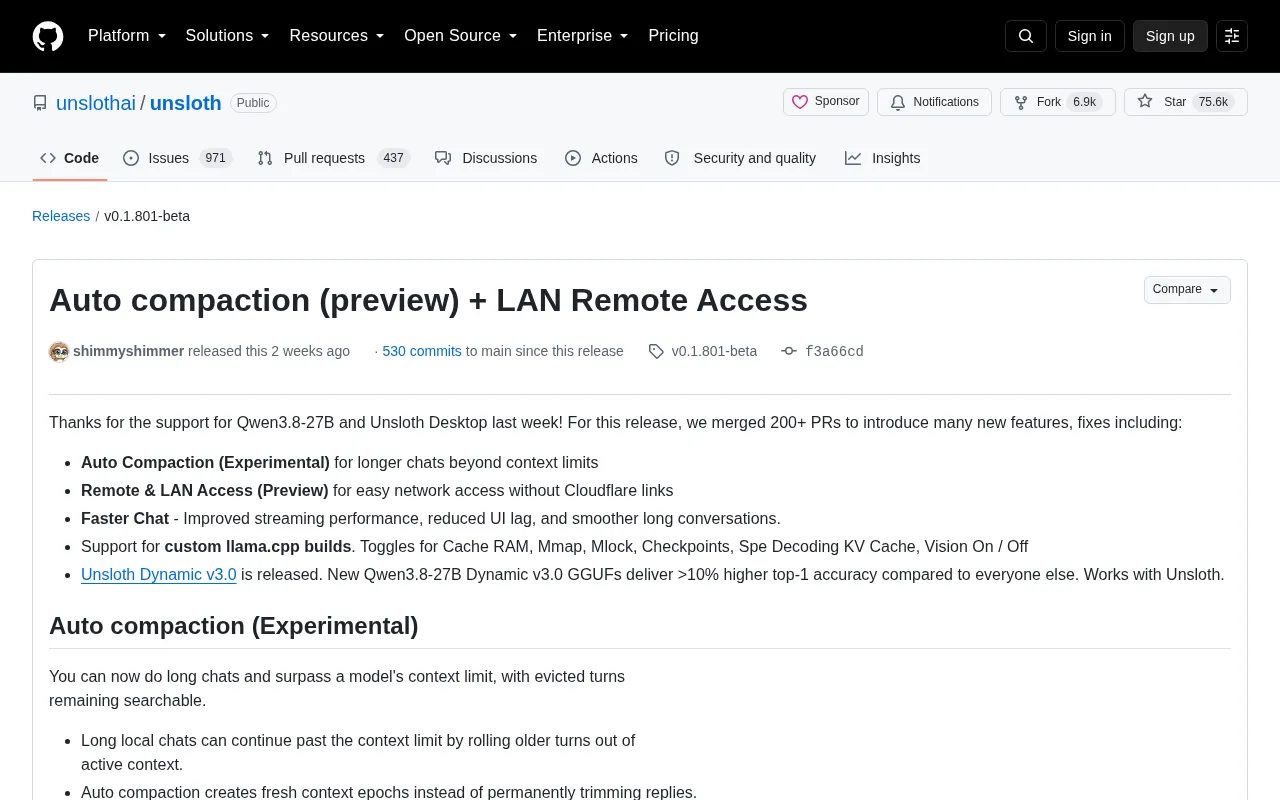
Unsloth v0.1.801-beta is a major update merging over 200 PRs. The two headline features are Auto Compaction — which uses a "context epochs" mechanism to archive evicted conversation history into a lexical-first RAG pipeline for precise recall — and LAN Remote Access, enabling cross-device connections to local model instances without Cloudflare tunnels, with security enforced via default-off settings and mandatory password change. The update also includes major streaming render performance gains, a Projects workflow system, Intel XPU support, improved ROCm/flash-attention compatibility, and Unsloth Dynamic v3.0 quantization with over 10% accuracy improvement. Both headline features remain experimental/preview.
The open-source LLM tool Unsloth recently released v0.1.801-beta, merging over 200 PRs in a single update and introducing several notable new features. The two standout additions are Auto Compaction and LAN Remote Access, alongside a wide range of improvements to inference performance, hardware compatibility, and training workflows. This article dives deep into the core value of this release based on official announcements.
Auto Compaction: Breaking Through Context Length Limits
For users running LLMs locally, context length limitations have long been a pain point in extended conversations. When a dialogue exceeds the model's context window, earlier content is typically truncated permanently — causing the model to "forget" key information mentioned earlier in the conversation. Unsloth's new Auto Compaction feature offers a more elegant solution.
How Auto Compaction Works
Unlike traditional truncation or summarization approaches, Unsloth's Auto Compaction uses a "context epochs" design:
- Whole-turn eviction: Only the earliest complete conversation turns are removed when necessary, and messages are never cut mid-way — the saved transcript remains intact.
- Searchable archive: Evicted turns are indexed into a per-thread searchable archive via Unsloth's existing RAG pipeline (storage, chunking, embedding, retrieval).
- Lexical search first: Since conversational lookups tend to be exact matches (names, numbers, IDs, etc.), the system prioritizes lexical search over semantic search.
- Forced recall: A recall is triggered at eviction time rather than relying on the model to search on its own, with subsequent retrieval handled via
search_conversation. - Cross-epoch persistence: The archive persists across multiple epochs, enabling future compactions to recover previously evicted context.
Notably, the team explicitly abandoned the summarization approach — real-world testing showed minimal benefit while adding roughly 190 seconds of overhead per compaction event. This pragmatic engineering decision reflects Unsloth's clear focus on performance.
LAN Remote Access: Cross-Device Access Without Cloudflare Tunnels
The second major update is LAN Remote Access. Previously, accessing a locally running Unsloth instance from another device required third-party solutions like Cloudflare Tunnels — cumbersome to configure and introducing external dependencies.
The new version adds a dedicated remote access section in settings, with the following highlights:
- Enable or disable LAN access without restarting;
- Provides connection addresses, QR code scanning, and optional auto-start;
- LAN access is disabled by default for security, and the system-generated admin password must be changed before it can be enabled.
This design strikes a good balance between convenience and security. Users can easily access their local LLM from a phone, tablet, or another computer, while the default-off policy and mandatory password change reduce the risk of accidental exposure.
Comprehensive Chat and Inference Experience Improvements
Beyond the two headline features, this update brings numerous quality-of-life improvements.
Better Streaming Performance for Long Conversations
The team invested heavily in optimizing streaming output and thread handling, significantly reducing UI stuttering. Looking at the merged PRs, considerable effort went into rendering performance — for example: "stop re-reading the entire reply on every streaming chunk", "stop re-rendering every message fragment on each stream block", and "don't re-render the entire thread when deleting a message". These low-level optimizations make long conversations noticeably smoother.
Projects: Organized Workflows
The new Projects feature lets you organize chats, files, and workspaces together. Chats can now remember composer settings, system prompts, and model sampling options. A prompt queue has been added (queue with Cmd/Ctrl+Enter and drag to reorder), along with customizable keyboard shortcuts. An edit_file tool is also included for partial file modifications, and tool-calling and MCP behavior have been improved.
Deep Hardware Compatibility and Inference Engine Enhancements
At the infrastructure level, this update adds support for custom llama.cpp builds and exposes multiple advanced settings toggles, including Cache RAM, Mmap, Mlock, Checkpoints, speculative decoding KV cache, and vision feature toggles.
Hardware compatibility improvements are particularly extensive:
- New Intel XPU support;
- Improved compatibility across ROCm, xFormers, and flash-attention configurations;
- Optimized MTP performance and VRAM handling;
- Better validation for missing GPU support and oversized GGUF models, preventing models from loading when they exceed available VRAM plus system RAM.
Unsloth Dynamic v3.0 Quantization and Model Accuracy
This release also ships Unsloth Dynamic v3.0. According to official benchmarks, the new Qwen3.8-27B Dynamic v3.0 GGUF achieves over 10% higher top-1 accuracy compared to alternatives. This advance in quantization technology means users can deploy quantized models locally with smaller file sizes while achieving better output quality — a meaningful improvement for resource-constrained local inference.
On the API and serving side, the Responses API now supports structured output formats, llama-server crash recovery has been improved, and support for OpenCode V2 has been added.
Summary
Unsloth v0.1.801-beta is a substantial and well-grounded release. Auto Compaction addresses the long-context problem with a thoughtful engineering approach, LAN Remote Access dramatically lowers the barrier to cross-device usage, and the 200+ merged PRs deliver meaningful performance and compatibility improvements that strengthen the tool's foundation. For developers and enthusiasts running LLMs locally, this update is well worth trying out immediately. That said, Auto Compaction is still in experimental status and Remote Access is in preview — keep an eye on stability as you use these features.
Related articles

world2vec: Building Mechanistic World Models with Latent Dynamics Learning
world2vec proposes a reward-free method for learning mechanistic world models via latent dynamics, faithfully reproducing systems over long horizons with at least an order of magnitude fewer parameters than DreamerV3, TD-MPC2, and LeWM, and achieving accurate system identification on 71 attractor benchmarks.

A New KL-DRO Paradigm: Adaptive Scenario Generation Around a Learned Density Model
KL-DRO research proposes centering the KL ball on a learned density model instead of the empirical distribution, with adaptive scenario generation guiding sampling toward the worst case. Experiments show lower cost under distribution shift when records are scarce and the model can extrapolate, with comparable in-distribution cost.

ODE Samplers for Discrete Diffusion Models: Exponential Residual Flows Accelerate Generation
Discrete diffusion models lack deterministic ODE sampling? This article introduces Exponential Residual Flows (ERFs), which introduce continuous residual variables per token to construct piecewise ODEs for deterministic sampling and support consistency distillation acceleration. Superior to prior methods on code and text generation tasks.