WeLM-Image: How a Unified Image Generation Model Lands on WeChat

WeLM-Image balances understanding, generation, and editing under single-GPU constraints with a unified architecture; Turbo generates images in 4.98 seconds with eight steps.
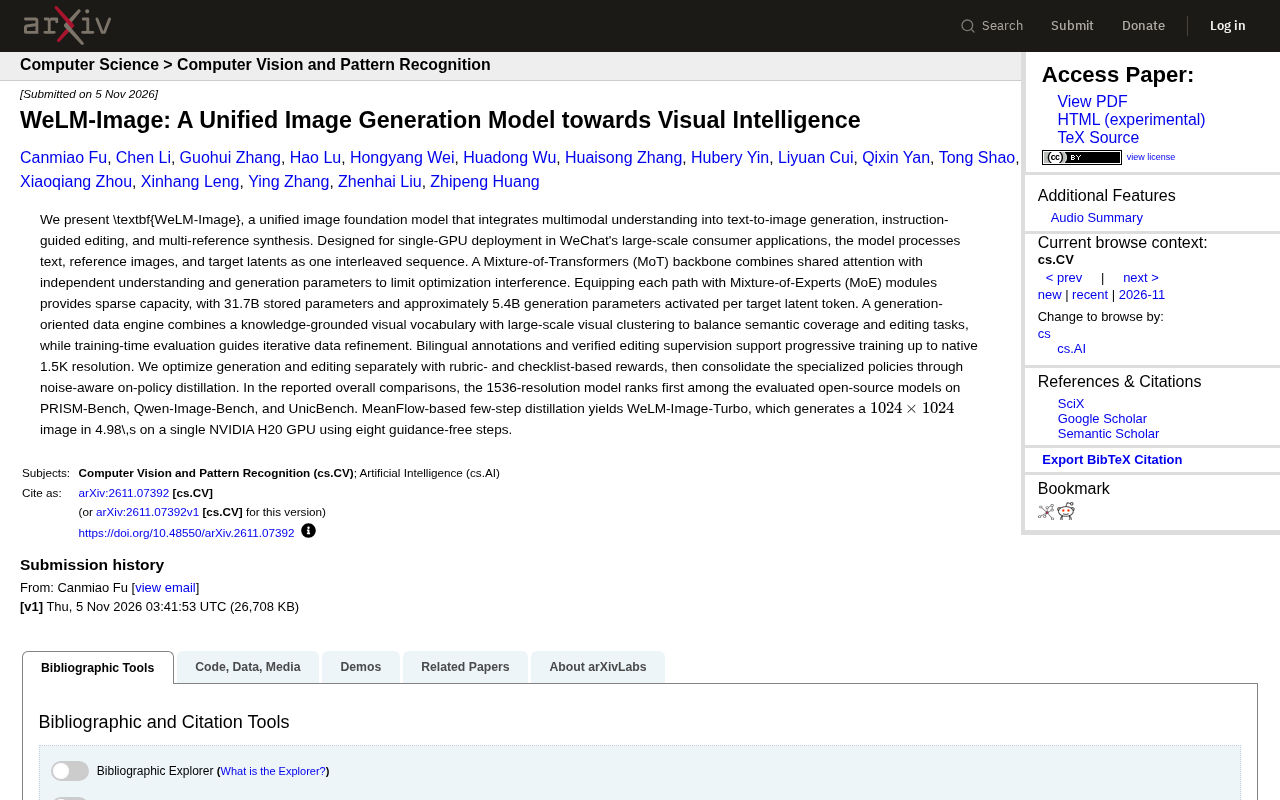
WeLM-Image is a unified image foundation model designed by WeChat for large-scale consumer applications, integrating multimodal understanding, text-to-image, instruction editing, and multi-reference synthesis into one interleaved sequence. It uses an MoT backbone with shared attention but separate understanding and generation parameters, plus MoE sparse modules per path, with 31.7B total parameters and about 5.4B activated per token for single-GPU deployment. Data uses a knowledge-anchored visual vocabulary and large-scale visual clustering, with bilingual annotation and verified editing supervision for progressive training to native 1.5K. Training first optimizes generation and editing separately with rubric/checklist rewards, then merges via noise-aware on-policy distillation. The Turbo version, based on MeanFlow few-step distillation, generates a 1024×1024 image in 4.98 seconds in eight steps on a single H20; the 1536 version self-reports ranking first among open-source models on three evaluations.
Behind WeChat's visual generation capabilities is a unified image foundation model designed for single-GPU deployment. WeLM-Image integrates multimodal understanding, text-to-image, instruction-guided editing, and multi-reference synthesis into a single architecture, with the goal of staying deployable in large-scale consumer applications—this balance between "breadth of capability" and "engineering constraints" is what makes it most worth noting.
Unified architecture: one interleaved sequence handles three task types
The core design of WeLM-Image treats text, reference images, and target latents as a single interleaved sequence. This means the understanding path and the generation path share the same attention computation, rather than stitching together multiple independent modules.
To prevent understanding and generation tasks from interfering with each other during optimization, the model uses a Mixture-of-Transformers (MoT) backbone: shared attention layers, but understanding and generation each retain independent parameters. On top of this, each path is equipped with Mixture-of-Experts (MoE) modules to expand capacity in a sparse manner. According to the original article, the model has 31.7B total stored parameters, while the generation parameters activated per target latent token are about 5.4B.
This combination of "sharing + separation + sparsity" is essentially answering an engineering question: how to preserve both the understanding and generation capability lines under the constraint of single-GPU deployment.
Why single-GPU deployment is a hard constraint
The original article explicitly states that the model is designed for WeChat's large-scale consumer applications and for single-GPU deployment. This premise profoundly influenced the architectural choices—the sparse activation brought by MoE, as well as the subsequent few-step distillation, are all means serving to control actual inference cost, rather than a pursuit of performance for its own sake.
Mixture-of-Experts (MoE) is a sparsely activated model architecture: the network contains multiple parallel "expert" feed-forward sub-networks and a gating mechanism responsible for routing, and each token is assigned to only a few experts for computation. This way, the total parameter count (storage footprint) of the model can be much larger than the number of parameters actually involved in computation per token (activation), thereby expanding model capacity with almost no increase in per-step inference compute. WeLM-Image leverages exactly this to keep the generation activation per target latent token at about 5.4B under 31.7B total parameters, making single-GPU deployment possible. The cost is that VRAM still needs to hold all expert weights, and routing imbalance affects training stability, so expert parallelism and load-balancing loss are common engineering accompaniments for such architectures.
Mixture-of-Transformers (MoT) is a variant structure of the multimodal Transformer. Its approach is to retain independent feed-forward layers and normalization parameters for different modalities (here, the understanding path and the generation path) within the same attention framework, sharing weights only at the attention layers. Compared with "using one Transformer to hard-handle all modalities," MoT gives different tasks dedicated capacity and reduces gradient conflicts; compared with "stitching multiple models together," it retains cross-modal attention interaction, allowing reference images, instruction text, and target latents to see each other in the same attention computation. This is two sides of the same design as the article's statement of "one interleaved sequence handles three task types": the sequence is the data organization method, and MoT is the parameter organization method.
Data engine: equal emphasis on semantic coverage and editing supervision
The difficulty of a unified model lies not only in architecture but also in data mixing. WeLM-Image's generation-oriented data engine combines a "knowledge-anchored visual vocabulary" with "large-scale visual clustering"; the former ensures semantic coverage, while the latter supports editing-type tasks. During training, evaluation in turn guides iterative data refinement, forming a closed loop.
The original article also mentions bilingual annotation and verified editing supervision, supporting progressive training of the model up to native 1.5K resolution. For products serving Chinese-language scenarios, bilingual annotation is not a bonus but a necessary foundation.
Training strategy: strategy integration by separating first, then merging
Generation and editing are optimized separately: using reward signals based on rubrics and checklists. Then, through noise-aware on-policy distillation, the two specialized policies are integrated together.
This "divide and conquer, then merge" approach avoids the two task types pulling against each other under a single reward signal. Compared with direct joint training, it more easily preserves quality on editing, a task with high requirements for instruction following.
Turbo version: near 5-second image generation on a single GPU
Few-step distillation based on MeanFlow produced WeLM-Image-Turbo: on a single NVIDIA H20 GPU, using eight-step guidance-free sampling, generating one 1024×1024 image takes 4.98 seconds. This number has direct significance for the interactive experience of consumer-grade products.
MeanFlow is a class of flow matching training methods oriented toward few-step generation. Conventional diffusion or flow models require dozens of iterations to approximate a probability flow path from noise to data, whereas MeanFlow directly learns the "average velocity field" along that path, i.e., using the network to predict the mean displacement from one time to another rather than the instantaneous velocity. This identity constraint enables the model to maintain trajectory accuracy even under large step sizes, thereby compressing the number of sampling steps to single digits. Combined with distillation, the student model can generate images within 4–8 steps. The Turbo in the article uses eight-step guidance-free sampling (i.e., no additional dual forward computation for classifier-free guidance), which is precisely the key to needing only 4.98 seconds for 1024×1024—both the number of steps and the number of forward passes per step are reduced.
On-policy distillation refers to using trajectories sampled by the current policy model itself as training data, then having a teacher signal (here, rubric/checklist rewards or a combination of multiple teachers) correct and score them, and the student updates accordingly. Unlike offline distillation using a fixed dataset, on-policy has the student receive guidance on the state distribution it will actually reach, which can alleviate error accumulation caused by inconsistency between training and inference distributions, and is especially critical for few-step generation. The emphasis on "noise-aware" in the article means aligning teacher and student behavior separately at different noise levels (i.e., different generation moments), so that distillation holds along the entire sampling trajectory rather than only at the beginning or end.
Evaluation performance: its position among open-source models
In the overall comparison reported in the original article, the 1536-resolution version ranks first among the evaluated open-source models on three evaluations: PRISM-Bench, Qwen-Image-Bench, and UnicBench. It should be noted that these are comparison results self-reported in the original article; specific leaderboard details and evaluation criteria should be referred to in the original paper.
From a positioning perspective, the value of WeLM-Image is not in刷新ing刷新ing刷新ing refreshing some single metric, but in demonstrating a path: unified multi-task capability, bilingual data, single-GPU deployability, and few-step fast inference—these constraints can be satisfied simultaneously. For readers concerned with AI application deployment and the open-source tool ecosystem, this set of engineering trade-offs is more worth reading closely than rankings alone.
One-line Summary
WeLM-Image balances understanding, generation, and editing under a single-GPU constraint with a unified architecture; the Turbo version generates images in 4.98 seconds with eight steps.
Paragraph Summary
WeLM-Image is a unified image foundation model designed by WeChat for large-scale consumer applications, integrating multimodal understanding, text-to-image, instruction editing, and multi-reference synthesis into the same interleaved sequence for processing. Architecturally, it uses an MoT backbone that shares attention but separates understanding and generation parameters, and equips each path with MoE sparse modules, with 31.7B total parameters and about 5.4B activated per token, to adapt to single-GPU deployment. On the data side, it uses a knowledge-anchored visual vocabulary to ensure semantic coverage and large-scale visual clustering to support editing, and progressively trains to native 1.5K with bilingual annotation and verified editing supervision. In training, generation and editing are first optimized separately using rubric/checklist rewards, then merged through noise-aware on-policy distillation. The Turbo version is based on MeanFlow few-step distillation and takes 4.98 seconds to generate a 1024×1024 image in eight steps on a single H20; the 1536 version self-reports ranking first among open-source models on three evaluations.
Related articles
Hugging Face Open Together: The Carnival of Open Source AI and a Declaration of Decentralization
Hugging Face Open Together brings together global developers to showcase demos, emphasize open source AI as a public resource, and declare that the AI revolution must not be centralized.

Building a Netflix-Style Media Server with Claude: Just 15MB
A developer built Holyarrs, an all-in-one home media server app with Claude, just 15MB in size and ~70MB idle memory, consolidating six tools like Sonarr and Radarr.

A Hilarious Record of 0.5B Small Model Conversations Going Off the Rails: Why Is It Always Obama?
Reddit users share hilarious conversations with Qwen 0.5B small models that frequently derail to Obama, revealing the limits of small models in common-sense reasoning and the impact of quantization.