Who Reviews AI-Written Code? Claude Code Reveals Its Six-Layer Review Process

Claude Code team reveals its AI code review process: self-verification, six layers of sieves, and review stop-loss points.
The article presents Claude Code team's code review practices in a context where 90% of code is AI-generated. Its core is three key points: requiring AI to self-verify before submission—running tests, running builds, and screenshotting against design mockups—plus deploying an "AI alter ego" to nitpick the final changes, estimated to improve quality two to three times; using six layers of stacked sieves with risk-graded approval—low-risk machine approval, ordinary changes one-person approval, high-risk two-person approval—backed by one-click rollback; and setting stop-loss points for AI reviewing AI, with three failed rounds triggering a rethink, after which only new changes are reviewed and similar issues are reported all at once, bringing reviews past five rounds down from nearly 10% to 1.5%. Human duties focus on setting direction, reviewing high-risk code, examining evidence, and taking responsibility.
When 90% of code is generated by AI, traditional line-by-line human review is clearly no longer feasible. The Claude Code team recently disclosed their code review process, an approach that has cut the proportion of changes requiring rollback by over 40% even as merged changes have doubled. So how should code review work in the AI era? Three key points are worth paying attention to.
Point 1: Prove It First, Then Submit
Don't let AI get away with a simple "done." The team requires AI to provide evidence before submitting code: run tests, run builds, and take screenshots to compare against design mockups. According to Claude Code's Boris, this single measure alone can improve code quality to two or three times its original level.
In addition, an "AI alter ego" is dispatched specifically to nitpick—it ignores the process and looks only at the final change, hunting for problems. This dual-AI collaboration model makes the pre-submission self-check more reliable.
AI alter ego nitpicking is an "adversarial review" model: the reviewer and the producer are different model instances, and the reviewer is forbidden from referencing the generation process—it only sees the diff. This avoids "explanatory bias"—producers tend to defend their own changes. This practice is known in the industry as LLM-as-a-Judge, and its reliability depends on whether the review prompt clearly lists a checklist (security, edge cases, test coverage, style consistency) and whether the reviewer is required to give verifiable localization (file, line number, reproduction steps) rather than vague assessments.
Point 2: Not One Gate, But Six Layers of Sieves
A single layer of review is easy to miss things, but when six layers of sieves are stacked, it's very hard for anything to slip all the way through. The team designed a multi-layer filtering mechanism, with each layer responsible for different inspection dimensions. And if something does slip through, there's one-click rollback as a fallback.
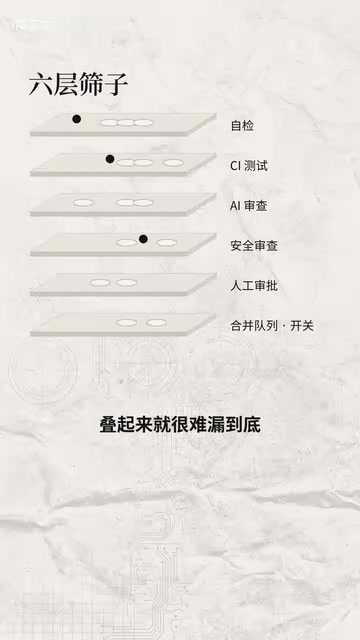
Approval authority is graded by risk: for low-risk changes like documentation edits, machines can approve everything, and team members can merge directly themselves; ordinary changes need one person's approval; the highest-risk changes require two people's approval. AI can approve low-risk changes, but it can never replace that one human vote.
Multi-level approval and risk grading is underpinned by the idea of "authorizing by blast radius": changes are tiered by scope of impact (documentation, configuration, business logic, core pathways), with different tiers corresponding to different numbers of approvers and intensities of automated checks. Typical layers include: static checks and formatting, unit tests, integration/end-to-end tests, security and dependency scanning, human or AI code review, and pre-release smoke verification. The more layers there are, the higher the probability that a single layer's missed detection is caught by subsequent layers, but it also increases latency and maintenance costs, so each layer needs a clear "interception responsibility" to avoid redundant checks.
Point 3: Restrain the Number of Review Rounds—AI Reviewing AI Needs a Stop-Loss Point
Why can't AI reviewing AI stop? Because AI is too obedient. When humans see minor issues, they glance and move on, but AI changes every single one, and each change triggers a new round of review. Moreover, the reviewing AI doesn't report all problems at once—nearly 60% of repeatedly reported issues already existed in the first round.
The team set a rule: if it doesn't pass after three rounds, stop and rethink the approach; afterward, only review new changes, and similar issues must be reported all at once. As a result, reviews dragging past five rounds dropped from nearly 10% to 1.5%.
Review stop-loss point draws on WIP limits and the "rule of three" from engineering management: when the same change still can't converge after multiple rounds, it usually means the approach itself is flawed, not the details. Setting the constraint that the reviewing AI must "report similar issues all at once" essentially requires it to output a structured, deduplicated, complete issue list (sortable by severity) rather than piecemeal, toothpaste-style feedback. This reduces back-and-forth rounds and avoids the oscillation of "fix one, spawn three." Supporting practices include: recording an issue fingerprint (issue type + location) for each review round to identify duplicates, and forcing a human consultation or redesign once a threshold is exceeded.
What Do Humans Still Do?
Code can be handed to AI, but responsibility cannot. Human work focuses on four things: setting direction, reviewing high-risk code, examining evidence, and taking responsibility. The complete implementation checklist is pinned at the top of the comments—developers using AI to write code may want to bookmark it first.
Related articles

Gemini 4 Carbon Tops Global Rankings as AI Productivity and Open-Source Ecosystems Surge
Google DeepMind's Gemini 4 Carbon tops global benchmarks, built for complex agents and system security. ByteDance launches Doubao Work integrated with Feishu, Anthropic's AI autonomously breaches 5 system-level attack chains, and ModelBest and Fudan open-source on-device multimodal and image generation models.

Overseas Creator Breaks Down N8n AI Agent Business Playbook: From Tooling to Monetization
An overseas creator breaks down the N8n AI agent business playbook: comparing Zapier, Make, and N8n, detailing four monetizable automation categories—lead capture, WhatsApp follow-up, booking, and content pipelines—plus agency pricing and a sales playbook.

Empacer: The Voice-First AI Assistant for Small Business Owners That Topped Product Hunt
Empacer is a voice-first AI assistant for small business owners: three-question setup, voice requests turned into customer replies, social posts, and invoices—all owner-approved. It won #1 Product of the Day on Product Hunt with 231 upvotes and 47 comments.