Why Does BatchNorm Work? The Core Mystery Still Unsolved a Decade Later
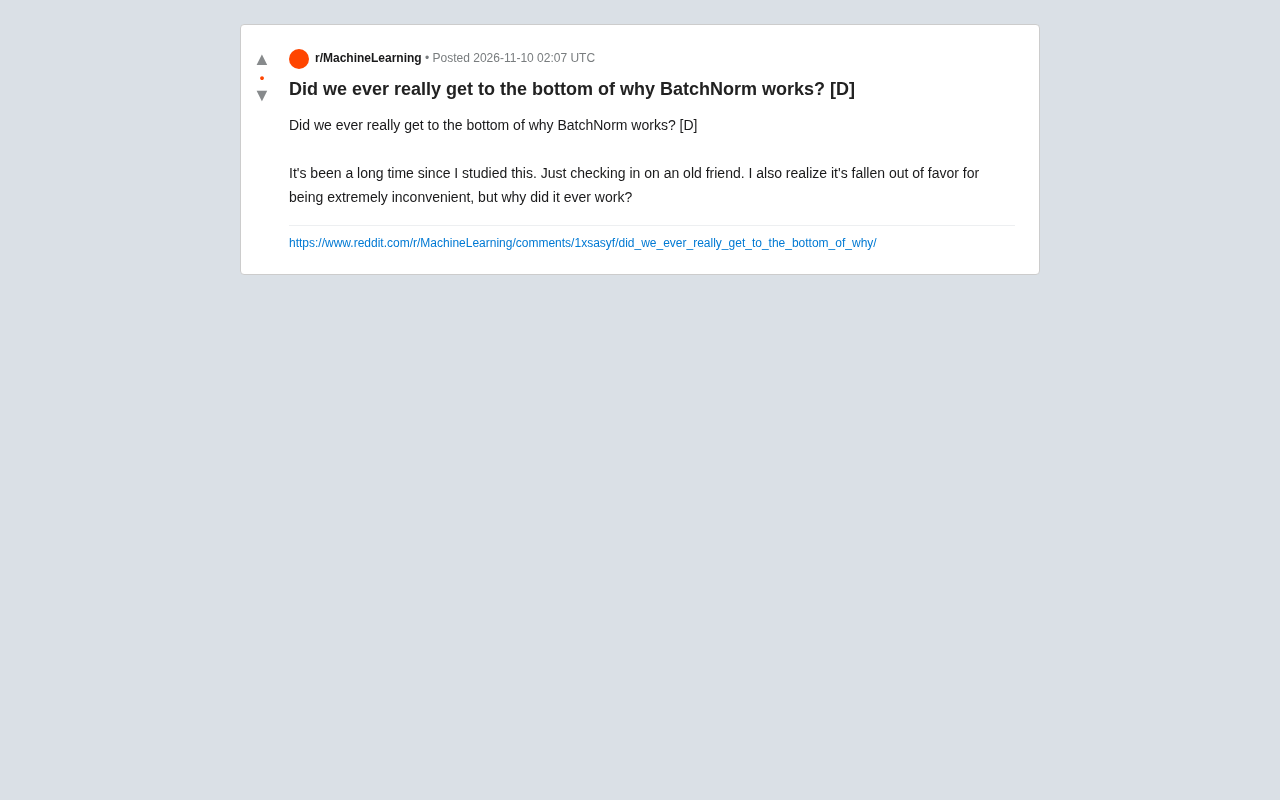
BatchNorm is widely proven effective, yet its fundamental mechanism has no consensus explanation and it is being replaced due to engineering inconvenience.
Starting from a Reddit discussion, the article explores the unsolved mystery of why BatchNorm works. Mainstream explanations include the internal covariate shift hypothesis, optimization landscape smoothing, and regularization effects, but none has been confirmed as the root cause—especially the covariate shift hypothesis, which has been questioned by subsequent research. Meanwhile, due to engineering defects such as training/inference inconsistency, failure with small batches, and conflicts with sequence models, BatchNorm is being systematically replaced in Transformer architectures by LayerNorm, RMSNorm, and others. The article notes that the theoretical gap has real costs: it is difficult to predict failure scenarios, and alternatives are mostly engineering-driven rather than theoretically derived. One view in the Reddit discussion suggests that BatchNorm may work through multiple pathways simultaneously, and that seeking a single root cause may itself be the wrong way to pose the question.
The Unsolved Mystery of an "Outdated" Technique
A Reddit user recently posted, reflecting that they hadn't studied BatchNorm in a long time but suddenly wanted to revisit this "old friend"—it has gradually fallen out of favor because it is extremely inconvenient to use, but why did it work in the first place? This question still has no universally convincing answer.
This post is not about the engineering implementation of BatchNorm, but points to a deeper theoretical gap: a technique that has been validated at scale by industry is still in a state of "partial explanation" regarding its underlying mechanism.
Mainstream Explanations and Their Cracks
The most widely circulated explanations in the literature for why BatchNorm works include:
- Internal Covariate Shift hypothesis: The idea that BatchNorm stabilizes the distribution of each layer's inputs, reducing distribution drift during training and thereby accelerating convergence.
- Smoothing the optimization landscape: Some studies point out that BatchNorm makes the loss surface smoother, allowing larger learning rates and improving training stability.
- Regularization effect: The batch statistics during training introduce noise, acting as a regularizer similar to Dropout.
The problem is that these explanations are not mutually exclusive, but none has been individually confirmed as the "root cause." The internal covariate shift hypothesis has been questioned repeatedly in subsequent research—experiments have shown that even when covariate shift is artificially induced, BatchNorm still brings benefits; conversely, suppressing the shift does not necessarily reproduce its acceleration effect. This suggests that the "standard answer" we are familiar with may only be correlation, not causal mechanism.
Internal Covariate Shift refers to the fact that during deep network training, parameter updates in earlier layers cause the input distribution of later layers to constantly change, forcing subsequent layers to continuously adapt to new distributions, thereby slowing down training. The original BatchNorm paper argued that normalizing each layer's inputs could alleviate this problem. But subsequent research (such as the 2018 work by Santurkar et al.) showed through experiments that even when covariate shift is artificially injected, BatchNorm still accelerates training; while suppressing the shift does not necessarily bring acceleration. This suggests that its benefits may come from improving the Lipschitz properties of the loss surface, rather than directly reducing distribution drift.
Why "Inconvenience" Actually Ended It
The "extremely inconvenient" mentioned in the post is the direct reason for BatchNorm's declining status in contemporary architectures. Specific manifestations include:
Inconsistency between training and inference. BatchNorm relies on the statistics of the current batch, causing model behavior to vary with batch composition; during inference, the statistics must be frozen, introducing a distribution discrepancy between training and inference.
Failure in small-batch scenarios. When the batch size is very small, batch statistics are too noisy and performance degrades significantly, which directly conflicts with distributed training and memory-constrained scenarios.
Friction with sequence models. In tasks such as variable-length sequences and autoregressive generation, the statistical assumptions along the batch dimension are not natural, and alternatives such as LayerNorm and RMSNorm have become the default choice in Transformer architectures.
These engineering defects compound, causing new-generation model architectures to systematically bypass BatchNorm, even though its theoretical mechanism remains unclear.
LayerNorm and RMSNorm are commonly used normalization alternatives in Transformers. LayerNorm computes the mean and variance across all feature dimensions of a single sample, does not depend on batch statistics, and therefore behaves consistently during training and inference, and naturally adapts to variable-length sequences. RMSNorm is further simplified, using only the root mean square for scaling, omitting mean centering, making computation more efficient and performing comparably in many large models. Both avoid BatchNorm's sensitivity to small batches and batch dependence, becoming the default choice in scenarios such as autoregressive generation.
What the Theoretical Gap Means
A technique has been widely used for years and then gradually replaced, yet its core mechanism remains unexplained—this is not uncommon in deep learning. The resonance triggered by the post lies precisely in this: we are accustomed to substituting "effective" for "understood."
This gap has real costs. If we don't know the true reason why BatchNorm works, it is difficult to judge in which new scenarios it will fail, and also difficult to design normalization schemes that are theoretically superior. The emergence of LayerNorm, GroupNorm, and RMSNorm is more of an engineering-driven substitution rather than the product of theoretical derivation.
Some views in the Reddit discussion also suggest that BatchNorm may work through multiple pathways simultaneously—improved optimization conditions, implicit regularization, gradient scale control—and that the dominant pathway differs across tasks. If this judgment holds, then seeking a single "root cause" is itself the wrong way to pose the question.
Conclusion
The story of BatchNorm shows that empirical success in deep learning often runs ahead of theoretical explanation. Whether it has truly "fallen out of favor" is not important; what matters is: when a technique is replaced, do we understand it better than when it was introduced? From the current discussion, the answer remains unclear.
Related articles
Anthropic Launches Dual Flagships Claude Fable 5.2 and Mythos 5.2, Topping Coding and Science Benchmarks
Anthropic releases Claude Fable 5.2 and Mythos 5.2 dual flagships, with full upgrades in coding, 3D interaction, and life sciences, topping third-party intelligence index, integrated by GitHub Copilot and Cursor, API pricing lower than competitors.
Claude Code Reportedly Leaks Secrets to GitHub, Sounding the Alarm for AI Coding Security
Claude Code reportedly exposed passwords and API keys to GitHub, per Ars Technica. We recap the incident alongside Claude Fable 5.2's 20% price cut and Meta Muse Ember, urging developers to check commit settings before granting permissions.
Getting Started with LangChain: Core Concepts of the Agent Development Framework
Starting from the three major limitations of LLMs, this article explains LangChain's positioning and value as an Agent development framework: limited knowledge, external system interaction, and state retention, along with its official documentation system and learning path.