You're Probably Still Underestimating How Fast AI Models Are Evolving

Most people's expectations for AI model capabilities are still not aggressive enough.
A viral tweet argues that most people are "not model pilled enough" — their expectations for AI model evolution still fall below the actual exponential growth curve. This article explores why human linear thinking consistently underestimates AI progress, what accelerating model capabilities mean for developers, investors, and everyday users, and where the rational boundaries of this exponential growth lie.
The Deeper Meaning Behind a Simple Reminder
Recently, a brief yet widely discussed tweet has been circulating in AI circles:
"Reminder: you are probably not model pilled enough. No matter how much you are betting on models right now, you are most likely still under the slope of the exponential."
The statement seems simple, but it precisely captures the prevailing mindset among tech practitioners, investors, and everyday users when facing the development of AI large models — we keep using linear thinking to measure something growing exponentially.
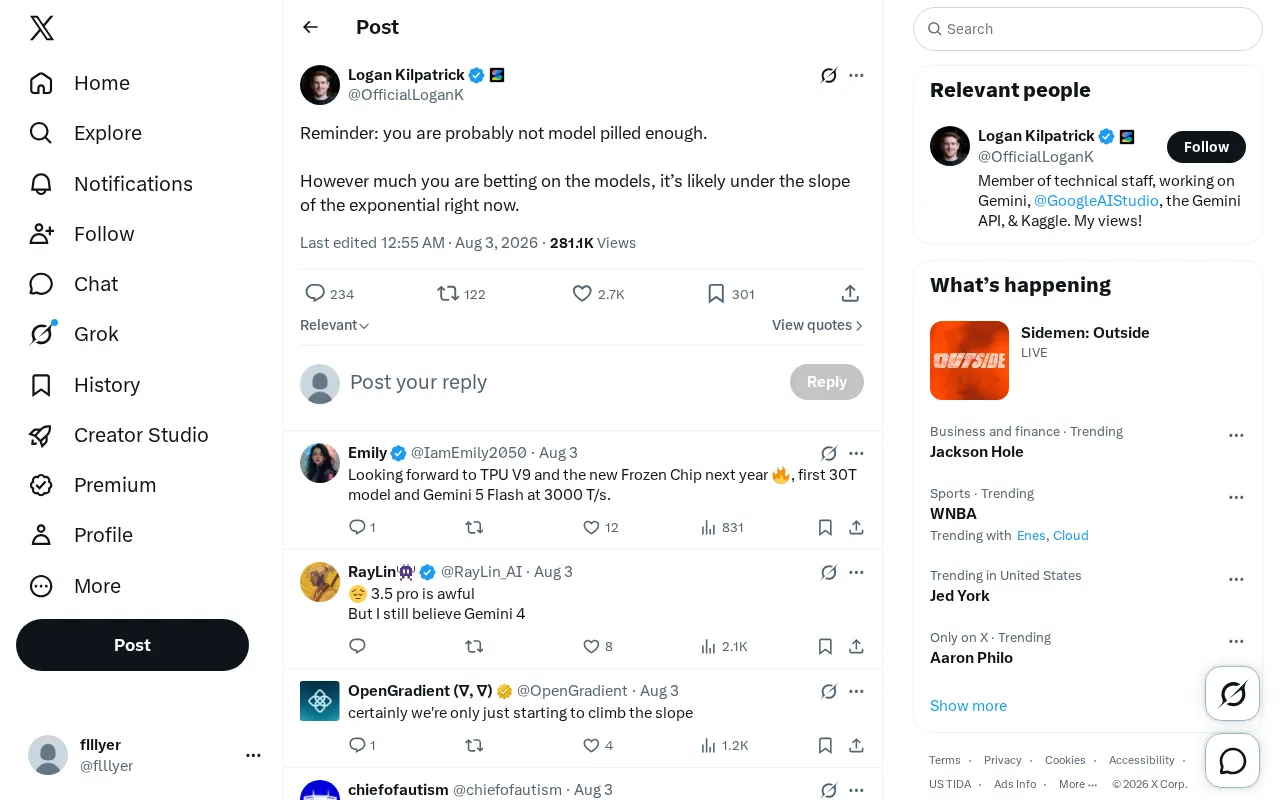
The term "model pilled" is internet slang in the English-speaking community, meaning someone who has been fully convinced of — or converted to believing in — the rapid evolution of AI model capabilities. The core argument of this tweet is: the vast majority of people's expectations for future model capabilities are still not aggressive enough.
Why We Consistently Underestimate the Exponential Growth of AI Models
The Linear Bias of Human Intuition
The human brain is naturally wired to handle linear relationships but is remarkably poor at intuitively grasping exponential growth. This cognitive bias is on full display when it comes to judging AI's trajectory.
When we witness the leap from GPT-3.5 to GPT-4, and then to the reasoning models now emerging from various labs (like the o1 and o3 series), many people's first reaction is, "This generation is already very powerful — how much better can the next one really be?" This is a textbook case of linear thinking. In reality, model capability improvements tend to follow a steep exponential curve: compute investment, data scale, and algorithmic improvements compound together to produce dramatic leaps in capability.
What "Under the Slope" Really Means
The phrase "under the slope of the exponential" in the tweet is particularly worth unpacking. It means: even if you're already an AI optimist, the future you envision probably still falls below the actual growth curve. In other words, the real pace of evolution will be faster than you imagine.
This claim has been validated repeatedly over the past few years. When ChatGPT launched, very few people predicted that within just two years, AI would achieve such remarkable breakthroughs in code generation, mathematical reasoning, and multimodal understanding. Nearly every declaration of "this is the ceiling" has been shattered within six to twelve months.
What Accelerating AI Model Evolution Means for Different Groups
For Developers and Founders
If you're building an AI-powered product, a common trap is designing around the current model's limitations — for example, piling on complex engineering logic to work around the model's reasoning shortcomings. But following the "model pilled" logic, these shortcomings are likely to be eliminated outright by the next generation of models.
This means: betting that models will get stronger is almost always a wiser strategy than betting they'll stay where they are. Products designed with the assumption that "models will be good enough" may reap unexpected rewards 12–18 months down the road.
For Investors
For capital markets, this reminder hints at an opportunity that may be systematically undervalued: AI capability evolution hasn't peaked yet, and the downstream ecosystem built around foundational model improvements still has enormous room to grow. Of course, caution is warranted — exponential-curve convictions can also generate bubbles through excessive optimism.
For Everyday Users
Even power users who interact with AI tools daily can easily fall into the cognitive trap of "what I experience today is the ceiling." Maintaining an open mind about the continuous expansion of capability boundaries is key to making the most of future tools.
Where Are the Rational Limits of Exponential Growth?
It's worth emphasizing that views like "you're not model pilled enough" carry a clear optimistic bias and are quite popular in Silicon Valley's accelerationist circles. Truly mature judgment requires balancing both sides:
- Exponential growth doesn't last forever: Every technology curve eventually hits the inflection point of an S-curve. Compute, energy, and data all face physical and economic constraints.
- Capability leaps don't automatically translate to value capture: There's still a gap between models getting stronger and achieving commercial viability and social acceptance.
- Risks grow exponentially too: The more powerful the models become, the greater the challenges around alignment, safety, and governance.
Therefore, this tweet should be understood more as a wake-up call against cognitive inertia than an unconditional declaration of optimism. It reminds us: when evaluating AI's future, don't drive by looking in the rearview mirror, and don't use today's ruler to measure tomorrow's world.
Conclusion
"You're probably not model pilled enough" — this statement resonates because it touches on a reality that has been validated time and again: in the field of AI, aggressive expectations tend to be closer to the truth than conservative ones.
Whether you're a developer, an investor, or a casual observer, it's worth asking yourself: is your vision of AI's future still stuck below the exponential curve? In an era where capability ceilings are shattered every few months, maintaining sufficient imagination is itself a competitive advantage.
Related articles

world2vec: Building Mechanistic World Models with Latent Dynamics Learning
world2vec proposes a reward-free method for learning mechanistic world models via latent dynamics, faithfully reproducing systems over long horizons with at least an order of magnitude fewer parameters than DreamerV3, TD-MPC2, and LeWM, and achieving accurate system identification on 71 attractor benchmarks.

A New KL-DRO Paradigm: Adaptive Scenario Generation Around a Learned Density Model
KL-DRO research proposes centering the KL ball on a learned density model instead of the empirical distribution, with adaptive scenario generation guiding sampling toward the worst case. Experiments show lower cost under distribution shift when records are scarce and the model can extrapolate, with comparable in-distribution cost.

ODE Samplers for Discrete Diffusion Models: Exponential Residual Flows Accelerate Generation
Discrete diffusion models lack deterministic ODE sampling? This article introduces Exponential Residual Flows (ERFs), which introduce continuous residual variables per token to construct piecewise ODEs for deterministic sampling and support consistency distillation acceleration. Superior to prior methods on code and text generation tasks.