#MLX
10 related articles

Ollama Releases v0.40.12-rc1, Adds LFM3 and d1 Model Support
Ollama releases v0.40.12-rc1 candidate, adding LFM3 and d1 models to the MLX backend. We examine what this means for local inference on Apple Silicon and what developers should watch.
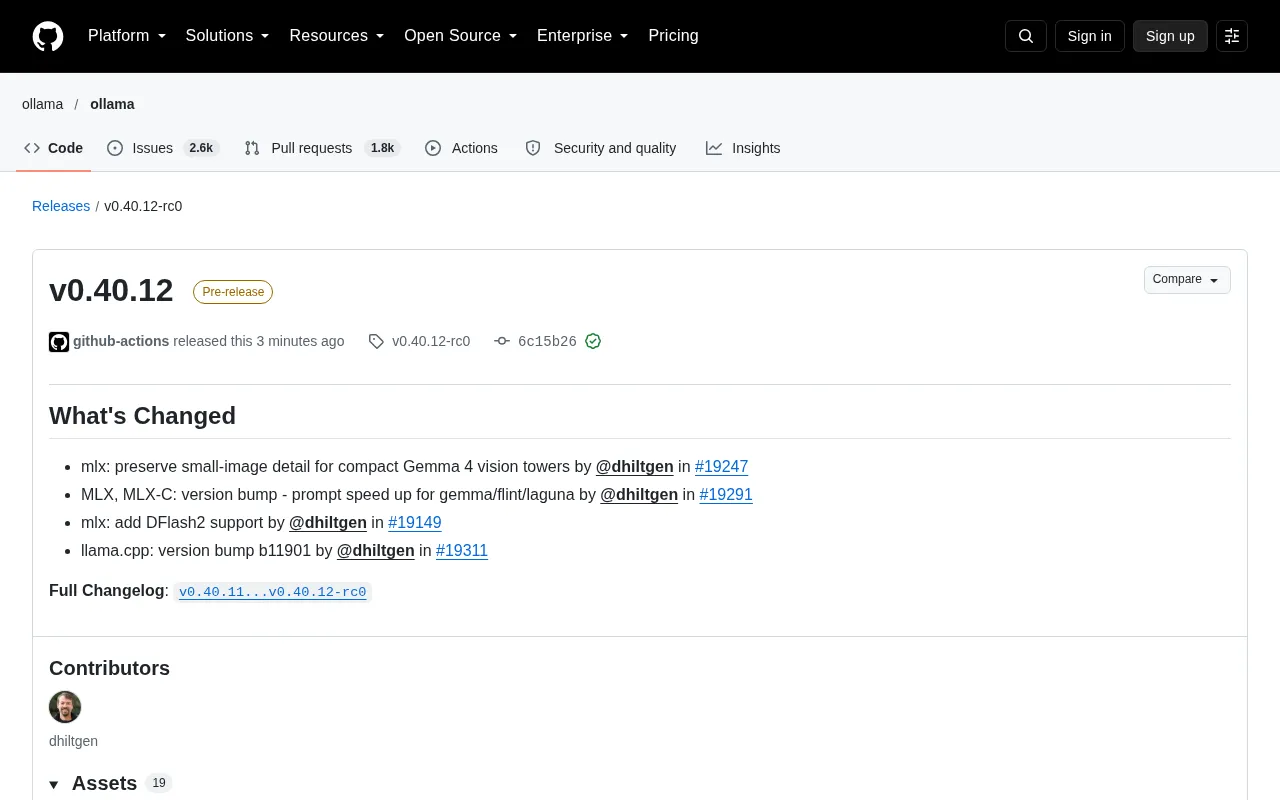
v0.40.12 Pre-release: MLX Inference Speedup and Gemma Vision Detail Optimization
v0.40.12 pre-release breakdown: MLX backend boosts prompt speed for gemma/flint/laguna, improves small-image detail in Gemma 4 compact vision tower, adds DFlash2, and syncs llama.cpp to b11901.
New MLX Release Adds Native Support fo…
New MLX Release Adds Native Support for Flint Model, Upgrading Inference Engine Capabilities
MLX v0.40.8-rc0 adds Flint model support with three changes: prompt JSON fidelity, ModelOpt expert bank assembly during safetensors import, optional learned sinks and device-side causal masks; existing APIs unchanged.

Ollama v0.40.7-rc1: MLX and GGML Share CUDA Runtime, Slimmer Package Size
Ollama v0.40.7-rc1 deduplicates the CUDA runtime shared by MLX and GGML, moving it into a sibling CUDA payload directory, retaining MLX private libs and JIT headers, packaging the full OpenBLAS Fortran runtime closure, and adding dependency checks at release to shrink the package and simplify dependency resolution.

Ollama v0.40.5-rc0 Released: MLX Version Bump
Ollama releases v0.40.5-rc0 candidate, a pure MLX backend version bump (commit #18993) with no new features or API changes. Apple Silicon Mac users should watch for the official release.

Ollama v0.40.4-rc0 Released: What the MLX Version Upgrade Means
Ollama releases pre-release v0.40.4-rc0, with the core change being an MLX and MLX-C version upgrade. This article analyzes the impact on Apple Silicon local inference performance and whether it's worth upgrading.
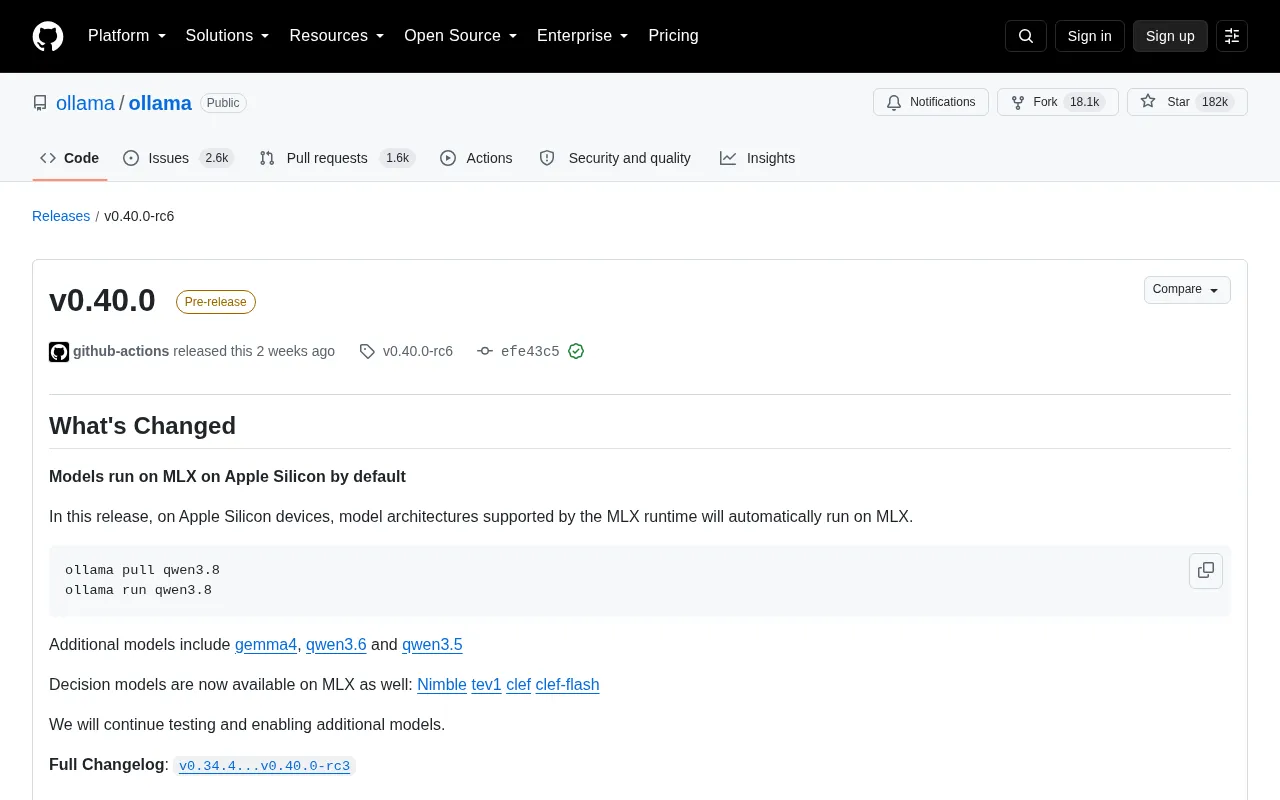
Ollama v0.40.0 Released: MLX Acceleration Enabled by Default on Apple Silicon
Ollama v0.40.0 enables MLX runtime by default on Apple Silicon, supporting qwen3, gemma4, and decision models for better local LLM inference performance on Mac.
Ollama v0.40.0-rc4 Released: Key Changes in the MLX Upgrade
Ollama v0.40.0-rc4 is out with a core MLX framework version bump for Apple Silicon and unit test memory optimizations. Here's what it means for developers.

Ollama v0.40.0-rc1 Released: MLX Tokenizer Aligned with Publisher Semantics
Ollama v0.40.0-rc1 aligns the MLX backend tokenizer with publisher semantics, covering BPE merges, Unicode boundaries, and pretokenization order for consistent Apple Silicon inference.
Ollama v0.35.0-rc1 Released: MLX Pull Retry Optimization
Ollama v0.35.0-rc1 is out, featuring improved MLX backend pull retry logic with bounded retries and a watchdog mechanism to prevent stalled model downloads on Apple Silicon.