#Triton
2 related articles

·2 min
Developer Builds Custom PyTorch Optimizer ApexW: Half the Memory, 1.5x Faster
Developer releases PyTorch optimizer ApexW with compact optimizer state and Triton execution path, about 1.5x faster than fused AdamW and roughly half the state memory in optimizer-only benchmarks, but small tensors and automatic mode still have clear weaknesses; the author openly seeks benchmark and implementation feedback.
Read more →
·3 min
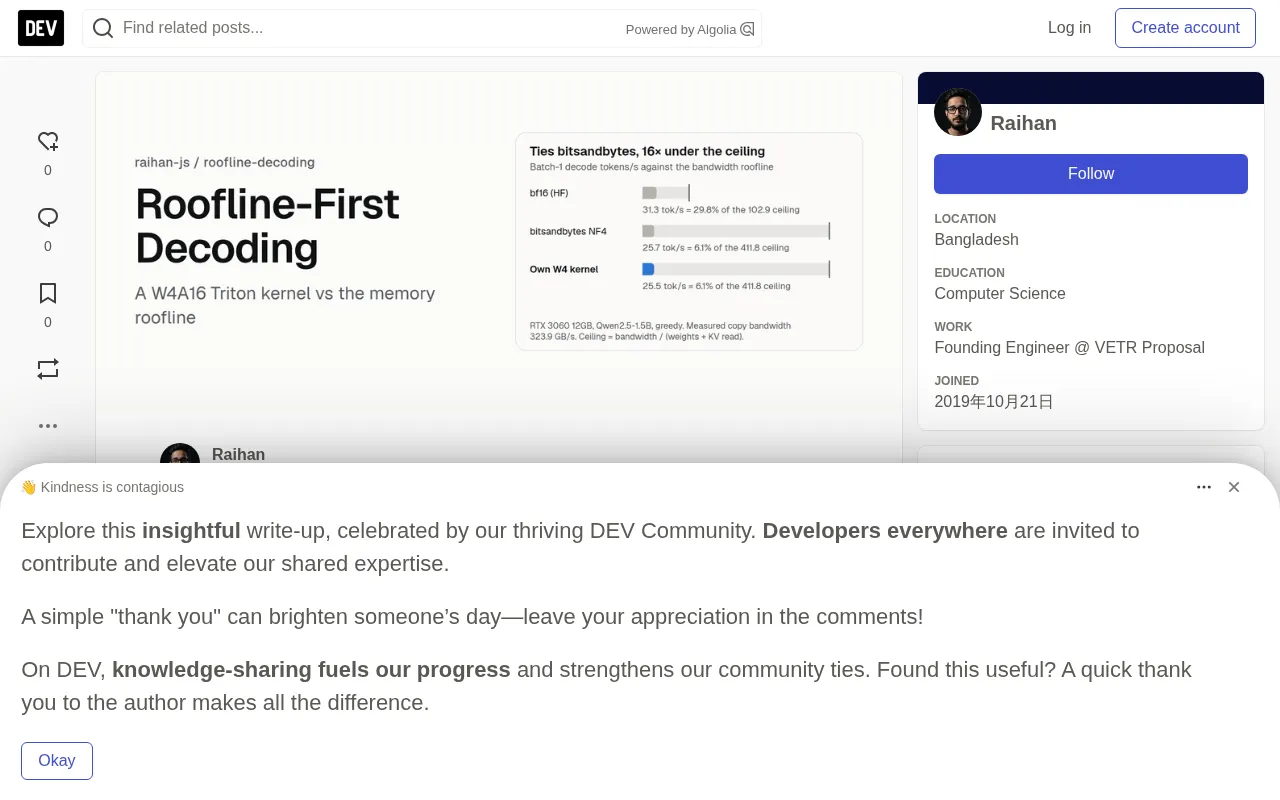
Triton Kernel Matches bitsandbytes: Why Both Lose to Math
A developer hand-writes a Triton W4A16 fused GEMV kernel on RTX 3060, matching bitsandbytes NF4 speed, but both lose to the bf16 baseline. This article analyzes roofline analysis, kernel optimization pitfalls, and the real performance bottleneck of quantized decoding.
Read more →