Accelerated Deployment of FLUX 3 Klein on NVIDIA Blackwell

FLUX 3 Klein paired with Blackwell accelerates diffusion model inference and reduces latency for interactive image generation.
The article focuses on deploying FLUX 3 Image Klein on NVIDIA Blackwell GPUs, noting that the multi-step denoising paradigm of diffusion models makes inference latency a core bottleneck for interactive image products. Blackwell's high memory bandwidth and low-precision compute (FP8/FP4) complement Klein's lightweight positioning to jointly compress end-to-end latency. It outlines three general acceleration paths: reducing sampling steps (few-step samplers and distillation), lowering numerical precision, and compilation and graph optimization. It also emphasizes that acceleration is not free and requires a three-way trade-off among latency, image quality, and memory, with different quality tiers set according to business scenarios and a fallback mode retained for high-quality final production stages.
Accelerated Deployment of FLUX 3 Klein on NVIDIA Blackwell
When you try to fit a diffusion model into design tools, image editors, and visual production pipelines, the first obstacle developers hit isn't whether the model looks good — it's whether the inference latency is tolerable. Waiting a dozen or more seconds to generate an image is essentially unusable in an interactive product. A recent technical article on the NVIDIA developer blog specifically discusses acceleration approaches for FLUX 3 Image Klein on NVIDIA Blackwell GPUs. This article combines that piece with community practices to provide an overview.
Why Diffusion Model Inference Latency Is the Key Bottleneck
The reason diffusion models are slow lies in their computational paradigm: a single generation requires multiple denoising iterations, and each step runs a full neural network forward pass. The more steps and the higher the resolution, the more latency grows linearly. For offline batch generation tasks, this may be acceptable; but once it enters the interactive loop of a design tool — where users drag sliders to adjust prompts and preview results in real time — latency directly determines product usability.
The NVIDIA article states this contradiction right at the outset: developers must incorporate inference latency into architecture design when deploying diffusion models, rather than optimizing after the fact. This also explains why engineering discussions around the FLUX series models have increasingly focused on inference acceleration rather than the models themselves in recent times.
The denoising process of diffusion models is essentially learning a reverse Markov chain: starting from pure Gaussian noise, it progressively predicts and removes the noise at each step until a clear image is obtained. Each denoising round is a complete U-Net or Transformer forward pass, in which the computational cost of the self-attention mechanism grows quadratically with image resolution. Therefore, when resolution doubles, single-step inference time may increase several-fold, and after stacking multiple iterations, end-to-end latency quickly exceeds the tolerance threshold of interactive scenarios. This is also why the industry focuses inference optimization on attention operators and low-precision computation.
What the Blackwell Architecture Brings to Image Generation
Blackwell is NVIDIA's new-generation GPU architecture designed for generative AI workloads, and its core improvement directions align closely with the inference characteristics of diffusion models: higher memory bandwidth, stronger low-precision compute, and hardware-level optimization for attention mechanisms. For image generation, this means the same denoising step can be completed in less time.
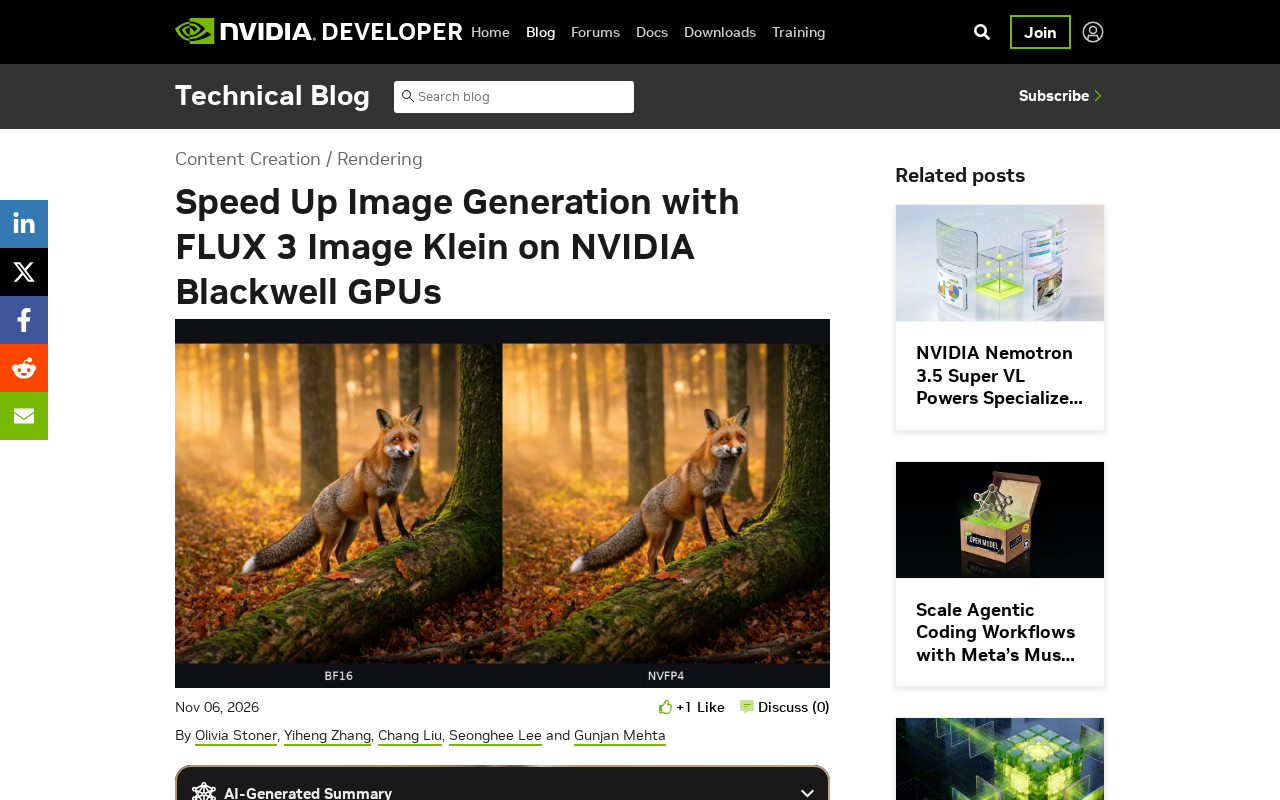
FLUX 3 Image Klein, as the version in the FLUX series geared toward lightweight deployment, pairs with Blackwell in a clear logic: the model side controls parameter count and computational load, while the hardware side provides high-throughput low-precision inference capability, and the two together compress end-to-end latency. The example image provided by NVIDIA in the article — a red fox beside a moss-covered fallen log in an autumn forest — is precisely a demonstration of the output from this combination.
Note: The original material only covers the beginning of the article and one example image; the specific acceleration technical details, performance data, and configuration steps could not be obtained in full. The following sections are based on general public practices for diffusion model acceleration, to help readers build background knowledge.
Blackwell's fifth-generation Tensor Cores natively support finer-grained low-precision formats such as FP4 and FP6, and together with the second-generation Transformer Engine, are specially optimized for matrix multiplication and Softmax in attention computation. In addition, its HBM3e memory provides higher bandwidth, significantly reducing the overhead of moving large-sized latents and weights between memory and compute units. For workloads like diffusion models that are memory-bandwidth sensitive and have regular computation patterns, these improvements translate directly into lower single-step denoising latency.
Three General Paths for Diffusion Model Inference Acceleration
Reducing Sampling Steps
The most direct approach is to switch to more efficient samplers and reduce the number of denoising steps while ensuring image quality. Few-step samplers combined with distillation-type methods can compress a generation process that originally took dozens of steps down to single digits.
Representative few-step samplers include DDIM, DPM-Solver, and their variants, which use higher-order numerical integration methods to approximate the original sampling trajectory with fewer steps. Distillation-type methods (such as consistency models and adversarial distillation) train a student model to directly learn a compressed multi-step mapping from noise to image, reducing generation steps to 1-4. The two can be used together, but distillation often requires additional training resources and involves substantial changes to model structure, so compatibility with existing weights must be evaluated during deployment.
Reducing Numerical Precision
Low-precision formats such as FP8 and FP4 are more fully supported on Blackwell. When weights and activations are represented in low precision, memory usage and computation time decrease simultaneously, which is especially effective for memory-sensitive deployment scenarios.
FP8 is currently a relatively mature low-precision solution for inference acceleration; its dynamic range is sufficient to cover the distribution of diffusion model weights and activations, while roughly doubling memory efficiency and matrix multiplication throughput. FP4 further compresses bit width, but requires block-wise quantization and scaling factors to suppress precision loss, placing higher demands on the quantization calibration process. In actual deployment, lower precision is usually used for weights while slightly higher precision is retained for activations, to strike a balance between image quality and speed.
Compilation and Graph Optimization
Handing the model computation graph to an inference compiler for operator fusion and memory reuse can further squeeze out framework-level overhead. This part of the optimization is strongly hardware-dependent, and it is precisely the kind of content that GPU vendors' official blogs typically elaborate on.
Several Issues to Watch Out for During Deployment
Acceleration is not free. If steps are compressed too aggressively, detail textures and complex compositions tend to break down; if precision is lowered too much, color shifts and artifacts appear. In actual deployment, it is usually necessary to make a three-way trade-off among latency, image quality, and memory, setting thresholds according to business scenarios rather than blindly pursuing maximum speed.
In addition, the positioning of FLUX 3 Image Klein determines that it is better suited to scenarios that are cost-sensitive and relatively less demanding on ultimate image quality — such as real-time previews in design tools and batch first drafts of e-commerce assets. For stages that pursue final production quality, it is still recommended to retain a high-quality mode as a fallback.
Conclusion
The signal from this NVIDIA technical article is clear: competition in image generation models is shifting from model capability to deployment efficiency. The combination of FLUX 3 Image Klein and Blackwell is a concrete example on this path. For developers, understanding where latency comes from and what each acceleration method costs is more valuable in the long run than memorizing a specific configuration.
Related articles
 Tech Frontiers
GitHub Daily · November 8: Agent Infrastructure Blooms Across the Board
GitHub Daily Nov 8: agent infrastructure dominates Trending—browser automation, design systems, skill libraries, VM runtimes, and context compression—while veteran tools warm up.
 Tech Frontiers
Comparing Routing Mechanisms of 10 Open-Source MoE Models: DeepSeek, Qwen, Mixtral, Llama 4, gpt-oss
A configuration-based comparison of routing mechanisms in 10 open-source MoE models, analyzing DeepSeek, Qwen, Mixtral, Llama 4, and gpt-oss on expert count, top-k, shared experts, gating, and load balancing.
 Tech Frontiers
Vibe Coding Step-by-Step Guide: Learn to Build Products with AI in Six Steps
Breaking down the six-step methodology of Bilibili's 748-episode Vibe Coding course, analyzing the usage boundaries and prompt techniques of Codex, Claude Code, and Cursor, and discussing who this AI coding course suits, who it doesn't, and how to avoid the trap of watching without acting.