Anthropic Financials Leaked: Revenue Far Exceeds Compute Costs, Claude Inference Gross Margin Hits 68%

Leaked data shows Anthropic's inference gross margin at 68%, with AI company losses concentrated in training rather than inference.
According to leaked Anthropic internal Q3 financial data, its revenue is roughly twice its total compute costs, and Claude's inference business gross margin reaches 68%, directly challenging the industry stereotype that "AI companies lose money on every query." The article points out that inference and training are two completely different sets of accounts: inference has achieved a positive unit economics model, while frontier training burns $2.8 billion per quarter and generates no direct revenue. This discovery is prompting capital markets to separately examine inference-side cash flow and training-side capex. However, the data is unaudited and requires cautious interpretation.
A Number That Breaks the Industry Stereotype
For a long time, there has been an almost default assumption about AI model companies: they lose money on every query they process. According to leaked financial data cited by a YouTube tech channel, Anthropic's internal Q3 figures show that its revenue is roughly twice its total compute costs, and Claude's inference business has already achieved a 68% gross margin. This number is prompting Wall Street bankers to re-examine the business models of AI companies.
The claim that "every query loses money" does not hold up on Anthropic's books. This is not to say AI companies don't burn cash—rather, it matters where the money is being burned: inference and training are two completely different sets of accounts.
Inference vs. Training: Two Accounts, Two Logics
The Inference Business Has Already Achieved Positive Gross Margin
The most critical takeaway from the leaked data is that Claude Inference reaches a 68% gross margin at its corresponding revenue scale. This means the user-facing inference service itself is already a gross-margin-positive business, rather than a traffic funnel sustained by subsidies.
The analyst in the video directly addressed this widespread skepticism: "There have been many voices asserting that Anthropic and OpenAI lose money on every query—that is not the case." His evidence is the comparison between revenue and compute costs—revenue is roughly twice total compute costs.
Gross margin is the profit percentage remaining after deducting direct costs (COGS) from operating revenue, reflecting a business's profitability efficiency before covering fixed expenses. For AI inference businesses, direct costs are primarily GPU compute, electricity, network bandwidth, and cloud service expenses; a positive gross margin means that for each additional user served, the revenue increment exceeds the compute increment—the business has the economic foundation for self-expansion. A 68% gross margin is not high compared to hardware vendors like Nvidia, but it is considerable in inference services that continuously consume compute, indicating that unit cost reductions from scaled deployment and inference optimizations (such as batching, KV caching, and quantization) are materializing.
Frontier Training Remains a Cash Furnace
On the other side, Frontier Training burns $2.8 billion per quarter. Training costs do not generate direct revenue, but they are a necessary investment to maintain the model's generational competitiveness. Spreading training expenses across the inference business naturally puts pressure on the overall books, but using inference gross margin to negate the entire business model is conflating two separate accounts.
Frontier Training refers to the large-scale pre-training and post-training investments made to train models at the frontier of capability, typically characterized by 10,000-GPU-scale clusters running at full capacity for weeks or even months. Such expenditures are usually capitalized and amortized over years in accounting rather than being charged as a one-time expense in the current period, so "burning $2.8 billion per quarter" may reflect either cash outflow or depreciation and amortization—two very different impacts on the income statement. Training investment does not directly correspond to revenue; its return is reflected in the performance leap of the next-generation model and pricing power, making it a typical strategic capital expenditure.
What a 68% Gross Margin Means
A 68% gross margin is mid-to-upper tier in the traditional SaaS industry, but quite rare in the asset-heavy, compute-intensive AI infrastructure sector. It demonstrates two things: first, the unit economics of model inference have improved with scaled deployment and inference optimization; second, pricing power still exists—users are willing to pay for Claude's output.
For the industry, this provides a reference sample: the losses of large model companies are not evenly distributed across all business lines, and the inference layer may be closer to health than outsiders imagine. The real money pit is concentrated in the arms race of frontier training.
Impact on AI Company Valuation Narratives
The "second look" triggered by the leaked data is essentially an adjustment of valuation logic. If the inference business can generate its own cash flow, then the market's pricing of AI companies should not focus solely on total net losses, but should separately examine cash flow on the inference side and capital expenditure on the training side. The video's mention of an "$800 billion AI IPO" scale also indicates that capital markets are re-evaluating such companies with a more granular financial perspective.
The analyst emphasized at the end that this kind of competition "is not about destroying anyone" but is "a very positive thing." From a financial structure perspective, this judgment has its basis: when leading companies' inference businesses begin to generate positive gross margins, the entire industry's commercialization narrative shifts from "when will we make money" to "how much generational leadership can training investment buy."
Caution Is Warranted
These numbers come from leaked materials, are unaudited, and lack complete disclosure of cost definitions—whether compute costs include depreciation and how the denominator of inference gross margin is defined can significantly affect the conclusions. Treating a single quarter's gross margin as a long-term trend is also risky; model price wars and changes in inference demand structure could both compress this space. For readers following AI commercialization, this data is better treated as an observation window than a definitive conclusion.
Background Context
The "$800 billion AI IPO" reference points to market expectations for the valuation magnitude of leading AI company IPOs. Such high valuations require both rapid revenue growth and margin improvement, which is why investors are beginning to use sum-of-the-parts valuation—discounting inference business cash flows and pricing training investment as option value separately—rather than simply multiplying total net losses by a multiple. This also explains why a single piece of unaudited leaked gross margin data could trigger Wall Street's "second look"—it changes the assumptions about inference-side cash flow in valuation models.
One-line Summary
Leaked data shows Anthropic's inference gross margin at 68%, with AI company losses concentrated in training rather than inference.
Paragraph Summary
According to leaked Anthropic internal Q3 financial data, its revenue is roughly twice its total compute costs, and Claude's inference business gross margin reaches 68%, directly challenging the industry stereotype that "AI companies lose money on every query." The article points out that inference and training are two completely different sets of accounts: the inference service has already achieved a positive unit economics model, while frontier training burns $2.8 billion per quarter and generates no direct revenue, making it the main cause of overall book pressure. This finding is prompting capital markets to separately examine inference-side cash flow and training-side capital expenditure, adjusting the valuation narrative for AI companies. However, the data is unaudited, and the cost definitions and sustainability of a single quarter's gross margin still require cautious treatment.
Related articles

Using and Topping Up Claude in China: Three Methods Compared and a Guide to Avoiding Account Bans
A guide to using and topping up Claude in China: compare direct overseas credit card payment, US Apple ID and Android Google Play in-app purchases, and self-service website top-up by barriers, cost, and suspension risk, plus five habits to reduce the chance of a ban.

From ChatGPT Content Restrictions to Eval, Observability, and Guardrail in Practice
Through a hands-on e-commerce order Agent, this article explains the engineering logic behind ChatGPT content restrictions and how Eval, Observability, and Guardrail work together to prevent same-name user data leaks and prompt injection risks.
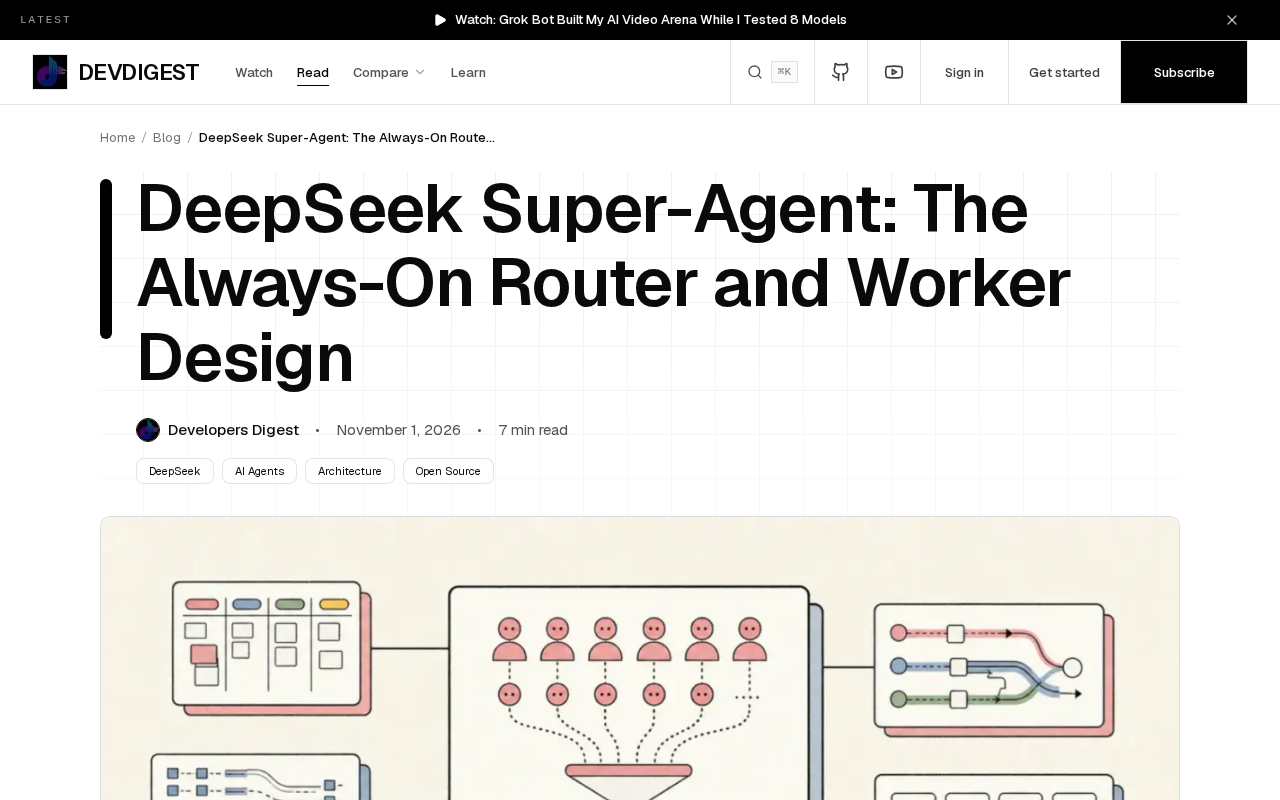
DeepSeek Open-Sources Super-Agent: An Architecture Deep Dive into the Router and Worker Design of an Always-On Coding Assistant
DeepSeek open-sources the always-on coding agent dsh-superagent, using a separated Router-Worker architecture that balances continuous operation and permission control. This article analyzes its design approach, what the code actually delivers, and the safety debate surrounding autonomous coding assistants, helping developers decide whether it is worth learning from.