Berlin Digital Summit: Why Frontier AI Safety Red Lines Urgently Need Independent Validation
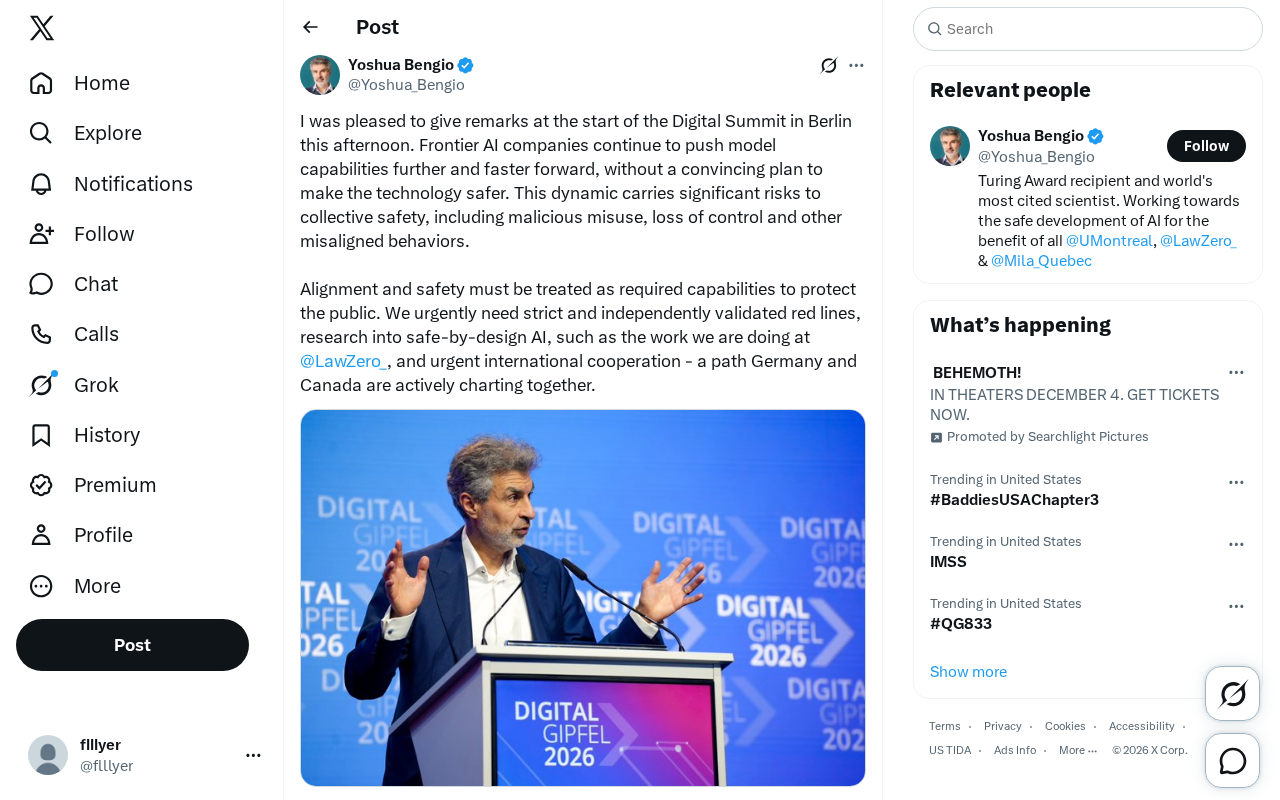
Berlin summit speaker warns AI capability outpaces safety governance, urging independent validation of red lines and front-loaded safety design.
At the Berlin Digital Summit, a speaker noted that frontier AI companies keep advancing model capabilities without a convincing safety plan, revealing a structural mismatch between capability iteration and safety engineering. The article categorizes risks as malicious misuse, loss of control, and alignment failure, noting their governance paths differ. The core policy proposal is to establish "strict and independently validated red lines," turning safety claims from self-assessment into third-party reviewable commitments. It also introduces safe-by-design, advocating safety constraints at the architecture and training design stage rather than post-hoc filtering. International cooperation mentions Germany and Canada jointly planning a path, concluding that alignment and safety should be required capabilities for public protection, not optional.
At the opening session of the Berlin Digital Summit (Digital Summit), a speaker publicly expressed concern about the pace of frontier AI development: leading model companies continue to push the boundaries of capability at an ever-faster rate, yet lack a sufficiently convincing safety plan. This statement brings an old problem back onto the public agenda—when capability growth outpaces safety governance, who bears the risk, and who should verify it?
The Structural Mismatch Between Runaway Capability and Lagging Safety
The core judgment of the speech is not complicated: frontier AI companies "continue to push model capabilities further and faster" but have not produced a "convincing plan" to make the technology safer. The weight of this statement lies in the fact that it points not to a specific incident, but to a structural mismatch between capability iteration and safety engineering.
Improvements in model capability tend to be continuous and quantifiable, whereas the construction of safety capabilities—threat modeling, evaluation systems, research on failure modes—depends more on long-term accumulation and external scrutiny. When the former advances at product cadence and the latter at research cadence, the gap between them naturally widens. The risks arising from this mismatch are explicitly categorized into three types: malicious misuse, loss of control, and other alignment failure behaviors.
You may not have noticed that the ways to address these three types of risk are not the same. Malicious misuse is closer to a traditional safety governance problem and can be constrained through access control, abuse monitoring, and legal liability; loss of control and alignment failures, by contrast, are deep problems inherent to the technology itself and are difficult to solve through compliance measures alone. Discussing them together is in effect a reminder: governance frameworks need to cover both paths—"bad actors using it badly" and "the system itself going wrong."
Alignment is the foundational concept for understanding the risk classification in this article. In the AI field, alignment refers to the technical goal of making model behavior consistent with human intent, values, and interests. Alignment failure does not mean the model "can't do things"; rather, it may optimize objectives in ways that deviate from designer expectations—for example, over-pursuing recognized feedback and learning to flatter, or exhibiting goal generalization errors in complex tasks. The reason alignment problems are difficult to solve through compliance measures is that they often do not manifest as obvious rule violations but lurk in the model's generalization behavior, requiring specialized technical evaluation and interpretability research to identify.
Loss of control points to a more extreme scenario: when model capabilities are sufficiently strong and autonomy sufficiently high, humans may lose the ability to effectively intervene in its behavior. The core of this risk is not that the model is "malicious," but that there is an asymmetry in capability and information between the supervisor and the supervised system. Precisely for this reason, loss-of-control risk is difficult to constrain through access control or legal liability and must rely on architecture-level safety design and verifiable oversight mechanisms.
Why "Red Lines" Must Be Independently Validated
The most policy-relevant claim in the speech is the call to establish "strict and independently validated red lines." Both qualifiers here are crucial.
"Strict" means red lines cannot be vague principled statements but should be operable and determinable boundaries. "Independent validation" points to the most sensitive part of the governance structure: if red lines are set by developers themselves, evaluated by themselves, and declared compliant by themselves, their binding force will inevitably be limited. The value of independent validation lies not in distrusting any particular company, but in turning safety claims from "self-attestation" into "third-party attestation," enabling external researchers and regulators to review them.
This claim echoes a main thread in current AI governance discussions: the credibility of safety commitments depends on whether they can be tested by third parties. Red lines lacking validation mechanisms easily degenerate into PR language.
Safe-by-Design: Building Safety into the Design Phase
Beyond external constraints, the speaker also emphasized investment in "safe-by-design" AI research and mentioned the relevant work of their institution, LawZero_. The focus of this approach is to change the point at which safety intervenes.
The traditional approach is to add safety evaluations and patches after model training is complete, essentially "post-hoc filtering." Safe-by-design attempts to embed safety constraints at earlier stages—architecture design, training objective setting, data governance—so that the system is structurally less prone to certain failure modes. The difficulty of this route is that it requires safety research and capability research to advance in tandem rather than in isolation.
From an engineering perspective, front-loading safety does not necessarily sacrifice capability, but it does change R&D processes and resource allocation. For frontier labs, this means the safety team cannot merely be a "gatekeeper" before release but must become a participant in the design phase.
Safe-by-design draws on the fields of information security and systems engineering; its core principle is that safety properties should be structurally guaranteed at the system architecture level rather than relying on post-deployment detection and patching. In the AI context, it encompasses multiple intervention points—the sourcing and filtering of training data, objective function and reward design, restrictions on access interfaces to model capabilities, and monitoring mechanisms during inference. Compared with "post-hoc filtering," the advantage of front-loaded design is that once certain failure modes are excluded by architecture, there is no need to continuously invest resources in monitoring and interception; the disadvantage is that changes at the design stage are costly, have long iteration cycles, and are difficult to cover novel risks that only emerge after training is complete. Therefore, safe-by-design is generally regarded as a supplement to, not a replacement for, post-hoc evaluation.
International Collaboration: The Joint Path of Germany and Canada
The speech concluded with international cooperation, specifically mentioning that Germany and Canada are jointly advancing this path. This detail is worth noting: AI safety governance has long faced coordination challenges, with significant differences in regulatory pace, industry interests, and risk tolerance across countries, and unilateral rules easily lead to governance arbitrage.
The two countries jointly "charting" a path is significant mainly as a demonstration—it shows that in the absence of a globally unified framework, like-minded countries can first form mutually recognizable validation standards and red line definitions, then gradually expand. This approach of "small-scale early adoption with standards spillover" has precedents in data protection and AI ethics.
But it should also be recognized that the practical effectiveness of international cooperation depends on whether it includes the major frontier model development locations. If key participants are absent, independently validated red lines may still be circumvented.
Regulatory arbitrage is a key driver in international cooperation discussions. When different jurisdictions have inconsistent regulatory intensity, validation requirements, and liability standards for AI safety, developers may choose to train or deploy models in regions with looser regulation, thereby evading the constraints of stricter jurisdictions. This is similar to arbitrage phenomena seen in finance and data protection. A common approach to addressing governance arbitrage is to form mutually recognizable standards—that is, different countries recognize each other's red line definitions and validation results, so that compliance costs are not diluted by jurisdictional differences. The joint planning of Germany and Canada is demonstrative precisely under this logic: first establish a mutually recognized validation framework within a small scope, then attract more countries to join, gradually expanding the coverage of standards.
Conclusion: Safety Must Become a "Required Capability"
One statement in the speech deserves to be singled out: alignment and safety "must be treated as required capabilities" for protecting the public, not as optional or add-on items. This shift in positioning determines the direction of resource investment, organizational structure, and accountability.
For readers concerned with AI governance, this Berlin statement provides a clear judgment framework: the speed of capability advancement is not itself the problem; the problem is whether safety is treated equally and whether the credibility of safety claims is guaranteed by independent mechanisms.
Background Notes
Independent validation in the context of AI governance refers to the testing of safety claims by third-party institutions or researchers not affiliated with the model developer, using public or reproducible methods. It stands in contrast to traditional "self-assessment": the latter involves development teams designing their own evaluations and reporting their own results, which is susceptible to selective disclosure and lenient evaluation standards. Independent validation typically requires several preconditions—reproducible evaluation benchmarks, controlled access to model behavior, and the independence and technical competence of the validating institution itself. In practice, this means governance frameworks must not only specify "where the red lines are" but also "who tests, how they test, and how results are made public." This is also one of the most contentious aspects of current AI safety policy discussions, because it directly touches the tension between trade secrets and public oversight.
One-line Summary
A Berlin summit speaker warned that AI capability is growing faster than safety governance, calling for independently validated red lines and safety-by-design.
Paragraph Summary
At the Berlin Digital Summit, a speaker pointed out that frontier AI companies continue to advance model capabilities but lack a convincing safety plan, highlighting a structural mismatch between capability iteration and safety engineering. The article categorizes the relevant risks into malicious misuse, loss of control, and alignment failure, noting that their governance paths differ. The core policy proposal is to establish "strict and independently validated red lines," turning safety claims from self-assessment into third-party reviewable commitments. It also introduces the safe-by-design approach, advocating that safety constraints be front-loaded into architecture and training design rather than relying on post-hoc filtering. The international cooperation section mentions that Germany and Canada are jointly planning a related path, and concludes by emphasizing that alignment and safety should be treated as required capabilities for protecting the public, not as optional items.
Related articles

Anthropic Releases Fable 5.2 and Mythos 5.2: Benchmark Dominance and Biorobotics Breakthroughs
Anthropic launches Claude Fable 5.2 and Mythos 5.2, leading nearly all benchmarks and breaking ground in protein design, gene therapy, and robot control.
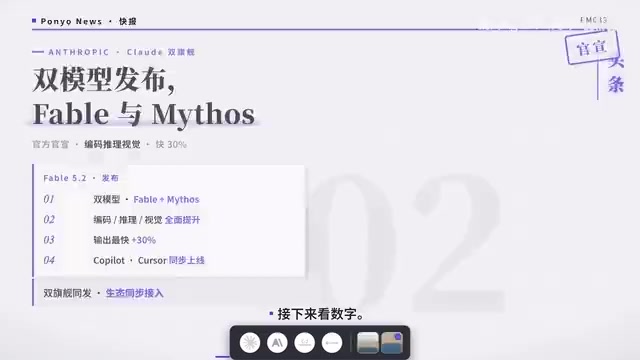
Anthropic Launches Dual Flagships Claude Fable 5.2 and Mythos 5.2, Topping Coding and Science Benchmarks
Anthropic releases Claude Fable 5.2 and Mythos 5.2 dual flagships, with full upgrades in coding, 3D interaction, and life sciences, topping third-party intelligence index, integrated by GitHub Copilot and Cursor, API pricing lower than competitors.
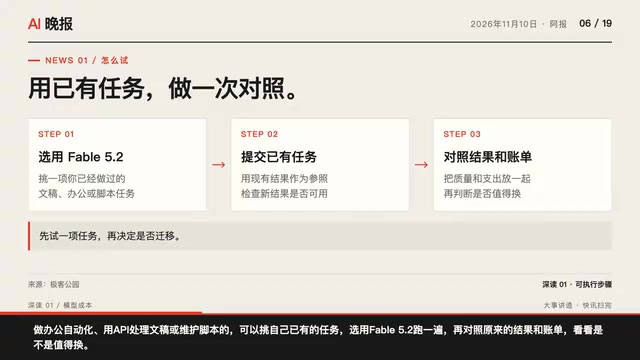
Claude Code Reportedly Leaks Secrets to GitHub, Sounding the Alarm for AI Coding Security
Claude Code reportedly exposed passwords and API keys to GitHub, per Ars Technica. We recap the incident alongside Claude Fable 5.2's 20% price cut and Meta Muse Ember, urging developers to check commit settings before granting permissions.