DeepSeek's Open-Source Agent Teardown: 11,700 Stars but Only One Commit

DeepSeek's open-source agent dsh-superagent follows a minimal-disruption principle, turning repository collaboration into auditable work orders via a seven-concept chain and three-layer authorization.
DeepSeek's open-source dsh-superagent is a proactive agent stationed in a repository, turning permitted team requests into work orders executed in isolated sessions and worktrees, with results written back to the original conversation, and it can also connect to Feishu. It follows a counterintuitive principle of minimizing attention occupation, stopping based on impact scope rather than workload. The chain is built on seven concepts (source, trigger, thread, evaluation, borrowing, authorization, dispatch), with three-layer authorization and observation mode as default. Engineering emphasizes a single writer, transactional commands, and recoverable dispatch, but OS-level isolation is weak, the database only grows, and it only supports public platforms—making it suitable for studying the design and experimentation, not for directly hosting production repositories.
DeepSeek's Open-Source Agent Teardown: 11,700 Stars but Only One Commit
A project has racked up 11,700 stars on a code hosting platform, yet has only one commit—and that commit was a one-shot public release of internally organized code. This is DeepSeekAd's open-source proactive agent, dsh-superagent. According to a teardown video by a Bilibili creator, its goal is not to be a chatbot or a code completion tool, but to let the agent "go to work on its own": long-term stationed in a repository, listening to people, turning permitted requests into work orders, and sending results back to the original conversation after execution.
What It Actually Does: A "Colleague" in the Repository
Simply put, dsh-superagent is a colleague that stays in a repository long-term. It watches a repository, listens to people, and turns permitted requests into work orders. Beyond code hosting platforms, it can also connect to Feishu—taking on work in chats, executing each work order in an independent session and directory, and finally sending results back to the original conversation.
This positioning defines its divergence from common AI programming tools: it does not passively respond to every input, but embeds itself in team collaboration workflows and acts continuously within clear boundaries.
Code hosting platform here broadly refers to services like GitHub and GitLab that provide repository hosting, Issue/PR collaboration, and Webhook event notifications. The agent obtains trigger signals by subscribing to repository events (such as new Issues, comments, code pushes), and then writes back comments or commits via platform APIs. The statement "does not support Enterprise Edition" in the original text means it only connects to public SaaS endpoints and cannot integrate with self-hosted instances or private deployments, which directly limits its usability for teams with high data compliance requirements.
Feishu is an enterprise collaboration platform launched by ByteDance, offering group chats, bots, message cards, and open platform APIs. Using Feishu as a source layer means the agent can treat @ messages in group chats as trigger events and send execution results back to the same conversation as messages, allowing "taking on work" to happen where teams communicate daily without forcing members to switch to the code hosting platform interface.
The Counterintuitive First Principle: Minimize Attention Occupation
Its first principle is quite counterintuitive: occupy as little of people's attention as possible. The logic is straightforward—an agent capable of acting for the entire team can also waste the entire team's attention. So it acts only when requested or when rules written by the team permit; it speaks only when a human must make a decision or when the result is truly usable. It asks one specific question at a time, and stops based on scope of impact rather than workload.
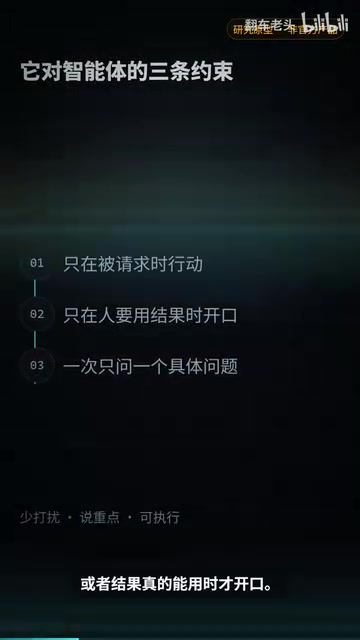
This "stop based on scope of impact" design means the agent won't frequently interrupt people just because the task volume is large, but seeks confirmation only when the decision truly matters.
Seven Core Concepts Linking the Entire Chain
The entire chain has only seven core concepts. Sources generate triggers; a trigger is an immutable event, and the same event can belong to multiple threads; a thread is the unit of evaluation and auditing, and a thread runs only one evaluation at a time; evaluation first passes admission, then does assessment, and finally gives borrow, stop, ignore, or incomplete; borrowing generates work orders and authorizations; authorization records policy version, scope, and strength; dispatch hands the work order to the executor, and results are written back to the source through channels.
The value of this seven-concept chain lies in turning "what the agent did, why it could do it, and how far it got" into a traceable structure, rather than scattering it across conversation history.
Immutable event means that once a trigger is generated, it is no longer modified, and all subsequent processing is based on a snapshot of that event. The benefit is a stable audit chain: the same event can be referenced by multiple threads, but no one can write back and tamper with the original input, avoiding the problem of "unclear responsibility caused by post-hoc requirement changes."
Admission is the first gate in the evaluation phase, determining whether a trigger under the current policy is worth entering assessment—equivalent to a cheap rule-based filter before consuming model inference resources. Assessment is intent understanding and impact evaluation of requests that pass admission, outputting one of four conclusions: borrow, stop, ignore, or incomplete. Splitting "whether to process" and "how to process" into two steps both reduces ineffective inference overhead and allows rejection reasons to be recorded and audited separately.
Authorization Mechanism: Three-Layer Admission and Observation Mode
What's truly interesting is authorization. It splits admission into three layers: who can initiate, with what strength, and how far this work order can go. The allowlist determines who can directly name; the admission table determines how to handle when not named; accounts in the bot list can only produce inferred candidates, not initiate explicit requests. For example, if someone not on the list follows up in a thread where a work order has already been opened, by default they will only get an inferred candidate, not directly become new work.
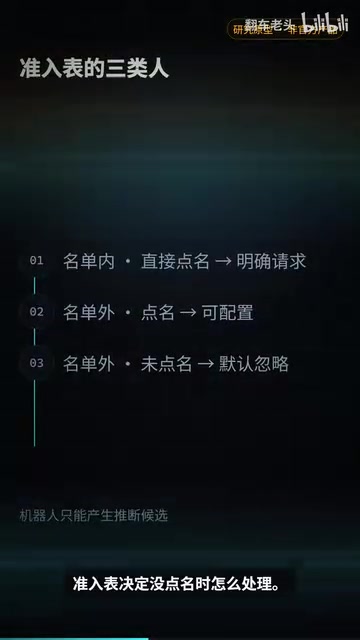
Borrow mode has two types: observation and automatic, with observation as the default first—recording only what would have been taken on, and switching to automatic after confirming the records are fine. Authorization can be manually stopped and will be re-validated after policy changes.
Observation mode (dry-run) borrows the canary idea from continuous delivery: the agent completes admission, assessment, and borrowing decisions as usual, but does not actually dispatch and execute; it only records "what would have been taken on and how it would have been changed" for human verification. It is isomorphic to mocking in unit tests or the plan phase in infrastructure—first make behavior visible, then make behavior effective. This default choice reflects the designer's judgment that the cost of "agent misbehavior" is higher than the cost of "agent doing less," and explains why switching to automatic mode is designed as an action requiring explicit confirmation.
Execution Isolation and State Management
Each work order has an independent session and an independent directory, usually a code worktree. The executor runs commands in the background; if it exceeds five seconds, it turns into a background task so people can interject at any time; background tasks run for at most thirty minutes, then are killed on time, leaving results for the next round. When concurrency is full, human messages still have an extra slot and won't be blocked by new work. After a restart, running dispatches restart with recovery prompts.
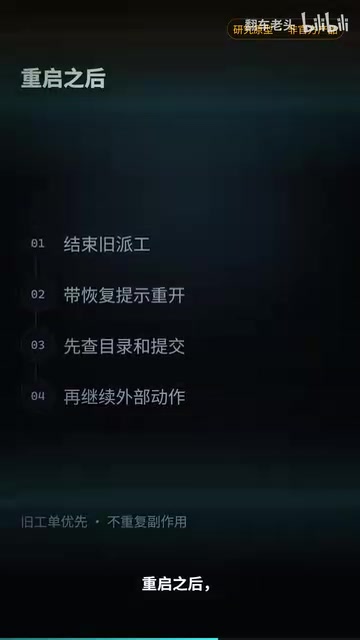
At the code level, it strictly controls who can write state: the engine is the sole writer of triggers, ready decisions, and work order dispatches; each command is one transaction; side effects go into a persistent queue with backoff retries on failure; the entire state is stored in a local database that can resume after restart. The source code also stipulates that the core layer does no input/output, and the source layer does not reversely depend on the application layer; settings and prompts are also saved by version, so upgrades won't overwrite text modified by the team.
Code worktree is a Git mechanism that allows checking out multiple independent working directories under the same repository, each pointing to different branches while sharing the same object database. Using it as the execution directory for each work order allows multiple tasks to modify code in parallel without interference, and makes it easy to discard or review the whole thing after the task ends. It should be noted that worktree isolation only resolves file-level conflicts and does not provide process or system call level isolation—this is exactly the meaning of the original text's statement that "the executor runs as an OS user and isolation is very weak": once the executor runs a malicious or erroneous command, the impact scope is still the entire user environment.
Several Design Details Worth Copying
Subscriptions automatically push subsequent discussions to the executor, so there's no need to @ again; but context subscription only provides information, not permission—the executor can follow along, but cannot use it as authorization. Policy changes notify only affected people and won't roughly cancel running work orders—to truly stop, only a human pressing stop, or re-validation failing.
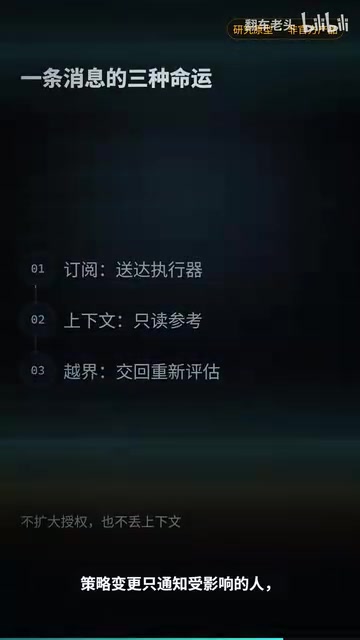
The common direction of these details is: strictly separate "permission" and "information," and reserve "stop" as an explicit human action.
It's a Research Prototype, Not a Product
It's important to be clear-headed: dsh-superagent is a research prototype, not a product. It has only one commit, much of the code was generated by the agent, and the style is inconsistent; the executor runs as an OS user with very weak isolation; the database only grows and never deletes, so it will keep growing over long-term operation; it only supports public code hosting platforms, not Enterprise Edition; and it cannot be downgraded after upgrade.
So it's better suited for reading the design and doing experiments, rather than directly hosting production repositories. If you want to see how a team-level agent should manage permissions, queue work, and not be annoying, this repository is worth reading; but don't put it directly into production—start with one repository in observation mode, let the agent first prove it won't cause trouble, then talk about automation. This is the most worth-learning part of this project, and also its most dangerous part.
One-line Summary
DeepSeek's open-source agent dsh-superagent follows a principle of minimal disruption, using a seven-concept chain and three-layer authorization to turn repository collaboration into auditable work orders.
Paragraph Summary
DeepSeek's open-source dsh-superagent is a proactive agent that stays in a repository long-term. Its goal is not chatting or completion, but turning permitted requests in the team into work orders, executing them in independent sessions and worktrees, and writing results back to the original conversation; it can also connect to Feishu. It follows the counterintuitive principle of "occupy as little of people's attention as possible," deciding when to stop and ask people based on scope of impact rather than workload. The entire chain is linked by seven concepts: source, trigger, thread, evaluation, borrowing, authorization, and dispatch. Authorization is split into three layers: who can initiate, with what strength, and how far the work order can go, with observation mode as the default to record first and then switch to automatic. Engineering emphasizes a single writer, transactional commands, background task timeouts, and recoverable dispatch, but OS-level isolation is very weak, the database only grows, and it only supports public platforms—so it's better suited for reading the design and doing experiments rather than directly hosting production repositories.
Related articles

Pi Agent Tutorial: How Minimalist Design Reshapes AI Agent Development
An in-depth look at Pi Agent's minimalist design philosophy: why it still draws high attention alongside Codex and Claude Code, from GitHub Star trends to extension mechanisms, with a Bilibili practical tutorial covering installation, configuration, and Agent development for beginners and advanced developers.

Codex in Practice: A Complete Guide to Enterprise-Grade Agent Skills Development
An in-depth analysis of a Bilibili Codex practical course covering core capabilities, agents.md configuration, MCP protocol, multi-agent collaboration, and enterprise plugin development—building a complete framework for enterprise AI coding tool adoption.

A Beginner's Guide to LLM Fine-Tuning: From Principles to Industry Implementation
Starting from the layered structure of general LLMs, this guide systematically covers the motivations, cost comparisons, and applicable scenarios of LLM fine-tuning, with three open-source cases: Bencao, LawGPT, and FinGPT, illustrating implementation paths in healthcare, law, and finance.