NeurIPS AI Detector Wrongly Rejects 178 Papers, Triggering Academic Trust Crisis

NeurIPS's black-box AI detector wrongly rejected 178 papers, exposing the dangers of algorithmic gatekeeping in academia.
NeurIPS's Position Paper Track used third-party AI detector Pangram to desk-reject 178 submissions (18.4% of all papers) with no human review or appeal channel. Researchers later found that the track chairs' own papers scored 24–69% AI-generated on the same tool, and that organizers had quietly adjusted detection parameters after an initial 42.7% flag rate looked too suspicious. The system also appears systematically biased against non-native English speakers — Stanford research shows over 60% of human-written TOEFL essays are misclassified by similar tools. The incident raises a critical question: should unexplainable black-box algorithms hold veto power over academic work?
178 Papers Desk-Rejected with a Single Click: Algorithmic Justice in Academic Review
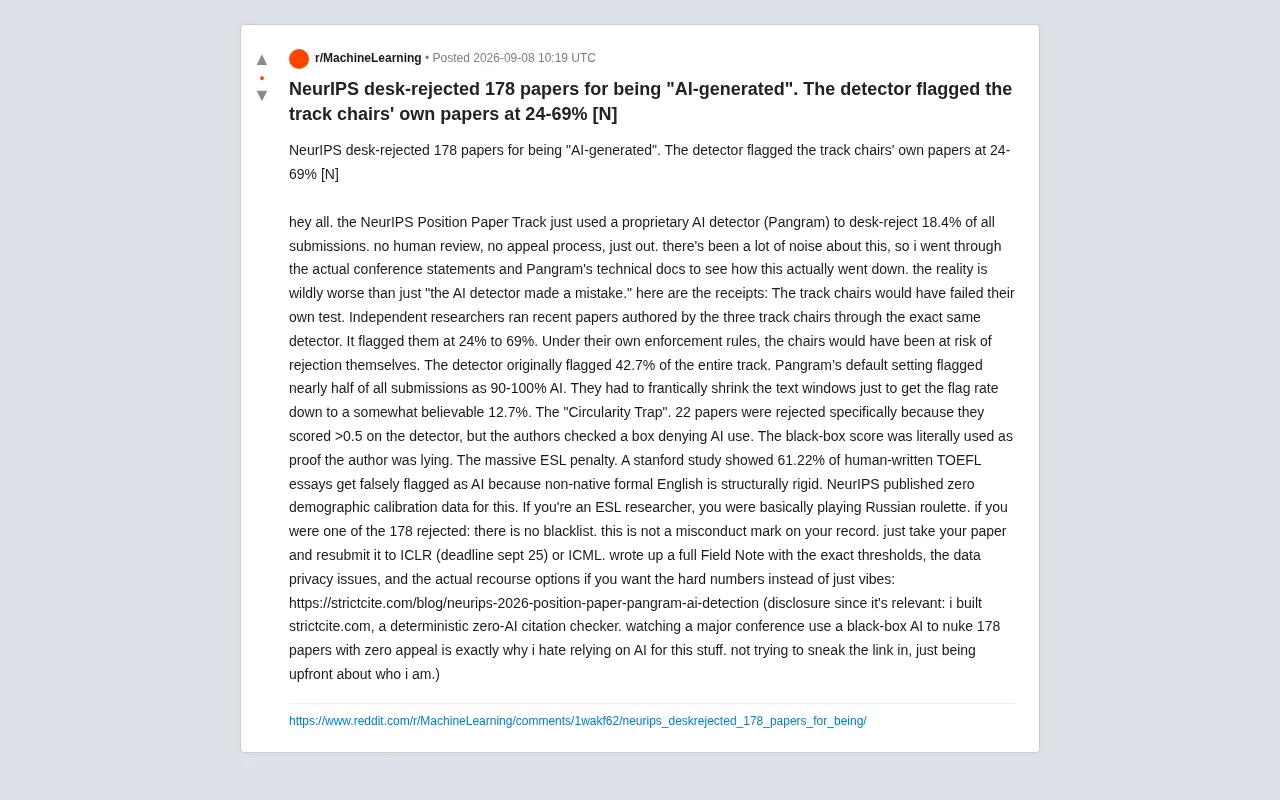
The machine learning community was rattled recently by events in NeurIPS's Position Paper Track. The track used a third-party proprietary AI detector called Pangram to desk-reject 18.4% of all submissions — 178 papers — with no human review and no appeal process.
For researchers who spent months on their work, being overruled by a black-box algorithm with no recourse already crosses a fundamental line in academic peer review. But as community researchers (including the creator of strictcite.com) dug into the conference's statements and technical documentation, the situation turned out to be far more absurd than anyone expected.
The People Who Made the Rules Can't Pass Their Own Test
The Track Chairs' Own Papers Were Flagged as AI-Generated
Perhaps the most damning finding: independent researchers ran the recent publications of all three track chairs through the same Pangram detector. The results showed AI-generation probabilities ranging from 24% to 69%.
Under the enforcement standard these chairs themselves put in place, their own papers would be at risk of rejection. The fact that the rule-makers couldn't pass their own test is a damning indictment of the standard's fundamental validity.
The Threshold Was Tuned on the Fly
The story behind the numbers is even more troubling. Pangram's default settings initially flagged 42.7% of submissions as 90–100% AI-generated — nearly half of all papers deemed "almost entirely machine-written."
Faced with this obviously anomalous result, organizers hastily narrowed the text detection window to bring the flagging rate down to 12.7%. This post-hoc adjustment reveals the truth: the so-called "scientific threshold" was nothing more than a number tweaked repeatedly until it looked reasonable.
Two Systemic Failures: Circular Logic and Identity Bias
A Black-Box Score as the Sole Evidence of Academic Misconduct
Among the rejected papers, 22 were rejected because their Pangram score exceeded 0.5 and the authors had checked a box declaring "I did not use AI."
The logic here is deeply troubling: an unexplainable, unverifiable probability score was treated as proof that an author lied. Authors had no opportunity to defend themselves — the algorithm's output was the final verdict. This is, in effect, replacing factual determination with statistical inference.
Systemic Bias Against Non-Native English Speakers
The fairness problem runs even deeper when it comes to non-native English (ESL) researchers. Stanford University research has shown that 61.22% of human-written TOEFL essays are misclassified as AI-generated by AI detectors.
Formal English written by non-native speakers tends to be more structured and formulaic — precisely the features AI detectors use to identify "machine text." Yet NeurIPS deployed this system without publishing any demographic calibration data.
For researchers whose first language isn't English, submitting to this track was a game of Russian roulette — rejection might have nothing to do with the quality of their work, and everything to do with their linguistic background.
Practical Advice for Rejected Authors
For those 178 rejected authors, community researchers have offered several practical suggestions:
- No lasting academic stigma: This rejection will not be marked as misconduct on any academic record
- Resubmit directly: Papers can be submitted as-is to ICLR (deadline September 25) or ICML
- Preserve writing evidence: If you're confident your work is human-written, save documentation of your writing process for future reference
Algorithms Should Not Hold Life-or-Death Power Over Academic Work
The core issue this incident exposes is not "Pangram isn't accurate enough." It's this: should we allow opaque, uninterpretable black-box algorithms to hold veto power over academic scholarship?
AI text detectors have fundamental, hard-to-overcome limitations by design — they output probabilities, not facts, and they carry systemic biases against specific groups (non-native speakers, formally structured writing styles). Using such tools for no-appeal, no-review automatic rejection is, in essence, forcing statistical uncertainty into a deterministic punishment.
The researcher who broke this story built strictcite.com — a "deterministic, zero-AI" citation verification tool. Having witnessed a top conference use a black-box AI to summarily reject 178 papers with no avenue for appeal, he is more convinced than ever: in high-stakes contexts like academic integrity, blind reliance on AI is a mistake.
The NeurIPS incident is a wake-up call for academia: as we embrace AI tools, we must preserve three non-negotiable safeguards for algorithmic decision-making — human review, transparent calibration, and an appeals process. Without them, the very tools we adopt in the name of fairness risk becoming new sources of injustice.
Related articles

Tencent WorkBuddy Hands-On: How AI Agents Crush Traditional Chat Assistants
WorkBuddy vs Doubao tested: how AI Agents directly operate computers to convert PPT to PDF, archive files and more. Analysis of WorkBuddy's low barrier, domestic ecosystem, pricing and plugin marketplace, plus AI Agent selection advice.

Azure Cross-Tenant Attack Chain: Root Cause Analysis of Five Paths
Binary Security analyzes five full cross-tenant compromise paths in Azure, trending 271 points on HN. This article interprets their shared root cause perspective and offers defense recommendations for cloud tenant isolation and reflections on responsibility boundaries.

Recreating a Real Bubble Tea Station in Isaac Sim: Script-Driven Unitree G1 Brews Tea
Developers recreated a real self-service tea station in NVIDIA Isaac Sim, using scripts to drive a Unitree G1 through a five-step tea-brewing process, exploring whether physics simulation can be a source of synthetic robot demonstration data and discussing contact stability and imitation learning.