NVIDIA PAIR Router: Pooling Local GPU Compute for Multi-Agent Collaboration
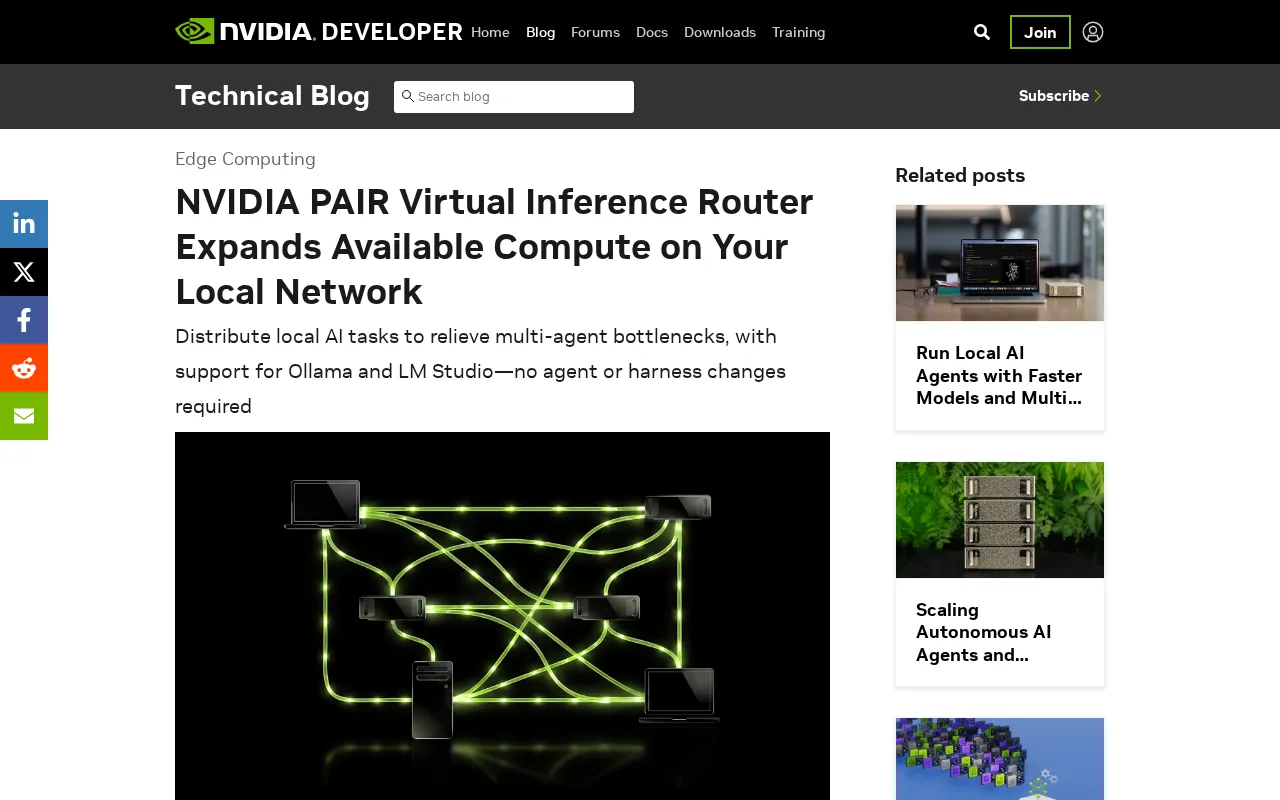
NVIDIA PAIR aggregates local network GPUs into a unified inference pool for low-latency, cost-efficient multi-agent workloads.
NVIDIA's PAIR (Personal AI Router) is a virtual inference router that aggregates GPU compute from multiple devices on the same local network into a unified resource pool for multi-agent systems. When a lead agent distributes subtasks to concurrent subagents, single-machine GPUs often become a bottleneck. PAIR uses intelligent routing and load balancing to dynamically dispatch inference requests to nodes with available capacity, scaling throughput horizontally without new hardware. Local inference also satisfies data compliance requirements in regulated industries and reduces long-term reliance on cloud APIs. PAIR signals a broader shift in AI inference infrastructure — from single-machine execution toward networked, distributed resource orchestration.
The Compute Bottleneck in the Age of AI Agent Collaboration
AI agents are learning to tackle increasingly complex tasks through collaboration. A lead agent can break down a complex task into smaller subtasks and delegate them to specialized subagents. This multi-agent architecture dramatically expands the capability of AI systems — but it also introduces an unavoidable practical bottleneck: compute supply.
When agent systems run locally, the GPU resources of a single machine are often insufficient to handle the concurrent inference demands of multiple agents. In enterprise networks or everyday development team environments, multiple GPU-equipped workstations and servers may exist, yet these compute resources remain siloed and impossible to schedule collectively. NVIDIA's PAIR (Personal AI Router) is designed precisely to address this pain point.
The Core Concept Behind PAIR: Pooling Local Network GPU Compute
Unifying Distributed GPUs into a Single Compute Pool
PAIR's core value can be summed up in one line: Expands Available Compute on Your Local Network. In the traditional model, inference tasks on one machine can only rely on that machine's GPU. As a virtual inference router, PAIR aggregates the compute resources of multiple devices on the same local area network, forming a unified compute pool that agent systems can schedule against.
This means that when a lead agent splits work into multiple subtasks, inference requests are no longer confined to a single machine — they can be intelligently routed to any device on the network with available capacity. For developers, small teams, or enterprises with multiple GPU-equipped machines, PAIR effectively expands capacity without requiring additional hardware purchases, boosting overall inference throughput.
Intelligent Routing and Load Balancing
As a "router," PAIR's key responsibility is distributing requests across multiple inference endpoints. It continuously monitors the compute status, load levels, and model deployments of each device on the network, directing inference requests to the most suitable node. This design aligns naturally with multi-agent workflows — the lead agent handles task orchestration while PAIR manages the underlying compute scheduling and load balancing, each fulfilling its distinct role.
Why Local Network Compute Aggregation Matters
Privacy and Data Security Compliance
Keeping inference tasks within the local network — rather than relying on cloud-based APIs — is critical for scenarios involving sensitive data. Industries such as finance, healthcare, and legal services face strict data residency and compliance requirements. Local agent inference allows organizations to fully leverage their existing hardware while ensuring data never leaves the internal network. PAIR makes a "local-first" AI deployment strategy significantly more viable.
Long-Term Cost Advantages
As agent applications grow more complex, the costs of calling cloud-based large model APIs accumulate rapidly. Many enterprises and developers already possess substantial GPU resources — they simply lack a unified scheduling layer to put them to work. PAIR reduces dependence on paid cloud inference services, converting idle local compute into real productivity and delivering meaningful cost savings over the long run.
Low-Latency Inference Responses
Inference requests within a local network don't need to traverse the public internet, resulting in lower latency and faster responses. For complex tasks requiring multiple rounds of interaction and frequent subagent invocations, the latency saved on each call adds up — significantly improving overall user experience and task completion efficiency.
The Deeper Significance of PAIR for Multi-Agent Architectures
The performance of multi-agent systems is highly dependent on the elasticity of the underlying inference infrastructure. When a lead agent simultaneously activates multiple subagents, a compute bottleneck can quickly lead to queuing, timeouts, or outright task failures. By horizontally aggregating local network compute, PAIR provides more abundant resource guarantees for concurrent multi-agent execution.
From an architectural evolution perspective, NVIDIA's move reflects an important trend: AI inference is shifting from "single-machine, single-task" toward a networked, distributed model of resource organization. PAIR occupies the role of an intermediate abstraction layer — abstracting away the heterogeneity and distributed complexity of the underlying hardware above, while maximizing utilization of every available compute resource below.
Looking Ahead: Infrastructure for Edge and Personal AI
The emergence of PAIR can be seen as a pivotal step in NVIDIA's infrastructure roadmap for "personal AI" and "edge AI." As more AI capabilities migrate to local devices and enterprise intranets, the ability to efficiently organize and schedule distributed compute will become a key determinant of application quality.
For developers, PAIR lowers the barrier to building complex multi-agent applications without being constrained by the ceiling of single-machine compute. For enterprises, it provides a viable path to deploying AI agents at scale while maintaining data security and controlling costs. As compute aggregation and routing technologies like PAIR mature, local networks will gradually evolve into elastic, scalable "private inference clouds."
Related articles

DeepSeek Harness: A Beginner's Installation and Testing Guide
A DeepSeek Harness tutorial for test engineers: set up Node.js, launch with one NPX command, configure official and third-party models, and explore web search, file I/O, and trace-view agent observability.
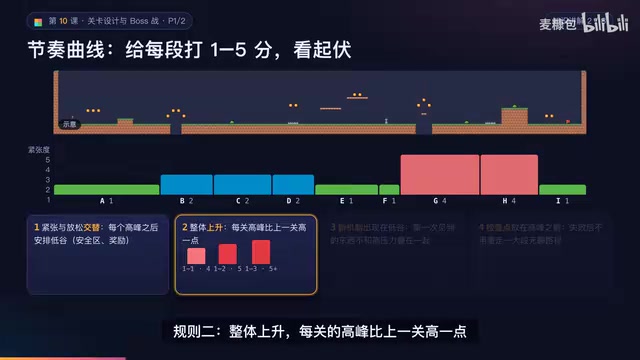
AI Game Development in Practice: Designing Levels with the Four-Step Method and Pacing Curves
AI game development lesson 10: design levels with the four-step method (teach, practice, combine, test) and a 1-5 pacing curve, plus sightline guidance and safety zones—implement Animatable Body 2D moving platforms and generate ASCII sketches for 1-2 Underground Cavern and 1-3 Guard Hall.
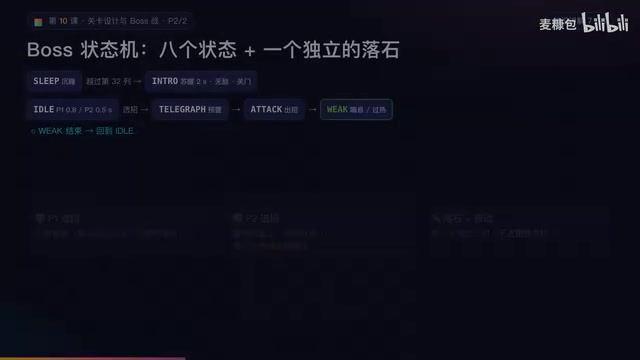
AI Game Development in Practice: Two-Phase Boss State Machines and Death Heatmap Tuning
AI game development lesson 10: implement a two-phase Boss with a state machine, guarantee fairness with color signals and a 0.4-second warning floor, locate difficulty cliffs with a death heatmap, and apply lightest-to-heaviest fixes one at a time, with an acceptance checklist and common pitfalls.