Qwen 4 Launch Imminent? The Community Buzz Behind "Qsoon"

Qwen team's "Qsoon" reply fuels community anticipation and speculation about Qwen 4.
The article outlines the AI community's anticipation for Qwen 4, sparked by the Qwen team's playful "Qwhen? Qsoon!" reply on X with a Chinese poster meme, which ignited discussion in the LocalLLaMA subreddit. Anticipation stems from an unconfirmed "next week" release tweet and the community's desire for stronger intelligence, lower resource needs, and faster speed. The discussion blends memes, rational reflection on rumor-driven expectations, and developers already planning hardware for a 250B-parameter MoE model.
An Anticipation Sparked by "Qsoon"
Recently, a mix of excitement and impatience has been spreading through the AI developer community. It started with a tweet from the Qwen development team on X: "Qwhen? Qsoon! For our friends outside China, the Chinese text in the poster comes from...". This playful response, paired with a Chinese poster meme, instantly ignited speculation about a Qwen 4 release.
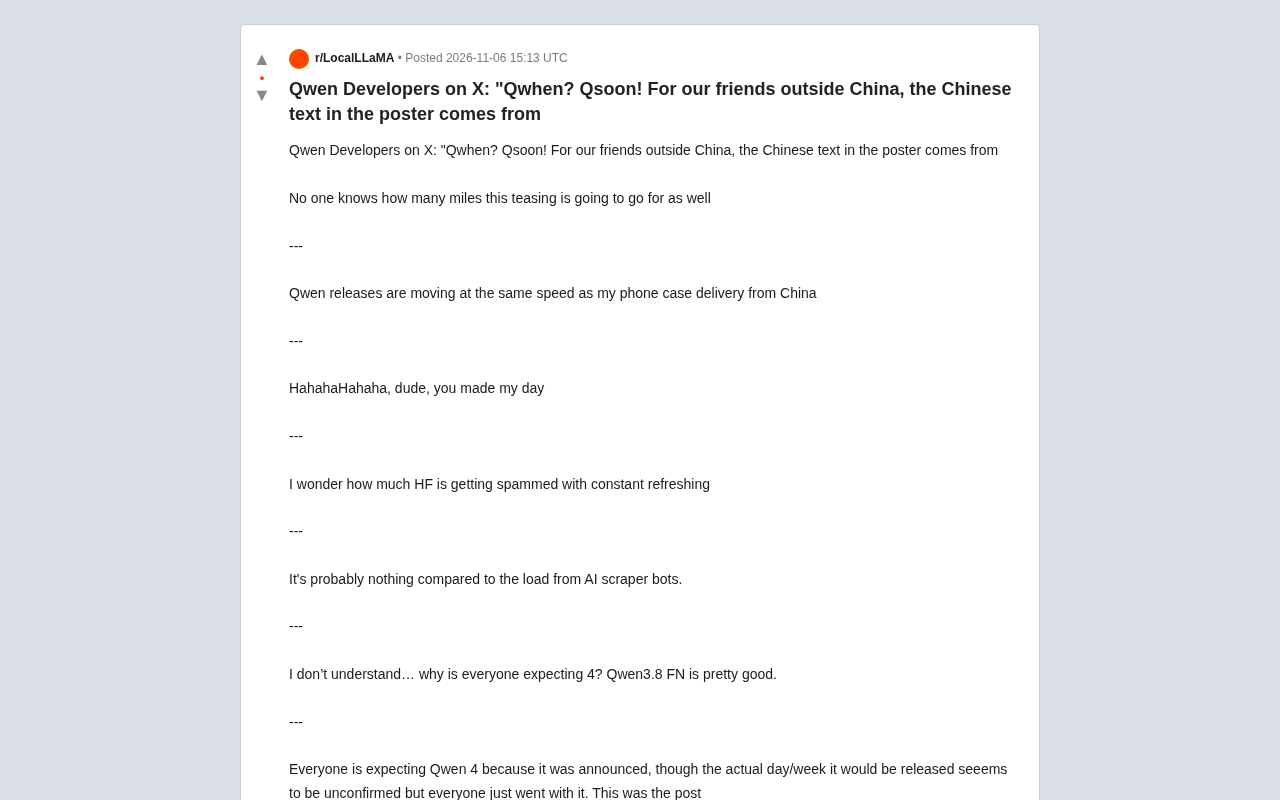
In the LocalLLaMA subreddit, related discussion quickly heated up. Users joked that "Qwen's release pace is as fast as my phone case shipping from China," while also compulsively refreshing the Hugging Face page, hoping the model weights would suddenly appear. This contradictory mindset precisely reflects the special status of the Qwen series within the open-source community.
Why Is Everyone Waiting for Qwen 4?
The Interweaving of Official Teasers and Community Rumors
According to community discussion, the anticipation for Qwen 4 is not unfounded. Some users pointed out that Qwen 4 has already been "announced," but the specific release date or week has not been confirmed. Previously, a post from Apsara Conference (titled "Qwen4 Next Week") circulated in the community, and the CTO's remarks in the screenshot were interpreted as "releasing next week." This unconfirmed news spread rapidly, leading many to expect Qwen 4 to appear this week.
However, the official line has consistently been "soon." This vague wording, combined with the community's own interpretation of "next week," has together created the current peak of anticipation. One user put it bluntly: "Everyone's expecting Qwen 4 because the news is out, but the actual date is uncertain, so people just guess along."
Apsara Conference is Alibaba's flagship annual technology summit, usually held in the Yunqi Town by the West Lake, where the latest achievements in cloud computing, AI, and chips are unveiled. Multiple generations of Qwen models have made appearances at such events. Because of this, the community is particularly sensitive to any CTO remarks or PPT screenshots that leak from the conference—in the open-source model circle, an oral teaser at a conference often surfaces earlier than official press releases and is more easily amplified and rewritten in retelling. This also explains why a post titled "Qwen4 Next Week" was quickly treated as a quasi-official signal, despite its source and exact wording being unverified.
The Desire for Stronger Intelligence and Lower Resource Requirements
Setting aside the release date, the community's anticipation for Qwen 4 fundamentally stems from the pursuit of model capability. Users hope to see "more intelligence, lower resource requirements, and faster speed." Currently, Qwen 3.8 FN is generally considered "pretty good," but Qwen 4 will most likely be better. This belief in iterative progress is the core driving force behind the open-source community's continued attention to Qwen.
It's worth noting that some developers have already begun preparing to run larger-scale models. One user mentioned that he is preparing enough memory to run a 250B-parameter MoE model and looks forward to an excellent flash model that can rival frontier models. This indirectly shows that the Qwen series' layout in medium-to-large parameter models is influencing developers' hardware planning.
MoE (Mixture of Experts) is a sparsely activated model architecture: the model contains multiple "expert" sub-networks internally, but each forward pass only routes to and activates a few of them, so the total parameter count can be very large while the actual computation per inference is far less than that of a dense model with the same parameter count. This is precisely why the community focuses on MoE when discussing 250B-parameter models—it makes very large models feasible under constrained VRAM and compute conditions. However, MoE still has high VRAM capacity requirements, because all expert weights typically need to reside in memory, which is why developers plan their memory configurations in advance.
The Community in All Its Variety: From Memes to Rational Analysis
Humor and Anxiety Coexist
There is no shortage of humor in the Reddit discussion. Someone joked that Hugging Face's servers might be getting "spammed" by constantly refreshing requests, while another user calmly responded: "Compared to the load from AI crawler bots, that's probably nothing." This lighthearted atmosphere adds a touch of fun to the waiting process.
Hugging Face is currently the most central model hosting and distribution platform in the open-source AI community, where model weights, datasets, and demo Spaces are mostly released. Since users repeatedly refresh model pages to be among the first to download when a new model goes live, its servers often bear a surge of traffic on the day a popular model is released, which the community jokingly calls "getting hammered." This also makes "staring at Hugging Face waiting for weights" a distinctive collective behavior in the open-source model release cycle.
Reflections on "Rumor-Driven" Expectations
Not everyone is immersed in anticipation. When one user explained that "people expect Qwen 4 to release this week because last week's unconfirmed tweet said the CTO mentioned 'next week,'" another user shot back: "So you're basing this on gossip? Got it!" This exchange highlights a typical phenomenon in community information dissemination: unofficial news often spreads faster than official statements and is more easily taken as fact.
This reflection does not deny the anticipation but reminds the community to stay rational amid enthusiasm. After all, the official word is "soon," and "soon" can be short or long.
The Open-Source Ecosystem in Waiting
Qwen's release cadence affects many developers' workflows. Some have already built working solutions with Qwen 3.8 FN, so their attitude toward Qwen 4 is "if they want to take their time, that's fine." This pragmatic attitude contrasts with users eager to try new things, and also shows the diversity of different user groups within the open-source community.
From a broader perspective, the reason the Qwen 4 release rumors can spark such widespread discussion precisely demonstrates that open-source large models have become part of the AI development infrastructure. Each version update may affect the performance boundaries and cost structures of downstream applications. And the memes, analysis, questioning, and preparation shown by the community during the wait together form a vivid picture of the open-source ecosystem.
As for when Qwen 4 will actually arrive, perhaps only "Qsoon" knows the answer. But one thing is certain: when it truly releases, the refresh button on Hugging Face will once again be put to the test.
Background Note
The "Soon" release culture is quite common in AI labs: to avoid committing to deadlines, teams often only tease with vague time words, while the community fills in the blanks itself, interpreting clues as specific dates. This information asymmetry creates a self-reinforcing cycle of expectations—the more specific the rumor, the greater the disappointment when it falls through, which in turn spawns the next round of speculation. Understanding this helps distinguish official signals from community narratives, and also explains why the same "soon" means completely different time spans to different people.
One-line Summary
Qwen team responded to release inquiries with "Qsoon," igniting community anticipation and speculation about Qwen 4.
Paragraph Summary
The article outlines the AI community's wave of anticipation for Qwen 4. It began when the Qwen development team on X responded playfully with "Qwhen? Qsoon!" alongside a Chinese poster meme, sparking discussion in the LocalLLaMA subreddit. The anticipation stems from two sources: first, an Apsara Conference-related tweet was interpreted as "releasing next week," which spread rapidly despite being unconfirmed; second, the community craves stronger intelligence, lower resource requirements, and faster speed. The discussion includes memes and humor about refreshing Hugging Face, rational reflections on rumor-driven expectations, and developers already planning hardware for a 250B-parameter MoE model. The article ultimately points out that this waiting reflects how open-source large models have become part of the AI development infrastructure.
Related articles
 Tech Frontiers
Google Omni 1.2 Flash: 15-Second AI Video at Just $0.07 per Second
Google DeepMind releases Gemini Omni 1.2 Flash: 15-second video, 720p at $0.07/sec (30% cheaper), multi-turn editing without regeneration, draft upscaling to 4K.
 Tech Frontiers
No AI Ghostwriting: Writer's Quarter Reinvents Novel Writing with a Visual Workbench
The Writer's Quarter is an AI-free novel writing and planning tool that unifies character building, story planning, and manuscript writing in one visual workbench. This article analyzes its positioning, target users, and differentiated value amid the rise of AI writing tools.
 Tech Frontiers
Fleeep: A Unified Inspiration Collection Notes App for Creatives
Fleeep is a notes app for creatives that unifies screenshots, bookmarks, saved posts, and inspiration into one calm, cross-device, offline-capable space. This article analyzes its positioning, differentiation, and target users.