Rounding Position Alignment: A New Method for Stable LLM Reinforcement Learning

Aligning rounding positions in key regions such as RoPE and SwiGLU between inference and training can stabilize BF16 reinforcement learning training.
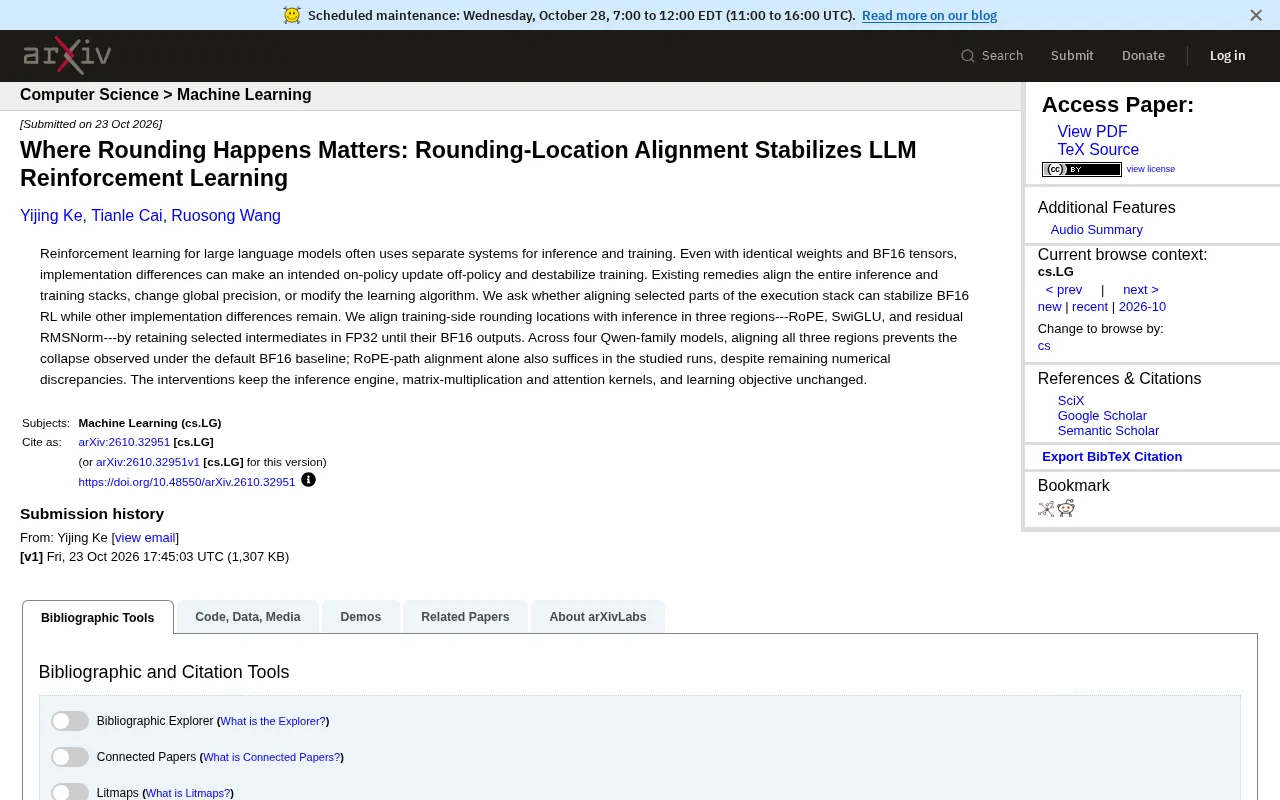
The article notes that in LLM reinforcement learning, inference and training often run on different software stacks. Even with identical weights and BF16 precision, differences in rounding positions of intermediate results can turn on-policy updates into off-policy ones, causing training collapse. The study proposes selectively keeping intermediate results in FP32 in three key regions—RoPE, SwiGLU, and residual RMSNorm—until the BF16 output stage before rounding, without changing the inference engine, matrix multiplication and attention kernels. Experiments on four Qwen series models show that aligning all three completely prevents collapse under the default BF16 baseline, and aligning only the RoPE path also stabilizes training. The method has low overhead and good compatibility, offering a lightweight solution for stable BF16 reinforcement learning.
Large language model (LLM) reinforcement learning training typically relies on two separate systems for inference and training. Even when the weights and BF16 tensors are identical, implementation differences can turn what should be on-policy updates into off-policy ones, leading to training instability. A recent study proposes that by aligning the rounding positions in inference and training, BF16 reinforcement learning training can be stabilized without changing the inference engine, matrix multiplication and attention kernels, or the learning objective.
Background: Why Are Identical Weights Still Unstable?
In the LLM reinforcement learning pipeline, inference and training often run on different software stacks. Even when both sides load identical weights and use BF16 precision, differences in implementation details can cause intermediate computation results to be rounded at different positions. These tiny numerical discrepancies gradually accumulate, causing policy updates during training to deviate from expectations and ultimately leading to training collapse.
Traditional solutions include aligning the entire inference and training stack, globally changing precision (e.g., using FP32), or adjusting the learning algorithm. But these approaches are either costly or sacrifice training efficiency.
BF16 and Rounding Error
BF16 (Brain Floating Point 16) is a 16-bit floating-point format that retains 8 exponent bits (same as FP32) but only 7 mantissa bits, giving it a large dynamic range but low precision. If the result of any floating-point operation cannot be exactly represented in BF16, it must be rounded to the nearest representable value, producing a relative error on the order of about 2^-8. In LLM RL training, forward inference and backward training involve a large number of matrix multiplications, normalizations, and activation operations, each step introducing such rounding errors. When the inference side and the training side choose different rounding timings for the same intermediate result (for example, one accumulates in FP32 before rounding, while the other rounds to BF16 at an intermediate step), the numerical trajectories of the two sides diverge. For on-policy algorithms such as PPO and GRPO that rely on importance sampling ratios, this divergence directly breaks the policy consistency assumption.
Core Method: Aligning Rounding Positions Only in Key Regions
The study proposes a more refined strategy: rather than changing the entire execution stack, selectively align the rounding positions on the training side and the inference side. Specifically, the research team keeps selected intermediate results in three key regions—RoPE (Rotary Position Embedding), SwiGLU (activation function), and residual RMSNorm—at FP32 precision until the BF16 output stage, where rounding is then applied.
The core insight of this method is that not all rounding differences matter equally; aligning the rounding behavior in key regions alone can significantly improve training stability.
Numerical Sensitivity of RoPE, SwiGLU, and RMSNorm
RoPE (Rotary Position Embedding) encodes relative position information by applying position-dependent rotations to query/key vectors. Its computation involves sin/cos and element-wise multiplication and is extremely sensitive to rounding position: a tiny deviation in rotation angle can change the relative ordering of attention scores. SwiGLU is a commonly used gated activation in Transformers, of the form SiLU(xW1) ⊗ (xW3), where SiLU contains exponential operations that easily lose precision under BF16. Residual RMSNorm performs root-mean-square normalization on the residual branch, and the normalization coefficient is determined by global statistics; any premature rounding gets amplified across the entire hidden state. Keeping the intermediate results at these three places in FP32 and rounding to BF16 only at the output stage is equivalent to making inference and training share the same rounding path in the numerically most fragile links, thereby eliminating the main source of policy divergence.
Experimental Results: Preventing Collapse, RoPE Alignment Alone Suffices
The study conducted experiments on four Qwen series models. The results show:
- Simultaneously aligning the three regions (RoPE, SwiGLU, and residual RMSNorm) completely prevents training collapse under the default BF16 baseline.
- Aligning the rounding position of the RoPE path alone was also sufficient to stabilize training in the runs studied, despite the presence of other numerical differences.
Interestingly, these interventions do not change the inference engine, matrix multiplication and attention kernels, nor the learning objective, giving them excellent compatibility and practicality.
Significance and Outlook
This study reveals the importance of rounding position alignment in LLM reinforcement learning and provides a lightweight solution for stable BF16 training. Compared with global precision adjustment, this method has lower computational overhead and is easy to integrate into existing systems. In the future, this idea could be extended to more model architectures and training scenarios, helping practitioners train large models more efficiently.
For AI engineers and researchers, this finding reminds us that in mixed-precision training, the choice of rounding position may be more critical than overall precision. Finely controlling the numerical behavior of key regions may be an effective way to balance training stability and efficiency.
One-line Summary
Aligning the rounding positions of inference and training in key regions such as RoPE and SwiGLU can stabilize BF16 reinforcement learning training.
Paragraph Summary
The article points out that in LLM reinforcement learning, inference and training often run on different software stacks. Even with identical weights and BF16 precision, differences in the rounding positions of intermediate results can turn what should be on-policy updates into off-policy ones, causing training collapse. The study proposes not changing the inference engine, matrix multiplication and attention kernels, but instead selectively keeping intermediate results in FP32 in three key regions—RoPE, SwiGLU, and residual RMSNorm—until the BF16 output stage before rounding. Experiments on four Qwen series models show that simultaneously aligning the three places can completely prevent collapse under the default BF16 baseline, and aligning only the RoPE path is also sufficient to stabilize training. The method has low overhead and good compatibility, providing a lightweight solution for stable BF16 reinforcement learning.
Related articles

Google Releases Gemini 4 Carbon: Its Strongest Model Yet, Debuting with a Cybersecurity Focus
Google releases Gemini 4 Carbon, calling it its strongest model, with a cybersecurity focus. It tops the third-party composite ranking at 59 points but leads by only one or two. This article analyzes its security test results, staged rollout, token pricing, and the divergence between self-reported and third-party tests on hallucinations.

LangChain Adds SchemagateRetriever: On-Demand Table Retrieval Cuts Text-to-SQL Prompts by 92.9%
LangChain docs add SchemagateRetriever: retrieves only the tables needed for text-to-SQL with permission filtering, cutting median prompt size by 92.9% on Spider 2.0 large schemas via offline BM25 selection with no model calls.

Multi-Step AI Agent Guardrail in Practice: Fact-Change Detection Drives False-Alarm Rate to 0%
Developer shares first version of a multi-step AI Agent guardrail: re-verifying dependency facts before irreversible actions cut false alarms from 50% to 17% across 23 scenarios, then to 0% via conservative normalization without lowering catch rate. Runs on local qwen2.5-7b.