SAO Async Optimization Algorithm Explained: How Stable 1000-Step Training Outperforms GRPO

SAO is a new LLM RL post-training method that claims stable 1000-step training while consistently outperforming GRPO.
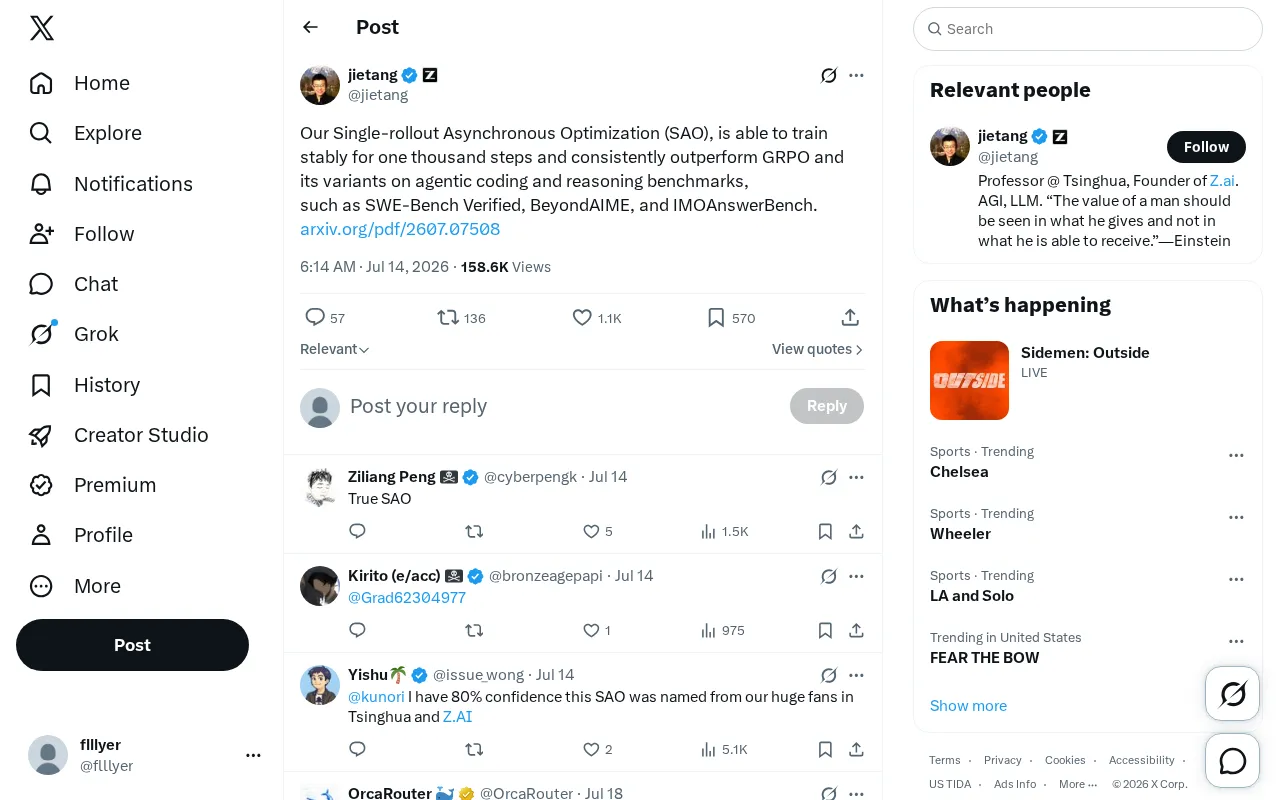
SAO (Single-rollout Asynchronous Optimization) is a new RL post-training method for LLMs designed to address the long-horizon instability of algorithms like GRPO, which often suffer from training collapse and reward oscillation. SAO streamlines gradient signals via single-rollout sampling and decouples data collection from policy updates through asynchronous optimization. The team reports stable training across 1,000 steps and consistent outperformance of GRPO on SWE-Bench Verified (agentic coding), BeyondAIME, and IMOAnswerBench (math reasoning). Its gains across two distinct task domains suggest generalizability, though full technical details and reproducibility remain to be validated.
A New Breakthrough in RL Training: Introducing SAO
In the post-training phase of large language models (LLMs), reinforcement learning (RL) is playing an increasingly critical role. Whether it's enhancing reasoning capabilities or building agents that can autonomously handle software engineering tasks, RL has become an indispensable approach. Yet existing mainstream methods still face significant challenges around training stability and scalability.
Recently, a new method called Single-rollout Asynchronous Optimization (SAO) has drawn considerable attention. According to the research team, SAO maintains stability across up to one thousand training steps and consistently outperforms GRPO and its various variants on multiple challenging benchmarks. For a field long plagued by RL training instability, this is a signal worth taking seriously.
GRPO's Limitations and SAO's Core Positioning
Why Training Stability Is the Critical Bottleneck
GRPO (Group Relative Policy Optimization) is a widely adopted RL algorithm for training reasoning models. It estimates the advantage function through within-group relative rewards, eliminating the need for a separate value network (Critic) as in traditional PPO — reducing both memory overhead and implementation complexity. However, GRPO and its variants frequently encounter training collapse, reward oscillation, and late-stage performance degradation in practice, issues that become amplified in long training runs aimed at fully extracting a model's potential.
When training can't stably progress through enough steps, models struggle to reach their theoretical ceiling on complex tasks. SAO's emphasis on "stable training for one thousand steps" targets this pain point directly — it's not chasing short-term performance peaks, but rather sustainable optimization capability over long training horizons.
The Design Philosophy: Asynchronous + Single-Rollout
SAO's core characteristics are captured in two key terms from its name:
- Single-rollout: Each policy update relies on a more streamlined sampling and trajectory generation mechanism, reducing dependence on multiple rollouts. This helps lower training overhead while potentially producing smoother gradient signals.
- Asynchronous optimization: Asynchronous optimization typically means decoupling data collection (rollout) from policy updates, running them in parallel. In large-scale RL training, this design significantly improves hardware utilization by avoiding resource waste caused by mutual waiting between the sampling and training phases.
Combining both, SAO seeks a balance between efficiency and stability, aiming to make long-horizon RL training more controllable.
SAO's Performance on Challenging Benchmarks
The SAO team selected three representative, high-difficulty benchmarks for validation, covering multiple frontiers of current AI capability evaluation:
SWE-Bench Verified: Evaluating Agentic Coding Ability
SWE-Bench Verified is an authoritative benchmark for evaluating a model's ability to solve real-world software engineering problems, with tasks drawn from actual GitHub issues and code fix requests. It requires models not only to understand code, but to locate bugs, generate patches, and pass tests within the full context of a code repository. SAO's strong performance here demonstrates its competitiveness in the practical Agentic Coding scenario.
BeyondAIME and IMOAnswerBench: Deep Mathematical Reasoning
BeyondAIME and IMOAnswerBench target advanced math competition problems at the AIME and IMO (International Mathematical Olympiad) level. These tasks impose extremely high demands on multi-step reasoning, logical rigor, and long-chain thinking. SAO's ability to surpass GRPO on these reasoning benchmarks indicates that models trained with SAO also benefit from a more stable optimization process in deep reasoning tasks.
Notably, SAO achieves leading performance across both coding and mathematical reasoning — two quite distinct task domains. This suggests the improvements are not the result of task-specific overfitting, but reflect a certain degree of generalizability.
Technical Significance and Future Outlook
The Decisive Impact of Long-Horizon Stable Training on Model Capability
As reasoning models become the industry's dominant direction, the scale of RL post-training continues to expand. The ability to stably train for a large number of steps directly determines the ceiling of model capability. SAO's demonstrated "thousand-step stability" offers the field a potentially more reliable training path. If this approach can be validated across more model scales and task types, it could become a strong alternative or complement to GRPO.
Key Questions Still Awaiting Validation
The information currently available comes primarily from the research team's initial disclosure. Several critical questions await a more complete technical report or paper:
- How large are the concrete performance gains of SAO over GRPO?
- Does single-rollout sampling sacrifice exploration capability on certain tasks?
- How does the asynchronous mechanism scale across different hardware configurations?
- What are the implementation details, and how reproducible is the method?
Until these details are made public, we should view these results with cautious optimism. Regardless, the direction SAO points toward — making RL training more stable, efficient, and scalable — is one of the most pressing breakthroughs needed in LLM post-training today.
Conclusion
SAO's emergence reinforces a broader trend: in the second half of the large model capability race, algorithmic improvements — particularly around RL training stability and efficiency — are becoming just as important as data and compute. For practitioners following cutting-edge AI research, SAO is worth tracking closely. The full technical report, when it arrives, should reveal more design details and invite broader community reproduction and scrutiny.
Related articles

Adaptive Development with Jetpack Compose: Media Query, Grid, and Nav3 in Practice
A deep dive into new Jetpack Compose adaptive development tools: Media Query capability APIs, Grid 2D layout, Flexbox, Navigation 3 scene strategies, and Compose Adaptive Skill, with large-screen adaptation benefits and case data.

Google Launches Connected Apps Platform: Build Once, Integrate with Gemini and Search
Google launches Connected Apps: developers build once with a declarative schema and MCP to integrate app capabilities into Gemini and Google Search, with remote MCP and Android MCP paths, Developer Mode testing, and risk-tiered confirmation.

Lightbuild: A Declarative Android Build Built for AI Agents
Google releases Lightbuild, an experimental Android build tool that replaces executable scripts with declarative configuration for fast IDE sync and first-class AI agent support.