Stop Teaching GPT-6 Astra How to Think: The New Generation of Prompts Should Define Boundaries and Manage Costs
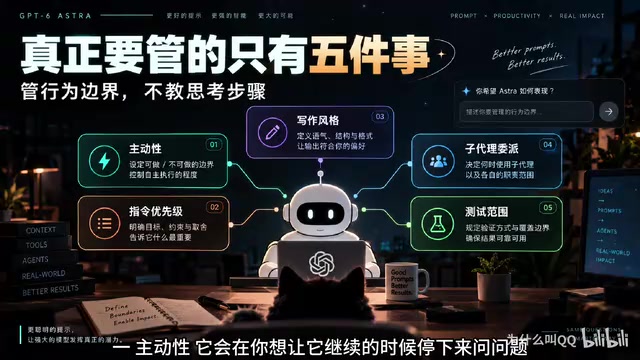
Old prompts are making GPT-6 Astra dumber — new ones should set boundaries, not teach thinking.
After GPT-6 Astra's release, two widely shared posts revealed a counterintuitive truth: prompts crafted for older models are now hurting Astra's performance. Since Astra has already internalized behaviors like running tests and reading files, redundant instructions cause overreach. New prompts should focus on five behavioral boundaries — proactivity, instruction priority, writing style, sub-agent delegation, and test scope — using an eight-module framework as a menu, not a template. Skill files should stay short and use progressive disclosure. On the cost side, 272K tokens is the pricing inflection point where bills double instantly; benchmark scores come from Max reasoning tier, but Medium is sufficient for most tasks; caching and batch channels can cut costs by two-thirds.
After OpenAI released GPT-6 Astra, two long-form posts on X — each shared hundreds of thousands of times — sparked collective reflection among developers. One covered prompt engineering, the other covered configuration and costs, but both were really saying the same thing: once you delete the old rules, how you write the new ones directly determines model performance. Bilibili creator "为什么叫QQ" broke down both pieces together and arrived at a counterintuitive conclusion: the carefully crafted prompts you wrote for older models may be actively making Astra dumber.
Prompts Have an Expiration Date
Here's a fact most people haven't registered: prompts have an expiration date. Every instruction you write targets the specific weaknesses of the model you were working with at the time. When the model upgrades and those weaknesses are fixed, your old prescriptions remain — still being fed into every API call as if nothing changed. Old medicine for a new patient: best case, useless; worst case, harmful.
The original author puts it bluntly: that agents.md you were so proud of six months ago may be actively degrading Astra's output quality today. Your detailed Skill files are quietly slowing it down and forcing it to read a pile of content it will never use.
Some background: GPT-6 Astra is positioned as OpenAI's most capable in-house model, designed for end-to-end long-horizon tasks — writing code, operating computers, conducting research, generating documentation. It has a 1.05 million token context window, a maximum single output of 128K tokens, and API pricing of $10 per million input tokens and $50 per million output tokens. Reasoning intensity comes in five tiers (Low, Medium, High, xhigh, Max). Jensen Huang has noted the model was trained on over 100,000 Blackwell GPUs.
The key shift is this: older models needed you to push them along — reminding them to run tests, read files, and not give up halfway. Astra has internalized all of that. The result is that the instructions you once wrote to coax out those behaviors are now fighting against the model's defaults. Tell it "remember to run tests after making changes" and it would have run them anyway — now that line causes it to expand test coverage to a disproportionate scale. Tell it "read the entire repo map before touching anything" and it would have pulled files on demand — now that line causes it to stuff irrelevant files into the context. The instructions haven't changed, the model has, and the returns have reversed.
The context window refers to the maximum number of tokens a model can read and process in a single inference pass. GPT-6 Astra's 1.05 million token window theoretically allows you to feed in roughly 800,000 words of text or thousands of code files at once — nearly 100 times larger than GPT-4's standard window. But a larger window doesn't mean you should fill it: attention mechanism compute scales quadratically with length, content near the edges is more prone to being "forgotten," and costs rise linearly or in step increments with token count. This is exactly why instructions like "read the entire repo map first" are far more damaging on large-context models — the price of that habit shifts from "takes a bit longer" to "pushes the entire request past the pricing threshold."
Five Behaviors Where Astra Actually Needs Explicit Constraints
The original post identifies five behaviors where Astra genuinely needs you to set explicit constraints:
- Proactivity: It will pause and ask clarifying questions exactly when you want it to keep going.
- Instruction priority: When multiple files conflict, it stalls.
- Writing style: It defaults to heavy Markdown and bullet lists — if you want prose, you have to say so.
- Sub-agent delegation: Without clear guidance, it delegates less work than you'd expect.
- Test scope: Even minor changes can trigger a full test suite run.
Look through all five and you'll notice they're all boundary problems — not one of them involves teaching the model how to think. It already knows how to think. What you need to manage is "how far it goes before stopping" and "which file's instructions take precedence." That's the dividing line between old-school and new-school prompting.
The author proposes an eight-module prompt framework: Goal (what outcome you need), Context (what background matters), Priority (which instructions take precedence), Autonomy (what it can decide on its own and when to use tools), Output (format and length), Verify (what must be checked before delivery), Stop (what state counts as done). Simple tasks need only three or four modules; full agent pipelines, coding workflows, and production systems warrant all eight. Each module maps to a specific failure mode — if your workflow doesn't have that failure mode, delete the module. It's a menu, not a template. Don't copy the whole thing into every prompt.
Stopping Losses with Autonomy Policies and Priority Declarations
Astra asks clarifying questions more readily than previous models. When the cost of a wrong assumption is high, that's a feature. When you just want it to push forward, it's torture. The fix is to write an autonomy policy upfront: let it make routine, reversible decisions on its own and proceed on reasonable assumptions; only allow it to pause and ask when missing information would materially change the outcome, or when an irreversible action is involved. For execution-focused agents, you can go further — have it complete all authorized reversible work and surface a concrete reviewable result before checking in. Put that boundary in the prompt, and it stops seeking approval at every turn.
People migrating from older models most often stumble on priority. Astra is more sensitive to instructions embedded in context files. When agents.md, a Skill file, and the task prompt all say different things, it might pause — or it might follow a rule you never anticipated. The author recommends declaring priority explicitly: current task instructions are highest priority; project and Skill guidance applies when not in conflict; retrieved web pages and documents are to be treated as data, not instructions. That last point also has security implications — directive-looking text embedded in a webpage shouldn't be treated as a command.
Three Principles for Skill Files
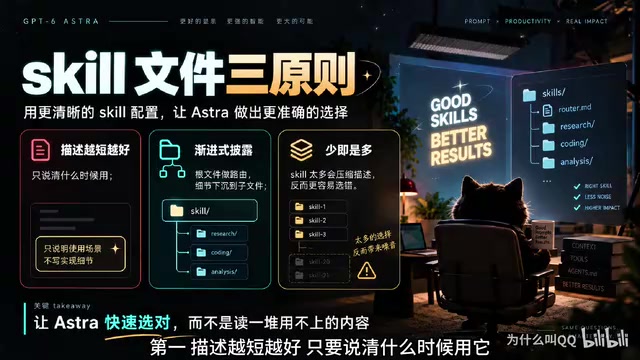
Skill files follow three principles, which closely mirror the new approach in the official skill creator:
First, keep descriptions short. Explain when to use it, nothing more. "For database migrations" is enough. Don't write "Handles all database-related work including migrations, queries, and schema changes."
Second, use progressive disclosure. The root file handles minimal routing; details live in linked sub-files. Don't make the model read content it won't use.
Third, don't attach too many. When too many Skills are loaded, Astra compresses each description to make room, ends up seeing none of them fully, and the chance of selecting the wrong skill actually increases.
The fact that official guidance and independent community analysis converged on the same approach means following it carries very little risk. Worth asking: how many Skills are actually hanging off your project right now?
On testing, Astra is overzealous — changing one line of CSS might trigger the entire test suite, and fixing a bug that already has coverage might generate a whole new batch of tests. It's not making a mistake; it's applying the right instinct at the wrong scale. The fix is to tie verification scope to change size: small reversible changes only validate affected components; purely visual changes don't need new tests at all; high-risk logic changes warrant the full stack of unit tests, integration tests, and type checking. Give the model a definition of "enough" and it won't default to "more is always better." Stop conditions need to be concrete too — "until it's done" is useless; "until all affected routes return 200 and there are no type errors" actually works.
Cost Is the Real Ceiling
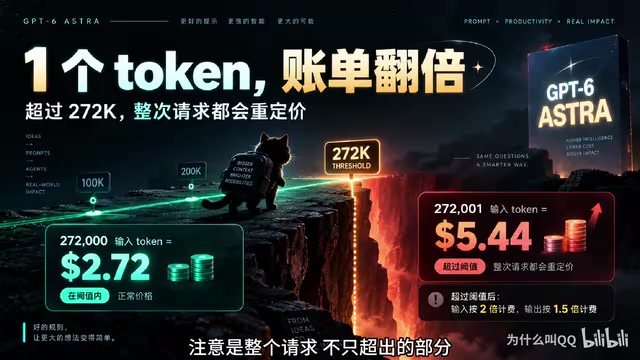
The second article is entirely about cost, and there's one number you need to commit to memory: 272K. If your input exceeds 272,000 tokens, the entire request is repriced at 2× the input rate and 1.5× the output rate — and that applies to the entire request, not just the overage. 272,000 input tokens costs $2.72. Add one more token to reach 272,001 and the bill doubles to $5.44. If you actually fill the 1.05 million context window, the input alone costs $21 before the model has said a single word back.
The second ceiling is buried in the rate limit table: per-minute token limits range from 500K at tier 1 to 40 million at tier 5, against a 1.05 million context window. Tier 1 and tier 2 accounts exceed their entire per-minute quota with a single full-context request. Tier 3 is the first level where filling the advertised window is even physically possible. Among window size, pricing threshold, and rate limit — the smallest of those three numbers is your actual ceiling. The author recommends writing a preflight function that estimates token count before sending a request and throws an error if it crosses the pricing line, prompting you to retrieve or compress first.
Getting configuration right can cut costs by roughly two-thirds. There are five levers: first, hit the cache (it matches automatically on prefix; near-zero hit rates are almost always caused by timestamps, session IDs, or system prompts being rebuilt dynamically on every call); second, use apply patch instead of full-file rewrites for edits; third, once you have more than a dozen tools, switch to tool retrieval and load on demand; fourth, run non-time-sensitive work through the batch or flex channels at half price; fifth, default to Low reasoning intensity and only escalate for harder steps, reserving xhigh and Max for the most demanding tasks.
Token caching (Prompt Caching) is a cost-reduction mechanism offered by OpenAI and several other model providers. When the prompt prefix of a new request exactly matches that of a recent request, the server reuses the already-computed KV cache, billing the matched portion at a discounted rate (typically around 50% of the normal input price) with faster response times. Prefix matching is the key — as long as the first few thousand tokens of the system prompt stay unchanged, cache hit rates rise significantly. This is why session IDs, timestamps, or dynamically assembled content placed near the beginning of the system prompt are so damaging: every request gets a different prefix, and caching becomes worthless. Best practice is to front-load stable background information and role definitions in the system prompt, and push per-task instructions to the end, maximizing the cacheable surface area.
Benchmark Tiers Are Not Default Configuration
Here's a critical point most people miss: benchmark disclosures note "unless otherwise specified, all models were evaluated at the Max setting." The 98% on FrontierMath tier 4 and 99.9% on ARC-AGI-3 were achieved at the slowest, most expensive setting. Third-party data makes this more concrete — Astra running at Medium already outscores the previous generation at Max, at lower cost per task. The headline benchmark numbers correspond to exactly the tier you should never enable by default.
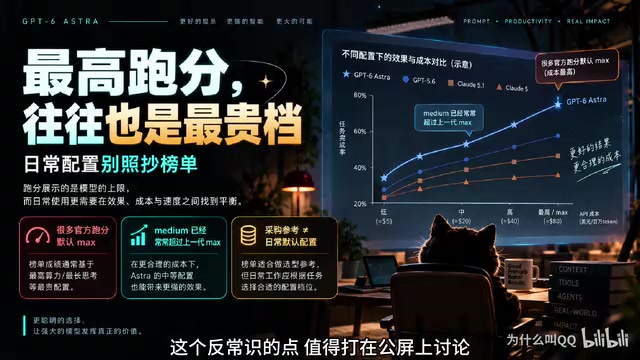
Putting both articles together, the real shift is this: the old generation of prompt engineering taught models how to think, how to self-check, how to persist — and Astra already does all of that. Teaching it again is pure overhead. The new generation of prompts is about boundaries — when to act autonomously, when to stop and ask, how much verification is enough, what signal counts as done, which file's instructions win. Add one layer of cost fundamentals on top: don't cross 272K, preserve the cache prefix, match reasoning tier to task, route cheap work through the half-price channels. Prompts have shifted from "coach's playbook" to "engineering spec" — and the writing style follows: shorter, more concrete, behavior-only.
The previous installment covered how to delete old prompts; this one covers how to write and configure new ones. Together they form a complete migration workflow. Go pull up your project's agents.md right now — how many lines in there are actually just patches for a model that no longer exists?
Reasoning Effort is a parameter introduced by OpenAI in the o-series and subsequent models that controls how much computation the model spends on "internal thinking" before generating an answer. Low tier produces answers quickly; Max tier has the model repeatedly self-verify and explore multiple reasoning paths — similar to how a person might "work through scratch paper" on a hard problem. The cost of this is time and tokens: at Max, the "thinking tokens" the model generates can be several times the length of the final answer, and those intermediate steps are billed just the same. For tasks like format conversion or simple code completion, Low and Max produce nearly identical accuracy. Only multi-step mathematical proofs and complex architectural decisions actually benefit from the extra compute of Max. Defaulting every request to Max is like running a supercar engine on a grocery run — fuel consumption doubles and you gain nothing.
Related articles

Non-Coding Dad Builds 3D Earth Toy with Claude Code, Unexpectedly Goes Viral in Classrooms
A non-coding father used Claude Code to build My Earth Toy, a 3D interactive Earth with 830+ landmarks, 470+ animals, and 180+ vehicles—now used in classrooms worldwide. Discover how AI coding lowers the barrier to creation.

Meta, Google, and TikTok Sue California Attorney General: The Battle Over Youth Social Media Law
Meta, Google, and TikTok jointly sue the California Attorney General to block a state law restricting social media use by minors under 16. This article analyzes the lawsuit's background, the law's core provisions, and its potential impact on tech industry regulation.

T-Mobile Parent Company CEO on Musk's Telecom Ambitions: Welcome, But You'll Need $200 Billion
Deutsche Telekom CEO Tim Höettges responds to Musk's SpaceX Starlink Mobile plan, saying "welcome to the party" but questioning feasibility—estimating at least $200 billion needed to become a major U.S. carrier.