The Jagged Frontier Debate: Math and Code Soar — But Will AI's Other Capabilities Hit a Ceiling?

RLVR can push math and code endlessly — but will non-verifiable AI capabilities stall at a data ceiling?
Large language models display a "jagged frontier": math and code can be pushed indefinitely via RLVR because their answers are machine-verifiable and reward signals scale at near-zero cost. But writing, value judgment, and open-ended reasoning lack ground truth, making automation hard and progress slow. The core debate is whether gains in non-verifiable domains stem from a general intelligence spillover from rigorous reasoning training — or merely from continuously injecting human data. The answer will determine whether RLVR can lift all capabilities, or whether a widening skill gap makes unique human data the decisive strategic asset.
A Question Worth Thinking About
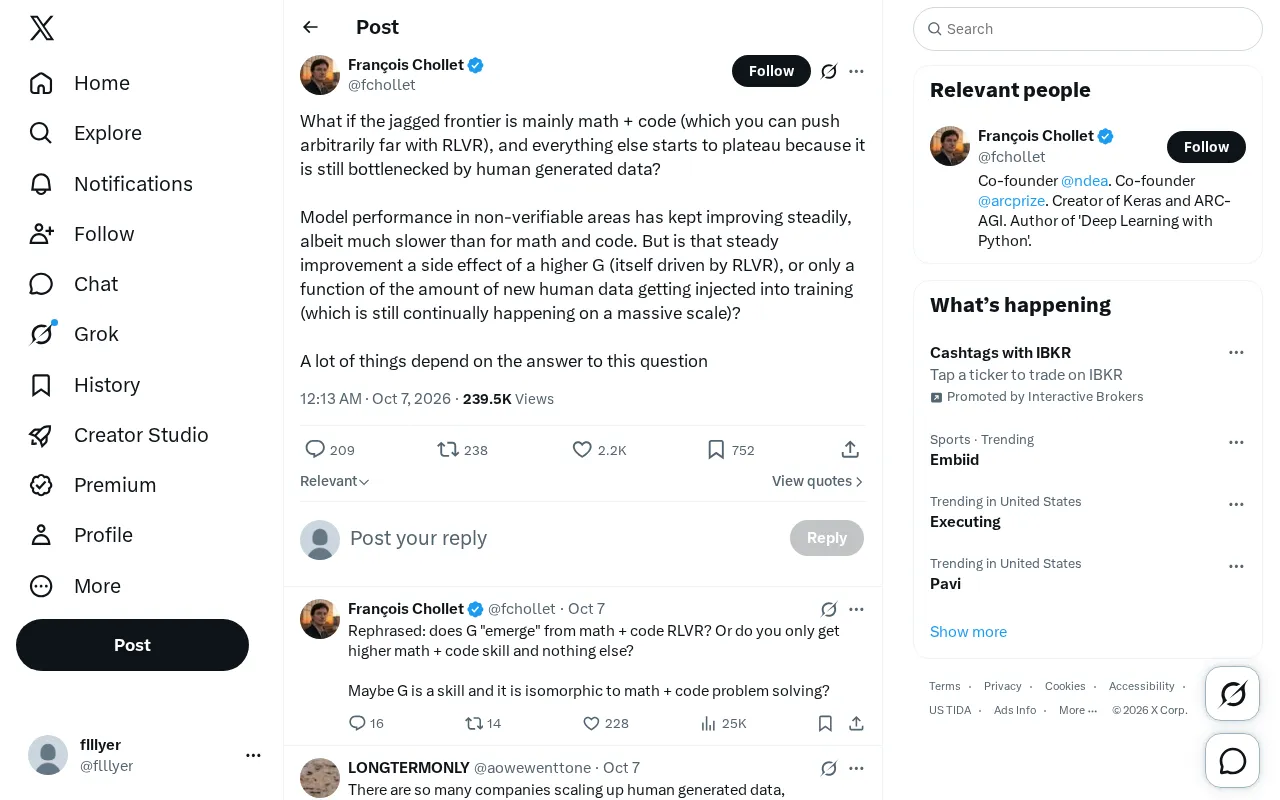
The capabilities of large language models exhibit a striking "jagged frontier" — approaching or surpassing human experts on certain tasks while performing mediocrely on others. A discussion on Twitter sharpened this imbalance into a more pointed question: If the jagged frontier is fundamentally concentrated in math and code — domains that can be pushed upward indefinitely through RLVR (Reinforcement Learning with Verifiable Rewards) — will other capabilities gradually hit a ceiling, still constrained by human-generated data?
This question may seem abstract, but it cuts to the core contradiction of how large models are trained today.
Why Math and Code Can Be "Pushed Indefinitely"
RLVR stands for Reinforcement Learning with Verifiable Rewards, and the key word is "verifiable." Math problems have definitive answers; whether code runs correctly or passes test cases can be automatically judged by a machine. This means models can iterate through massive cycles of self-directed trial and feedback — without human annotation for each step.
In other words, in these domains, reward signals are objective, scalable, and generated at nearly zero cost. Given sufficient compute, models can continuously "compete against themselves" and push their capabilities to ever-higher levels. This is precisely why recent frontier models have made jaw-dropping progress on math competition benchmarks and coding evaluations.
Among the pioneers of RLVR in practice are DeepSeekAd-R1 and OpenAI's o1/o3 model series. During training, these models repeatedly generate solution steps, which are then verified by automated evaluators checking whether the final answer is correct — producing dense reward signals. This paradigm is essentially a language-domain transfer of the AlphaGo approach: just as the outcome of a Go game can be machine-adjudicated, so can the answer to a math problem. Compared to traditional Reinforcement Learning from Human Feedback (RLHF), RLVR does not rely on human raters, has extremely low marginal cost, and can operate at a scale far exceeding RLHF. As a result, model scores on competition math (e.g., AIME, IMO problems) and code generation (e.g., Codeforces problems) have followed a nearly vertical growth curve over the past year.
The Concern About Non-Verifiable Domains
The other side of the picture involves capabilities that are not verifiable — writing quality, commonsense reasoning, value judgment, emotional expression, complex multi-turn dialogue, and more. These tasks have no single correct answer; reward signals are difficult to automate, and they remain heavily dependent on human annotation and human-produced text data.
The original author astutely observes that model performance in these non-verifiable domains has indeed been steadily improving — just far more slowly than in math and code. But the truly critical question is: Where does this steady improvement actually come from?
Two possible explanations emerge:
Explanation 1: Spillover from General Capability
One possibility is that the stronger "general intelligence" (denoted as G in the original post) cultivated through RLVR training in math and code naturally spills over into other domains. In other words, training a model to reason rigorously and decompose complex problems step by step improves foundational capabilities that transfer to softer tasks like writing and conversation. If this is the case, then continuing to push math and code will lift the model's overall capabilities across the board.
This hypothesis has a counterpart in cognitive science — "transfer learning" or "domain-agnostic reasoning ability." The intuition is that rigorous mathematical training strengthens the model's underlying circuits for step-by-step inference and self-contradiction detection in latent space — circuits that activate when handling other tasks as well. Some researchers draw an analogy to Spearman's "g factor" (general intelligence factor) — a domain-universal cognitive foundation. Indirect supporting evidence comes from models like o1/o3, which are trained with reasoning as a core objective and have shown marked capability improvements in non-mathematical areas like medical diagnosis and legal analysis — domains that were not direct targets of their reinforcement learning. However, "how far the spillover extends" remains an open question.
Explanation 2: Continuous Injection of Human Data
The alternative explanation is considerably more pessimistic: progress in non-verifiable domains is simply the result of continuously injecting large volumes of new human data during training. The gains come not from a leap in intelligence itself, but from accumulating more data. If this is the case, once the supply of high-quality human data slows or runs out, capabilities in these domains could genuinely hit a ceiling.
The difficulty of measuring non-verifiable capabilities is itself a deep problem. Tasks like writing quality, emotional resonance, and value judgment lack ground truth. Current mainstream evaluation methods — whether MT-Bench, AlpacaEval, or using another LLM as a judge (LLM-as-Judge) — all carry risks of circular dependency and scoring bias. This means that even when we observe "non-verifiable capabilities steadily improving," it's hard to rule out that this is merely a shift within the evaluation system itself rather than a genuine leap in model capability. Building trustworthy benchmarks for open-ended tasks is one of the most intractable challenges in AI evaluation today.
Why This Question Matters So Much
As the original author notes, "a lot depends on the answer to this question." This is not a purely academic exercise.
If Explanation 1 holds, the trajectory for AI development is relatively optimistic — reinforcement learning in verifiable domains can leverage overall capability growth, significantly reducing the impact of data bottlenecks. Labs can concentrate resources on scalable training methods like RLVR.
If Explanation 2 holds, we face a far more complex situation: math and code will continue to race ahead while capabilities like creative writing, humanistic judgment, and open-ended reasoning may gradually stagnate. Models will become increasingly "lopsided," and rather than narrowing, the jagged frontier gap will widen. This would also mean that high-quality human data becomes unprecedentedly valuable — whoever controls unique data sources controls the key to breaking through the ceiling.
Reality Likely Lies Somewhere in Between
Current evidence is insufficient to reach a definitive conclusion. The continued improvement in non-verifiable capabilities is an objective fact, but its drivers are extremely difficult to disentangle — gains from general capability improvement and from data injection are likely happening simultaneously and intertwined.
The value of this debate lies not in immediately resolving the question, but in reminding the entire industry: don't be dazzled by the impressive scores in math and code and assume all capabilities can be advanced at the same pace. Determining which capabilities can self-scale through algorithms and which remain firmly locked behind data will define the true direction of the next phase of the large model race.
For practitioners and observers following the AI frontier, the question of "exactly where the jagged frontier gets stuck" is one worth continued tracking and verification.
Related articles

Last Week Tonight Exposé: The Dangerous Ties Between Politicians and White Supremacy
Last Week Tonight investigates Georgia Senate candidate Mike Collins and Florida candidate Marshall Rawson, exposing their multiple ties to white supremacists and the Republican Party's silent response.

AI Buzz Weekly: GPT-6.5 Leak, New Claude Model, and MiniMax's Cost-Effectiveness
This week's AI buzz roundup: suspected GPT-6.5 leak, Microsoft configs showing GPT-6.1 Tera, Anthropic's new model that can identify entire classes of bugs, disappointing early Gemini 4 Carbon results, and MiniMax M3.1 Flash beating Claude Opus 5 and GPT-5.6 Sol in benchmarks at extremely low cost.

AI Briefing: Gemini 4 Carbon Released, Ant Open-Sources Ling-3.1
AI Briefing: Google releases Gemini 4 Carbon qubit model, claiming to surpass Opus 5.5 with half-price tokens; Ant open-sources Ling-3.1-1019 for real-task Personal Agents; domestic AI drug discovery succeeds in 18 of 19 projects, hitting all 6 GPCR targets; zero-revenue company valued at $20B raises another $1B; Sichuan convenience store robot sales fail.