Top 10 Fastest-Growing AI Open Source Projects on GitHub This Week
This week's GitHub star growth chart shows AI open source projects packaging professional capabilities into a single instruction.
This article reviews 10 AI open source projects from GitHub weekly star growth data compiled by a Bilibili creator, categorized into reverse engineering, visualization, memory and cost optimization, and vertical scenarios. REA leads with 214K stars in a week; Skills, Diagram Design, and OpenMontage package workflows and content production; Claude MEM adds long-term memory, Free Claude Code accesses free quotas, and AirLLM runs a 2.8T-parameter model on 4GB VRAM; Knowledge Work Plugins, Text to CAD, and OpenSRE cover non-technical roles, manufacturing, and operations. The common trend is rapidly falling professional barriers.
Weekly Star Growth Chart: New Trends in AI Open Source Projects
On GitHub's trending list this week, AI open source projects show a clear divergence: some gained explosive attention in a very short time, while others were rediscovered at specific moments thanks to long-term accumulation. Based on GitHub weekly star growth data compiled by a Bilibili creator, this article breaks down what problem each of these 10 projects solves, why it's popular, and what new capabilities you gain after installing it.
Looking at the composition of the list, there are developer-oriented coding enhancement tools, plugin packs that benefit non-technical roles, and inference solutions that break through constraints in hardware-limited scenarios. Let's break them down one by one.
Reverse Engineering and Code Understanding
REA: Let AI Tear Apart Any App for You
REA (Reverse Engineer Anything) is the fastest-growing project on this week's list, with 269,000 total stars. The repo was created in April, and it gained 214,000 stars this week alone, with over 30,000 new stars in a single day. Its positioning is straightforward: when you see a particularly well-made feature in another app, in the past you needed to understand assembly and use decompilation tools to grind through it line by line. Now you just say to the AI, "Help me figure out how this app's search works, give me the evidence, and then build something similar in my project."
The AI calls reverse engineering tools like Ghidra and IDA and follows the call chain all the way down, attaching evidence to every conclusion. In the official case study, the AI restored a function in an old game that calculates the left and right audio channels into C code, with all 3,200+ test cases matching, and the compiled 63 projects being byte-for-byte identical to the original. This means the barrier to reverse engineering has been dramatically lowered, and feature teardown has gone from an expert skill to a single instruction.
Ghidra and IDA in Reverse Engineering
Ghidra is a disassembly and decompilation framework open-sourced by the US National Security Agency (NSA). It supports multiple processor architectures and can restore binary programs into pseudocode close to C language, making it the mainstream choice among free solutions. IDA Pro is the benchmark for commercial reverse engineering tools, with stronger interactive analysis, debugging, and plugin ecosystem, and has long been used by security researchers for malware analysis and vulnerability discovery. Both can translate machine code into human-readable assembly or high-level language representations, but when facing large applications, manual work is still needed to trace call chains layer by layer and determine data structures. REA's value lies in calling such tools as its "hands," while the large model takes on the reasoning work of "reading code, forming hypotheses, and finding evidence," thereby compressing a reverse engineering process that was originally highly experience-dependent into natural language instructions.
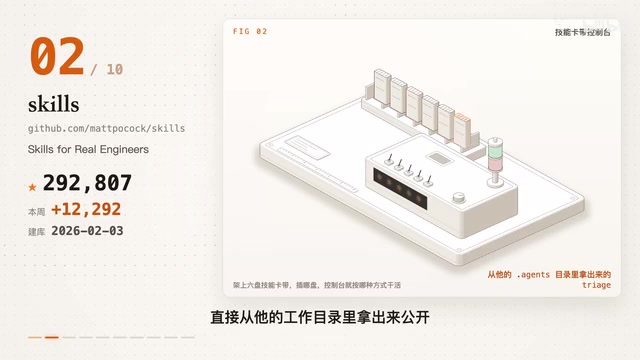
Skills: Skill Packs for Engineered Workflows
The author, Matt Pocock, is a well-known teacher in the TypeScript community. The project has 292,000 total stars and gained over 12,000 this week. He directly published a set of AI skills he actually uses every day when writing code, straight from his working directory.
The most popular one is called "Grill Me," and its approach is the reverse: before the AI starts working, it first questions you—what exactly are you trying to do, where are the boundaries, how should each situation be handled—and only writes after things are clear. Another skill is to first write a failing test that shows red, then change the code to make it green, with feedback at every step. There are also workflows for troubleshooting bugs and skills for regularly doing health checks on code architecture. Each skill is very small and can be freely modified into your own version. With it installed, AI goes from a newcomer who writes code with its head down to an engineer who asks clarifying questions first and verifies step by step.
Visualization and Content Generation
Diagram Design: Teaching AI to Draw Professional Diagrams
When you ask AI to draw an architecture diagram, it usually tosses you a Mermaid box inside a box, cramped and ugly. Diagram Design lays down the rules for 45 types of diagrams, including architecture diagrams, sequence diagrams, four-quadrant charts, flowcharts, and timelines, each with light and dark styles. You just say in plain language, "Draw me an architecture diagram of my application, frontend, backend, database, Redis cache," and the AI picks the diagram type itself, arranges them on a four-quadrant grid, checks for overlap or out-of-bounds elements, and finally gives you an HTML file you can open by double-clicking.
More practically, if you give it a URL, it will learn your website's color scheme and fonts, and every diagram it draws afterward will look like your own brand. The project has 55,800 total stars. The repo was created in mid-April, and it gained 17,000 stars this week.
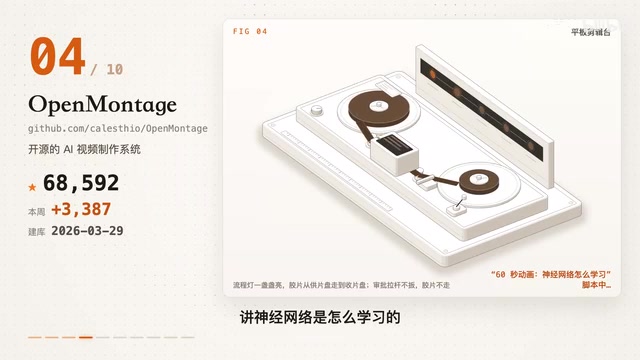
OpenMontage: Generate a Complete Video from One Sentence
OpenMontage is an open source AI video production system with 68,500 total stars and over 3,300 gained this week. It turns the AI coding assistant you already have (Claude Code, Cursor, Codex, etc.) directly into a video studio. You say, "Make me a 60-second animation explaining how neural networks learn," and it researches on its own, generates visuals and voiceover, edits and composites, and finally produces the finished video.
Inside there are a dozen production pipelines, over 100 tools, and more than 700 skill and production experience files. Before starting work, it gives you a quote first; before generating assets, it shows you the storyboard first; only after you nod does it start spending money. In an official short film, "A Lonely Banana and a Kiwi Become Friends," the total cost for 60 seconds was $1.33. You can also throw it a video you like, and it will analyze the rhythm, shots, and style, then make a new piece on a different subject following that approach.
Memory, Cost, and Resource Breakthroughs
Claude MEM: Giving AI Long-Term Memory
Claude MEM is an older project that has existed since August last year, with 101,000 total stars. It gained over 7,000 this month and over 3,000 this week. Anyone who has written code with AI knows that when you start a new conversation, it forgets everything, and the bug you fixed yesterday and the plan you settled on have to be explained all over again.
Claude MEM watches in the background what tools the AI uses and what it changes each time, automatically records it, and then uses AI to compress it into summaries stored in a local database. The next time you start a new conversation, it doesn't stuff everything back in at once; instead, it first queries the index to pick out a few relevant entries, and only fetches details when needed. The official claim is that this saves about 10x in tokens. It can be installed on Claude Code, Codex, Gemini, and OpenCode. Once installed, the AI is like an old colleague who has been following this project all along and remembers where you left off.
Free Claude Code: Try AI Coding Tools at Zero Cost
Claude Code, Codex, and other coding tools are great but expensive. Free Claude Code's approach is to start a proxy on your computer and forward requests sent by these tools to other model providers. It connects to multiple providers, including various free tiers, totaling over 1.3 billion free tokens per month, and can also connect to your local models.
By default it uses models on NVIDIA NIM, with 11 coding tools sharing one model catalog. If one provider goes down, it automatically switches to the next model in your ordered list, and the current conversation doesn't have to restart. You can even send an instruction from your phone via Telegram or Discord to have it write code.
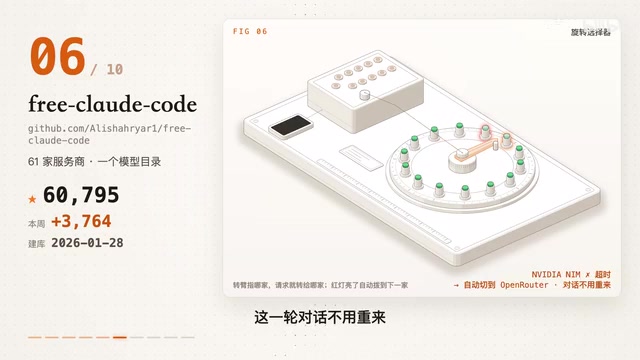
To be clear: it is not an official Anthropic project, and the models running behind it are not Claude itself. But if you want to try this kind of AI coding tool at zero cost first, this is currently the lowest-barrier path. The project has 68,000 total stars and gained over 3,700 this week.
AirLLM: Run Huge Models on Small VRAM
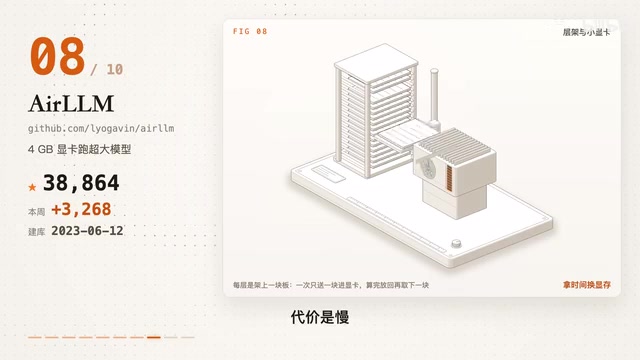
AirLLM is an older project that has existed since 2023, with 38,800 total stars. It suddenly gained over 3,200 this week because it just added support for a batch of new very large models. Normally, running a 70-billion-parameter model requires several large GPUs, because the entire model has to be crammed into VRAM all at once. AirLLM's idea is simple: the model is computed layer by layer anyway, so don't load all of it. The model stays on disk, and when computing a layer, only that layer is moved into VRAM; after computing, it's discarded and the next layer is loaded.
No quantization, no distillation, and no quality reduction. In actual tests, the largest open source model, Kimi K2 (2.8 trillion parameters), used only 3.72 GB of VRAM; last month it also added support for training, and a 125-billion-parameter model can be fine-tuned within 6 GB of VRAM. The cost is speed—it trades time for VRAM. But this means an ordinary computer at hand can let you personally try models that used to run only in data centers.
Why Large Models Must "Fully Reside in VRAM"
In conventional inference, the GPU needs to keep the weights of every layer of the model in VRAM, because matrix multiplication repeatedly reads parameters within an extremely short time, and VRAM bandwidth is far higher than that of hard drives and memory. A 70-billion-parameter model stored in FP16 requires about 140 GB of VRAM, far exceeding a single card's capacity, so multi-GPU parallelism or quantization compression is usually required. AirLLM adopts inter-layer pipelining: it loads only the current computation layer at a time and releases it after computation, reducing VRAM usage from "the entire model" to "a single layer plus activations." The cost is that every layer must move weights from disk, and throughput is limited by PCIe and disk speed, so generation speed is significantly slower. This is a typical engineering tradeoff of trading space for time, suitable for validation, debugging, and low-concurrency scenarios, but not for high-throughput production services.
Vertical Scenarios: From Parts to Operations
Knowledge Work Plugins: AI Plugins for Non-Technical Roles
The previous few are all for people who write code. This one is official from Anthropic, for people who don't write code—sales, legal, finance, marketing, customer service, product managers, data people, and biology researchers. One plugin per role, 11 in total. Each plugin packages the professional knowledge, common workflows, and slash commands for that role, and also connects to commonly used company tools such as Slack, Notion, and Snowflake.
With the sales plugin installed, one command helps you prepare what you need for a client call; with the legal plugin installed, it can first go through contracts and NDAs for you. The entire plugin is just a bunch of Markdown and JSON files, with no code. Write your company's terminology and processes into it, and it becomes your company's own version. The project has 29,800 total stars and gained over 2,600 this week.
Text to CAD: Generate Machinable Parts from One Sentence
In the past, making a 3D part required opening modeling software, drawing sketches, extruding, chamfering, and building step by step. Now you tell the AI, "Make me a bracket for mounting a Raspberry Pi, with four M2.5 screw holes, 2 mm thick," and it generates the 3D model locally and exports standard formats such as STEP, STL, and 3MF. It also performs manufacturability checks to see whether the part can actually be machined, then produces an engineering drawing with dimensions, and finally can connect directly to 3D printing, sheet metal, and CNC machining services to place an order and make the physical object. It can be installed on Claude Code, Codex, Cursor, and Gemini. The project has 27,000 total stars, nearly 2,000 this week.
Differences Between STEP, STL, and 3MF
STEP is an exchange standard in the CAD field. It stores precise boundary representation (B-rep) geometry and design history semantics, and can be further edited by software such as SolidWorks and Fusion 360, making it suitable for engineering and manufacturing. STL records only triangular facets, losing surface precision and feature information. It is mainly used for 3D printing slicing; the file is simple but cannot be parametrically modified. 3MF is a newer printing format that, beyond meshes, can also carry metadata such as materials, colors, units, and print settings. Text to CAD exports all three formats at the same time, meaning the generated model can both go back into CAD tools for further modification and be sent directly into slicing software or machining services, covering different handoff points from design to manufacturing.
OpenSRE: Let AI Take the Night Shift for You
SRE is the engineer responsible for the stability of online services. When a service has a problem in the middle of the night, the evidence is scattered across logs, monitoring metrics, call traces, recent release records, and a pile of chat messages, and you have to go through them one by one. OpenSRE is an open source toolkit that lets you build your own AI SRE. When an alert comes in, it automatically pulls relevant logs, metrics, traces, and recent deployments, first masks sensitive identifiers before handing them to the model, and the model queries back and forth among the 60+ tools you've connected, forms hypotheses, verifies them, and finally gives you a conclusion with evidence and suggestions on how to fix it. If you agree, it can even take action to fix it directly, then send a summary to Slack.
You can also ask it directly from the command line, "Why has the checkout API gotten slower?" The project has 11,900 total stars and is currently still in public beta. What they want to build is a training ground for AI operations, turning thousands of real online failures into tests for AI to practice in.
SRE and the Three Pillars of Observability
SRE (Site Reliability Engineering) originates from Google's operations methodology. Its core is to manage service stability with software engineering methods, including defining SLOs, controlling error budgets, and conducting postmortems. The "three pillars of observability" relied on during troubleshooting are logs (discrete event records), metrics (values aggregated over time, such as latency and error rate), and distributed tracing (the call path of a single request across services). The reason OpenSRE pulls all three types of data at the same time is that a single signal is often insufficient to locate the root cause: metrics tell you "it got slower," traces point out "which service is slow," and only logs explain "why it's slow." Combined with recent release records and chat context, the model can form verifiable hypotheses instead of giving suggestions based on guesswork.
What This Week's List Shows
These 10 projects cover reverse engineering, code generation, diagram creation, video production, memory management, cost optimization, VRAM breakthroughs, role-based plugins, CAD generation, and operations automation. What they have in common is that each one gives AI a specific new capability, and the barrier to entry is dropping rapidly. From running a 2.8-trillion-parameter model on 4 GB of VRAM to generating a machinable part from one sentence, things that used to require professional toolchains and years of experience are being reorganized into one instruction plus a set of skill packs. For people who know how to use AI, the tools available are becoming more numerous and more specific.
One-line Summary
This week's GitHub star growth chart shows AI open source projects packaging professional capabilities into a single instruction.
Paragraph Summary
This article reviews 10 AI open source projects from GitHub weekly star growth data compiled by a Bilibili creator, breaking them down into four categories: reverse engineering, visualization generation, memory and cost optimization, and vertical scenarios. REA tops the list with 214,000 stars gained in a week, letting AI call Ghidra and IDA to complete reverse engineering with evidence; Skills, Diagram Design, and OpenMontage package engineering workflows and content production into skill packs and pipelines; Claude MEM provides long-term memory, Free Claude Code uses a proxy to access free quotas, and AirLLM uses inter-layer loading to run a 2.8-trillion-parameter model on 4 GB of VRAM; Knowledge Work Plugins, Text to CAD, and OpenSRE cover non-technical roles, part manufacturing, and operations troubleshooting respectively. The common trend is a rapid drop in professional barriers.
Related articles

Encoders Understand Bengali Compound Verbs, But LLMs Only Translate Literally
BengaliCV-Probe benchmark tests 26 models: encoders distinguish Bengali compound verb meanings with up to 93% accuracy, but LLMs rarely use this knowledge. Translation systems literalize 15%-55%, and a small model beats Qwen2.5-7B on correct collocations.
HKU Open-Sources Supervisor-Skills: Packing a Decade of PhD Advising Experience into AI
HKUST's open-source Supervisor-Skills distills a decade of PhD advising into theory guides plus 12 skills covering the full paper workflow, installable by AI agents.

DeepFinance Benchmark: Can AI Handle Due Diligence for Multi-Billion Private Equity Firms?
DeepFinance benchmark evaluates AI on 21 end-to-end PE and IB tasks averaging 27.1 human hours. Best config GPT-6 Astra satisfies only 57.6% of criteria, often computing right answers from wrong inputs—exposing gaps in financial due diligence judgment.