vLLM: Building the Most Accessible and Efficient LLM Inference Engine

vLLM core maintainer Simon Mo stars in the PyTorch Conference promo, spotlighting vLLM's role as the leading open-source LLM inference engine.
vLLM core maintainer Simon Mo appeared in the PyTorch Conference promotional video, putting this open-source inference engine back in the community spotlight. Powered by PagedAttention — which applies OS-style virtual memory paging to KV cache management — vLLM delivers dramatically higher GPU memory efficiency and throughput compared to traditional implementations, directly lowering the hardware cost of production LLM deployment. Combined with an OpenAI-compatible API, a clean Python interface, and out-of-the-box model support, vLLM advances both efficiency and accessibility simultaneously. Amid strong competition from TensorRT-LLM, SGLang, TGI, and others, vLLM maintains its lead through an active open-source community and rapid iteration. The PyTorch Conference runs October 20–21 in San Jose.
vLLM Featured in PyTorch Conference Promo Video
Recently, vLLM core maintainer and Inferact CEO Simon Mo (@simon_mo_) appeared in the latest promotional video for the PyTorch Conference. As one of the most closely watched projects in the open-source inference engine space, vLLM is once again at the center of community attention. In the video, Simon Mo clearly articulates vLLM's core mission: to build the most accessible and most efficient inference engine.
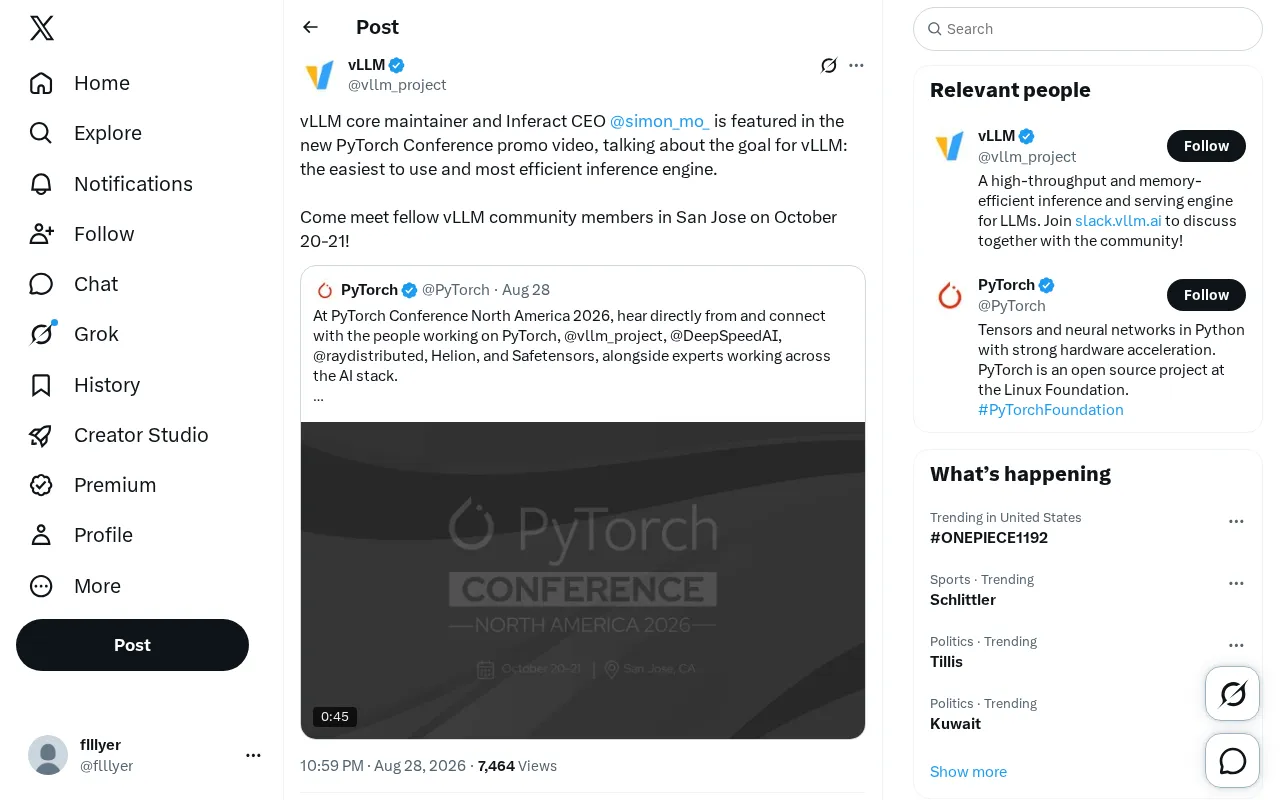
This isn't just an empty tagline. In an era where large model deployment costs remain stubbornly high, the efficiency of an inference engine directly determines whether organizations can deliver model capabilities to users at an acceptable cost — and that's precisely where vLLM has found its value.
Why vLLM Matters
PagedAttention: A Core Technical Innovation
vLLM originally stood out in the industry through its innovative PagedAttention mechanism. Inspired by virtual memory paging in operating systems, this technique manages the KV cache of the attention mechanism in discrete blocks, dramatically reducing GPU memory fragmentation and waste. Compared to traditional implementations, vLLM achieves several-fold improvements in throughput while keeping inference latency low.
For large-scale online services, this means the same GPU resources can serve far more concurrent requests — translating directly into significant cost savings. This is the fundamental reason vLLM has so quickly earned the trust of both the open-source community and enterprise users.
Pursuing Both Usability and Efficiency
The "most accessible" aspect Simon Mo emphasizes deserves equal attention. In the inference engine space, it's not uncommon to find solutions that are powerful but difficult to configure. vLLM dramatically lowers the barrier to entry for developers through several design choices:
- OpenAI-compatible API, minimizing migration costs
- Clean Python interface — a few lines of code are all it takes to launch an inference service
- Out-of-the-box support for popular models, covering widely used architectures like LLaMA and Mistral
This dual pursuit of "accessibility" and "efficiency" reflects a genuinely challenging product philosophy — making it easy for beginners to quickly stand up a working inference service, while giving experts the tools to squeeze every last bit of performance from their hardware. vLLM's ability to continuously balance these two demands is key to maintaining its competitive edge.
vLLM's Place in the PyTorch Ecosystem
The fact that vLLM was featured in the PyTorch Conference promo video speaks for itself — it signals the project's importance within the deep learning ecosystem. Built on top of PyTorch, vLLM is deeply integrated with the broader open-source AI stack, serving as a critical link between model training and production deployment.
The PyTorch Conference is scheduled for October 20–21 in San Jose. Simon Mo extended an open invitation for community members to attend and connect in person. For developers focused on LLM inference optimization, this is a rare opportunity to learn about the latest vLLM developments and engage directly with core maintainers.
The Competitive Landscape of LLM Inference Engines
The Rise of Open-Source Inference Frameworks
In recent years, competition in the inference engine space has intensified considerably. Beyond vLLM, solutions like TensorRT-LLM, SGLang, and TGI are all vying for market share. As a leading open-source project, vLLM has built a significant advantage through its active community ecosystem and rapid iteration cadence.
Simon Mo's dual role as both a core vLLM maintainer and CEO of Inferact reflects a clear and emerging trend: high-quality open-source infrastructure is increasingly becoming the foundation for commercial products. Open-source projects build technical influence through community contributions, while commercial companies build enterprise-grade services and support around these projects — creating a healthy, self-reinforcing cycle.
What This Means for AI Developers and Enterprises
For AI developers and organizations broadly, the kind of "efficient inference" that vLLM represents is becoming increasingly critical. As large model applications move from experimentation into production at scale, inference cost and response latency have become core factors that determine whether a product succeeds or fails. Choosing a mature, efficient, and accessible inference engine can significantly shorten the path from model to product.
Conclusion
vLLM's appearance in the PyTorch Conference promotional video is yet another strong affirmation of its technical value and community influence. The goal of being "the most accessible and most efficient inference engine" may sound straightforward, but achieving it demands continuous innovation across architecture, engineering optimization, and developer experience. As the PyTorch Conference approaches, the vLLM community is poised to grow even more active — and we look forward to seeing what new breakthroughs this open-source project brings to the world of LLM inference optimization.
Related articles

DeepSeek Open-Sources DeepInfer: What Is an Inference Framework Actually For?
DeepSeek open-sources its inference framework DeepInfer under Apache 2.0, supporting DeepSeek V4.1 Flash offline inference. This article explains its request scheduling, FlashMLA/DeepGEMM compute optimization, DSPark speculative verification acceleration, and what it means for developers and ordinary users.

Open-Source AI Learning Agent: A Full Workflow Experience from Topology Graphs to Exam Generation
Explore an open-source AI learning agent: built on DeepSeek API, it constructs knowledge systems via topology graphs, with automatic document generation, notes, super documents, and exams. Learn about its Agent workflow and design highlights.

DeepSeek Whale Girl Open-Source MV Meme: AI Industry Coded Slang About Pivoting to Closed Source
Bilibili's DeepSeek Whale Girl rap MV uses fictional memes to tease the AI open-source vs. closed-source debate, with lyrics full of industry slang. This article explains the meme culture, the Whale Girl symbol, and the open/closed tension.