#vLLM
54 related articles

vLLM Singapore Meetup: Focus on High-Throughput Inference and Agent Infrastructure
vLLM Singapore Meetup on November 13 at SQ Collective features engineers from inferact, NVIDIA, Alibaba Cloud, and vLLM-Omni discussing high-throughput prefill, RL, Blackwell, Vera Rubin, Agent infrastructure, and interactive world models.

vLLM Delivers Day-0 Support for MiniMax M3.1 Flash: Engineering Optimizations for Automation and Visual Reasoning
vLLM announces Day-0 support for MiniMax M3.1 Flash, a model built for multi-step automation, real-codebase engineering, and visual reasoning, with native NVFP4 KV cache, NVFP4 MoE weights, and DSpark speculative decoding.
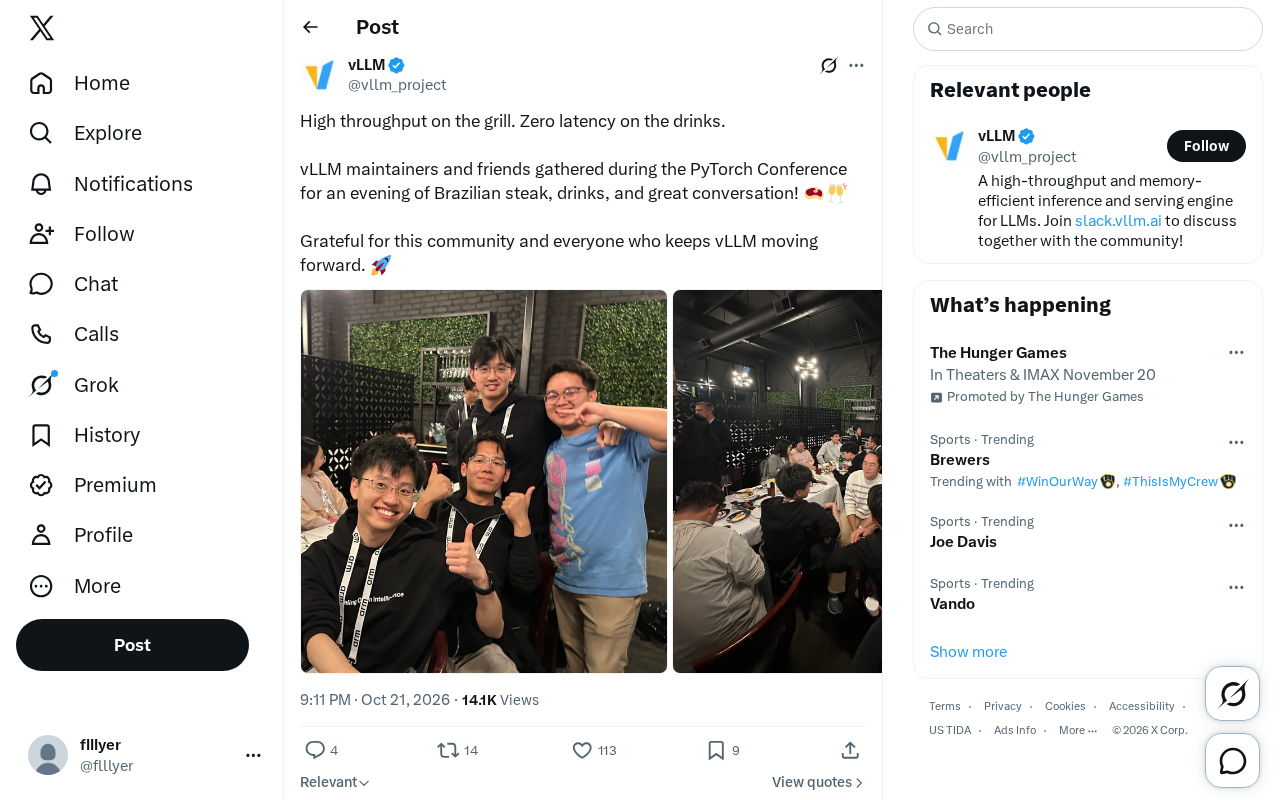
vLLM Maintainers Dine at PyTorch Conference: High-Throughput BBQ and Zero-Latency Toasts
vLLM maintainers held a dinner during the PyTorch Conference, using technical puns about high-throughput BBQ and zero-latency drinks to thank the community for pushing the project forward. This article covers the gathering's background and vLLM's community culture.

MiniMax M3.1 Flash Goes to Production: A Milestone for the Open-Source Inference Ecosystem
MiniMax M3.1 Flash is running at production scale with SLA-backed inference from @inferact, and engineering improvements are flowing back upstream to vLLM. Here's what it means for the open-source inference ecosystem and developer choices.

vLLM Catches Up to DeepSeek's In-House Engine DeepInfer: The Technical Dynamics Behind Decoding Performance
vLLM matches DeepSeek's in-house DeepInfer engine under the DeepSeek-V4.1-Flash decoding config, using only DEP32 against EP64DP64. This article analyzes the technical background, practical implications for developers, and how open-source collaboration is closing the inference engine gap.
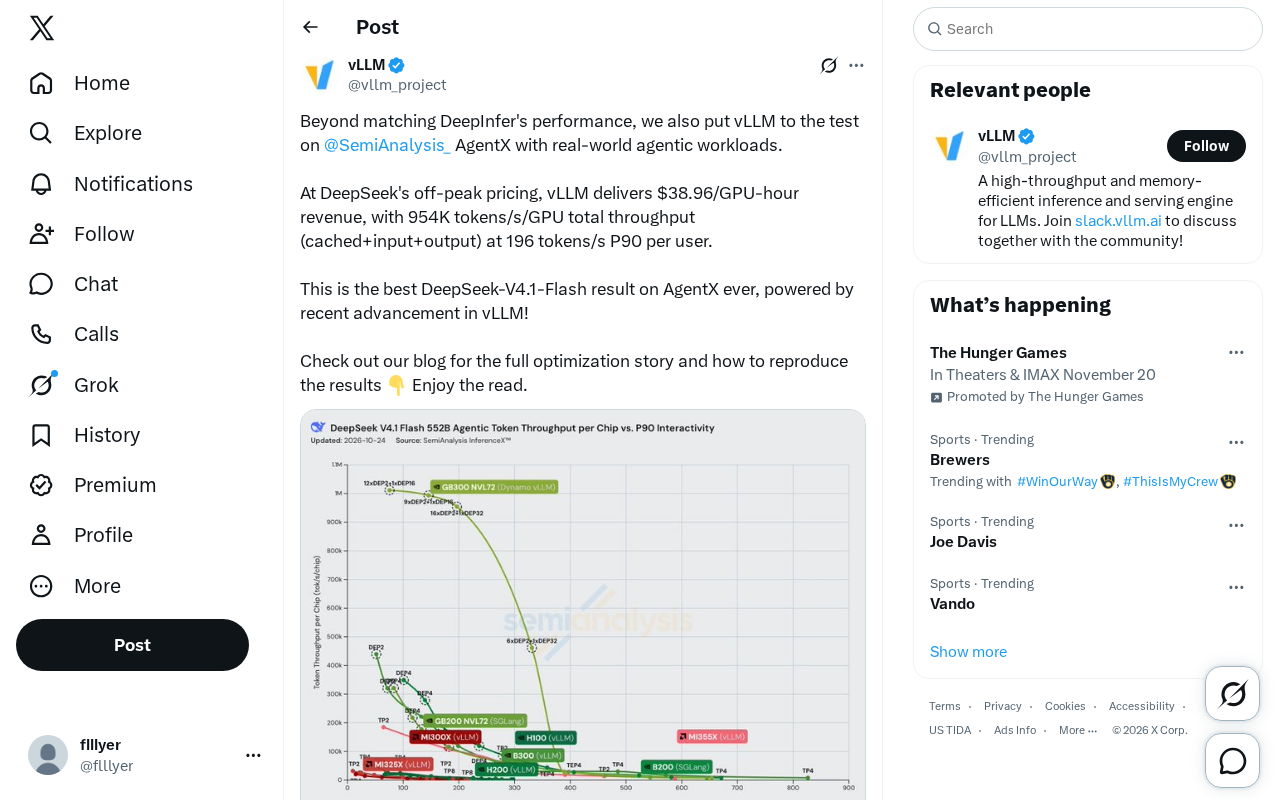
vLLM Achieves Best Result on AgentX: Breaking DeepSeek Inference Record
vLLM sets the best DeepSeek-V4.1-Flash result on AgentX with real agentic workloads, achieving 954K tokens/s/GPU throughput and $38.96/GPU-hour revenue, matching DeepInfer.

vLLM v0.33.0rc1 Fixes Stale NVFP4 Decode Test Selector on DGX Spark
vLLM v0.33.0rc1 fixes a stale NVFP4 decode test selector on DGX Spark via PR #64107, highlighting CI test matrix growth, backport strategy, and new-hardware risks.
vLLM v0.33.0rc0 Released: CUDA Profiling Fix and MRV2 Optimization
vLLM releases v0.33.0rc0, fixing MRV2 skipping adaptive verification cost profiling in CUDA. This article explains the bugfix, its impact on inference deployment, and upgrade notes.
DeepInfer Open-Sourced: A Deep Dive into DeepSig's Production-Grade Inference Engine
DeepSig open-sources DeepInfer, a production inference engine built on vLLM, compatible with NVIDIA SM10 and Ascend 950 NPU, handling 155 trillion tokens/day with 96% cache hit rate. We analyze its custom kernels, scheduling, and offline limitations.

Qwen4-27B Accidentally Exposed: vLLM PR Leaks Clues About New Model
Reddit community discovers vLLM XPU repository PR #22 potentially leaking clues about Qwen4-27B, involving KV cache specs and Intel platform adaptation; this article reviews PR information, community reaction, and reference value for developers.
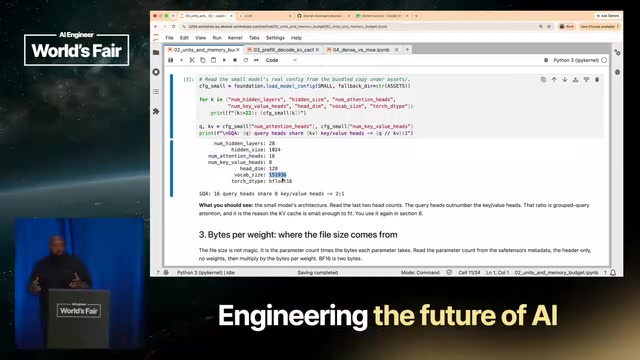
Build Your Own Inference Stack: A Practical Guide to Running Production-Grade AI Agents on Dedicated GPUs
Based on an Akamai workshop recording, a detailed guide to building a production-grade AI agent inference stack on dedicated GPUs: vLLM deployment, VRAM budgeting, real-world FP8 quantization gains, speculative decoding pitfalls, and concurrency tuning.
vLLM Introduces Push-Based KV Transfer: 3x TTFT Improvement in Disaggregated Inference
vLLM introduces a push-based NIXL connector to optimize KV cache transfer in disaggregated inference. On Amazon EC2 P5en with AWS EFA, TTFT improves up to 3x and TPOT by 30%.

vLLM Bidirectional KV Transfer Optimizes Multi-Turn Agent TTFT
vLLM introduces bidirectional KV cache transfer, letting prefill and decode nodes reuse context across rounds. TTFT improves up to 1.6x for Qwen3-32B and 3.3x for GLM-5-FP8 in multi-turn agents; this article explains the mechanism and measured data.

vLLM P/D Disaggregation: The Calculation Rule Where KV Transfer Cost Determines Benefit
Is vLLM prefill/decode disaggregation worth it? We break down KV cache transfer bytes and bandwidth ratios, showing overhead for 70B models from 100GbE to 400Gb links, with a p99 ITL measurement script and a decision table.
One Parameter Fits 128K Context on a 4090: FP8 KV Cache Quantization in Practice
A deep dive into vLLM's FP8 KV cache quantization: one parameter fits a 7B model's 64K context on a 24GB 4090, halving VRAM and cutting cost to a quarter, with 128K VRAM math and calibration tips.

GPUStack vLLM Production Deployment: KV Cache Pinning and OOM Avoidance in Practice
Real-world ops lessons from a four-node mixed GPU cluster: pinning KV Cache in GPUStack + vLLM production deployments, avoiding 70B model OOM, and diagnosing TTFT and RSS decay.

vLLM temperature=0 Is Not Deterministic: 23 of 200 Evaluation Answers Flip
vLLM temperature=0 does not guarantee determinism. Continuous batching changes GPU kernel reduction order, and floating-point addition is not associative—23 of 200 evaluation answers flipped. This article analyzes the root cause and offers reproducible evaluation solutions: serialization, semantic scoring, and logprob gap monitoring.
vLLM Releases v0.32.1rc0: Adds Weight-Transfer HTTP Protocol Documentation for Trainers
vLLM releases v0.32.1rc0 candidate, adding weight-transfer HTTP protocol documentation for trainers. We explain its role in RL weight sync, version attributes, and upgrade advice.
20-Minute Hands-On Guide: Deploying DeepSeek-R1 Locally with vLLM
Step-by-step tutorial: deploy DeepSeek-R1 distilled locally with vLLM on Ubuntu, covering Miniconda setup, NVIDIA drivers, CUDA 12.4, PyTorch and vLLM install.

Muse Spark Open Lands on vLLM: A Big Story for a Small Model
Muse Spark Open lands on the vLLM inference engine, combining multimodal understanding, 1M context, agentic planning, DSpark, and cross-platform support. This article examines its technical features, the significance of vLLM integration, and the practical impact on developers.