#vLLM
54 related articles

vLLM v0.30.0 Released: Fixes DeepGEMM Build Issue on CUDA 12.9
vLLM v0.30.0 is released, fixing the DeepGEMM release build failure on CUDA 12.9 (PR #57554). Learn about the fix, its impact, and upgrade recommendations for LLM inference deployments.

vLLM Conference Wraps Up: The Explosive Energy of the Open-Source Inference Community
The vLLM Conference drew standing-room-only crowds, with sessions lining up out the door. All recordings are now public. See why vLLM is the top open-source LLM inference framework.

vLLM v0.30.0rc2 Released: Fixes NIXL Notification Request Handling
vLLM v0.30.0rc2 fixes a bug in the NIXL transport layer that caused notification-only requests to trigger unnecessary receive reports, improving distributed inference stability.

vLLM Deployment of Kimi K3 Achieves 2.2–2.8x Throughput Gain: A Performance Optimization Breakdown
Kimi K3 on vLLM achieves 2.2–2.8x throughput gains on B300 benchmarks over v0.27.1, driven by optimizations in scheduling, KDA state handling, and MoE kernels.

vLLM v0.30.0rc1 Released: Isolates FlashInfer BF16 Autotuning Logic
vLLM v0.30.0rc1 release candidate fixes FlashInfer BF16 autotuning isolation (PR #57285). Learn the technical background and its impact on inference deployment.

vLLM Integrates Chord Kernel: Up to 2.15x Inference Speedup for Kimi K2.x
vLLM's Humming backend now supports Novita Labs' open-source Chord W4A16 MoE kernels, optimized for Kimi K2.x. 1.33x on H200 TP8, up to 2.15x on B300 EP8 decoding. Indexed path available now.

vLLM Releases proto-v0.3.0: Another Iteration of the High-Performance Inference Framework
vLLM releases proto-v0.3.0, independently versioning its protocol submodule with SSH signature verification — strengthening distributed inference infrastructure and supply chain security.

vLLM Releases proto-v0.2.0: Internal Protocol Module Update
vLLM releases proto-v0.2.0 (vllm-proto 0.2.0), signed with a verified signature and validated through PR #56538 CI. A look at the engineering significance of component-level versioning and release security.
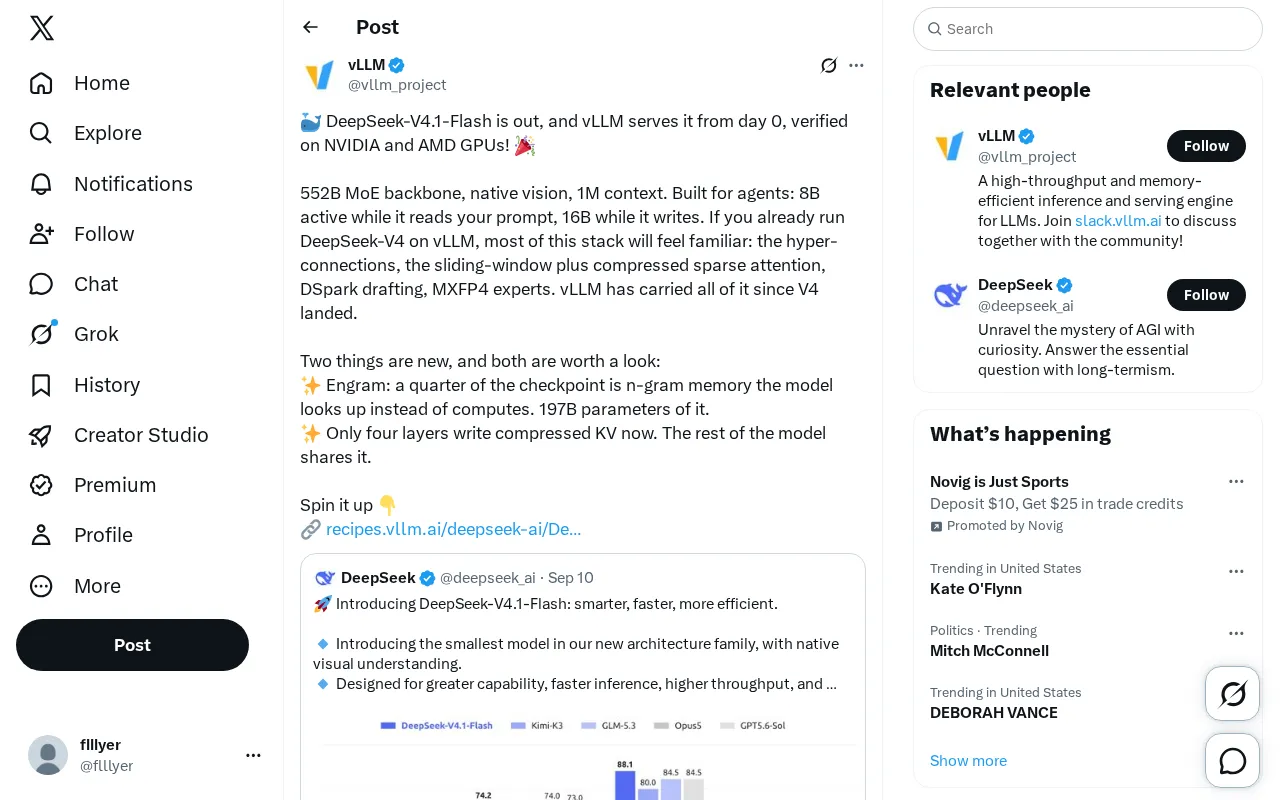
DeepSeek-V4.1-Flash Released: Breaking Down the 552B MoE Architecture and Engram Memory
DeepSeek-V4.1-Flash launches with a 552B MoE backbone, 1M-token context, and native vision. Deep dive into Engram memory and compressed KV sharing, with day-0 vLLM support on NVIDIA and AMD.

vLLM Hackathon Bounty Goes Live: A Real-World Deployment Showdown for Open-Source Models Under 33B
NVIDIA and Red Hat co-sponsor a 'Best Use of vLLM' bounty focused on real-world deployment of open-source models under 33B. A breakdown of the signals and what it means for developers.

vLLM Hybrid HiSparse: Sparse MLA Breaks the Memory Bottleneck for Long-Context Inference
vLLM's Hybrid HiSparse combines Sparse MLA with tiered memory scheduling to boost long-context concurrency 3–4× without extra hardware. Coming in vLLM v0.30.

vLLM v0.29.0 Released: Model Runner V2 Becomes the Default Engine, Inference Performance Gets a Major Boost
vLLM v0.29.0 is out with Model Runner V2 as the new default engine. Key updates include Kimi/DeepSeek optimizations, Mamba prefix caching, speculative decoding observability, and P2P RL weight sync.

After Day-0 Support: How the Community Achieved 3–4x Inference Speedup for MiniMax M3
AMD and EmbeddedLLM detail how they achieved 3–4x throughput gains for MiniMax M3 on Instinct MI355X using vLLM, with a "follow the bottleneck" optimization approach.
 Tutorials
vLLM and SGLang Local Deployment Tutorial: A Practical Guide to 3-8x Performance Gains
Complete guide to deploying vLLM and SGLang locally. Compare performance vs LM Studio, deploy in 3 steps with Docker + AI assistant. Covers SGLang vs vLLM selection, 5090 VRAM optimization, and Cherry Studio integration.