#vLLM
54 related articles
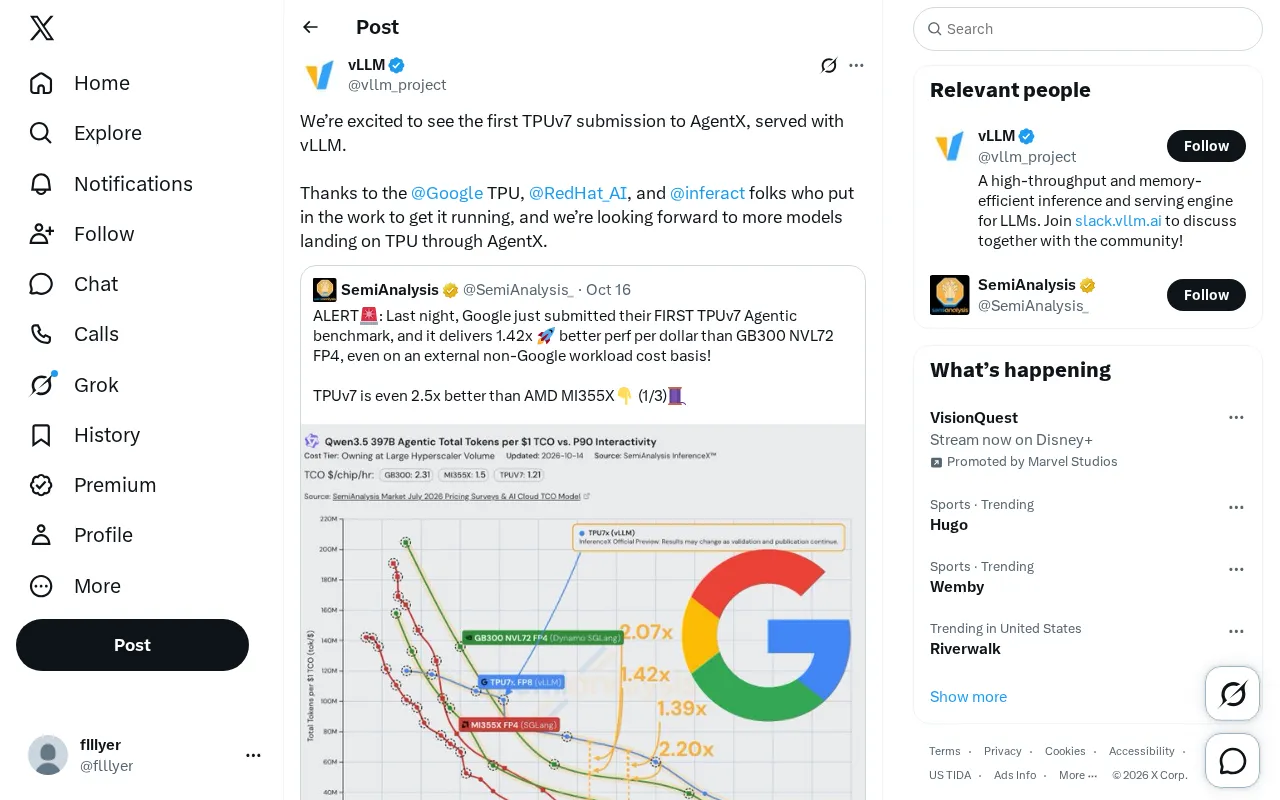
First TPUv7 Submission to AgentX: vLLM Helps Google's TPU Ecosystem Score Another Win
AgentX receives its first TPUv7-based model submission deployed via vLLM, a three-way collaboration between Google TPU, Red Hat AI, and inferact. We break down what it means for vLLM and TPU ecosystem compatibility.
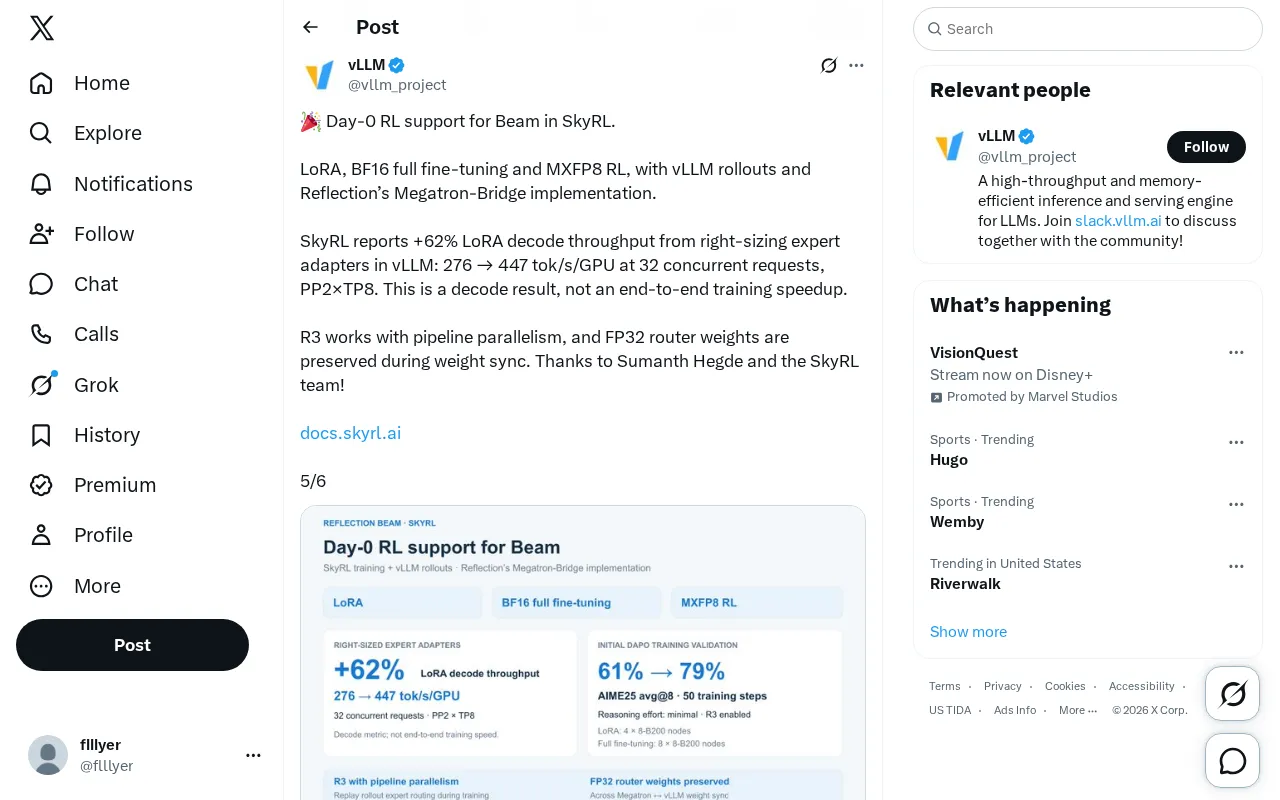
SkyRL Delivers Day-0 RL Support for Beam, Boosting LoRA Decode Throughput by 62%
SkyRL announces Day-0 reinforcement learning support for Reflection's Beam model, covering LoRA, BF16 full fine-tuning, and MXFP8 RL, with vLLM rollout and Megatron-Bridge, boosting LoRA decode throughput by 62% to 447 tok/s/GPU.

vLLM Releases v0.32.0rc2: DeepSeek-V4.1-Flash Evaluation Pinned to FP8-Engram Revision
vLLM releases v0.32.0rc2, with a CI change pinning DeepSeek-V4.1-Flash-NVFP4 evaluation to the FP8-Engram revision, reflecting the inference framework's focus on reproducible multi-precision evaluation.
proto-v0.5.0 Released: Reading the GitHub Release Tag
Developer BugenZhao releases the signed and verified proto-v0.5.0 (vllm-proto 0.5.0) tag on GitHub. This article covers signature verification, engineering significance, and upgrade recommendations.

vLLM v0.31.1rc0 Released: Exposing Cached Prompt Token Metrics by Cache Tier
vLLM v0.31.1rc0 adds per-cache-tier cached prompt token metrics (PR #56318), enabling finer observability for LLM inference cost optimization and performance monitoring.
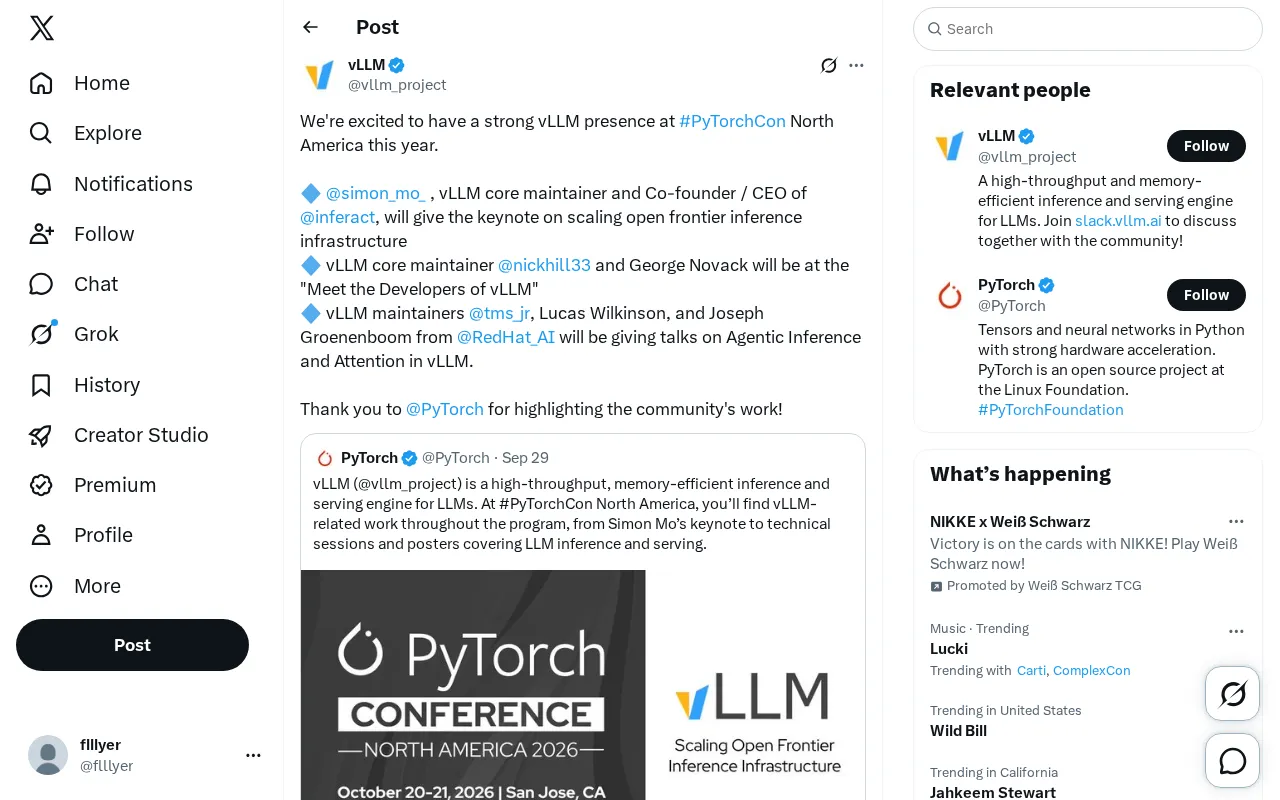
vLLM Takes the Stage at PyTorchCon: A Collective Voice for Open-Source Inference Infrastructure
vLLM core maintainers took the stage at PyTorchCon with a keynote, developer meetup, and sessions on agentic inference and attention — signaling open-source inference infrastructure's rising role in AI.

vLLM Semantic Router Releases Decision 2.0: Answer 64 Questions Per Request in a Single Inference Pass
vLLM Semantic Router releases Decision 2.0 with open models from 0.6B to 27B, answering 64 request questions in one forward pass under Apache-2.0 license.
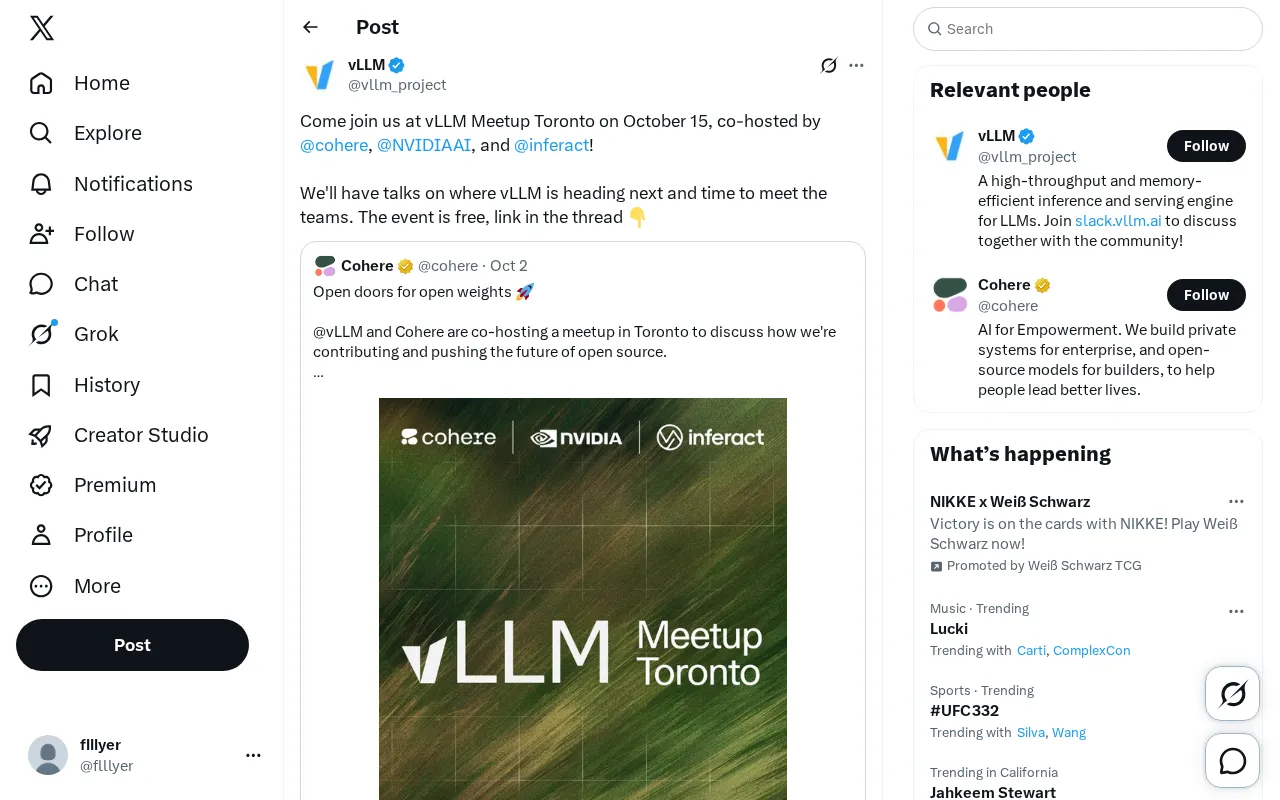
vLLM Toronto Meetup Announced: Co-hosted by Cohere and NVIDIA
vLLM announces a free in-person meetup in Toronto on October 15, co-hosted by Cohere, NVIDIA AI, and Inferact, focusing on vLLM's future roadmap and team networking.
vLLM Releases v0.31.0: Adds Upper Bound Constraint for Transformers Version
vLLM v0.31.0 adds an upper bound on the Transformers library dependency, improving compatibility and deployment stability for LLM inference environments.

vLLM v0.31.0rc5 Released: Adding an Upper Version Bound for Transformers
vLLM v0.31.0rc5 adds an upper version bound for the transformers library (PR #59614), improving dependency stability and predictability for production inference deployments.

Building a High-Performance, Portable vLLM Linear Backend with Helion
Explore how integrating the Helion GPU kernel DSL into vLLM's linear backend enables a single universal kernel with autotuning to boost LLM inference performance and portability.
Getting Started with Local LLM Deployment: Ollama vs. vLLM for Deploying Qwen3
A beginner's guide to local LLM deployment: comparing Ollama and vLLM, covering VRAM trade-offs, high concurrency, and deploying the qwen3-0.6B model with vLLM.

vLLM v0.31.0rc4 Released: Fix for MTP Acceptance Collapse Under FULL CUDA Graph Mode
vLLM v0.31.0rc4 is out, fixing MTP multi-token prediction acceptance collapse under FULL CUDA graph mode. Learn about the technical background and upgrade tips.
vLLM v0.31.0rc3 Released: Model Runner V2 Introduces Randomized Dummy Inputs
vLLM v0.31.0rc3 introduces randomized dummy inputs for Model Runner V2, improving GPU memory profiling and inference warm-up accuracy. Release candidate overview.
vLLM Releases proto-v0.4.0: Signature Verification and Protocol Layer Upgrade Explained
vLLM releases proto-v0.4.0, a standalone update to its vllm-proto component with verified SSH signature. Learn what this means for distributed inference and supply chain security.

vLLM Releases v0.31.0rc2 Preview: Mamba Sparse Sampling Fix
vLLM v0.31.0rc2 release candidate fixes a critical Mamba SSM bug where prefill checkpoints were dropped under sparse sampling, ensuring correct inference results.

vLLM v0.30.0 Released: Major Upgrades to Hybrid Attention and Speculative Decoding
vLLM v0.30.0 is out with hybrid attention hot-path optimizations, HiSparse hierarchical sparse decoding, Model Runner V2 speculative decoding, content watermarking, Fast Start, and new model support.
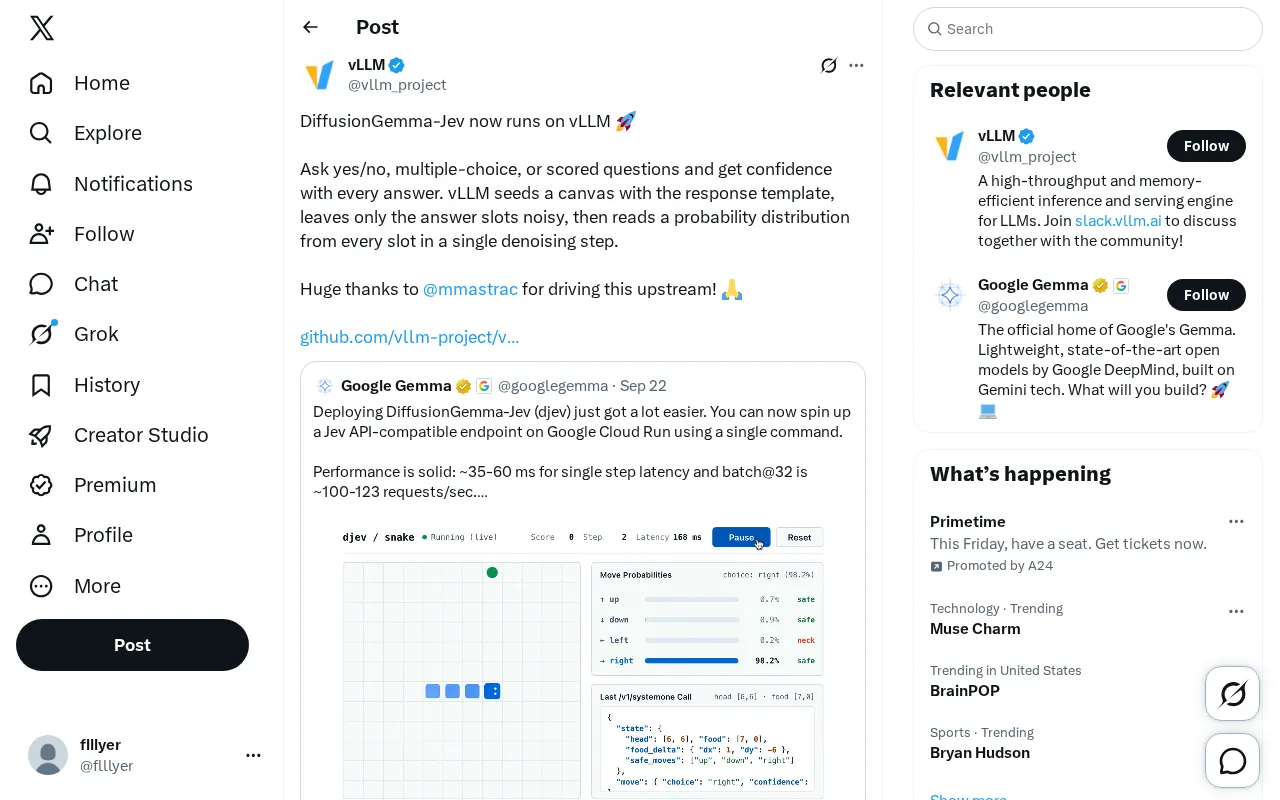
DiffusionGemma-Jev Joins vLLM: Every Answer Now Comes with a Confidence Score
DiffusionGemma-Jev now runs on vLLM, outputting confidence scores for yes/no, multiple-choice, and scored questions via single-step denoising across answer slots.

Local LLM Broke Your Config? Let's Talk About the Real Challenges of vLLM Operations
A Reddit meme exposes the real pain of local LLM ops: why letting models auto-modify vLLM configs is risky. We break down silent CUDA failures and offer practical tips for safe inference management.
How Shopify Built a Continual Learning Loop with PyTorch and vLLM — Cutting Costs by 96%
Shopify built a continual learning loop on PyTorch and vLLM, compressing daily production failures into model weights—surpassing frontier quality while cutting serving costs 96%.