vLLM v0.29.0rc2 Released: Deep Dive into the Multimodal Shared Memory Cache Fix

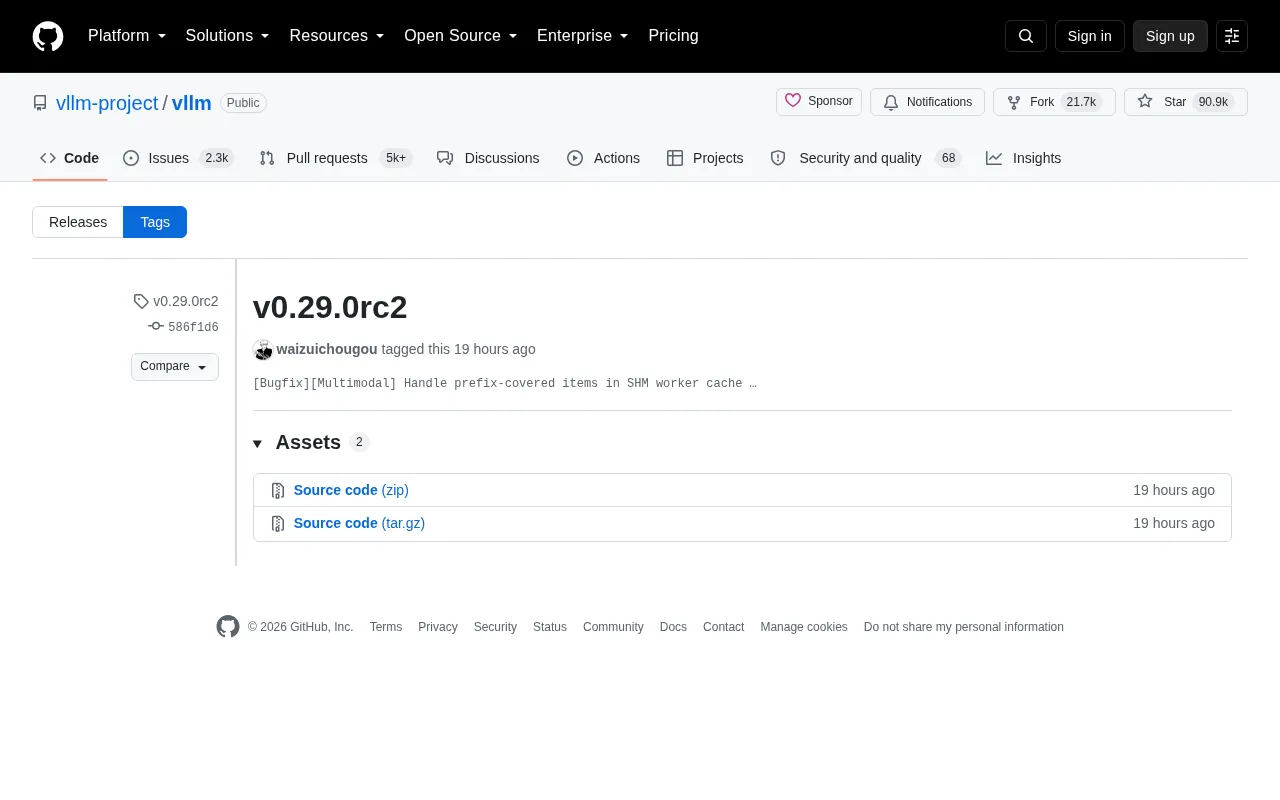
vLLM v0.29.0rc2 fixes a shared memory cache consistency bug in multimodal prefix caching scenarios.
vLLM v0.29.0rc2 is a release candidate centered on a targeted bug fix: resolving an edge case where multimodal inputs (e.g., images) in the SHM worker cache get partially overwritten by request prefixes, causing data corruption or crashes under concurrent load. The fix addresses a key stability pain point for teams running Vision-Language Models in production. vLLM's disciplined RC process and structured commit labeling reflect its maturity as enterprise-grade infrastructure. Production users are advised to validate in staging environments and wait for the official v0.29.0 release.
vLLM Keeps Iterating: v0.29.0rc2 Release Candidate Published
As one of the most popular inference and serving frameworks for large language models, vLLM has recently published its v0.29.0rc2 release. This is a Release Candidate (RC), meaning the version has entered its final testing phase before an official release — primarily aimed at gathering community feedback, validating stability, and paving the way for the final stable build.
In terms of community traction, vLLM has now accumulated over 90,900 stars and 21,700 forks on GitHub, firmly placing it in the top tier of open-source inference frameworks. These numbers reflect the explosive growth in demand for large model deployment and the increasing importance of a mature ecosystem around high-efficiency inference engines.
The Core Fix: Shared Memory Cache Issues in Multimodal Scenarios
The central change in this rc2 release focuses on a specific bug fix:
[Bugfix][Multimodal] Handle prefix-covered items in SHM worker cache
This commit message is concise, but it carries several important technical signals.
What Is the SHM Worker Cache?
SHM stands for Shared Memory. In vLLM's distributed inference architecture, multiple worker processes need to collaborate in handling requests. For multimodal models — such as Vision-Language Models (VLMs) that accept image or video inputs — input data tends to be large in volume. Repeatedly copying this data across processes introduces significant performance overhead.
To address this, vLLM introduced a shared memory-based worker cache mechanism, allowing different processes to efficiently share multimodal data (e.g., image features, encoded tokens) without redundant computation or data transfer, thereby improving overall throughput.
What Are "Prefix-Covered Items"?
The "prefix-covered items" targeted by this fix refer to edge cases in cache reuse. In practice, vLLM relies on Prefix Caching to reuse KV Cache for requests sharing the same prefix — a key optimization for improving efficiency in multi-turn conversations and batches of similar requests.
When multimodal content intersects with the prefix caching mechanism, a cached item may be partially overwritten by a request prefix, leading to corrupted data references or inconsistent state. This bugfix ensures that such prefix-covered cache items are handled correctly, preventing inference errors or crashes in specific concurrent multimodal scenarios.
Why This Fix Matters
Multimodal Inference Is Becoming the Main Battlefield
With the proliferation of multimodal models like GPT-4o, Qwen-VL, and LLaVA, an inference framework's ability to handle non-text inputs — images, video, and beyond — is increasingly a competitive differentiator. Compared to pure text inference, multimodal scenarios introduce far greater complexity in memory management, data transfer, and cache consistency.
By addressing the interaction between multimodal inputs and shared memory caching in this release, vLLM signals its continued investment in production-grade stability for multimodal deployments. For teams already running or planning to deploy VLMs in production, fixes like this often carry more practical value than new features — because they directly affect service reliability.
How to Properly Use an RC Release
It's worth noting that rc2 is a release candidate, not the final stable version. For production users, the recommended approach is:
- Validate in a test environment first: Evaluate the impact of this version on your existing workloads in a staging or canary cluster, especially for scenarios involving multimodal inputs and prefix caching;
- Wait for the official release: RC versions typically converge into the final v0.29.0 within a short timeframe — production deployments can afford to wait for the stable build;
- Run regression tests on critical paths: Since this fix touches cache consistency logic, upgrading warrants focused validation of cache hit rates and inference correctness.
vLLM's Engineering Practices Through the Lens of Version Cadence
The naming convention of v0.29.0rc2 reveals that vLLM follows a relatively disciplined release candidate process: publishing multiple RC versions for thorough validation before freezing into an official release. This practice isn't always strictly followed in fast-moving AI infrastructure projects — many ship directly to major versions for speed, inadvertently carrying instability into production.
vLLM's commitment to the RC process, combined with clearly categorized commit labels (e.g., [Bugfix], [Multimodal]), reflects the engineering maturity of a project evolving toward enterprise-grade, production-ready infrastructure. This discipline is also a key reason the project has earned broad community trust and maintained high activity levels.
Summary
While vLLM v0.29.0rc2 is a release candidate centered on a single bug fix, the issue it addresses — multimodal shared memory cache consistency — hits squarely at a core pain point in modern large model deployment: the stability and efficiency of multimodal inference.
For developers and teams focused on inference performance and production reliability, keeping track of vLLM's release progression and understanding the technical rationale behind seemingly minor fixes helps build a clearer picture of where high-performance inference frameworks are heading. Keep a close eye on the upcoming official v0.29.0 release for a fully validated and stable set of capabilities.
Related articles

DeepSeek Open-Sources DeepInfer: What Is an Inference Framework Actually For?
DeepSeek open-sources its inference framework DeepInfer under Apache 2.0, supporting DeepSeek V4.1 Flash offline inference. This article explains its request scheduling, FlashMLA/DeepGEMM compute optimization, DSPark speculative verification acceleration, and what it means for developers and ordinary users.

Open-Source AI Learning Agent: A Full Workflow Experience from Topology Graphs to Exam Generation
Explore an open-source AI learning agent: built on DeepSeek API, it constructs knowledge systems via topology graphs, with automatic document generation, notes, super documents, and exams. Learn about its Agent workflow and design highlights.

DeepSeek Whale Girl Open-Source MV Meme: AI Industry Coded Slang About Pivoting to Closed Source
Bilibili's DeepSeek Whale Girl rap MV uses fictional memes to tease the AI open-source vs. closed-source debate, with lyrics full of industry slang. This article explains the meme culture, the Whale Girl symbol, and the open/closed tension.