What a 1.5-Hour Transformer Training Run That Beat Many LLMs Actually Tells Us
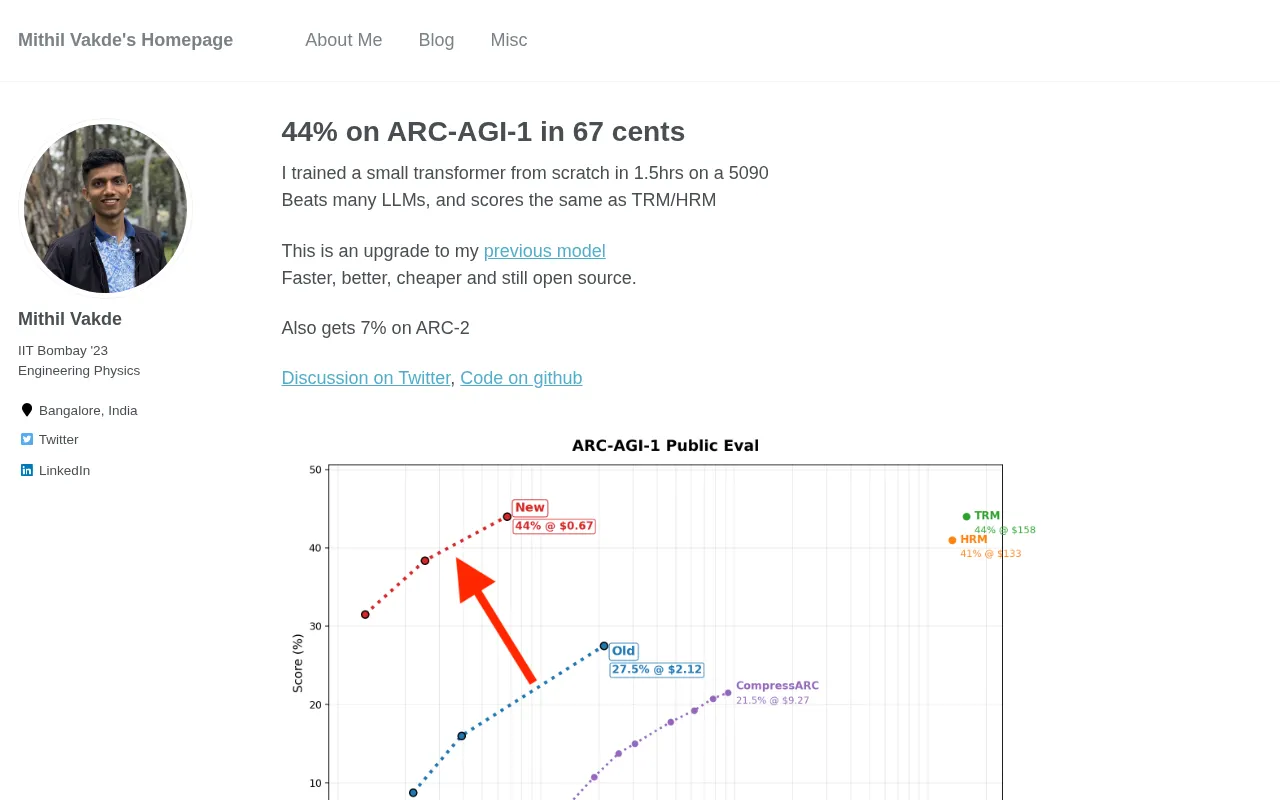
A 1.5-hour Transformer training run beat many LLMs on a specific task — here's what that actually means.
A developer shared a counterintuitive experiment on Hacker News: a small Transformer trained in just 1.5 hours outperformed many mainstream large models on a specific task, sparking broad community discussion. The key reason is task specialization — a small dedicated model can focus all its parameters on the target data distribution rather than covering general knowledge. However, the article cautions that "beating large models" must be examined in context: test set independence and comparison fairness are critical factors. The practical takeaway is that for structured tasks like classification or sentiment analysis, small models often win on cost, latency, and privacy — and future AI architectures will likely be hybrid, combining large and small models strategically.
A Counterintuitive AI Experiment
As the large model arms race intensifies — with hundred-billion-parameter models and million-dollar training runs becoming the industry norm — an experiment posted on Hacker News sparked widespread discussion. A developer trained a small Transformer model in just 1.5 hours, and it outperformed many mainstream LLMs with far larger parameter counts on a specific task.
The post quickly garnered 536 upvotes and 146 comments, reflecting the community's strong interest in the "small but mighty" model approach. It challenges a popular assumption: that bigger models are always better, and longer training always yields better results.
Why a Small Transformer Can "Beat" a Large Model
The Power of Task Specialization
The core insight of this experiment is: when a task is clearly defined, a small specialized model can often achieve excellent performance at a fraction of the cost. General-purpose large models must balance across vast knowledge domains, and a significant portion of their parameters are dedicated to capabilities that will never be used in any given specific application.
By contrast, a small Transformer trained with a focused objective can direct all of its "attention" to the data distribution of the target task. This means it can more precisely fit the task's characteristics on specific benchmarks, outperforming "jack-of-all-trades" giant models along that particular dimension.
Rethinking Training Efficiency
A 1.5-hour training run strongly suggests this experiment was completed on a single consumer-grade or data center GPU. This speaks directly to several key technical trends:
- Modern training frameworks (such as PyTorch 2.x, Flash Attention, etc.) have significantly improved training throughput
- High-quality, focused datasets are more valuable than massive noisy ones
- Sound architecture design and hyperparameter tuning can yield outsized gains
The Two Sides of Benchmarks: How to Interpret "Beating an LLM"
Claims of Outperforming Large Models Deserve Careful Reading
The comment section included plenty of measured voices. Many experienced practitioners pointed out that "beats many LLMs" needs to be understood in context. It is entirely reasonable for a small model to outperform a large model on a narrow, in-distribution task — but this does not mean it possesses a large model's generalization ability, instruction-following capability, or breadth of world knowledge.
In other words, if the benchmark happens to closely align with the training data, then "beating" a larger model reflects highly specialized overfitting rather than a genuine capability improvement. When evaluating models, a few key questions must be answered:
- Is the test set truly independent from the training distribution?
- Are the LLMs being compared using zero-shot inference or fine-tuning?
- What is the difficulty and diversity of the task itself?
The Importance of Fair Comparisons
Comparing a purpose-trained small Transformer against general-purpose models on a specialized task is inherently a "home field advantage" scenario. It's like putting a professional sprinter against a decathlete in the 100 meters — the outcome isn't surprising. Comparisons that are genuinely useful should evaluate models' overall capabilities and cost-effectiveness under equivalent conditions.
Practical Takeaways for AI Developers and the Industry
Not Every Use Case Needs a Giant Model
The most practical value of this experiment is a reminder to developers: before reaching for an expensive large model API, think carefully about the actual requirements of your task. For structured tasks like classification, sentiment analysis, domain-specific Q&A, or constrained format generation, a carefully trained small model may win across the board on latency, cost, and controllability.
For resource-constrained teams and individual developers, the small model approach is especially attractive:
- Cost control: No ongoing API call fees
- Data privacy: Model runs locally; data never leaves your environment
- Low latency: Small models have extremely fast inference
- Easy iteration: Short training cycles enable rapid idea validation
A Sensible Division of Labor Between Large and Small Models
Future AI application architectures will likely be hybrid: large models handle open-ended, complex tasks requiring broad knowledge, while a fleet of small specialized models handle high-frequency, well-defined vertical tasks. This "divide and conquer" strategy strikes a better balance between cost and performance.
Look at Results Rationally, Then Get Your Hands Dirty
The greatest significance of this 1.5-hour Transformer training experiment may not be in who it "beat," but in how it lowers the psychological barrier to AI experimentation. It proves that you don't need a massive compute budget — ordinary developers can gain valuable output and insight from the model training process too.
That said, it's equally important to avoid swinging to the other extreme — assuming small models can fully replace large ones. The two serve different scenarios, and each has irreplaceable value. True engineering wisdom lies in choosing the right tool for the task at hand, rather than blindly chasing any single trend.
For developers looking to get started, this experiment is an ideal entry point: find a well-defined task, prepare high-quality data, train a small Transformer model, and feel its power firsthand. That hands-on experience will teach you far more than any abstract debate about parameter counts ever could.
Related articles

Cursor AI in Practice: Weighing Efficiency Gains Against Costs in an AI IDE
An in-depth look at Cursor AI IDE's interface layout, four modes (Agent/Plan/Debug/Ask), model selection, and Git context integration, with hands-on demos weighing subscription costs against going direct to Claude.
Free Landing Page Design Rules Library: A Practical Guide for Claude Code and Cursor
A free landing page design skill for Claude Code and Cursor: MIT licensed, nearly 9,000 stars, asks about offer/audience/action before planning 12 sections with hard font and spacing constraints.
Cursor Keeps Writing Wrong Code? The Problem May Be Context, Not Prompts
Cursor keeps writing wrong code? The problem may be context, not prompts. Learn how to supply relevant files, full error messages, and expected results, plus a plan-first, small-step, test-driven workflow to reduce AI coding errors—while remembering code review remains the developer's job.