Deep Dives
In-depth AI analysis, industry observations, and technical insights — slow down and read.

A New Paradigm for LLM Cultural Adaptation: From Q&A to Repeated Social Interactions
LLM cultural competence evaluation is shifting from static Q&A to dynamic social interaction. A new study in a sandbox environment finds that memory mechanisms are key to norm assimilation, cross-scenario transfer, and multilingual adaptation in repeated interactions, offering a new paradigm for cultural alignment of interactive agents.

StepBack: Step-Level Error-Localized Resampling Cuts Reasoning Tokens by 41%
StepBack introduces step-level error-localized resampling: locate the first erroneous step in draft trajectories, resample that step and its suffix, matching self-consistency accuracy on seven math reasoning and multi-hop QA benchmarks while cutting token usage by up to 41.26%. It can also be combined with adaptive reasoning methods such as Adaptive Consistency.

Label-Wording Augmentation: Effective for Unfamiliar Words, Ineffective for Abbreviations and Code
A study compares two versions of the multilingual cross-encoder Ru-Jev and finds that label-wording augmentation improves accuracy by up to 0.24 on ordinary words and loanwords, but yields no gains—and even performs worse—on abbreviations and opaque codes.

How Mechanistic Interpretability Backstops AI Safety: A Deep Dive into One Survey
A deep dive into a mechanistic interpretability survey for AI safety: contrasting mechanistic evidence with behavioral evaluation, covering features, polysemanticity, circuits, and methods like feature extraction, circuit discovery, and causal verification, plus safety applications including knowledge editing, steering, and monitoring, and their limitations.

MedGraph: Using Graph Memory to Track Patient State and Improve Accuracy in Long-Term Medical Conversations
MedGraph uses graph memory to track patient state, solving outdated information, person confusion, and safety omissions in long-term medical conversations, leading baselines by over 10 percentage points on MedMemoryBench.

Hidden Markov Preference Models: Online Prediction of an Attacker's Next Move
The paper proposes a hidden Markov preference model that jointly models attacker mode switching and time-varying action parameters, worth 0.8 nats per step on CAGE 2.

MAEM: Scaling the Interpretation of Residual Stream Directions with Reinforcement Learning
The MAEM metamodel uses label-free reinforcement learning to map residual stream directions into strongly activating text examples, outperforming corpus search and NLA on Qwen3.6-27B and activating 89% of held-out SAE features and recovering LoRA backdoor payloads.

Strong-to-Weak Distillation More Compute-Efficient Than GRPO? New Study Reveals Key Conditions
New study compares strong-to-weak OPD vs GRPO compute efficiency: external teachers lose to GRPO with response-length inflation; self-GRPO-checkpoint teachers distill math tasks at 1/50 the FLOPs; multi-teacher OPD costs just 5.2%–8.0%.

Large-Step Adversarial Training: New Findings on Implicit Bias, Optimization, and Sharpness
This paper studies gradient descent dynamics in adversarial training with large step sizes, finding three key differences from standard training: a persistent implicit bias gap, no unified convergence rate, and two-phase sharpness dynamics rather than edge-of-stability.

Can Finite Experiments Validate Integrated Information? New Study Reveals Identifiability Boundaries of Mechanism-Level Measures
New study precisely analyzes identifiability of integrated information φ in finite experiments: same behavior but different mechanisms, precision floors from partial access, drastic measure shifts at edges, yet one-sided lower bounds remain certifiable. Measurability becomes a computable design problem.

Scientist World: Building a Runnable Research World for AI Scientists
Scientist World turns every paper into an executable research environment, with 1,000 validated environments. AI scientists outperform humans in 74% of cases, and 6,400 hours of research trajectories boost small-model research ideation by 158%.

User Embeddings Are Sparse Superpositions of Interpretable Behavioral Patterns
New research on user embedding interpretability: user embeddings are sparse superpositions of interpretable behavioral patterns, recovered and named automatically via SAEs, enabling zero-shot audience retrieval. Post-hoc and model-agnostic.

XStack Benchmark: A Touchstone for Cross-Framework ML Code Migration
XStack is a benchmark for evaluating agents migrating ML codebases between PyTorch and JAX. Claude Opus 5 passes 75%, GPT-5.6-sol 45%, others at most 40%. Learn the details and significance of this cross-framework challenge.
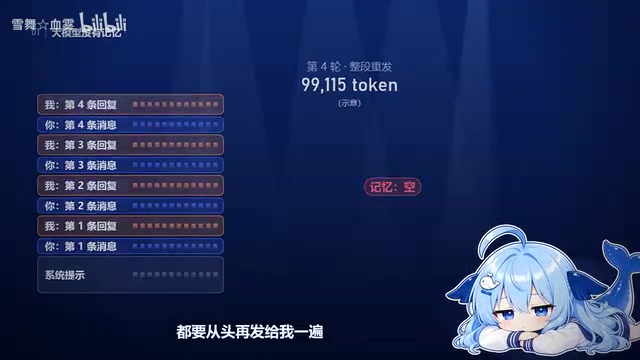
How Token Caching Can Save You 98% on Your DeepSeek Bill
The root cause of DeepSeek API bills varying by dozens of times lies in token cache hit rates. This article breaks down LLM input/output pricing, disk caching, and the 1/50 price gap, with practical money-saving strategies.

Token-Saving Memory Plugin Sick Memory: Just ¥0.9 per Day
Bilibili creator 大肥鱼呀 introduces Sick Memory, a memory plugin using a unified hub, relevance-ranked memory, and Dream organization to let AI characters remember you selectively with evidence, cutting the token cost of reloading old content—about ¥0.9 per day.

Always Running Out of Tokens? This Five-Layer Methodology Saves You Real Money
Tokens getting expensive? This five-layer optimization methodology covers streamlined input, model tiering, context bloat control, cache reuse, and systematic measurement, plus open-source tools like kintestmode and CodeGraph and a 30-second self-check list.

OpenAI Abandons Data Center NDAs: A Key Step Toward Rebuilding Community Trust
OpenAI announces it will no longer sign NDAs with public officials for data center projects, responding to midterm voter opposition. This article analyzes the policy shift's industry impact and significance for rebuilding community trust.

Bypassing DeepSeek Detection: Sneaky Reverse-Proxy Tricks to Avoid Bans and Their Risks
A Bilibili creator shares a DeepSeek reverse-proxy scheme to avoid bans: evading XML tags, using a single English word as trigger, and registering with overseas emails. This article breaks down the technical approach, Harness integration results, and the real risks of this "unlimited tokens" game in terms of rule confrontation, account stability, and compliance.

4 Must-Have Plugins for Saving Tokens in DSH — Stop Installing Blindly
A detailed guide to 4 must-have DSH token-saving plugins: DSH Shops shortens tool output, Billion Context compresses early context, Vision Router converts images to text, and Thinking Levels auto-adjusts thinking depth — plus backup and verification tips before installing.

Retested 51 Times: DeepSeek Harness Token-Saving Plugins — Use Them Right and Save Half, Use Them Wrong and Pay More
51 test runs of three DeepSeek Harness token-saving plugins: Ops saves half only in PTC mode, Flash Presets saves ~20% via rules, Billion Context saves context space but not money. Includes selection guide and pitfalls.