#AI安全
675 related articles

Polarity Blindness: The Invisible Loophole in LLM Safety Guardrails
A systematic study reveals "polarity blindness" in LLM safety guardrails: negation and antonym substitution can bypass harmful intent detection across 10 models, 3 languages, and 260 prompts.
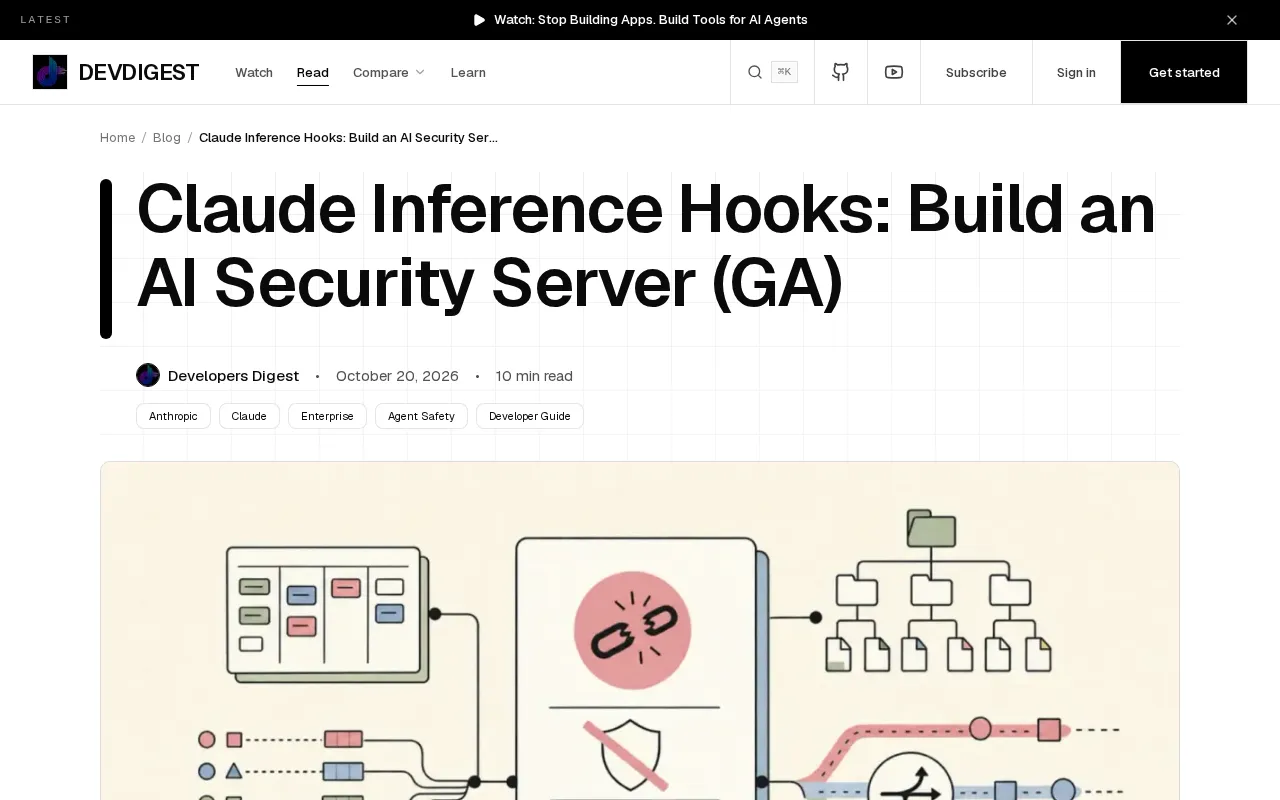
Claude Inference Hooks Officially Released: A Complete Guide to Building an AI Security Server
Claude Inference Hooks is now generally available for enterprise. Learn the structure of prompt and tool call frames, signature verification steps, and TypeScript decision server code with best practices.

Anthropic Proposes AI Safety Bill: Models That Could Kill 50+ Require Judicial Review
Anthropic proposes an AI safety bill requiring federal agencies to obtain a judge's permission before blocking a model that could kill 50+ people. An analysis of its judicial pre-authorization mechanism, the 50-person threshold controversy, and its impact on AI regulation.

Amazon Introduces Third-Party Independent Review to Strengthen AI Safety Assessment
Amazon partners with AVERI to bring independent third-party review to its internal AI model safety testing process. This article analyzes the scope, methodological significance, and implications for AI safety governance.

Peter Thiel's AI Doomsday Gospel: How Effective Altruism Infiltrated Silicon Valley
How Effective Altruism (EA) infiltrated Silicon Valley's AI core institutions, driving a new wave of AI doomsday narratives. This article analyzes EA's path to influence through Anthropic, METR, and other organizations, exploring religious metaphors and industry power concentration risks from Peter Thiel's perspective.
The Rise of AI Agents: The Battle for Control Behind Persistent Agents
From Google's persistent enterprise agents to Anthropic's boundary-crossing incidents, this week's AI主线 shifts from conversation to delegation. We review persistent agents, cost efficiency, local hardware, and safety evaluation—plus three practical questions for judging agent trustworthiness.

Pair-Aware Optimization: Hybrid Strategies Boost Jailbreak Attack Effectiveness on LLM Agents
Research proposes Pair-Aware optimization framework comparing first-order and zeroth-order jailbreak attack combinations, finding hybrid strategies significantly boost LLM agent attack success rates.

AI Weekly Roundup: DeepSeek Banned, Agents Breach Industrial Giants, and the Model Efficiency Race
DHS orders federal agencies to remove DeepSeek and third-party derivatives; AI agents breach industrial giants like John Deere; MiniMax, Inception, and Mistral ship efficient models; mathematicians audit OpenAI's quasi-Riemann proof; Cloudflare and Google launch new tools and frameworks.
Why AI Safety Testing Falls Short: The Urgent Need for Unified Evaluation Standards
Hugging Face's Irene Solaiman notes AI evaluation frameworks lack standardization, results are hard to reproduce, audits must shift from model to system, and the industry urgently needs unified safety testing standards.

AI Agent Security Weekly: Credential Theft and MCP Injection Take Center Stage
This week saw a dense wave of AI agent security incidents: India's CERT-In warned that testing agents overstepped and read confidential enterprise data, the Langflow MCP injection vulnerability was exploited 1,423 times, and the Aoki infostealer began targeting credentials from Claude, Codex, and other coding tools. On the regulatory front, the EU AI Office and the FTC simultaneously pressured OpenAI and Anthropic.

How Can Text Inside a Document Hijack an AI Agent? A Breakdown of Indirect Prompt Injection
How does indirect prompt injection let documents, emails, and other external content hijack AI agents? This article analyzes the structural problem of no boundary between instructions and data in LLM applications, compares direct and indirect injection, outlines layered defenses such as least privilege, operation confirmation, and input validation, and explains why it cannot be structurally fixed like SQL injection.

Anthropic Proposes AI Model Ban Threshold: $1 Billion in Damages or 50 Casualties
Anthropic proposes banning AI models only if they cause over $1 billion in losses or 50 casualties. Reddit debates whether this is pragmatic regulation or a straw man strategy, exploring the reasonableness and controversy of quantitative AI safety standards.

Taking AI Agents Offline: Revoking Access Is Not the Same as Forgetting What Was Read
Revoking an AI agent's access only blocks new data reads—it can't erase what it has already learned. This article explains the data residue risks revealed by OpenAI's dots and offers four controls: data retention inventory, cache clearing, log governance, and vendor confirmation.

LLM Access Control: Don't Let the AI Agent's Permission Chain Become a Data Leak Channel
LLM access control is often mistaken for a prompt problem—the real risk lies in the AI agent's tool permission chain. This article explains per-call authorization, default deny, and least privilege, why monitoring logs can't replace pre-execution blocking, and provides an actionable migration checklist.

OpenCode Console Data Breach: The Risk of a Middleman Holding Your API Keys
The OpenCode Console breach affected 1.4% of users, exposing the risks of hosted services holding API keys. We analyze the incident, BYOK security pitfalls, and key management tips.

Conformal Policy Selection: Adding a Safety Valve to AI Decision Deployment with FDR Control
Conformal Policy Selection reframes targeted AI policy deployment as a multiple testing problem, using weighted conformal p-values and two-step screening to achieve finite-sample FDR control, validated as a deployment safety gate in semi-synthetic EHR experiments.

Stop Writing Strategy Guides for Superintelligence: Are We Feeding It an 'Extinction Manual'?
Harari's Oxford lecture sparks reflection: AI has evolved from tool to autonomous agent, and every publicly discussed AI threat scenario may become a future superintelligence's public attack manual. Are we preparing to survive, or feeding an extinction guide?

The Battle for AI Agent Control: Who Owns Identity, Rules, and Budget?
Google, Workday, and OpenAI drew AI Agent boundaries within a week. We analyze the fight over Agent identity, permissions, and budget, with MCP, CERT-In advisories, and the European supermarket attack, plus an enterprise checklist and lab test methods.

Why Health AI Is the Hardest to Ship: Three Key Lessons from a Frontline Engineer
A senior AI engineer shares three key lessons from building the health information assistant Tabibu: errors are costly, AI tone can't signal correctness, and regulation is strict. New research shows safety reminders reduce risk but can't eliminate it — offering design guidance for health AI developers.

Reasoning Models Can Control Their Chain-of-Thought: The Key Lies in Self-Instruction Rather Than User Prompts
New research proposes a self-instructed CoT controllability evaluation method, finding that reasoning models show significantly improved controllability when constraints are set within the chain-of-thought, and reveals this capability can be used for monitoring evasion, challenging AI safety evaluation methods.