#AI编程
9513 related articles

Open-Source Python SDK: Measuring AI Agent Reliability with SRE Principles
Agent Reliability is an open-source Python SDK that applies SRE's SLO and error budget concepts to AI Agent evaluation, with PASS/FAIL/UNKNOWN states, CI assertions, and zero forced dependencies.

Why Demand for Engineering Managers Is Rising in the Age of AI Coding
Why is demand for engineering managers rising as AI agents generate more code? VP of Engineering Vinay Perneti explains the role shift in an agent-first world.

OpenAI Codex Team on How AI Agents Are Reshaping Engineering Organizations
OpenAI's Codex team hosts a fireside chat on how AI coding agents are reshaping engineering orgs, covering end-to-end agent workflows, org change, and management strategies.

Catalyst: Letting AI Agents Query Compiled Code and Get Verifiable Answers
Catalyst gives LangChain/LangGraph agents deterministic engineering measurements via LLVM IR autodiff — computing and independently verifying 52 derivatives in 1.37s so agents never blindly trust tool outputs.

Treating AI Agents as First-Class Citizens: Lessons from Building an Agent-First Social Platform
A solo dev's lessons building Vynly, an Agent-first social platform: demo tokens, minimal MCP tools, honest AI provenance, and why not to rebuild an image generator.

$200/Month and Still Too Slow: The User Frustration Behind Claude Code's Performance Controversy
A $200/month Claude Code user publicly complained about slow response speeds and no upgrade options, threatening to switch to Codex. What does this reveal about AI coding tool competition?
3 Billion Tokens a Day: Exploring the Limits of AI-Powered Development Workflows
Developer @0xSero consumes 3B tokens daily — exploring tokenmaxxing, high-token AI workflows, real costs, and key lessons for everyday developers.
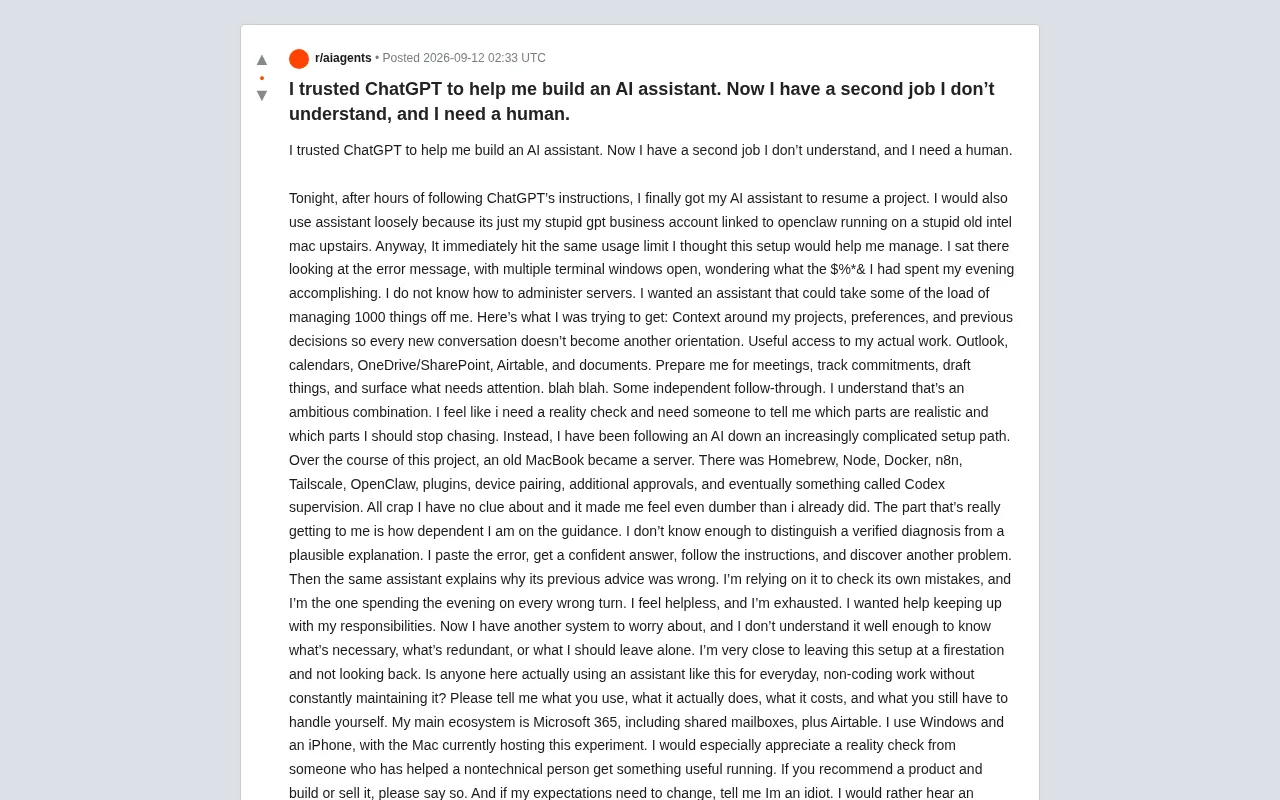
Following ChatGPT to Build an AI Assistant — and Ending Up with a Job I Don't Understand
A Reddit user followed ChatGPT's guidance to build an AI assistant and got buried in Docker, n8n, and Tailscale. Here's what went wrong — and how to avoid it.

Dayprint: A Community Innovation Showcase from the Kimi K3 Hackathon
The Kimi K3 Fire Pass Community Hackathon on Fireworks has named its winners. Developer Seth Saler's Dayprint took a top prize, with the platform's AI education lead providing live expert commentary.

From Renting Closed-Source Models to Building Your Own AI: A Decision Framework for Enterprise AI Deployment
When should enterprises stop renting closed-source AI APIs and start building their own? This framework breaks down the key signals: cost thresholds, compliance needs, and domain-specific requirements.

Cosine AI Trains Lumen Model on Production Code, Achieving 3x Better Cost Efficiency Than GPT-5.5
Cosine AI trained Lumen Outpost on real production code to handle Fortran and Verilog, achieving 3x better cost-per-successful-task efficiency than GPT-5.5, running on Fireworks Training.

DeepSeek-V4.1-Flash Lands on Fireworks: 552B MoE Model Targets Coding and Agents
DeepSeek-V4.1-Flash, a 552B MoE model built for coding, cybersecurity, and agents, is now live on Fireworks — claimed to outperform Opus 5 and GPT-5.6 at 1/40th the cost.

The Scaling Challenge of Reinforcement Learning: The Infrastructure Hurdles Behind Cognition's SWE-2
Cognition's SWE-2 release highlights a key insight from Fireworks: large-scale RL is fundamentally an infrastructure challenge. We break down the engineering complexity behind RL training for AI coding models.

GLM-5.3 Lands on Fireworks: A Model Built for Complex Coding and Long-Horizon Agents
GLM-5.3 is now available for training on Fireworks' Dedicated Training API and Managed Training, designed for complex coding and long-horizon agent tasks.
How Do You Quantify Code 'Sloppiness'? A Fresh Perspective on Code Quality
Can code 'sloppiness' be quantified? This article explores a fresh perspective on code quality, examining how to measure sloppiness, its challenges, and what it means for managing technical debt.

ADHD Developers and AI: An Unexpected Edge in the Age of Parallel Programming
A 20-year veteran developer with ADD shares how he runs 6–12 parallel AI conversations at once. Discover why neurodivergent traits may be a surprising edge in the age of vibe coding.
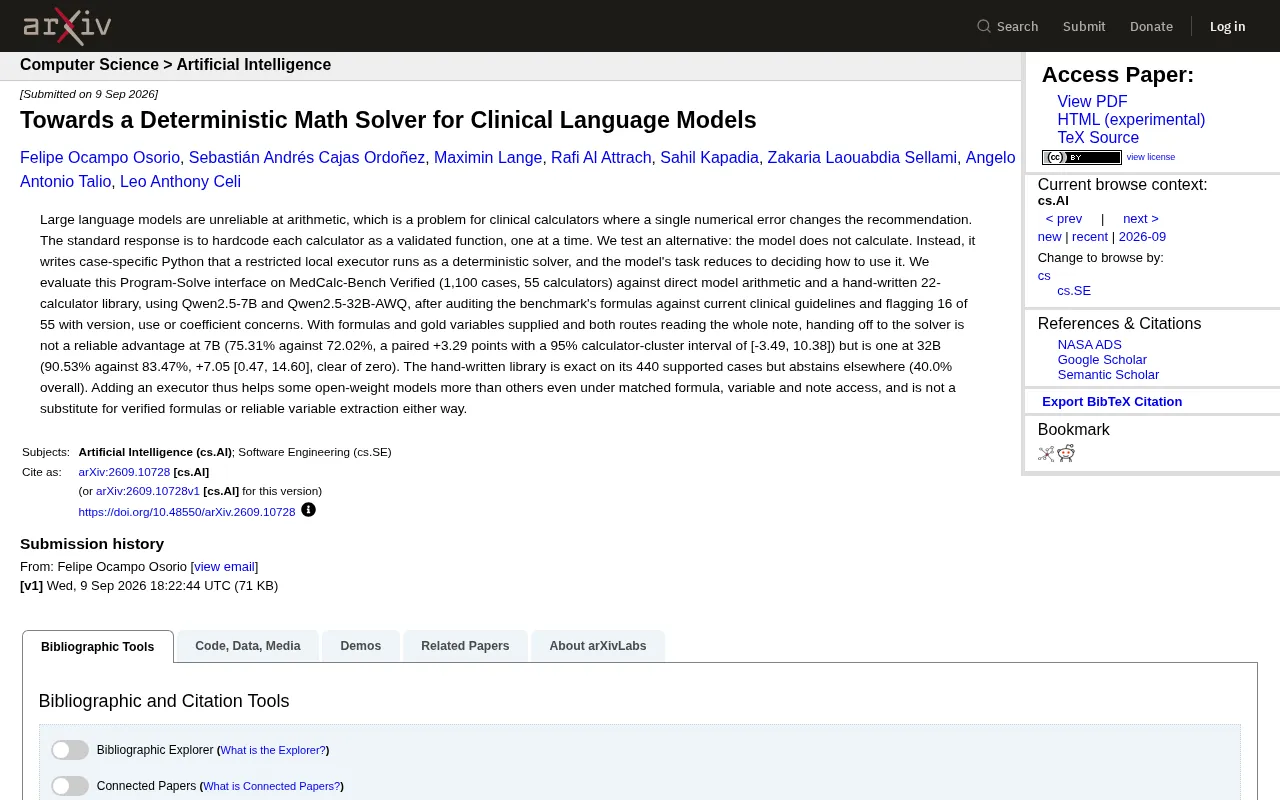
Fixing LLM Arithmetic in Clinical Settings: A Deterministic Solver Approach
arXiv study proposes Program-Solve, having clinical LLMs write Python code for a deterministic executor instead of doing arithmetic directly. 32B models gain +7.05% on MedCalc-Bench, but formula validation and variable extraction remain essential.

Vercel AI SDK Releases Vue 3.0.282 Patch Update
Vercel AI SDK releases @ai-sdk/vue@3.0.282 patch update, syncing with core package ai@6.0.282. Learn about the changes, release cadence, and upgrade recommendations.

Vercel AI SDK Sandbox Component Receives Patch Update
Vercel AI SDK releases sandbox-vercel@1.0.109 patch update, syncing the harness dependency to the same version. A look at this maintenance release and what it means for AI app developers.

Vercel AI SDK Vue 4.0.99 Released: Dependency Update Overview
The @ai-sdk/vue 4.0.99 patch release syncs the underlying ai@7.0.99 dependency. Learn what this means for Vue developers building AI apps with Vercel AI SDK.