#MoE
33 related articles

Reflection Beam: 501B Stored, 23B Awake — A Must-Read for Self-Hosters
Reflection AI releases Beam, a 501B-parameter open-weight MoE model with Apache 2.0 license and 1M context. We break down what 501B storage vs 23B activation means for self-hosters, its benchmarks, and engineering details.
AMD MoRI + vLLM: Wide Expert Parallelism and RDMA KV Cache Transfer for MoE
AMD engineers will demonstrate MoRI + vLLM for MoE serving at PyTorch Conference 2026, featuring Wide Expert Parallelism and RDMA KV cache transfer on AMD hardware.
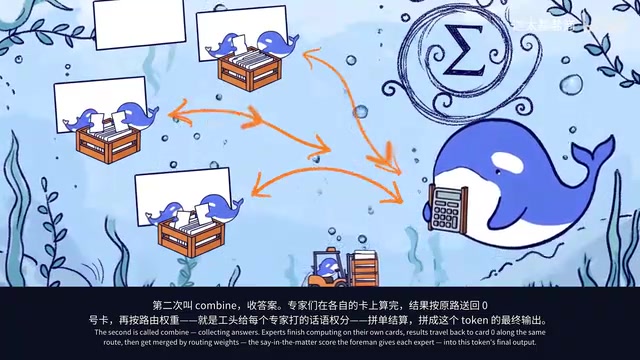
DeepEP Ascend Deep Dive: DeepSeek's MoE Communication Library Ported to Huawei Ascend NPU
DeepSeek's MoE communication library DeepEP is now ported to Huawei Ascend NPU. We break down Dispatch, Combine, FP8 compression, compute-communication overlap, and benchmark bandwidth from EP8 to EP128.

Breaking Down DeepEP and DeepGEMM: MoE Communication and Matrix Computation Acceleration in Practice
Deep dive into DeepSeek's DeepEP and DeepGEMM Ascend: DeepEP achieves 90%+ theoretical bandwidth for MoE communication; MegaMoE fusion operator hits 852 TFLOPS, boosting training 1.5× and decode 2.5×.

How MoE Architecture Cuts Costs and Boosts Efficiency: Efficient Training of Biological Foundation Models
NVIDIA explores using Mixture of Experts (MoE) architecture to efficiently train biological foundation models, decoupling parameter scale from compute costs for DNA and protein modeling.

Colibri Pure-C Engine Goes Viral: Running a 744B Model on 25GB of RAM
Colibri is a zero-dependency pure-C inference engine that runs 744B MoE models on 25GB RAM using three-tier VRAM/RAM/NVMe scheduling. Supports GLM, Kimi, DeepSeek and more.

Dense or MoE? How to Choose the Right AI Model Architecture
Dense vs MoE: what's the difference and when should you use each? This guide breaks down sparse vs full parameter activation to help you choose the right AI architecture.

Dense Models vs MoE: Active Parameters, Throughput, and a Practical Selection Guide
A deep dive into Dense vs MoE models: active parameters, total parameters, and throughput explained. Includes a practical selection guide using NVIDIA Nemotron 3.5 Lightning as a case study.

Accelerating Dropless MoE Training in JAX: A Deep Dive into NVIDIA Transformer Engine
Learn how NVIDIA Transformer Engine accelerates Dropless MoE training in JAX, covering MoE architecture, token dropping, FP8 precision, and grouped GEMM optimizations.

DeepSeek-V4.1-Flash Lands on Fireworks: 552B MoE Model Targets Coding and Agents
DeepSeek-V4.1-Flash, a 552B MoE model built for coding, cybersecurity, and agents, is now live on Fireworks — claimed to outperform Opus 5 and GPT-5.6 at 1/40th the cost.
 Expert Opinions
Rethinking Scaling Laws: Parameters Are Not the Only Answer
Deep analysis of Scaling Law evolution from Kaplan to Chinchilla to the MoE era, exploring why blindly stacking parameters is a mistake, and how GLM-5.3 proves scaling has multiple knobs.
 Deep Dives
NVIDIA Dynamo Multi-Turn Agentic Interaction: Deep Integration of Streaming Tokens and Tool Calling
Deep dive into NVIDIA Dynamo's multi-turn agentic interaction support, covering streaming token output, structured tool calling, state management, and MoE synergy for production-grade AI agents.
