#RAG
296 related articles
Chatbots, Workflows, and AI Agents: The Three Layers of AI Capability Explained
Everyday examples explain the three layers of AI capability: chatbots, AI workflows, and AI Agents—from passive answering to preset automation to goal-driven autonomous decision-making, with RAG vs. Agent clarified.
AI Agents vs. ChatGPT: The Paradigm Shift from Passive Responses to Autonomous Action
Explaining the essential differences between AI Agents and ChatGPT: from passive chatbots and preset AI workflows to LLM-driven autonomous agents, covering the ReAct framework, self-correction loops, and human-in-the-loop safeguards.
Dify × RAG in Practice: Build a Delta Force Game Assistant from Scratch
A practical tutorial on building a Delta Force game assistant with Dify and RAG: from zero-base concepts of agents and knowledge bases to local deployment, LLM integration, vector retrieval configuration, and web embedding delivery, plus a learning path toward LangChain and LangGraph.

Enterprise AI Memory Systems: The Real Cost of Bad Retrieval and Incorrect Ingestion
Analyzing the real costs of bad retrieval and incorrect ingestion in enterprise AI memory systems—from token waste to manual correction and user trust loss—with governance advice.
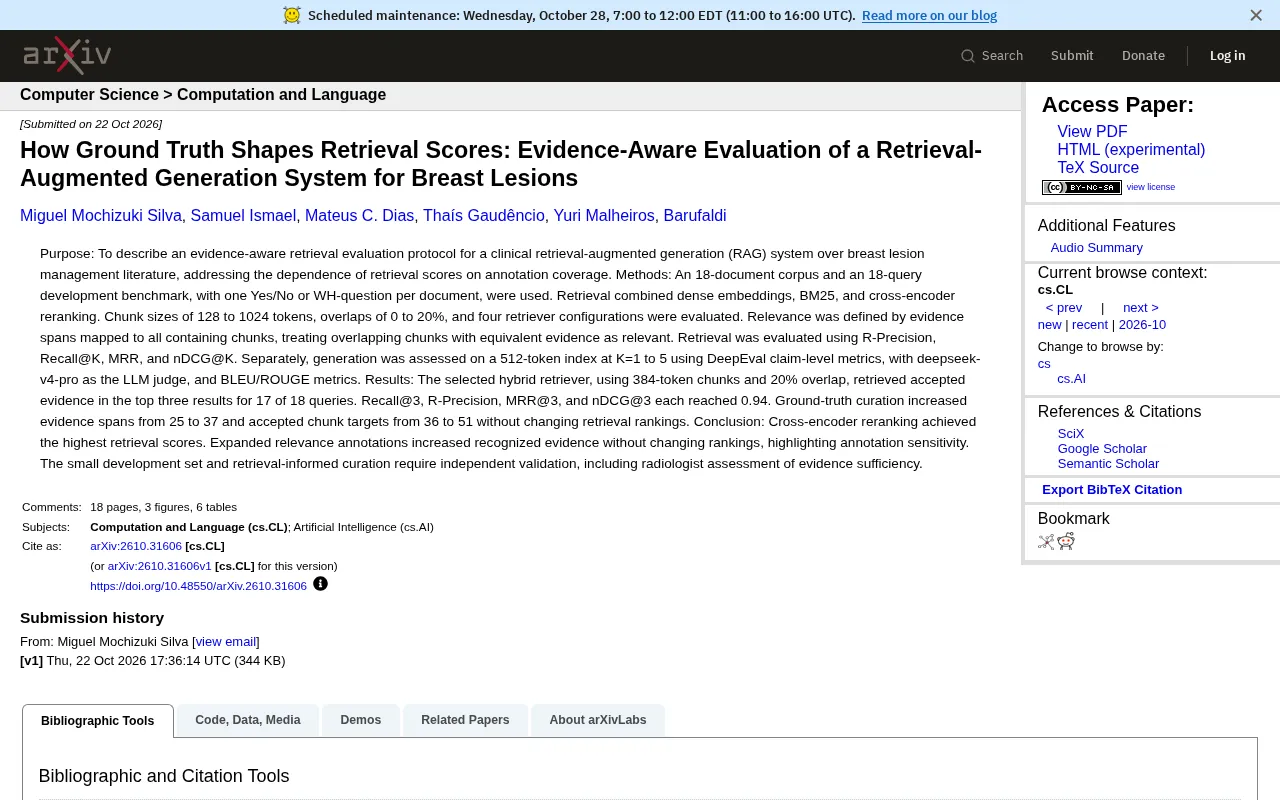
How Annotation Coverage Distorts RAG Retrieval Scores: An Empirical Study on Breast Lesions
An empirical study on a breast lesion RAG system shows ground truth annotation coverage significantly affects retrieval evaluation, urging clinical RAG assessments to report annotation sensitivity.
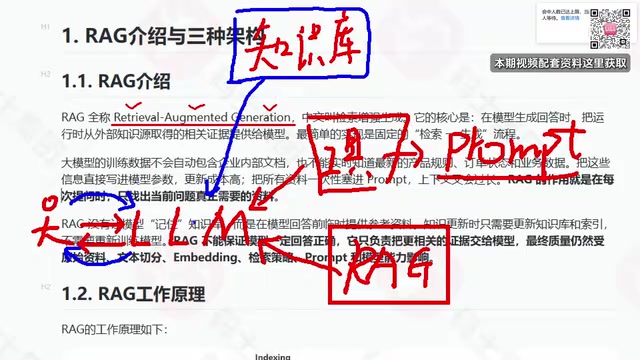
RAG Getting Started in Practice: From Principles to Building an Enterprise Knowledge Base
Bilibili RAG course highlights: from retrieval-augmented generation principles, document chunking and vectorization, to five accuracy factors and enterprise knowledge base boundaries, with fine-tuning vs RAG selection advice.
Cohere Releases Rerank 5: New Context Focus Feature Cuts Token Costs Dramatically
Cohere releases Rerank 5 reranking model, with Pro ranking first on nanoMTEB and ViDoRe V3 and Fast beating Qwen3-Reranker, plus Context Focus to cut token costs.
From Zero to AI LLMs in Three Months: A Pragmatic Self-Study Roadmap
Breaking down a Bilibili AI LLM beginner tutorial's learning path: from prompting and API calls to RAG and vector stores, then building an Agent to understand the ReAct loop. A pragmatic three-month roadmap to AI application development for career changers and productivity seekers.
yggy: An AI Tool for Building Your Own Knowledge Graph — Say Goodbye to Sourceless RAG
yggy is a schema-free knowledge graph AI tool that auto-extracts entities and relationships from documents, preserves sources, supports reversible merging, and serves teams and AI agents via API and MCP with EU hosting for data sovereignty.

Selling a Complete RAG Solution or Audit Services? What Clients Are Really Paying For in 2026
Reddit hot discussion: Is selling a complete RAG solution or RAG audit services easier to close? In 2026, clients truly pay for quantifiable business results, reduced trial-and-error costs, and operational certainty. This article breaks down the sales difficulty and pricing strategies of both service forms.
Deconstructing Coze 3.0 Agent Core Capabilities: From Beginner to AI Talent in Three Months
Deconstructing Coze 3.0 agent core capabilities: a three-step learning path from prompt engineering and RAG knowledge bases to multi-agent practice, plus a rational look at three-month employment promises.
n8n Workflow in Practice: Human-in-the-Loop JIRA Tickets and RAG Implementation
Two n8n practical cases: a human-in-the-loop JIRA ticketing workflow using Gmail triggers, AI Agent, and Wait forms, and an insurance claims RAG assistant that embeds Google Drive docs via Gemini into Supabase.
RAG-Powered Anomaly Detection in Manufacturing: Say Goodbye to Reading Batch Records One by One
Explore how RAG (Retrieval-Augmented Generation) revolutionizes manufacturing batch record review with automated anomaly detection. Learn how it works, key implementation points, and deployment challenges—say goodbye to inefficient manual page-by-page reading.

Your AI Knowledge Base Had 61 Pages. 24 Were Obsolete: The Hard Truth About RAG Document Rot
A dental clinic's AI quoted the wrong price: 24 of 61 RAG knowledge-base pages held false claims. See four rot types, why quarterly reviews fail, plus a scanner, 12-probe audits and a three-field fix.

Retrieved Correctly, Still Wrong? Experimental Design for RAG's "Lost in the Middle"
RAG retrieved the correct evidence but the answer is still wrong? Based on the "Lost in the Middle" paper, this article designs an experiment that changes only evidence position while fixing other variables, measuring model reliance on context position using answer accuracy, citation correctness, and position sensitivity.
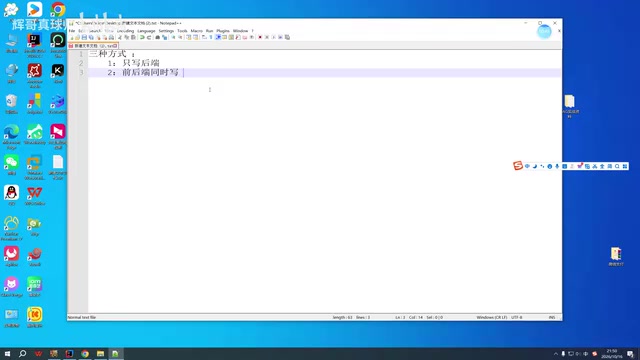
LangChain4j in Practice: Analyzing Three Implementation Approaches for an Enterprise-Level RAG Knowledge Base Project
Bilibili creator Hui Ge's LangChain4j enterprise RAG hands-on project opens with an analysis of three implementation approaches, prerequisites (Spring, databases, Redis, LangChain4j proficiency), target audience, and current limitations.

Best AI Database Solutions for 2026: A Selection Guide Beyond Vector Storage
2026 AI database selection guide: why vector storage alone can't support AI production, specialized vector databases vs. general-purpose extensions like pgvector, and key evaluation dimensions for RAG pipeline selection.

Internal AI Still Using Outdated Info? Practical Methods to Test Data Freshness
How can internal AI assistants be tested to stop using outdated company information? A Reddit developer shares four methods: policy update test cases, document version tagging, manual spot-checking, and automated regression testing, plus two major challenges: conflicting document priority and test maintenance costs.
Building a Precise AI Agent Knowledge Base: Hybrid Retrieval and Reranking in Practice
Elastic workshop recap: from semantic search and BM25 to RRF hybrid retrieval and reranking, a hands-on guide to building a precise AI agent knowledge base and fixing LLM hallucination, with ESQL and Agent Builder tips.

RAG Meets Agent Memory: How Agentic GraphRAG Keeps Agents from Forgetting
Agentic GraphRAG unifies the RAG context layer and Agent memory layer into one graph, using knowledge, working memory, and decision memory layers to solve decision staleness after document changes. Agents can cite exact source versions, and affected decisions are automatically flagged when documents update.