Build Apps Without Writing Code? The Right Way to Do Vibe Coding

Vibe coding speeds up the first version, but testing, security, and delivery responsibility remain human.
The article discusses "vibe coding," where describing requirements in natural language lets AI generate code. It lowers the barrier from idea to prototype, but AI-generated code may contain defects and security weaknesses, and demos differ from reliable products. It recommends a single-feature loop of describe, generate, run, test, and review.
Describe the app you want in natural language, and an AI coding assistant can start generating it: landing pages, dashboards, even a runnable prototype can take shape without writing code line by line. This approach, known as "vibe coding," is changing the starting point of software building—but between a demo and a reliable product lies a gap that must be taken seriously.
When "describing requirements" becomes "writing code"
In traditional development, turning an idea into a clickable interface requires requirement breakdown, technology selection, coding, integration and testing, and many other steps. Vibe coding drastically lowers the barrier to a first version: you only need to explain in everyday language what functionality you want, and the AI will produce the corresponding code and interface.
The appeal of this model is speed. A prototype that used to take days to build may now take shape in a single conversation. For validating ideas, doing internal demos, and rapid trial and error, this is a leap in efficiency. Creators no longer need to become engineers first to turn the product outline in their heads into something visible.
But speed itself is not the goal. A demo that runs and a product that can withstand real users are two different things.
Common tool forms for vibe coding
Vibe coding usually relies on AI coding assistants with code generation and file operation capabilities, such as conversational tools integrated into editors (e.g., Cursor, GitHub Copilot Chat), command-line agents (e.g., Claude Code, Aider), or generation platforms that can directly preview interfaces (e.g., v0, Bolt). What these tools have in common is that they accept natural language instructions, read project context, generate or modify multiple files, and can run results locally or in a sandbox environment. Understanding the boundaries of the tools is important—they are good at completing code based on existing patterns, but they are not always clear about project-specific constraints, dependency versions, and runtime environments, so generated results still need human verification.
The gap between demo and product
AI-generated code may contain defects, security weaknesses, and features that break as soon as real users arrive. This is not a denial of AI capabilities, but a reminder about the practice of "shipping directly." Generative models are good at producing code that looks reasonable based on patterns; they do not inherently understand your business boundaries, exception paths, and attack surface.
A page that works when clicked through in a demo environment will expose problems under concurrent access, abnormal input, and permission checks. This is especially true for security: input validation, authentication, and data exposure surface need to be deliberately designed, not guaranteed by "it looks right when generated."
This responsibility cannot be outsourced to tools. Tools can accelerate, but judging what counts as "ready to release" is still something people must do.
Common security weaknesses
The security issues most easily overlooked when AI generates code include: failure to perform server-side validation of user input, placing sensitive logic on the frontend, hardcoding keys or database connection strings, missing authentication and permission checks, and directly concatenating SQL or commands leading to injection risks. In addition, missing error handling can expose stack information through exception paths. These problems are often invisible in demos because demos only follow the "normal path." To find them, you need to specifically check input validation, authentication and authorization, data exposure surface, and dependency vulnerabilities, rather than just checking whether the page can be clicked through.
A smart workflow: one step at a time
Faced with these risks, the reasonable approach is not to reject AI generation, but to change the granularity at which you use it. Rather than having AI generate the entire application at once, narrow the scope: describe one feature, generate it, run it, test it, review the code, and repeat.
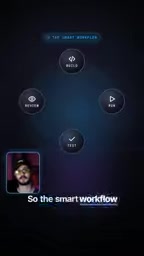
The value of this loop is controllability. The output of each step is small enough that you can truly read it, verify it, and find problems. Feature-level iteration limits the impact of errors and also lets you adjust the next round of description based on the real performance of the previous round.
For creators without an engineering background, this process also brings a hidden benefit: through round after round of generation and review, you gradually build basic judgment about code quality. Knowing where problems are likely to occur has more long-term value than simply being able to "have AI write it."
Focus of code review in AI-generated scenarios
When code is generated by AI, the focus of review differs slightly from handwritten code: first confirm whether the feature is truly implemented as described, then check handling of boundary conditions and abnormal input, then see whether unnecessary dependencies were introduced or sensitive information exposed, and finally confirm whether the scope of changes is limited to the current feature. Because AI may "conveniently" modify unrelated files, reviewing the scope of the diff is equally important. For creators without an engineering background, you can start with three things—reading the diff, running tests, and reproducing exceptions—to gradually build judgment.
AI accelerates the first version, not responsibility
The most practical positioning of AI in the development process is this: it can significantly accelerate the birth of the first version. The path from zero to one used to consume the most effort, and now it can be greatly compressed. This is a real benefit; there is no need to exaggerate or belittle it.
But it does not replace testing, does not replace security, and does not replace the responsibility of "delivering something usable." Releasing a product means you are responsible for how it performs in the real environment and for users' trust. There is no shortcut for this part of the work, and "AI-generated" should not be used as an excuse.
Vibe coding is a way of building worth mastering, provided you treat it as an accelerator rather than a replacement. Describe, generate, run, test, review—walk this loop solidly, and speed and reliability can coexist.
One-line Summary
Vibe coding accelerates first-version development, but testing, security, and delivery responsibility remain with people.
Paragraph Summary
The article discusses "vibe coding," a way of building by describing requirements in natural language and having AI generate code. It greatly lowers the barrier from idea to runnable prototype, enabling creators without engineering backgrounds to quickly validate ideas. But AI-generated code may contain defects, security weaknesses, and features that fail in real user scenarios, and there is a clear gap between a demo and a reliable product. The article recommends narrowing development granularity and adopting a single-feature loop of "describe, generate, run, test, review" to control risk and gradually build code judgment. The final conclusion is: AI accelerates the first version from zero to one, but does not replace testing, security, or the responsibility to deliver a usable product.
Related articles

Anthropic Files S-1: $16.3B Revenue, $80.7B Net Loss in Half a Year — Who Controls the Company?
Anthropic files S-1 for a Nasdaq IPO: H1 2026 revenue of $16.3B, an $80.7B net loss from valuation remeasurement rather than cash burn, founders' Class F shares holding 50.1% voting power, and no price or date yet.

Anthropic Files S-1: The Truth Behind $16.3B Revenue and $80.7B Loss
Anthropic's S-1 reveals $16.3B revenue and $80.7B net loss in H1 2026, with $72.4B from accounting effects. The filing also discloses $265.6B compute commitments, cloud deal details, and a 50.1% founder voting control structure, while IPO pricing remains blank.

Anthropic Financials Leaked: Revenue Far Exceeds Compute Costs, Claude Inference Gross Margin Hits 68%
Leaked Anthropic financials show revenue roughly twice total compute costs, Claude inference gross margin at 68%, while frontier training burns $2.8B per quarter. This article breaks down the two accounts and analyzes shifts in AI company valuation logic.